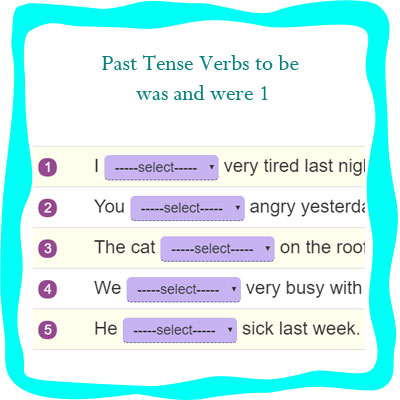
Working with past tense to be verbs in actual production
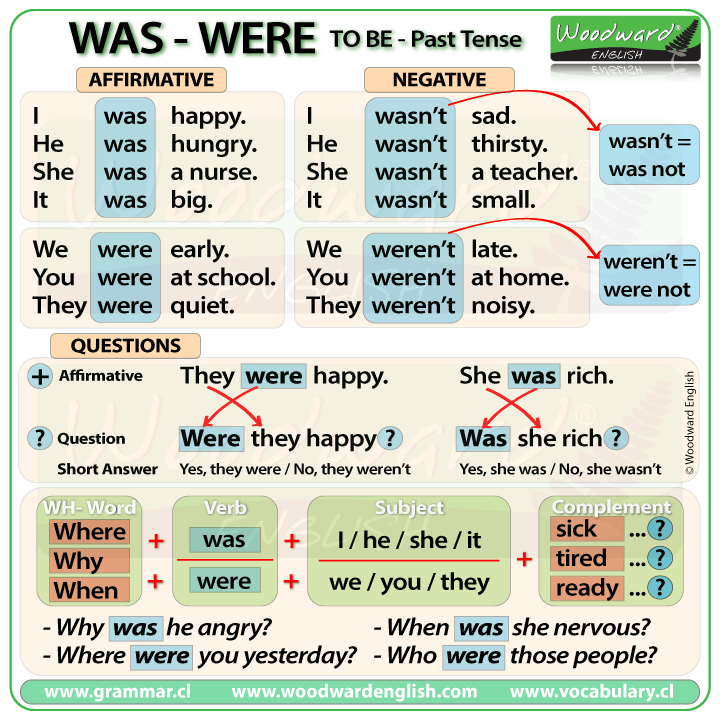
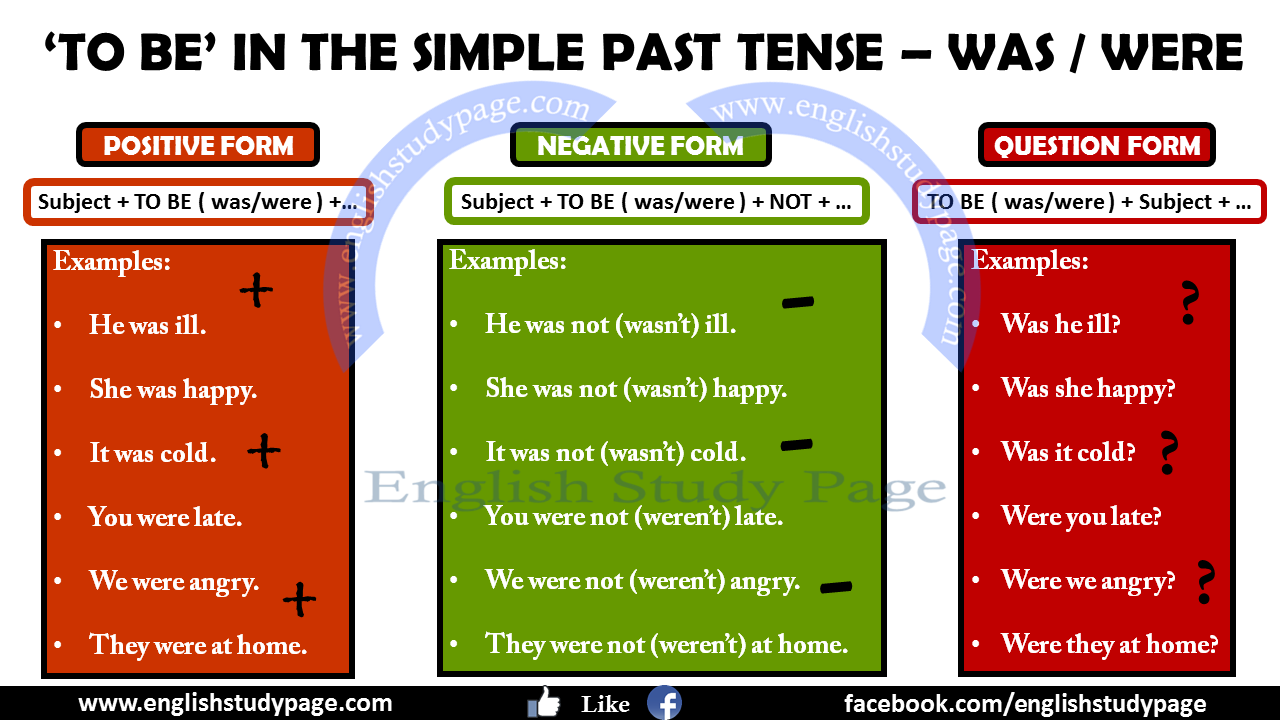
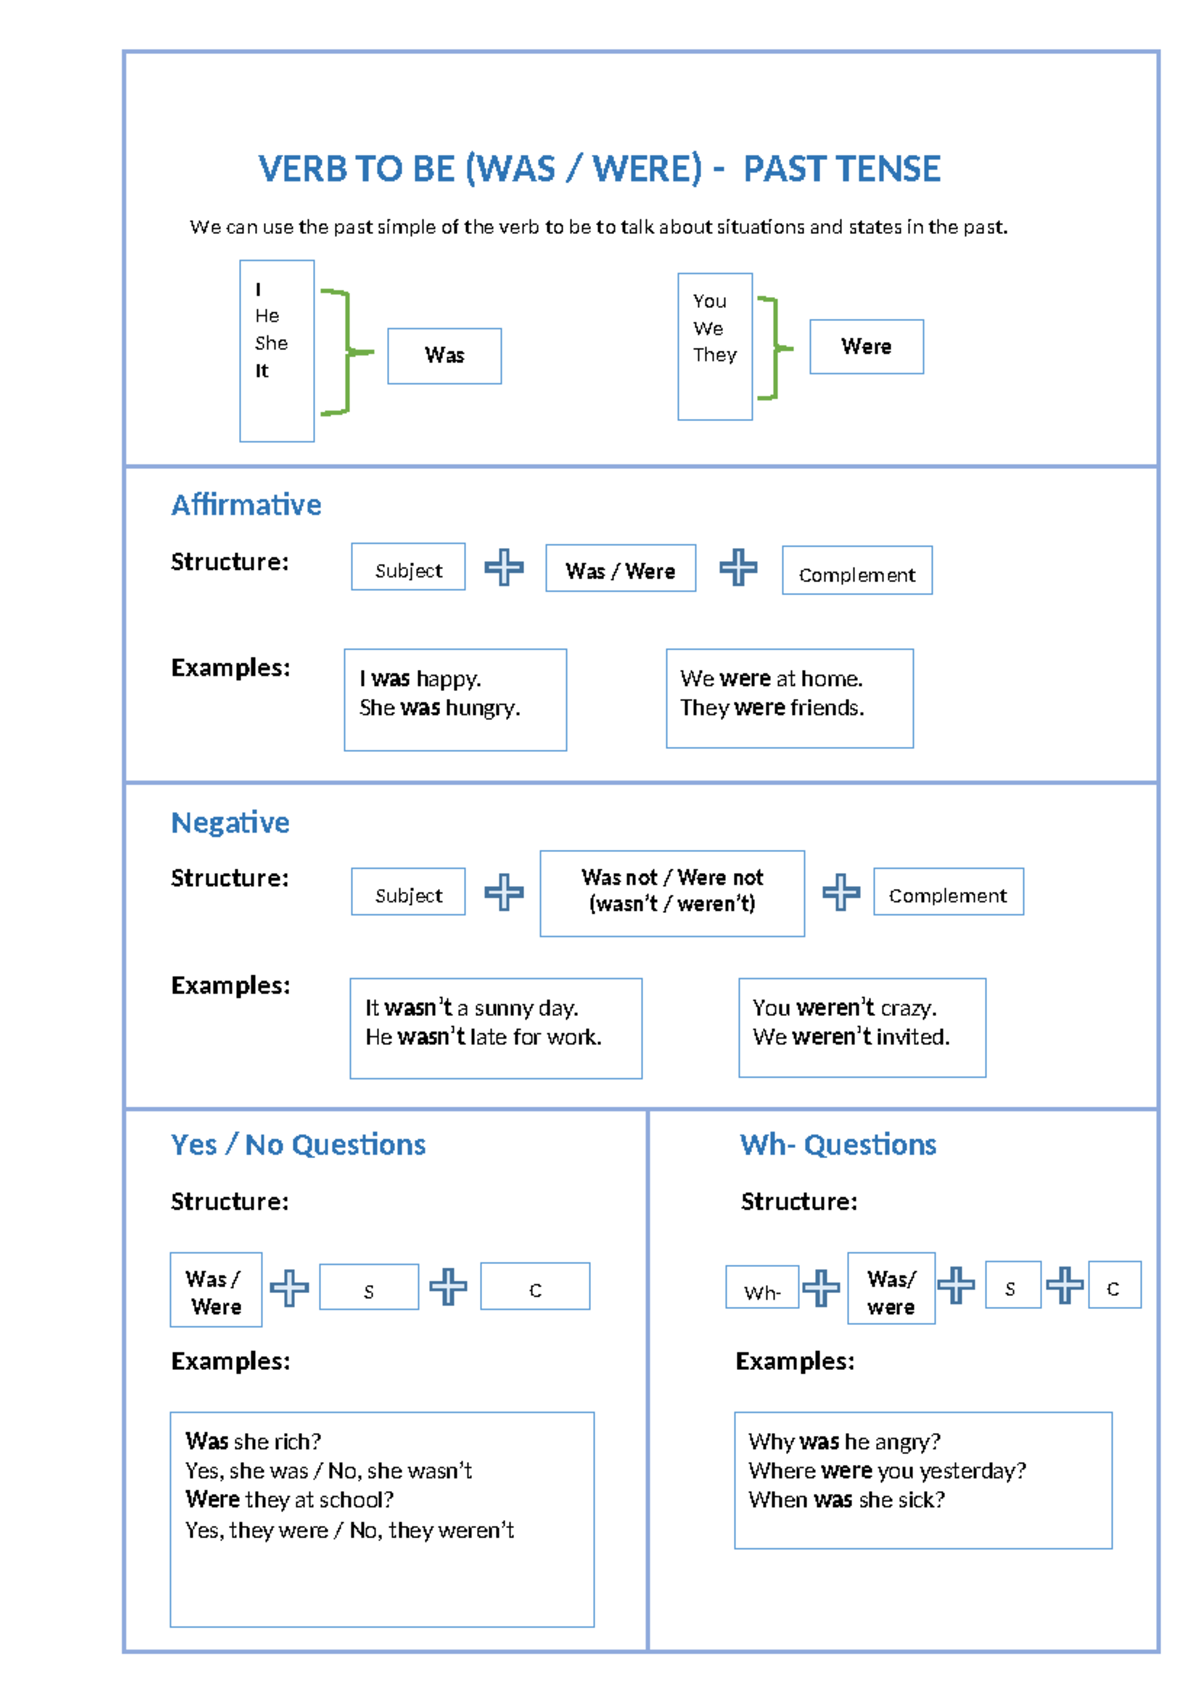
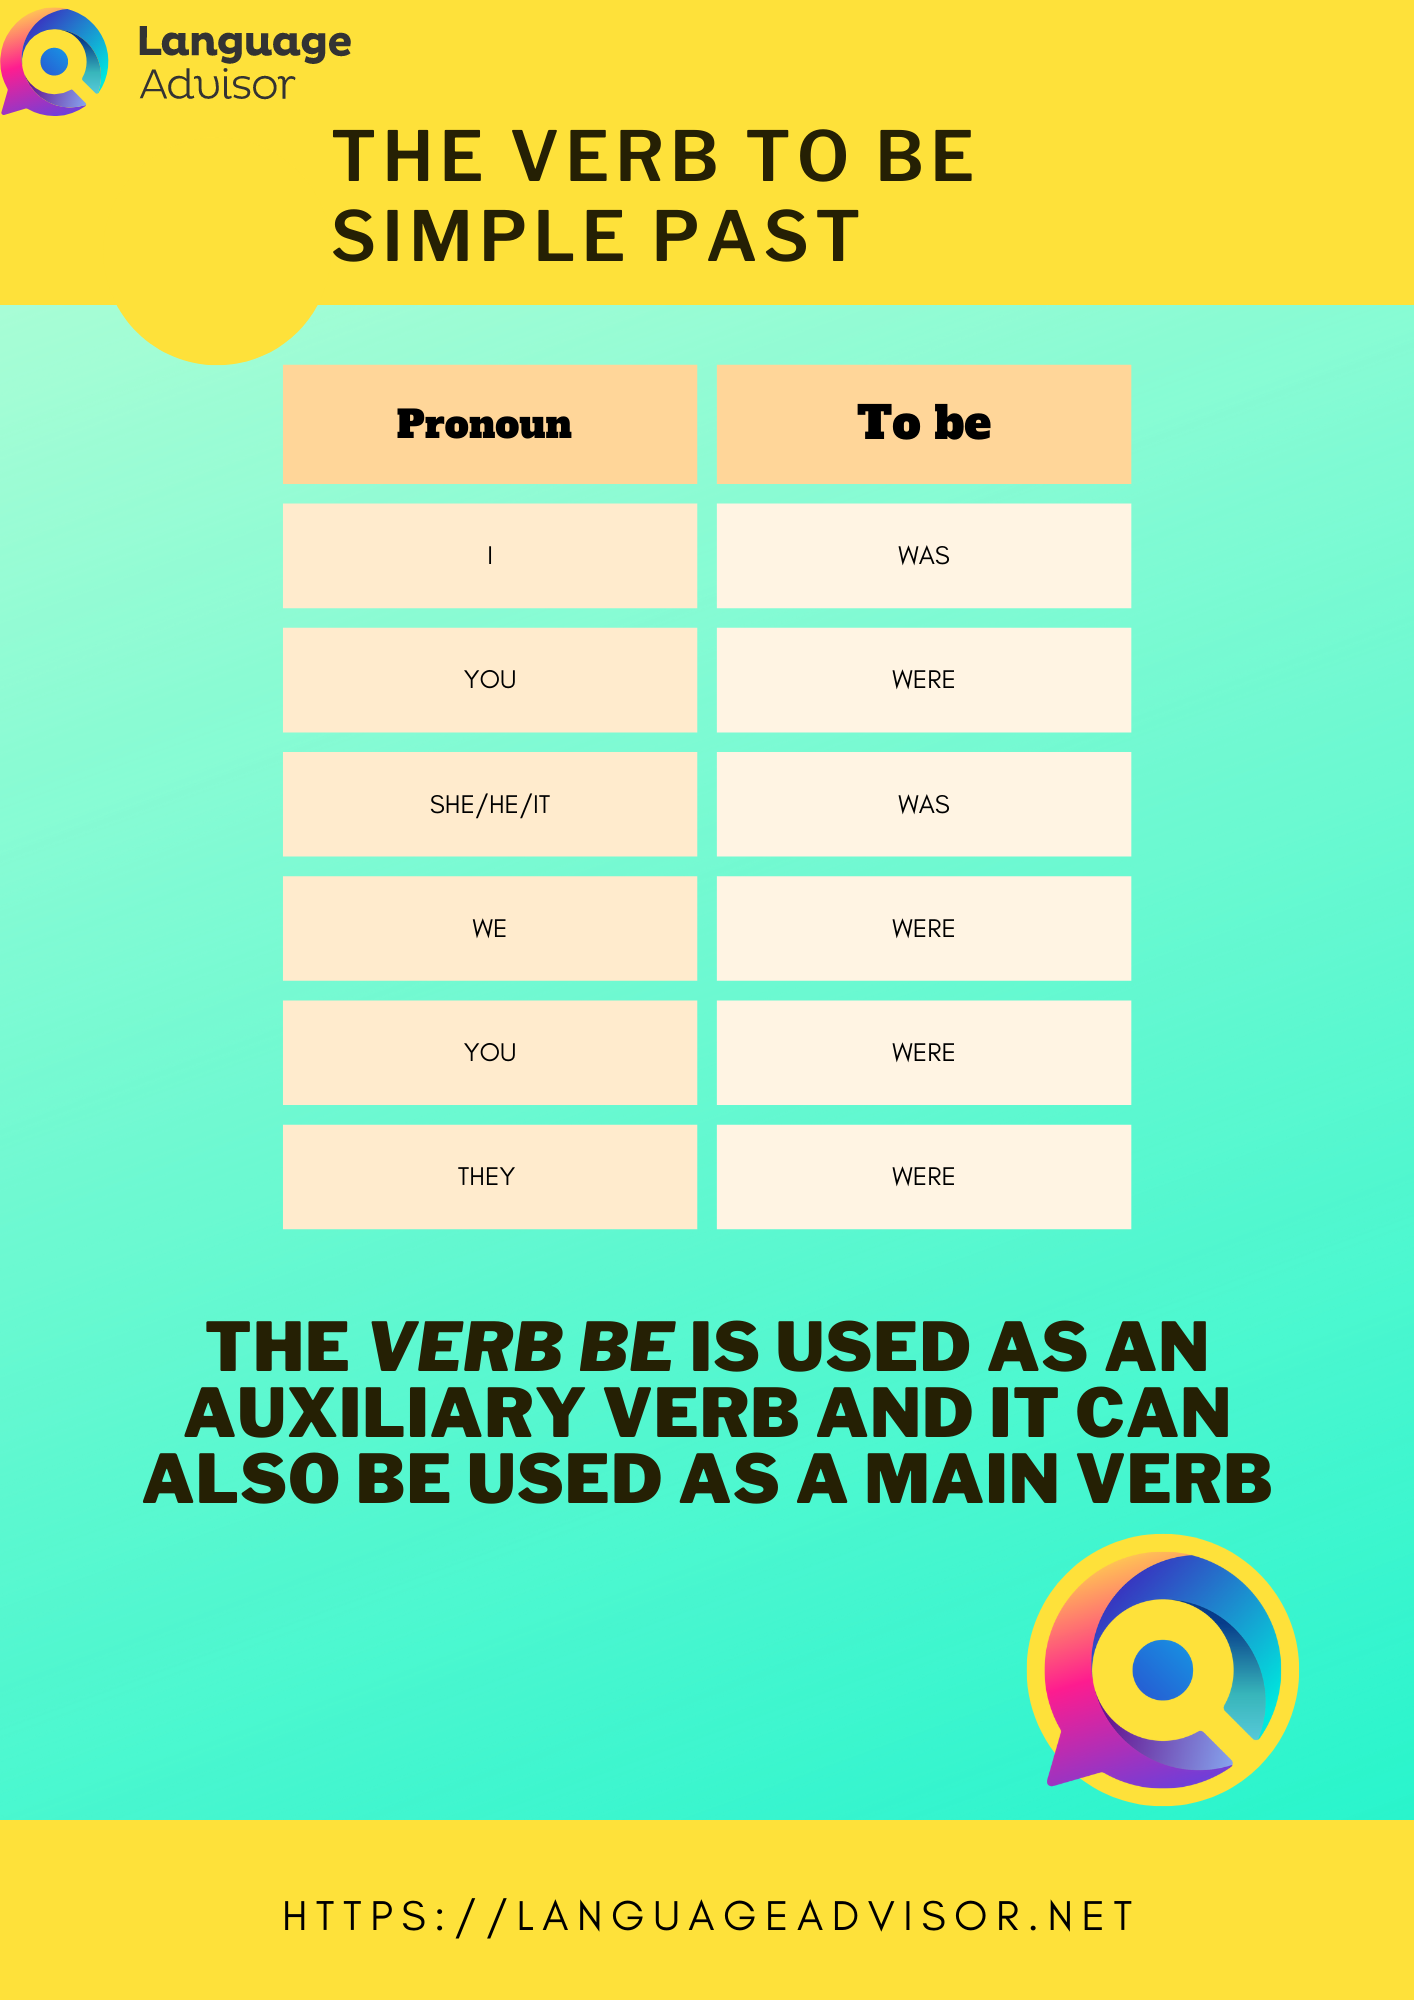
The past tense forms of "to be" are was and were. That's the whole vocabulary. You use was with singular first and third person subjects (I, he, she, it) and were with plural subjects and second person (you, we, they). Anything more complicated than that is usually someone overthinking it. I spent three weeks last year debugging a rule engine that was supposed to parse past-tense narrative text for a content moderation pipeline. The system kept misclassifying borderline cases. It turned out the training data had subtle inconsistencies where "were" was used with collective nouns like "team" and "staff" in some examples but not others. The model had picked up on a pattern that wasn't actually consistent in the source material. I ended up writing a small pre-processing script that normalized those cases before they hit the classifier. Saved the model from learning noise.
How Past Tense To Be Verbs function in real applications
In most NLP work, you won't be conjugating verbs by hand. You'll be dealing with tokenizers, lemmatizers, or morphological analyzers that need to recognize that "was" and "were" are past tense forms of the base lemma "be". Here's the practical breakdown: Was appears in these configurations: I was, he was, she was, it was, [singular noun] was. Were appears in: you were, we were, they were, [plural noun] were. The subjunctive mood throws a wrench in this - "if I were" or "they were here" - where "were" shows up with singular subjects in conditional or counterfactual constructions. Most basic parsers miss this. If you're building anything that needs to handle written English at a reasonable accuracy level, you need to account for the subjunctive separately. Another thing people don't plan for is contraction handling. "Wasn't" and "weren't" are past tense to be verbs with negation attached. In a tokenized pipeline, these often get split into the verb plus a separate negation token depending on which normalizer you're using. spaCy handles them as single tokens. Some older rule-based systems split them. The choice affects how your downstream components interpret the sentence.
I ran into a specific edge case with medical text where "was" and "were" appeared in past clinical notes alongside dates. The parser was supposed to extract temporal relationships, but it kept pulling the wrong anchors because "was administered" and "were prescribed" created different dependency structures depending on whether the subject was singular or plural. I solved it by adding a custom rule that checked the verb agreement against the subject noun phrase before trusting the dependency parse tree. It cost maybe two hours of implementation and fixed about 80% of the erroneous extractions. If you're working with morphology libraries, the main tools are NLTK's WordNetLemmatizer, spaCy's morphological analysis, and Morphy from the Pattern library. NLTK's default lemmatizer will map "was" and "were" back to "be" if you specify the verb lemma type. But it's not always reliable with out-of-context tokens. SpaCy is heavier but more accurate for this particular task. The downside to relying on lemmatizers is that you lose the morphological signal during normalization. Sometimes knowing whether the original text used "was" or "were" matters for agreement checking, subject detection, or stylistic analysis. If your application needs that distinction preserved, you should store the original form alongside the lemmatized version rather than replacing it outright. That's a common mistake I see people make - they lemmatize and move on without considering whether the past tense inflection carries information their system actually needs.
Get the Full Details

For anyone building a simple conjugation table or teaching material, a flat mapping dictionary covers 95% of use cases. For anything approaching production-grade text processing, you need the subjunctive exception handling and the contraction normalization strategies I described above. There's no shortcut around that part.