Getting PCA to work in R without losing your mind
Principal Component Analysis is one of those techniques everyone reaches for when their dataset has more columns than sense. I've done this so many times that the ritual is basically muscle memory now. You load a wide dataframe, you think about what you're actually trying to find, you run prcomp(), and then you stare at a biplot wondering if it means anything at all. The thing most guides don't tell you is that PCA in R starts with a decision about scaling. The prcomp() function has a scale. parameter, and if you leave it as default FALSE, your variables measured on huge scales will dominate the components while your tiny-scale variables disappear entirely. I learned this the hard way on a project where one variable was measured in thousands and another in hundredths. The first component essentially just mirrored the large-scale variable and explained 94 percent of variance. It was useless. Setting scale. = TRUE fixed it immediately, but not before I wasted a morning trying to interpret garbage results.
Why Pca Analysis In R usually surprises people
R handles PCA differently than some other environments. princomp() exists and uses eigen decomposition instead of SVD, but it's slower on large datasets and doesn't handle missing values the same way. Most people end up using prcomp() anyway. The function returns an object with three key pieces: $sdev (the standard deviations of the principal components, which you square to get variance explained), $rotation (the loadings matrix showing how original variables map to components), and $x (the actual principal component scores). Here's what that looks like in practice. You import your data, clean it, and then run something like this: data - read.csv("my_dataset.csv")
data_clean - na.omit(data) pca_result - prcomp(data_clean[, 3:25], scale. = TRUE) summary(pca_result)
Get the Full Details
The summary output gives you the proportion of variance explained by each component and the cumulative proportion. That's your first checkpoint. If the first two components together explain less than thirty percent of total variance, you probably don't have much dimensionality reduction going on and you should reconsider whether PCA is the right tool. The scree plot is your second checkpoint. Use plot(pca_result) and you get a bar chart of standard deviations across components. The elbow point tells you how many components to keep, though honestly I've found the elbow is often not as clean as textbooks suggest. In those cases I default to keeping components until cumulative variance hits around seventy to eighty percent, but that's arbitrary and depends on what the downstream analysis requires.
The part nobody warns you about: outliers break PCA
PCA is a linear technique built on covariance matrices, which means outliers exert disproportionate influence. I ran into this last year on a consumer behavior dataset with about twelve thousand rows and forty variables. The PCA looked reasonable at first glance, but when I added a small subset of data points and re-ran it, the component structure changed significantly. The loadings on the first two components shifted by enough that several variables that previously loaded heavily on component one moved to component two. It wasn't a visualization issue. The outliers were actually distorting the covariance structure. The workaround I use now is to check for multivariate outliers before running PCA. A quick way is to compute Mahalanobis distance on the raw data and flag anything beyond a chi-squared threshold. Another approach is to run a preliminary robust PCA or simply winsorize extreme values. I usually go with the Mahalanobis distance check because it's fast and doesn't require loading extra packages. Another thing that comes up constantly: correlation structure matters. PCA assumes your variables have meaningful correlations. If your dataset is essentially random noise with near-zero correlations between variables, PCA will still run and give you components, but they'll be arbitrary. I once spent an afternoon trying to interpret a four-component solution for a dataset of environmental sensor readings that turned out to have an average pairwise correlation of 0.08. The components were statistically valid but semantically empty. Bartlett's test of sphericity can tell you whether your data is even suitable for PCA before you invest time in it.
Interpreting the output without fooling yourself
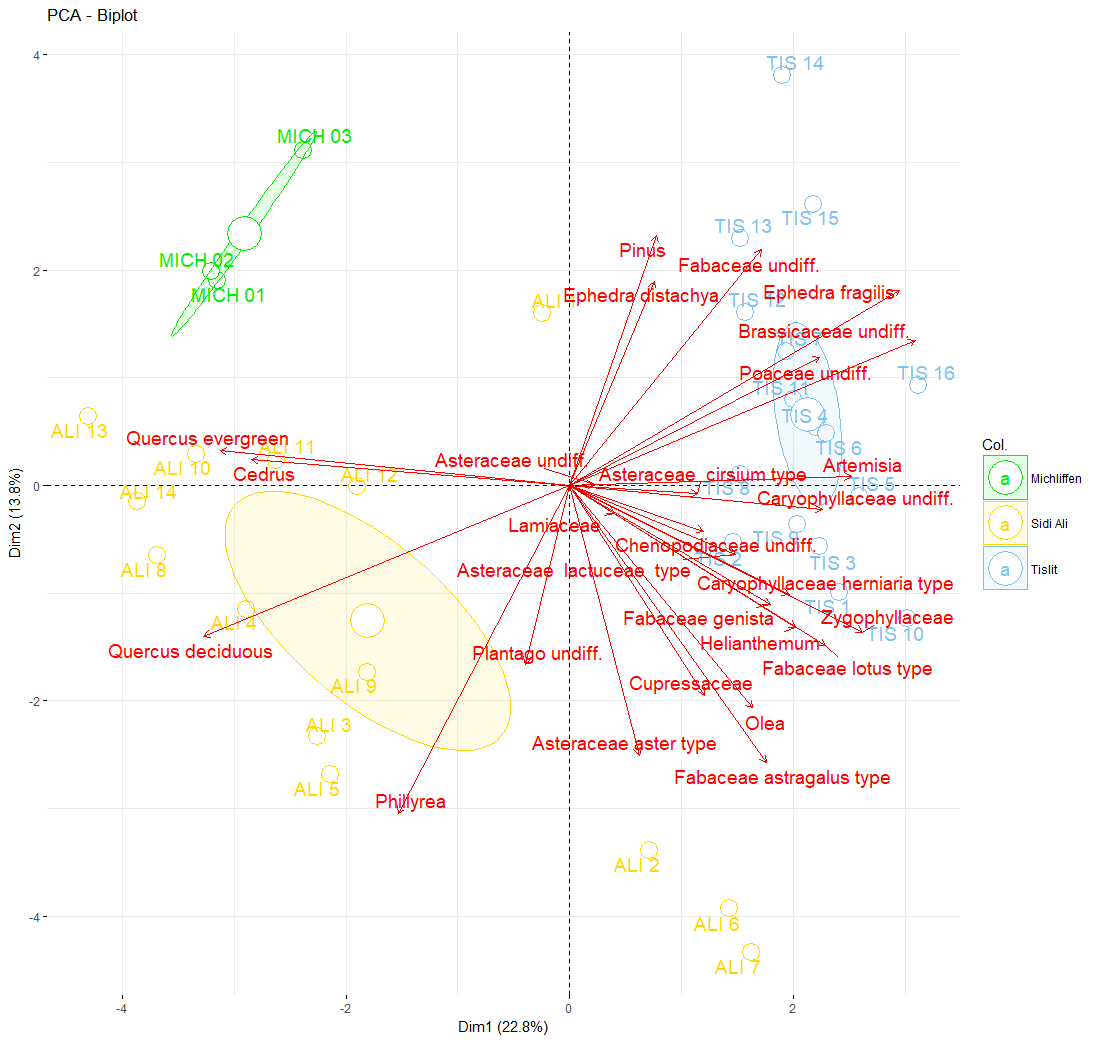
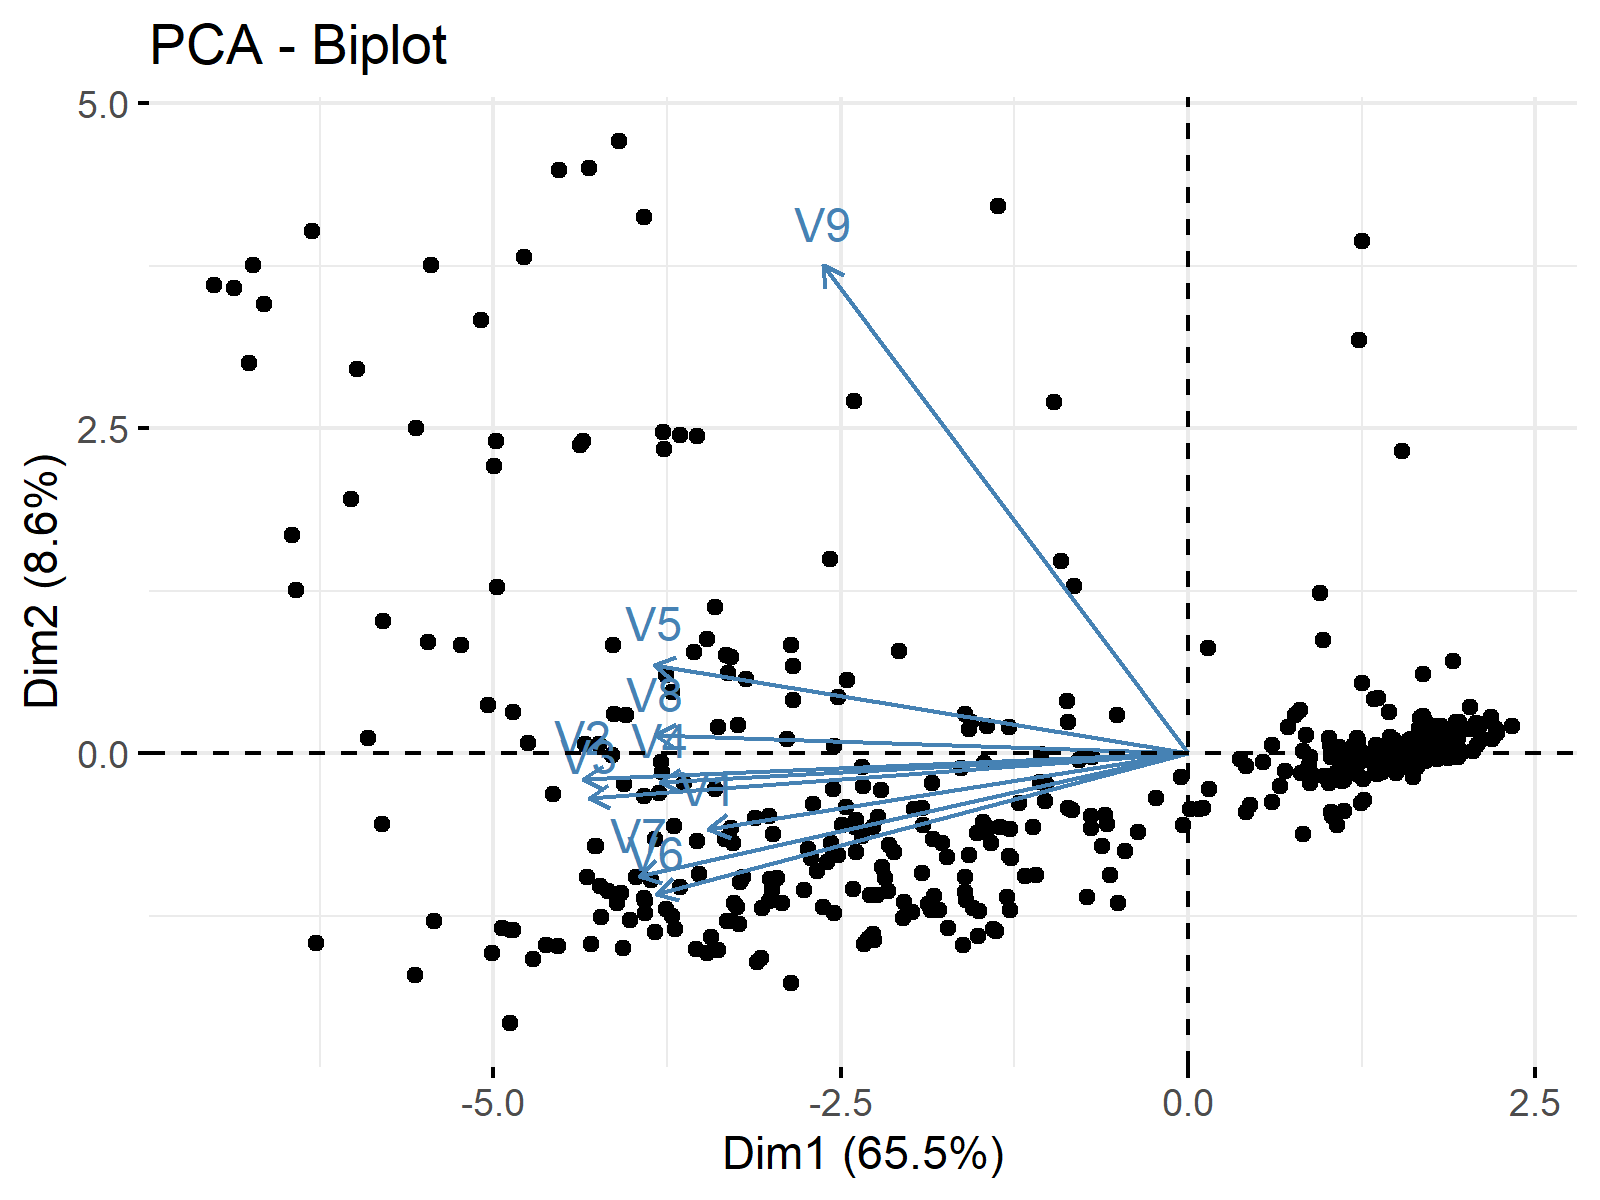
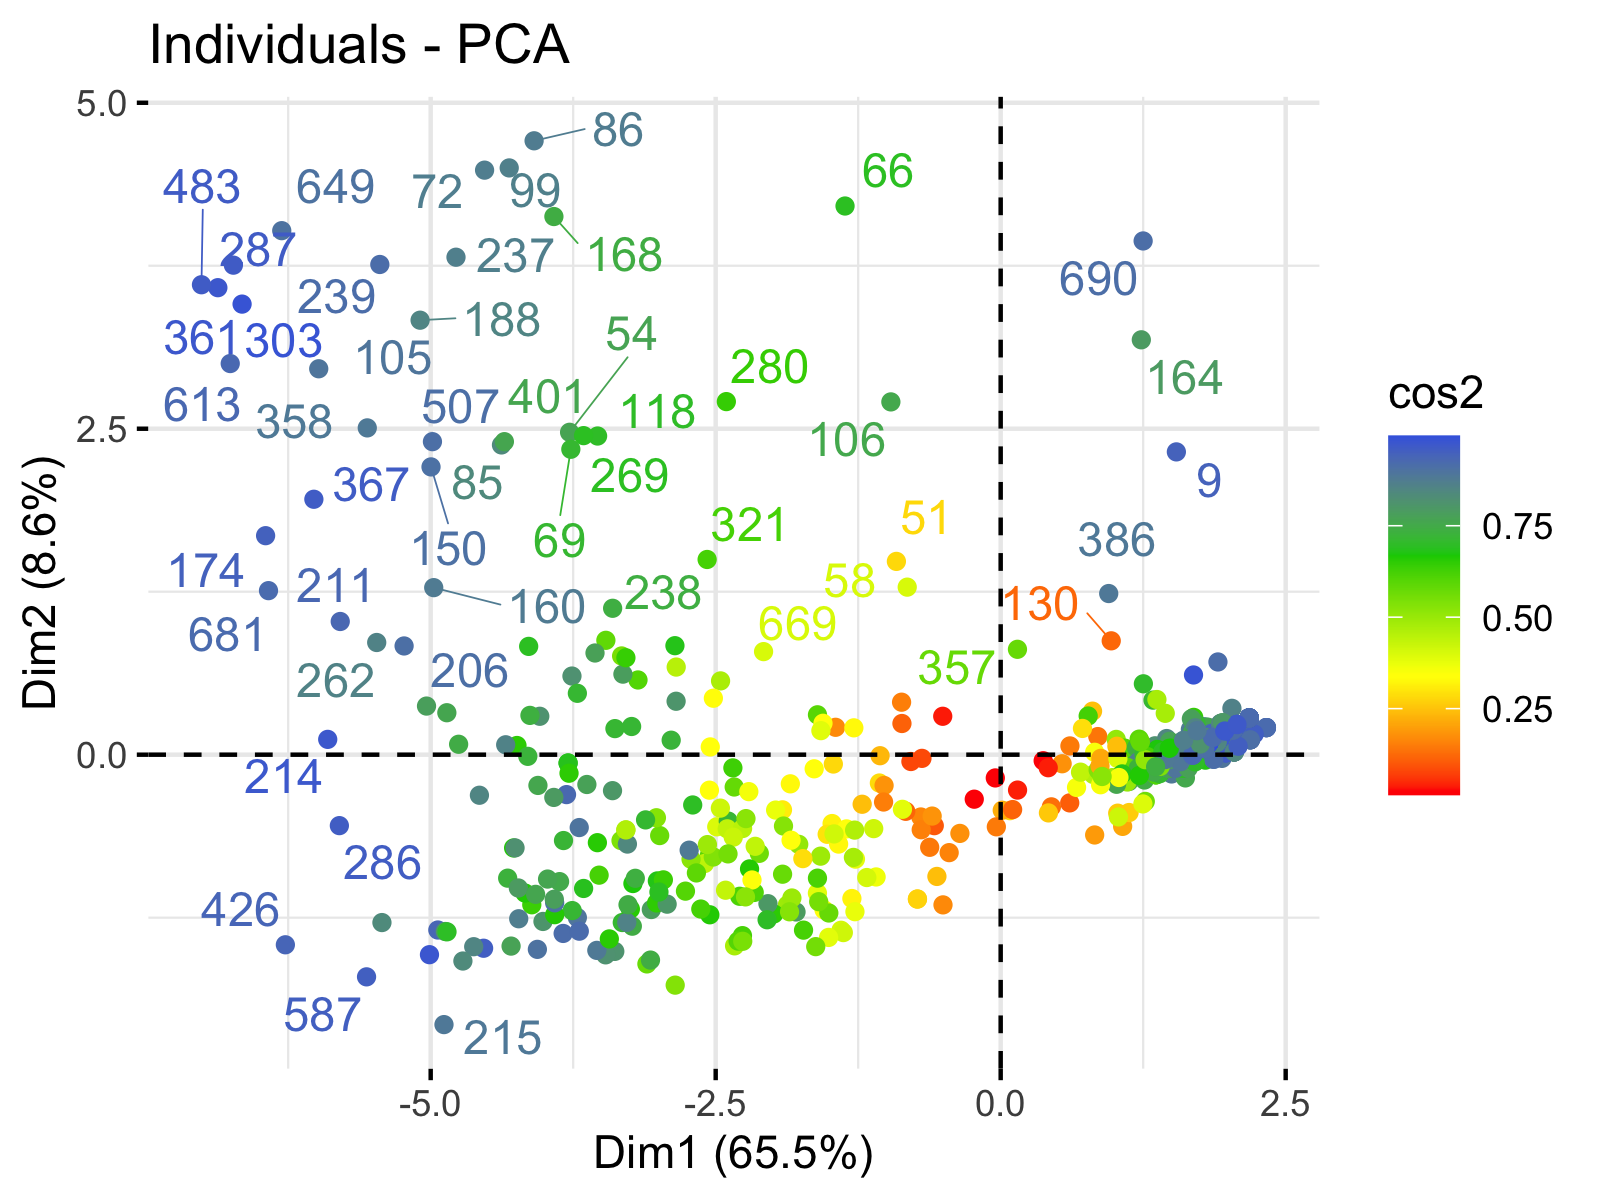
Loading plots are where most people get confused. The rotation matrix from prcomp() shows loadings, which are the correlations between original variables and principal components. A loading of 0.8 on component one means that variable has a strong positive relationship with that component. But here's the nuance: loadings and scores are different things. Scores are the transformed data points projected onto the new component space. Confusing them leads to statements like "variable X explains component 1," which isn't technically accurate. Variable X contributes to component 1 based on its loading. For visualization, the ggbiplot() function from the ggbiplot package or the autoplot() function from the FactoMineR package both work, though autoplot is generally more flexible. A standard biplot shows both observations as points and variables as arrows. The direction and length of each arrow tells you how that variable relates to the components. Long arrows mean the variable is well represented in the reduced space. Short arrows mean it got compressed away. One counter-intuitive point: high variance in a variable does not make it important in PCA. What matters is how much that variable covaries with other variables. A highly variable but independent variable can end up with low loadings on all components. I've seen people exclude variables with low variance thinking they're noise, only to discover later that those variables actually captured distinct underlying dimensions that higher-variance variables were masking.

Common mistakes that waste hours
Not checking for multicollinearity before PCA is a frequent error. If two variables are nearly perfectly correlated, PCA will essentially duplicate information across components rather than separating it. Check the correlation matrix. If you see correlations above 0.95, consider removing one of the pair before running PCA. This also speeds up computation since you're reducing redundant dimensions early. Another mistake is rotating components without reason. Unlike factor analysis, standard PCA doesn't require rotation, and rotating principal components actually changes their interpretability in ways that may not match your goal. If you need rotated components for interpretability, you're probably doing exploratory factor analysis instead. Both can be done in R, but the packages and approach differ. And don't forget to back-transform when you need to. If you're using PCA for downstream regression or classification, you feed the component scores into your model, not the original variables. Interpreting coefficients from a model built on component scores requires converting back through the loadings matrix, which most people skip and then can't explain their results to stakeholders.
When PCA in R just won't cut it
Linear PCA fails when your data has nonlinear structure. I've worked with customer segmentation data where the natural groupings formed curved manifolds rather than along linear axes. Running standard PCA on that data produced components that mixed multiple meaningful patterns together. In those cases I switched to kernel PCA or t-SNE, though those come with their own trade-offs around computational cost and reproducibility. Mixed data types are another hard limit. PCA requires numeric input. If your dataset has categorical variables, you need to encode them first, and the encoding choice affects the result in non-trivial ways. Multiple correspondence analysis exists for categorical data, but it's a different technique entirely and the R implementations are less polished than prcomp(). Finally, PCA doesn't handle missing data natively in prcomp(). You can't pass a dataframe with NAs and expect it to work. You have to impute or remove rows, and the choice between listwise deletion and imputation can shift your results enough to change conclusions. For moderate missingness, median imputation per variable is fast and usually acceptable. For larger gaps, consider the mice() package, though it adds significant runtime to the preprocessing step.
The fact that Pca Analysis In R is straightforward to code is almost its biggest drawback. It's easy to run without thinking critically about whether the assumptions hold, the data is appropriate, or the results are interpretable. I've seen good analysts produce technically correct but practically useless PCA results because they treated it as a black box. The code takes thirty seconds. The thinking takes longer.