Working with PDF Coffee – What It Actually Does and Where It Falls Apart
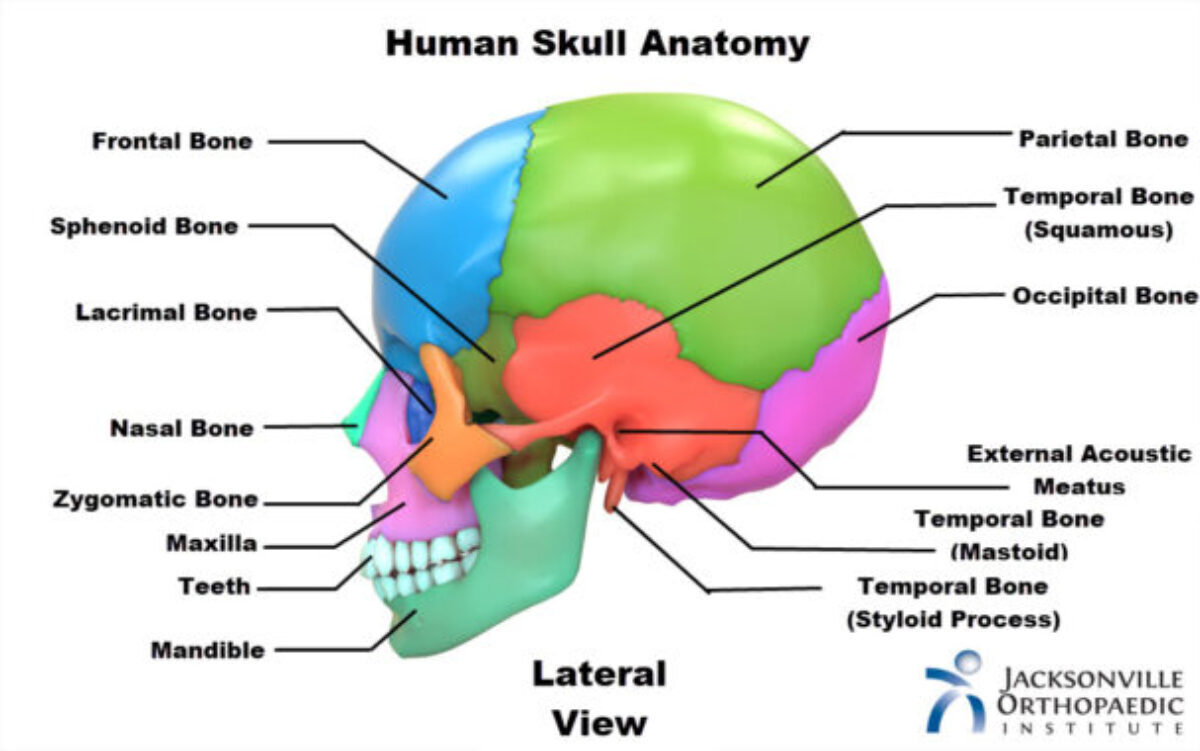
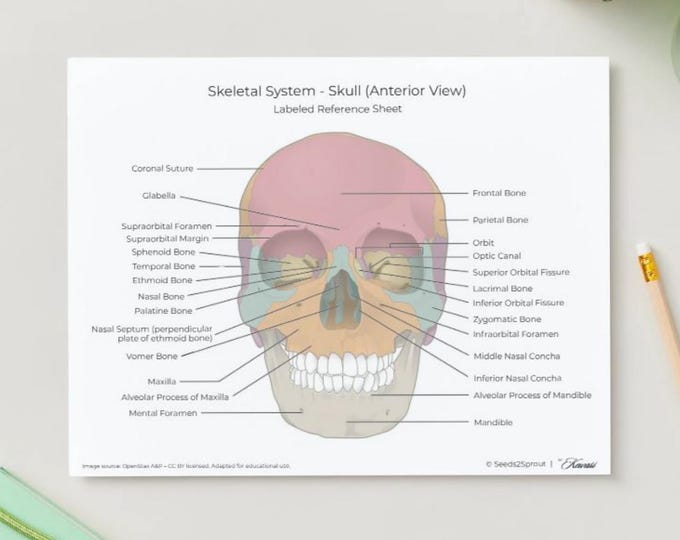
I've spent a decent amount of time with PDF Coffee over the years. It is a free online toolkit for converting between PDF and other formats, splitting files, merging them, and doing basic editing. The interface is straightforward. You upload, you select a function, you download. It does not try to be anything other than what it is. I ran into this exact search phrase once on a support thread. Nobody could explain it. The reality is pretty plain: the skull icon or logo appears as one of the visual identifiers across several of their tool pages. People see it, they remember it, and then they type it into Google hoping it means something technical. It does not. It is branding. The actual product is just a PDF utility suite. The useful part is the converter engine underneath. PDF Coffee handles most common format pairs — Word to PDF, Excel to PDF, images to PDF, and the reverse operations. It also does merge, split, compress, and watermark operations without requiring an account for basic use.
How I Actually Use It In Practice
My workflow usually involves batch conversion for a stack of scanned receipts or legacy Word documents. I upload multiple files, let it convert to PDF, then download the ZIP. The process typically takes less than three minutes for a batch of twenty files under five megabytes each. For anything larger, things slow down noticeably. I also use the split function when a client sends me a single combined contract and I need individual pages for separate filing. You can specify page ranges. It works cleanly for that purpose. One thing I learned the hard way: PDF Coffee runs everything server-side. Your files leave your machine and go to their processing servers. If you are handling anything with sensitive content, you should be aware of that. The privacy policy is standard for this type of tool, but it is still third-party processing. For personal documents or public materials it is fine. For legal or financial documents with PII, I recommend looking at local tools instead.
A Specific Problem I Encountered And The Workaround
Last year I was converting a set of approximately forty high-resolution engineering drawings from PDF to JPEG. The output quality dropped significantly on the ones that contained complex vector shading. Colors looked washed out and some fine line work became muddy. The issue was not the source files. PDF Coffee defaults to a lower resolution preset for image-heavy documents to keep processing times reasonable. The workaround was to first compress the original PDFs to reduce file size using a different tool, then re-upload for conversion. The second pass forced the engine to allocate more processing budget per page and the output quality improved enough to be usable. It added about eight minutes to the overall job, but the alternative was redrawing the affected pages by hand. I also found that checking the file after download and comparing page count is essential. Once I uploaded a thirty-page PDF and received back a twenty-two-page result. A few pages were skipped silently. I do not know why. The support team did not have a clear answer. I now verify page counts before considering any job complete.
Get the Full Details
Where It Fails and What I Use Instead
PDF Coffee has clear limits. The free tier enforces file size caps that vary depending on traffic conditions. During busier periods I have seen those caps tighten noticeably. There is also no programmatic API for the free version, so if you need to automate anything, you are out of luck. For bulk automation, I switched to using command-line tools like ImageMagick for image-based conversions and LibreOffice headless mode for document conversion. Those run locally, respect privacy, and can be scripted. They take longer to set up initially, maybe two or three hours of configuration depending on your environment, but they pay off after the first handful of jobs. Another limitation worth noting: PDF Coffee does not reliably handle OCR on scanned document uploads. If you upload a flat image-based PDF, it will convert the format but it will not add searchable text. I encountered this when a colleague sent me a scanned archive and expected text extraction. Nothing happened. The tool simply does not include OCR in its free tier.
Practical Tips That Actually Matter
If you are going to keep using this tool, a few things will save you time. Name your files clearly before uploading. The system sometimes returns mixed-up filenames when processing multiple files, especially if the originals share similar names. I learned this after losing an afternoon tracking down mislabeled documents. Keep your source files under twenty-five megabytes when possible. Above that threshold, upload times increase and the quality of output begins to degrade on certain file types. I usually run a quick compression pass before uploading anything that large. Use the merge function sparingly. It works, but I have seen it corrupt the bookmark structure in complex PDFs with nested outlines. If your document relies on bookmarks for navigation, merge the files first as a test with a small sample, then apply the same operation to the full document.
Bottom Line
PDF Coffee is functional for light, everyday PDF work. It handles basic conversions and manipulations without requiring payment or registration. It is not built for enterprise workflows, sensitive documents, or heavy automation. The skull branding is irrelevant to the actual functionality. Knowing the tool's limits upfront will save you more time than any tutorial could. For occasional use it is acceptable. For regular production work, local alternatives with proper API support and offline processing are worth the initial setup time. The difference between the two approaches becomes obvious after your third failed batch or your first privacy concern.