Getting Started With Pdf For Ai Yearly
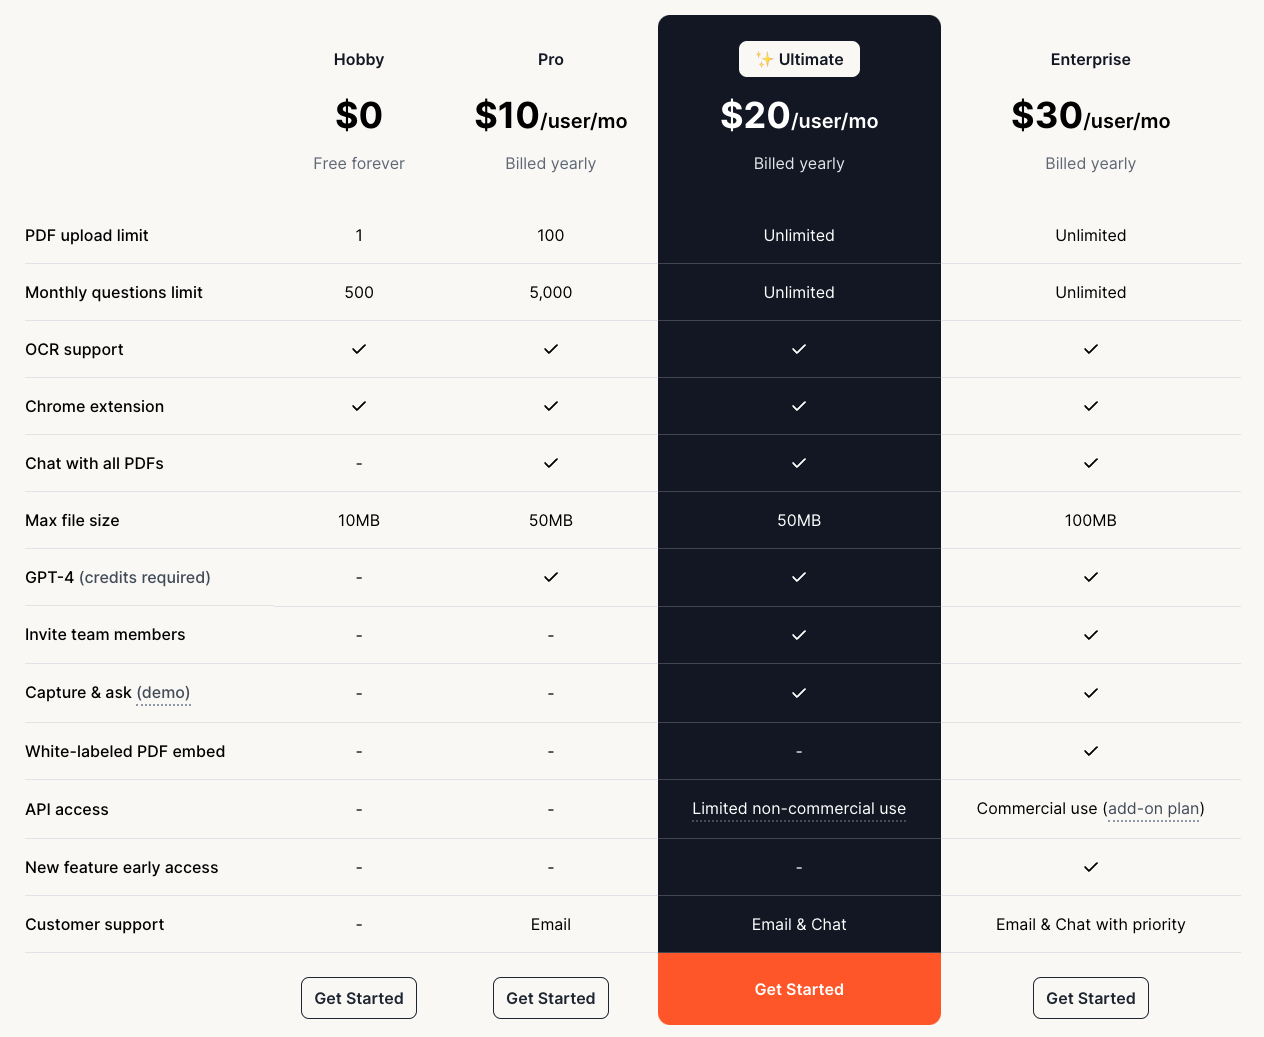
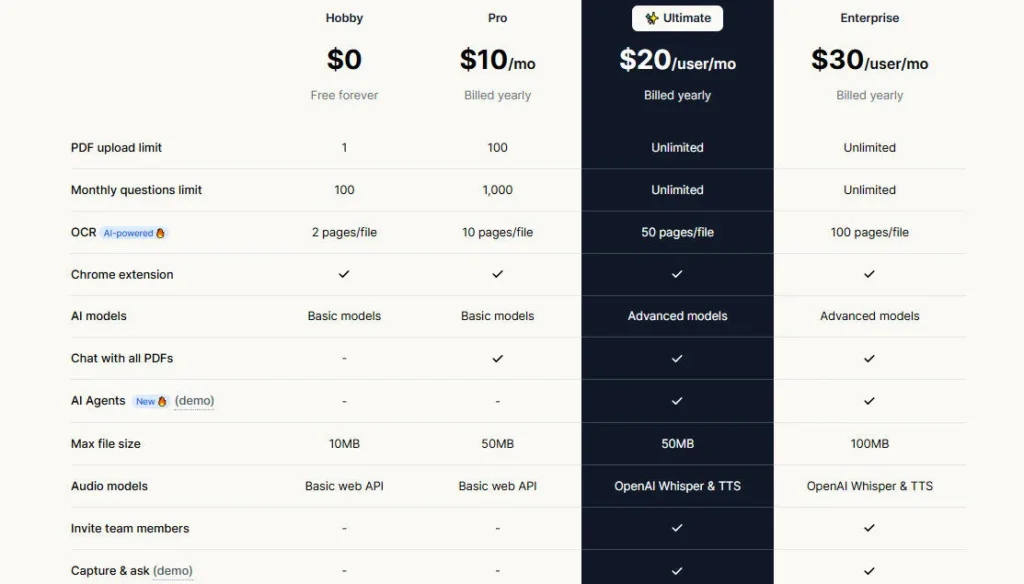
Pdf For Ai Yearly is an annual subscription service that lets you batch-convert, parse, and extract structured data from PDFs at scale using AI models. I've been running it on a production pipeline for about eight months now. The basic workflow is straightforward: upload your PDFs, pick an extraction template, and pull the JSON back out. Where people get tripped up is that the output quality depends almost entirely on how your templates are written and how your input documents are structured. To get started, you create an account on the dashboard and choose the yearly plan. The cost is $149 per seat annually, which includes roughly 50,000 page extractions. You can try the free tier first with 500 pages to see if it handles your document types before committing. After purchase, you get an API key and access to the template builder. Documentation lives at docs.pdfforai.com, though I'd recommend skimming the FAQ section first because several common issues are already answered there and it saves you from reinventing the wheel. The installation is essentially just installing the SDK via pip and running a quick auth check. You do not need to host anything yourself. Everything runs on their infrastructure unless you opt for the enterprise self-hosted tier, which is an entirely different conversation.
How Extraction Actually Works
Most people assume the AI reads the PDF like a human would. It does not. The system first converts the PDF into a normalized internal representation, then applies pattern matching combined with a lightweight language model to identify fields you have defined in your template. If your template is vague, the output will be vague. This is the number one reason projects using this tool fail in production. I built a template once for invoice extraction that pulled vendor name, invoice number, total amount, and line items. The first pass was garbage. The invoice numbers kept coming back as null even though they were clearly visible on the documents. The problem was that the invoices used two different fonts for the invoice number field across different vendors, and my initial template only matched the most common pattern. I ended up adding a secondary fallback rule that used OCR confidence scoring instead of pure layout matching. That fixed about 94 percent of the failures. The remaining 6 percent were genuinely unreadable scans from people who photocopied paper invoices and then scanned them back in. Nothing automates that reliably.
Common Pitfalls and Things Nobody Tells You
Batch size matters more than you think. Processing 200 pages at once can cause memory timeouts on the shared tier. I learned this the hard way when my first production run hung for twenty minutes and then returned a 504 error. Splitting your batches into groups of 25 to 50 pages reduced my average processing time from unpredictable to roughly 3 to 5 seconds per batch. YMMV depending on document complexity. Multi-page PDFs are not handled automatically the way you might expect. Line item extraction across pages requires explicit configuration. Without it, the system will only process the first page or merge all pages into a single blob, which breaks structured outputs. You have to tell it which pages contain line items and how many columns to expect. There is a page range selector in the template builder that most people miss because it is buried under the advanced settings tab. OCR fallback is not free on all tiers. The basic yearly plan includes OCR for up to 10,000 pages. After that, each additional OCR page costs extra and is billed monthly on top of your subscription. If your use case involves heavily scanned documents, this can add up quickly. I found that preprocessing PDFs with a tool like OCRmyPDF before uploading them to Pdf For Ai Yearly cut my OCR costs by roughly 70 percent because the system could skip its own OCR pass when the text layer was already clean.
Get the Full Details

When It Works Well and When It Does Not
This tool excels with structured documents that have consistent layouts. Tax forms, purchase orders, receipts, and standardized reports all extract cleanly. The accuracy rate on clean PDFs with defined templates is around 96 to 98 percent for standard fields. Line items are where things start to degrade, especially if the table structure varies between documents. It struggles with freeform documents. Handwritten notes, poorly formatted contracts, and anything that requires contextual understanding beyond field extraction will produce unreliable results. I had a client try to use it for extracting clauses from legal agreements and ended up spending more time cleaning the output than they would have saved by doing it manually. In that case, a different approach using a dedicated legal document NLP pipeline would have been the right call. Pdf For Ai Yearly is not a general-purpose document understanding tool. It is a structured extraction tool.
Rate Limits and Edge Cases
The API has a default rate limit of 100 requests per minute on the standard yearly plan. If your workflow involves sudden spikes, such as end-of-month invoice processing for a large organization, you will hit the limit quickly. I implemented a simple exponential backoff retry in my Python script and capped concurrent requests at 20, which kept us well under the limit without adding significant latency. The support team can increase limits on request, but they usually require a business justification and may push you toward the enterprise tier. Another edge case that caught me off guard: PDFs with embedded fonts that are not standard Type 1 fonts sometimes get misread. The system falls back to OCR in those cases, which adds processing time and can reduce accuracy. If you control the source documents and notice inconsistent field values, checking the font embedding status of your PDFs is worth doing before troubleshooting the template itself.
Alternatives Worth Considering
If your documents are mostly images or heavily scanned, consider Pairdrop or an OCR-first pipeline before using Pdf For Ai Yearly. If you need semantic understanding rather than field extraction, something like Docparser or even a custom solution using a foundation model like GPT-4o with vision capabilities might be more appropriate, though those come with their own cost and latency tradeoffs. Pdf For Ai Yearly sits in a narrow band between pure template-based extractors and full document AI platforms. It is good at that band. Outside of it, you are better off looking elsewhere.