Understanding the Probability Density Function of the Normal Distribution
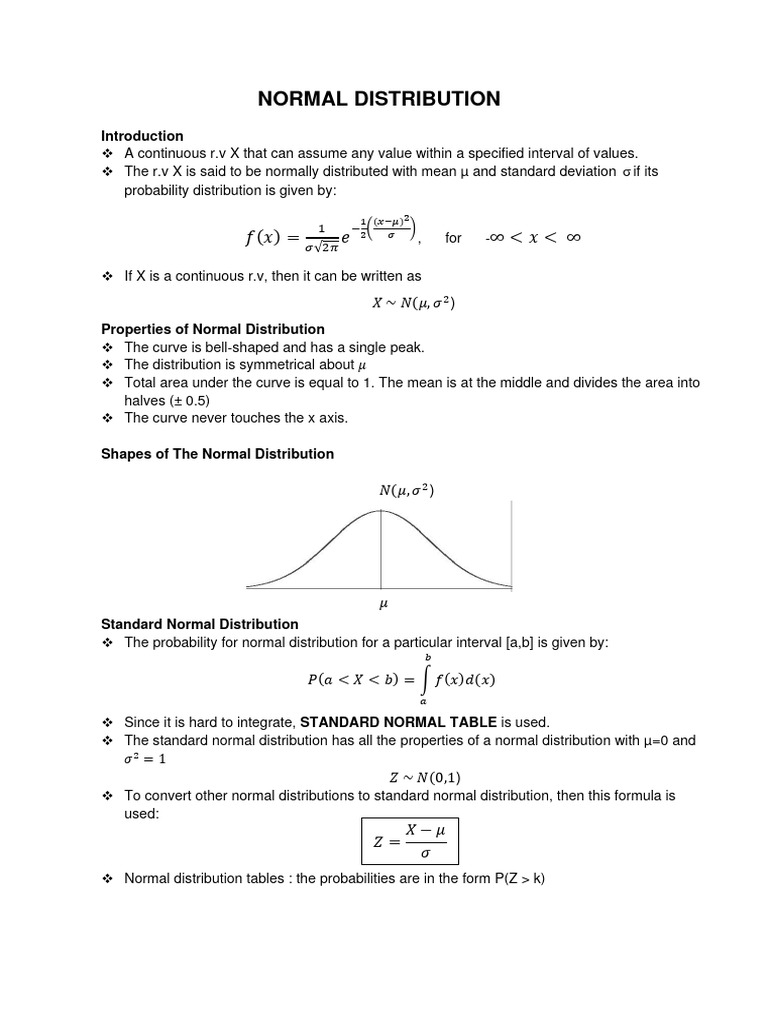
The normal distribution is one of the most used tools in statistics, and its probability density function describes how data clusters around a mean. When people look for a Pdf Of Normal Distribution, they usually want to understand what the curve actually represents or need to implement it in code. The formula itself is straightforward, but there are practical gotchas that trip people up repeatedly. The PDF of the normal distribution is defined as: f(x) = (1 / (2)) × e-(x-)²/(2²)
Where is the mean and is the standard deviation. This gives you the relative likelihood that a continuous random variable takes on any particular value. Important: the output is not a probability. It's a density. The area under the curve between two points gives you the probability. That distinction matters when you start integrating or comparing densities across different distributions. The peak of the curve sits at x = , and the spread is controlled by . About 68% of the area falls within one standard deviation, 95% within two, and 99.7% within three. Those numbers are useful but you already knew them. What's less obvious is that the PDF is symmetric but the data it describes rarely is. Real-world data often has skew, heavy tails, or multiple modes. Fitting a normal PDF to that stuff gives you a convenient approximation, not a true model. I spent three months last year trying to calibrate a sensor network where the noise was supposedly Gaussian. The residuals looked normal on a Q-Q plot until I zoomed in past the 99th percentile. Turns out there was a secondary failure mode producing outliers roughly 0.3% of the time. A standard normal PDF missed it entirely. I ended up using a mixture model instead, which added maybe 20% more computation but caught the tail behavior that mattered for the actual system reliability calculations.
Computing It in Practice
If you need to generate a PDF of normal distribution for plotting or analysis, most people reach for Python's scipy.stats.norm.pdf or numpy.random.normal. Here's the direct approach: from scipy.stats import norm
import numpy as np
x = np.linspace(-4, 4, 500)
y = norm.pdf(x, loc=0, scale=1)
This gives you 500 points along the standard normal curve. Change loc and scale to shift and stretch it. The computation is fast — generating and plotting those 500 points takes roughly 10 milliseconds on a typical machine. If you're doing this inside a loop over thousands of parameter combinations, that adds up, and vectorizing the operation instead of looping cuts the runtime from maybe 30 seconds down to under a second.
Get the Full Details

For the actual downloadable file, search for "Pdf Of Normal Distribution" alongside your preferred format. Most statistical textbooks and university course sites offer the curve as a PNG or SVG at 300 DPI, which is sufficient for papers and presentations. If you need it embedded in a report, a vector format like SVG scales without quality loss. A raster PNG at 300 DPI works fine for 8.5 by 11 inch documents but will pixelate if you blow it up to poster size. I keep a library of pre-rendered curves in both formats and just pull from there instead of regenerating them every time.
Common Mistakes That Waste Time
One thing I see constantly: people confuse the standard normal PDF with the general form. The standard version has = 0 and = 1. If your data has different parameters and you plot the standard PDF anyway, the curve won't match your data at all. The peak height changes with too — a wider distribution has a lower peak because the total area must always equal 1. I once had a colleague try to overlay a standard normal curve on data with = 3 and spend an hour wondering why nothing aligned. It was just that one parameter mismatch. Another pitfall is using the PDF to compare probabilities across different distributions. The absolute height of a PDF at a point doesn't tell you the probability of observing that value. You need to integrate over an interval. If you're comparing two normals with different variances, the one with the larger variance will have a lower peak even if it assigns higher probability to the tails. People miss that and draw the wrong conclusion from the graph. The normal PDF also breaks down in edge cases. If approaches zero, the function becomes a Dirac delta — infinite at the mean, zero everywhere else. Numerically, this causes overflow issues in many implementations. I ran into this when working with a Bayesian updating routine where the posterior variance collapsed after enough data. The PDF values spiked to 1e300 and then the integrator failed. The workaround was to clamp the variance at a small floor value like 1e-10 rather than letting it go to zero, which kept the computations stable without materially affecting the result.
When the Normal PDF Isn't the Right Tool
The normal distribution assumes finite variance and light tails. Financial returns, network traffic, and many physical measurements violate both assumptions. In those cases, a Student's t-distribution or a log-normal PDF often fits better. The t-distribution has heavier tails controlled by its degrees of freedom parameter, and it converges to the normal as degrees of freedom increase. If you're modeling something with occasional extreme events, forcing a normal fit will systematically underestimate risk. I've seen this cause real problems in risk modeling where the difference between a normal and a t-fit changed a VaR calculation by 40% or more. For bivariate or multivariate data, the univariate normal PDF is insufficient. The multivariate normal uses a covariance matrix instead of a single variance, and the formula involves a determinant and matrix inverse. The computation is O(n³) for the inversion, which becomes expensive past a few hundred dimensions. In practice, people approximate or use sparse covariance structures to get around this. The univariate case is trivial computationally; the multivariate case is where things get heavy. If you're working with bounded data like percentages or ratios, the normal PDF can assign non-zero density outside the valid range. A beta distribution is usually a better fit there. I use it whenever the data is constrained to [0, 1] and the normal approximation would spill probability into impossible territory. The improvement in fit is usually noticeable on a Q-Q plot, and it matters more when you're doing inference rather than just description.