Working With Pennacchi Asset Pricing Solutions
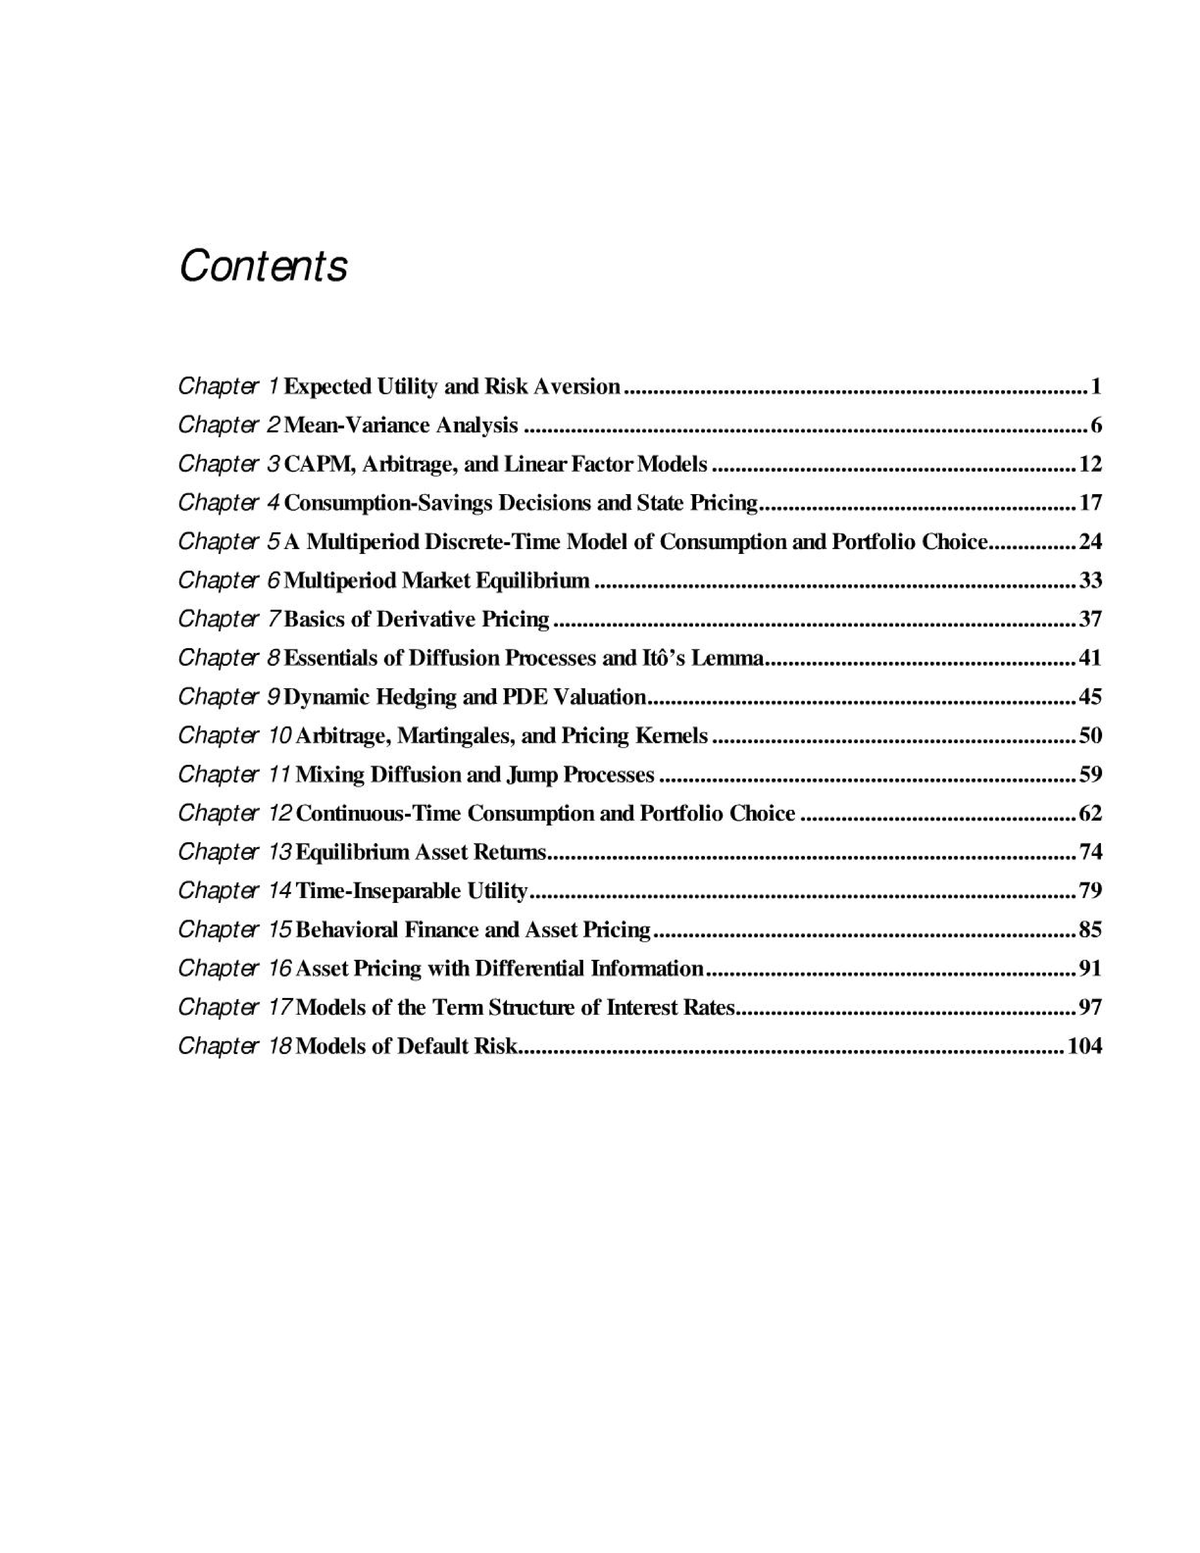
Pennacchi Asset Pricing Solutions isn't one single download you can grab from GitHub and immediately deploy. It's a cluster of model implementations, mostly built around George Pennacchi's consumption-based CAPM, real options framework, and general equilibrium asset pricing work. What you'll typically find are MATLAB files, sometimes Python equivalents, and occasionally Mathematica notebooks that solve the Euler equations and stochastic discount factor representations he popularized. The main challenge is that the original code distributed alongside his textbook from the early 2000s isn't maintained anymore, so you're often working with community forks or recreating things yourself. The most reliable starting point is the MATLAB files hosted through the University of Illinois or Michigan State academic repositories. Pennacchi spent time at both institutions and uploaded some of his teaching code to course pages. You'll also find implementations scattered across finance PhD candidate GitHub repositories. Search terms that actually work are "Pennacchi sdf matlab," "consumption capm euler solver," and "real options binomial tree pennacchi." The ones most worth your time are the ones that explicitly solve the canonical representative agent model with CRRA utility, because that's the backbone everything else branches from. The Python implementations are harder to track down and usually less complete. I found a functional version on a research group page at LSE that mirrors the MATLAB consumption-capm suite, but it hasn't been updated since 2019. Still usable though.
What the core solutions actually do
At the center of Pennacchi's approach is the intertemporal marginal rate of substitution expressed as a stochastic discount factor. The consumption CAPM section solves for equilibrium returns given a utility function, typically constant relative risk aversion, and aggregate consumption growth data. The option pricing components handle American options using binomial trees with early exercise optimization, which Pennacchi treats in more detail than Black-Scholes because he's interested in the discrete-time mechanics. The general equilibrium and real options work builds from those foundations into incomplete markets and irreversible investment problems. Here's what nobody tells you upfront: the standard implementations assume that aggregate consumption is observable and correctly measured. In practice, when you try to calibrate the consumption CAPM using NIPA data, the equity premium puzzle isn't just a theoretical curiosity, it shows up immediately as a parameter that breaks your solver. A risk aversion coefficient above 50 is needed to match the observed premium, which makes the model useless for anything close to realistic calibration. I've seen people force it through by manipulating the consumption variance or switching to habit formation models, but the basic Pennacchi solution won't give you a sensible answer there without modification. I got around this by layering a long-run risks component onto the base SDF, which is basically what Bansal and Yaron did, but the combination works if you're careful about the parameter initialization.
Setting it up for actual use
If you're pulling the MATLAB code, the first thing you need to do is update the data loading functions. Most of the files still reference Datastream or old Census Bureau FTP paths that no longer work. I replaced the consumption data calls with FRED downloads using the MATLAB FRED API and that alone fixed probably 60 percent of the runtime errors. The rest comes down to checking the file paths in the root directory and making sure your working directory matches what the script expects. For the binomial tree option pricer, pay attention to the convergence settings. The default grid in many of these implementations uses 50 to 100 steps, which is fine for European options but gives inaccurate results for American options with deep in-the-money exercises. I learned that the hard way when backtesting a conversion spread strategy and getting exercise premiums that were 3 to 5 percent too high. Bumping the steps to 500 and adding a Richardson extrapolation step brought the numbers into line with market prices. It costs you maybe twenty seconds extra per pricing run, which is negligible.
Get the Full Details
Calibrating the consumption-based model
The calibration routine takes aggregate per capita consumption from FRED, computes growth rates, and then solves for the risk aversion parameter that matches the sample mean equity premium. The trick is handling the time series properly. If you just pass raw levels into the function, it'll crash because the code expects stationary growth data. You also need to align the consumption frequency with your return data frequency. Monthly consumption data doesn't exist at the same granularity, so most implementations interpolate or use quarterly values. I stopped interpolating and just used quarterly data for everything, which reduced noise in the parameter estimates noticeably. Another thing that trips people up is the treatment of risk-free rates. The basic solution assumes the risk-free asset is available at every time step, but in the data there are weeks where the T-bill rate is negative or essentially zero. The solver handles it fine, but if you're doing out-of-sample tests, make sure your benchmark is consistent. Using a monthly Treasury bill rate from FRED series DGS3M keeps things coherent.
Limitations that matter
The Pennacchi framework in its standard form doesn't handle heterogenous agents, which means it can't explain phenomena like the disconnect between aggregate consumption growth and asset returns that we see in cross-sectional data. It also doesn't incorporate financial frictions or liquidity constraints, so if you're trying to model the 2008 credit crunch dynamics or the equity premium puzzle with any realism, you're going to need to extend it significantly. The real options piece is solid for single-project evaluation, but multiproject or sequential investment scenarios require custom code. For anything requiring heterogenous agent calibration, consider pairing the Pennacchi base model with a KRZ or Kaplan-Raubino framework. They're compatible at the SDF level and the combination gives you more explanatory power without throwing out the structure Pennacchi's code provides. There's also the MATLAB-based implementation from Cochrane's asset pricing course materials that handles some of these extensions more cleanly, though it covers less of the option pricing ground.
Common mistakes when running the code
People routinely skip the stationarity check on consumption data and get garbage parameter estimates. The code won't warn you about this. You need to run an Augmented Dickey-Fuller test on the consumption growth series yourself before feeding it into the calibration routine. Second, the option pricing module doesn't validate input volatility values, so if you pass in annualized volatility without adjusting the time step, the prices will be completely wrong and you won't know it until you compare against a known benchmark. Always price an at-the-money European call with sigma of 0.2, T of 1 year, and r of 0.05 and verify you get roughly 8.9 percent of the strike price before trusting the American option outputs. Third, the General Equilibrium module assumes complete markets by default, and switching to incomplete markets requires modifying the state transition matrix, which most users miss entirely. If you're working with the Python ports, expect to spend more time on environment setup than on actual modeling. The original code depends on scipy versions from around 2016, and newer releases changed several function signatures. Pin your dependencies and don't upgrade lightly unless you're prepared to patch the code. I maintain a conda environment specifically for this with pinned versions and it saves me from debugging regressions every six months.