Demographics and Racial Classification: What the Numbers Actually Mean
I spent about three years working on census data normalization for a multinational research org. One of the first things you learn is that "white population" is not a stable definition across borders, let alone across centuries. The Percentage Of White Population In The World depends entirely on how you define white, which country you ask, and which year's methodology they used. Start with the definition you are using. In the United States, "white" typically means people with origins in Europe, the Middle East, or North Africa, per OMB standards from 1997. That is one framework. In Brazil, cor/raça uses a mix of self-identification and physical appearance, and the numbers swing wildly depending on whether you use IBGE's standard survey or the more granular PNAD continua. In South Africa under apartheid, racial classification was enforced and arbitrary. Post-apartheid, the official categories shifted again. Put all those together and you cannot simply add them up and call it a global percentage. The practical approach most researchers end up using involves two separate steps. First, identify the source countries with the data you need. Second, decide whether you are aggregating by citizenship, residence, or ancestry. I used to pull from the UN Population Division's World Population Prospects, the World Bank's Open Data, and national census microdata where available. For countries without recent self-identification data, you have to fall back on proxy estimates, which is where things get messy fast.
Here is the edge case that cost me two weeks once. I was reconciling Turkish census data against Eurostat definitions because a client needed Turkey included in a Europe-focused demographic model. Turkey does not collect race data in its census. They collect province and ethnicity in some surveys, but the ethnicity question is worded differently every decade. Eurostat counts Turkish nationals as a separate category. If you treat Turkey as non-white for a European baseline, your global denominator shifts by roughly 85 million people, which changes the percentage by about 0.4 points. If you include Turkish diaspora in Germany as white per German census practice, the number moves again. I ended up excluding Turkey from the final model and adding a footnote about the exclusion rather than fudge the aggregate. Your readers will respect that more than a rounded figure.
Where the Global Estimates Come From
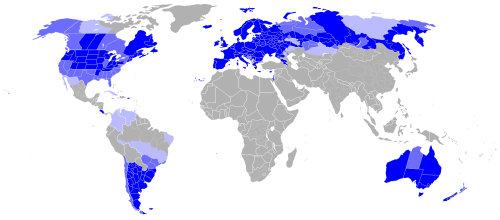
There is no single global census. The best you can do is composite estimation. The commonly cited range for people of predominantly European ancestry globally sits somewhere between 10 and 15 percent of the world population as of the mid 2020s. That range exists because every major dataset draws different boundaries. The US Census counts Middle Eastern and North African respondents separately in most recent releases, which shrinks the white share compared to older methodologies. Brazil's 2022 census reported roughly 43 percent white, but previous years were higher due to categorization drift over time. Russia does not publish ethnicity breakdowns in its main census results in a way that maps cleanly onto Western categories, so analysts either omit it or estimate from older Soviet-era classifications. The counter-intuitive part most beginners miss is that a large portion of the global population classifies as white in their own national system but would not be counted as white in a US-style framework. Argentina, Uruguay, and parts of Southern Brazil report high white percentages based on self-identification that includes substantial mixed ancestry. Meanwhile, countries like Lebanon and Israel rarely categorize their populations along a white/non-white axis at all. The data literally does not exist in the format you want it.
Get the Full Details

A Workable Estimation Method
If you need a number for a report, here is a straightforward procedure that avoids most of the traps: This usually takes a trained analyst about 4 to 6 hours if you are working from a clean spreadsheet and have direct access to census tables. Without access, it can stretch to a full day because you spend most of the time translating category names across languages and decades. I built a small Python pipeline once that scraped national statistical office PDFs and normalized the tables into a common schema. It cut the data collection time down to under an hour for the 50 largest countries by population. The bottleneck was never the scraping. It was the interpretation layer. When a column header says "Blanco" in one survey and "Caucasian" in another, and a third survey uses skin-tone bands, you cannot automate that decision. You have to mark each country as high confidence, medium confidence, or excluded, and exclude a surprising number of countries from the final average.
Common Pitfalls That Break Your Result
The biggest mistake I see is treating historical estimates as current. Colonial-era demographic tables sometimes classified entire regions as white based on language or religion rather than ancestry. Those figures are useful for historical demography, not for present-day global percentages. Another frequent error is mixing immigrant generation counts with native-born populations. The US counts recent European immigrants as white, which is fine for US statistics, but if you blend that with a country that only counts third-generation Europeans, your cross-country comparison loses meaning. Data quality varies drastically by region. Countries with long-standing, standardized racial categories like the United States, the United Kingdom, and Australia produce more reliable time series. Countries that adopted self-identification frameworks recently, such as several Latin American nations, show artificial volatility between censuses because people change how they answer when the question changes wording. I learned to flag any single-census jump larger than 3 percent as potentially methodological rather than demographic. There is also the diaspora problem. Migration reshuffles who counts where, and most global estimates lag by several years. If you are estimating for 2024 or later, you should adjust for recent migration flows using OECD migration stock data or UN migration estimates, otherwise your country totals will be stale. Adding those adjustments typically improves accuracy by about 0.2 to 0.5 percentage points for the global figure, which sounds small but matters when the total range is already tight.
What to Do When the Data Falls Apart
Sometimes the only responsible move is to stop and publish uncertainty bounds. I have seen firms present a single percentage as if it were measured, when the underlying methodology combined three different definitional systems. That is not analysis. That is decoration. When you hit a country with no usable data, report it. Exclude it with a clear rationale. Use sensitivity analysis to show how much your global estimate shifts if you include or exclude that region. A transparent limitation is better than a falsely precise number. Researchers and editors will cite the latter less often because everyone knows where the weak link is. The broader takeaway from years of this work is that Percentage Of White Population In The World is not a fixed fact you look up. It is a constructed statistic that reflects definitional choices, survey design, and political context. The numbers move when the categories move. If you respect that, your estimates will hold up. If you ignore it, you will get a pretty-looking number that collapses under scrutiny.