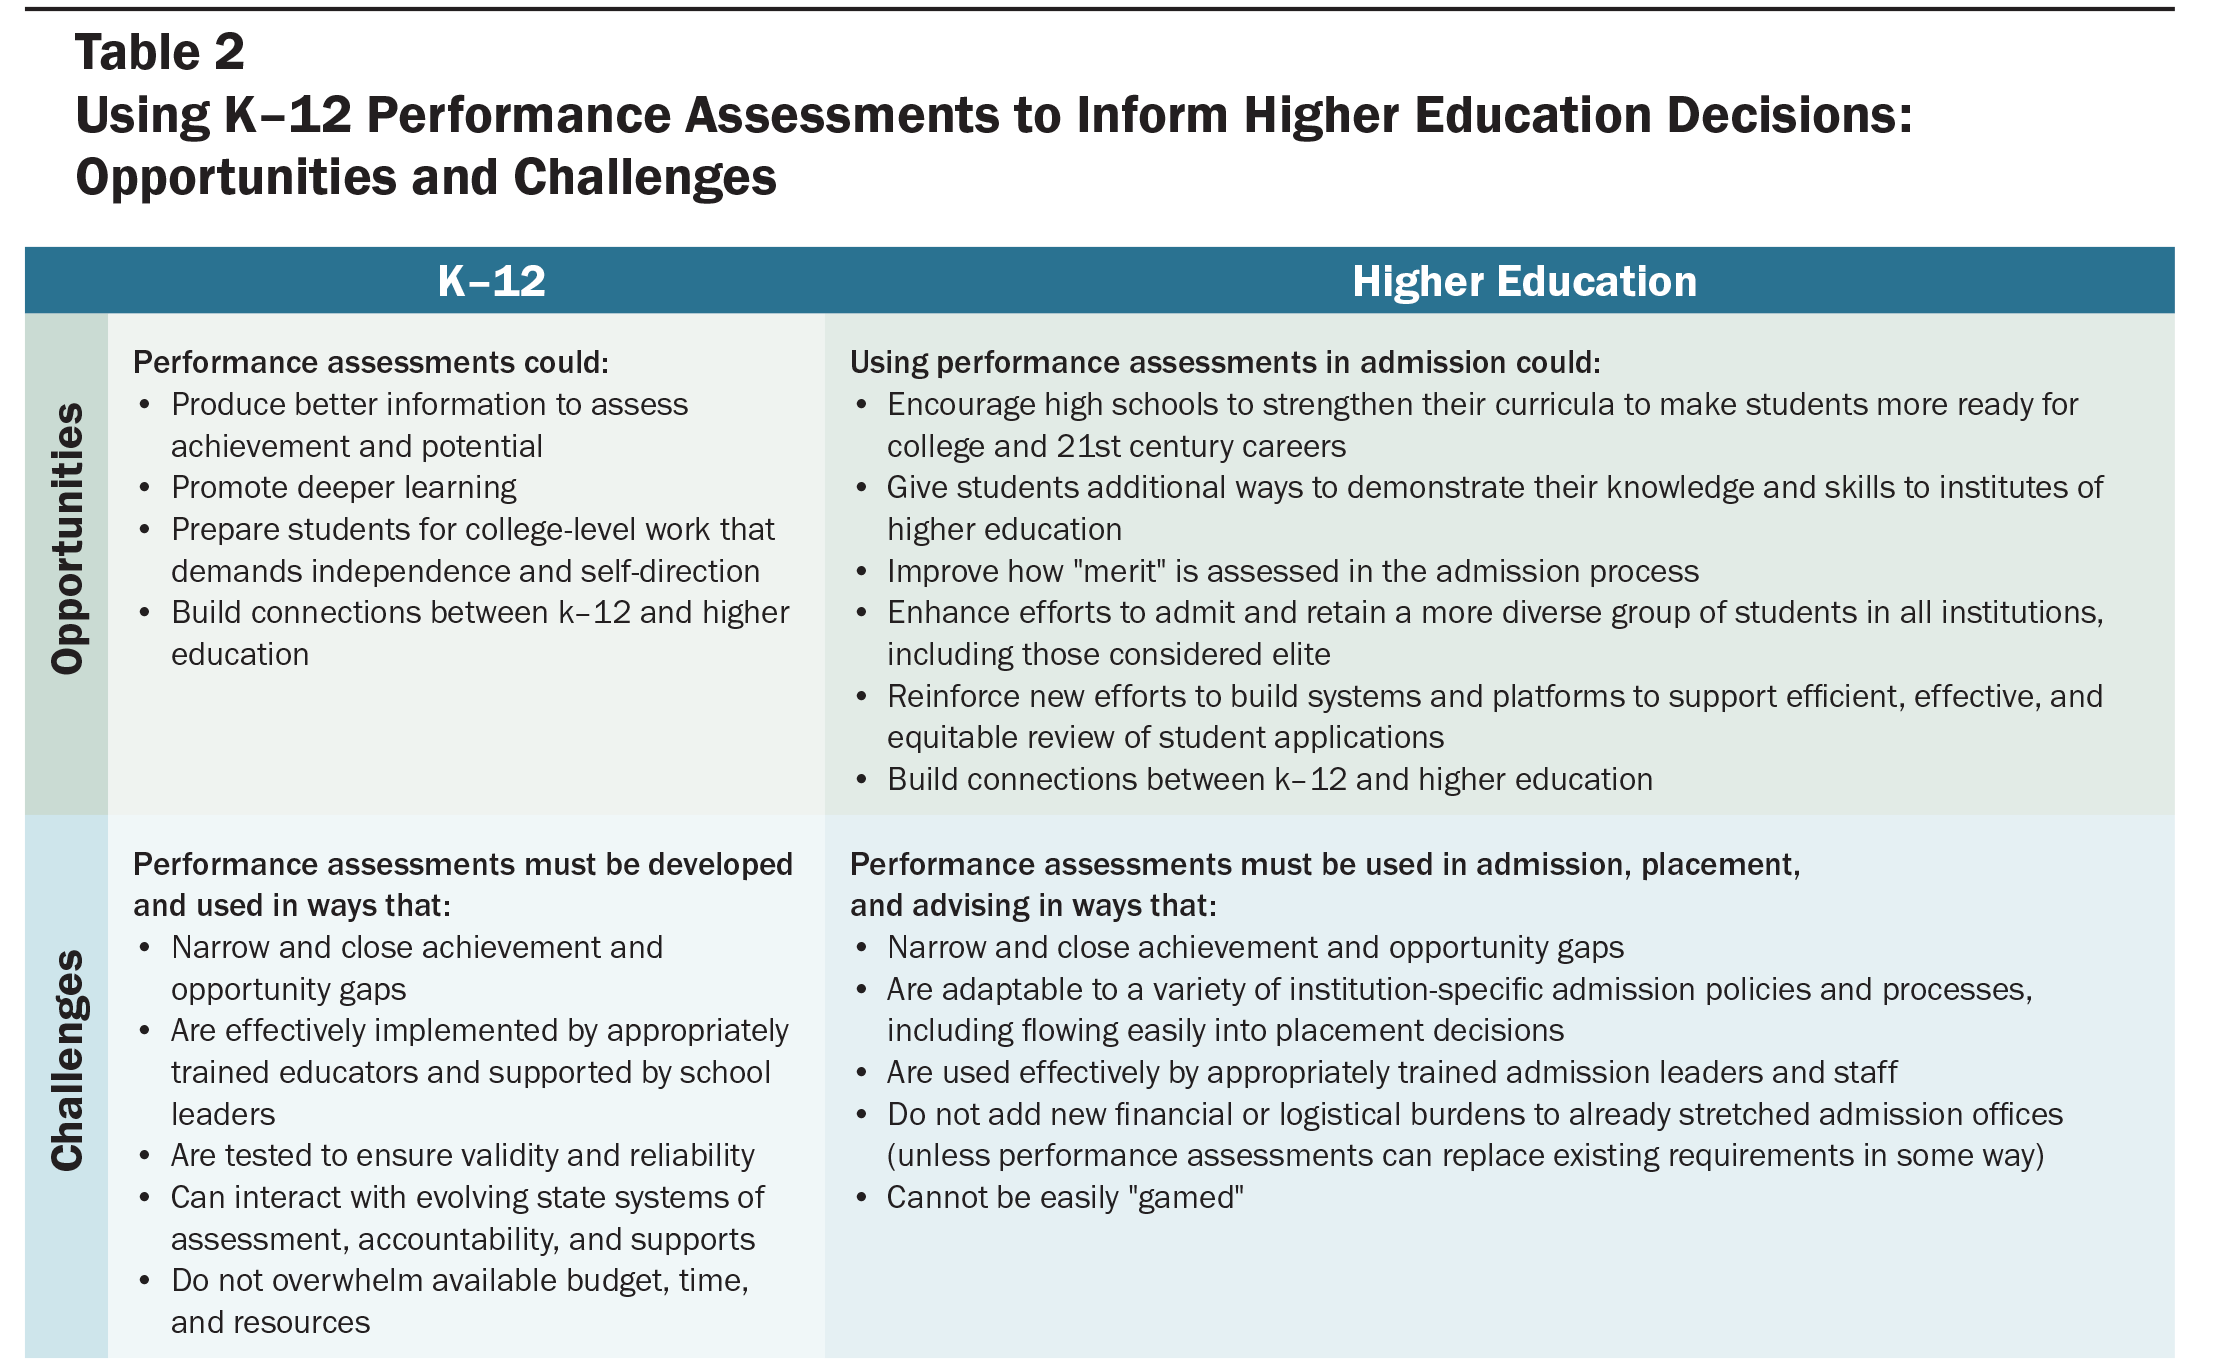
Why Most Performance Assessments Fail Before They Start
Performance Assessment In Education is often treated like a buzzword in admin meetings. Teachers get a slide deck, a rubric template from a district consultant, and told to implement it by next semester. Two weeks later, half the assignments are being graded on a curve anyway because the scoring rubric produced a bell curve that looked wrong, and the other half became performative busywork where students spent more time producing a polished final product than demonstrating actual learning. The core problem isn't the concept. It's the execution. A performance assessment is any evaluation that requires a student to demonstrate knowledge through action rather than selection or recall. That sounds simple enough. The complication is that "demonstration" in practice usually collapses into one of two traps: either the task is so open-ended that grading becomes subjective guesswork, or it's so tightly scripted that it's just a multiple-choice question wearing a costume.
What Performance Assessment In Education Actually Looks Like
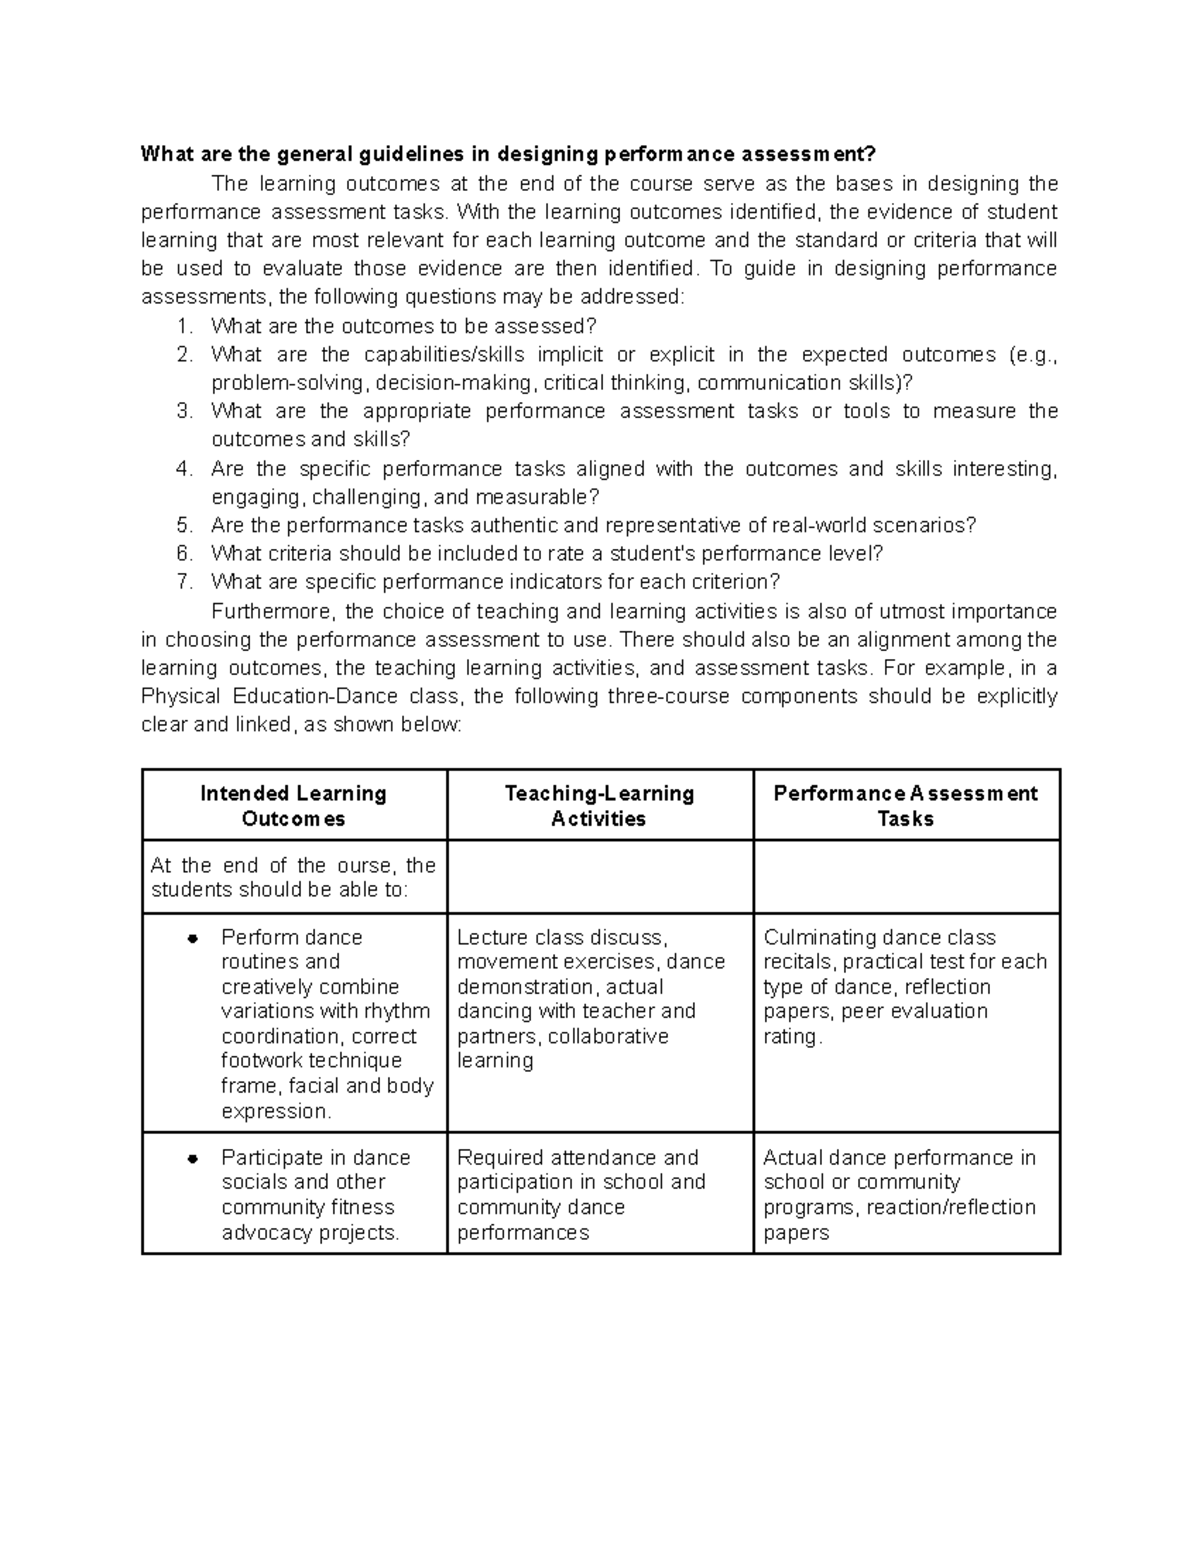
At its best, it measures whether a student can apply knowledge in a context that mirrors real use. A chemistry student who can balance equations on paper but can't identify which reagent caused the unexpected precipitate in a lab hasn't demonstrated chemistry fluency. A history student who can date events on a timeline but can't construct a sourced argument about causation hasn't demonstrated historical thinking. The assessment format needs to require the same cognitive moves that the domain demands. This means designing tasks around authentic performance conditions. Not "authentic" as in theming a worksheet around a local government scenario. Authentic as in the student encounters the same kind of constraint, ambiguity, and material that a working practitioner in that field encounters. An engineering student should work with incomplete specs. A writing student should receive a real audience with real expectations. A language learner should need to negotiate meaning in conversation, not fill in blanks from a scripted dialogue.
Designing a Rubric That Doesn't Collapse Under Its Own Weight
Rubrics are the single most common failure point. I've watched entire departments spend three months refining a five-criteria rubric for a senior capstone project, only to discover that when they tried grading a real batch of student work, two of the five criteria produced inter-rater reliability below 0.65. That means two trained graders looking at the same submission would disagree more than they'd agree. The rubric wasn't measuring student performance. It was measuring ambiguity. The fix starts with anchor samples. Before you write a single rubric criterion, collect three to five student works spanning the full performance range — exceptional, adequate, and inadequate. These become your calibration set. Score them yourself first. Then have two other trained graders score the same set independently. Compare where you disagree. Every disagreement point is a rubric criterion that needs rewording, collapsing, or removal. I once designed a portfolio-based assessment for a first-year writing course that required students to submit a research paper with annotated drafts, a revision memo, and a self-assessment. The rubric had seven criteria. After the first grading round, inter-rater reliability was 0.58. The problem wasn't the graders. It was that "thesis clarity" and "argument coherence" were essentially the same construct described differently, and "use of sources" conflated citation accuracy with source relevance. I collapsed it to four criteria, eliminated the overlap, and rescored the anchor set. Reliability jumped to 0.82 on the second round. The rubric went from seven items to four, and grading time per portfolio dropped from 45 minutes to roughly 25.
Get the Full Details
The Scoring Process: What Nobody Tells You
Performance assessments are expensive to score. That's not a bug. It's the trade-off. When you ask a student to produce something original, you cannot use scantron machines or automated text analysis to grade it at scale. The scoring cost is real, and if your program can't absorb it, you're better off using a different assessment format. Here's the practical workflow that actually works: Blind double-score every submission. Two independent raters, same rubric, no knowledge of each other's scores. If their scores fall within one point on a four-point scale, accept both and average them. If they diverge by two or more points, a third rater adjudicates. This sounds heavy, but it prevents the single-rater bias that quietly corrupts every performance assessment that skips this step. I've seen a professor's "harsh grader" reputation skew an entire department's grade distribution by nearly a full letter grade across three years because nobody noticed the consistency gap.
Use calibrated rater training, not orientation. A one-hour orientation where someone reads the rubric aloud doesn't make people consistent graders. Rater training means everyone scores the same three anchor samples independently, discusses discrepancies, and repeats until the group's internal variance drops below a predetermined threshold. Budget two full training sessions before the first grading round begins. It will save you six hours of post-grading score revision work. Score in waves, not sequentially. Don't read one student's entire portfolio from top to bottom before moving to the next. Score all submissions on Criterion A first, then all on Criterion B. This keeps your judgment frame consistent and reduces halo effects. When you read a full portfolio end-to-end, the strong writing in the introduction unconsciously elevates how you judge the weaker analysis in the conclusion.
When Performance Assessments Completely Fail
They fail when the task doesn't align with what you actually claim to be measuring. This is the most common error I see in curriculum documents. A program will list "critical thinking" as a learning outcome, then assess it with a timed case-study analysis where the real skill being measured is reading speed under pressure. Or they'll claim to measure "collaborative problem-solving" and assign an individual presentation. The mismatch between claimed construct and actual task invalidates every data point the assessment generates. They also fail in large-enrollment introductory courses where class sizes exceed 80 students. I worked with a department that tried to implement performance assessments across twelve sections of introductory psychology with a combined enrollment of over 900 students. They hired graduate student graders, ran two calibration sessions, and still couldn't maintain reliability above 0.70. The variance between sections became so large that course-level grades were essentially random depending on which section you landed in. They pivoted to a hybrid model: performance assessments for the senior seminar tier only, standardized measures for the introductory sequence. The data quality improved immediately, and graders reported significantly less burnout. Performance assessments are also a poor fit when you need to diagnose specific knowledge gaps for remediation. A project-based assessment tells you whether a student produced an acceptable final product. It doesn't tell you whether the student can factor quadratic equations, identify subject-verb agreement errors, or distinguish between mitosis and meiosis. For diagnostic purposes, targeted item-level assessments remain more efficient and more accurate.

A Realistic Implementation Timeline
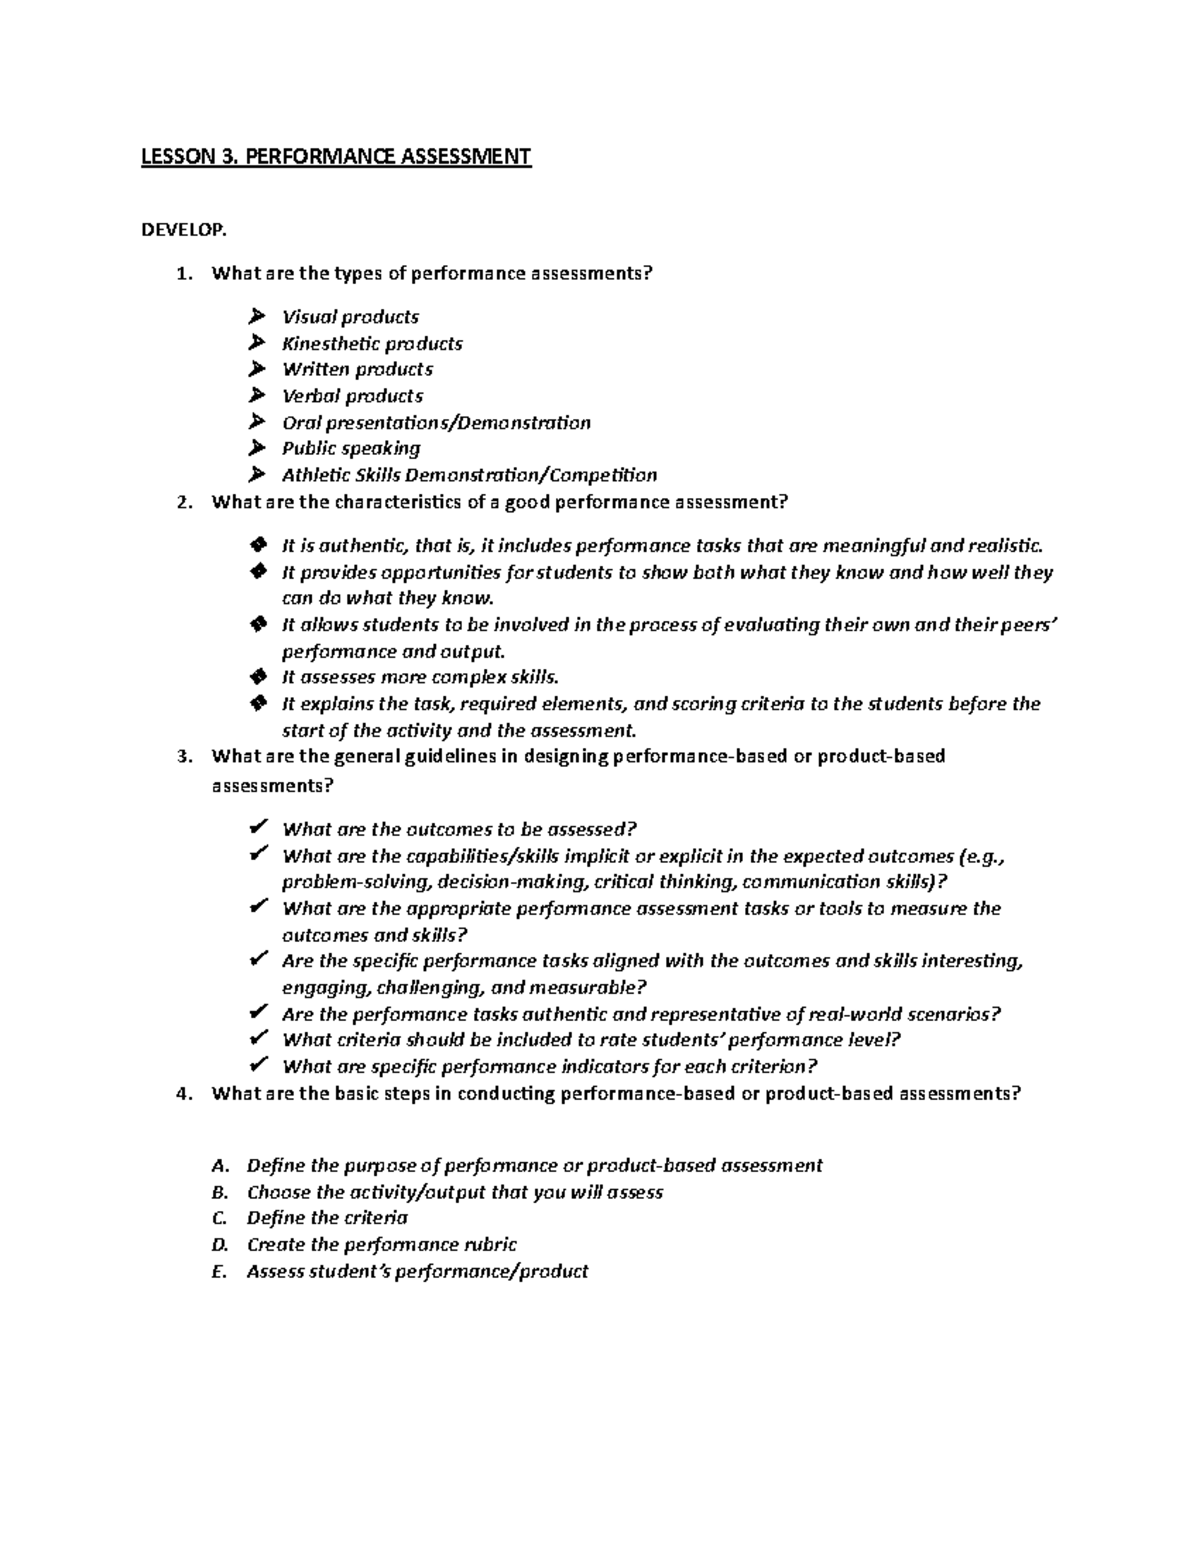
If you're designing a new performance assessment from scratch, here's what a functional timeline looks like. Don't compress it. Everything that gets compressed here comes back as data quality problems later. Weeks 1-2: Construct definition. Write a one-page document specifying exactly what knowledge, skill, or competency the assessment targets. Define what successful performance looks like in observable terms. Include one example of what an adequate response would be and one example of what an exceptional response would be. This document becomes the reference point for every subsequent decision. Weeks 3-4: Task design and pilot. Build the assessment task. Have five to seven students complete it under normal conditions. Don't grade it formally. Observe where students get stuck, what instructions they misinterpret, and how long it actually takes. A task that looks like it'll take 90 minutes often takes 140 when students hit the first ambiguous instruction.
Weeks 5-6: Rubric development with anchor samples. Draft the rubric. Collect anchor samples from the pilot. Score them. Refine the rubric based on where the anchors expose ambiguities. Repeat until the rubric consistently sorts the anchor set the way you intended. Weeks 7-8: Rater training and reliability testing. Train graders. Run inter-rater reliability checks. Fix any criteria that don't reach 0.75 agreement. This step gets skipped constantly, and it's the single biggest predictor of whether your final data will be usable or garbage. Week 9 onwards: Full administration. Run the assessment. Score using the calibrated process. Analyze results against your construct definition. Archive the anchor samples for next year's rater training. The cycle repeats, and each iteration should produce slightly more reliable data than the last.
The Data You Can Actually Use
Performance assessments generate rich qualitative data, but that data is nearly useless unless you systematize how you collect and analyze it. I've seen departments collect hundreds of student portfolios and produce narrative summaries that read like individual anecdotes rather than program-level evidence. The difference between anecdote and data is aggregation. Code every submission against your rubric criteria. Track not just the final score per criterion but the distribution of scores across criteria. If 80 percent of students score "adequate" or above on content knowledge but only 30 percent meet the threshold for "evidence integration," you've identified a specific teaching gap, not a vague "students need to write better" problem. That specificity is what makes the assessment worthwhile for curriculum improvement. Also track the correlation between your performance assessment scores and other measures in the program. If your performance assessment claims to measure "scientific reasoning" but correlates 0.12 with students' performance on a validated reasoning instrument, you should question whether your assessment is measuring what you think it is. A correlation below 0.40 with a established measure of the same construct usually indicates a validity problem worth investigating before you present the results to anyone outside your department.

The assessment itself isn't the output. The output is the information it gives you about whether students can actually do what you claim to teach them. Everything else — the rubrics, the scoring sessions, the calibration meetings — is infrastructure for getting that information reliably. Build accordingly.