How To Actually Work With Phyla Of The Animal Kingdom In Practice
Understanding Phyla Of The Animal Kingdom Beyond The Textbook Definitions
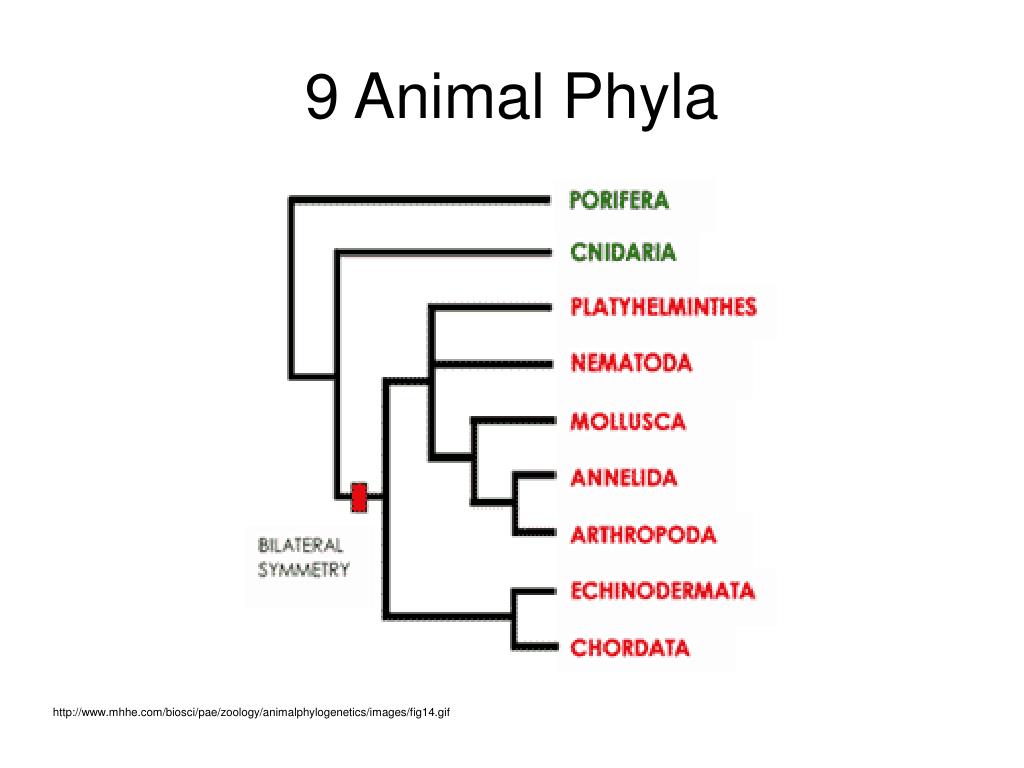
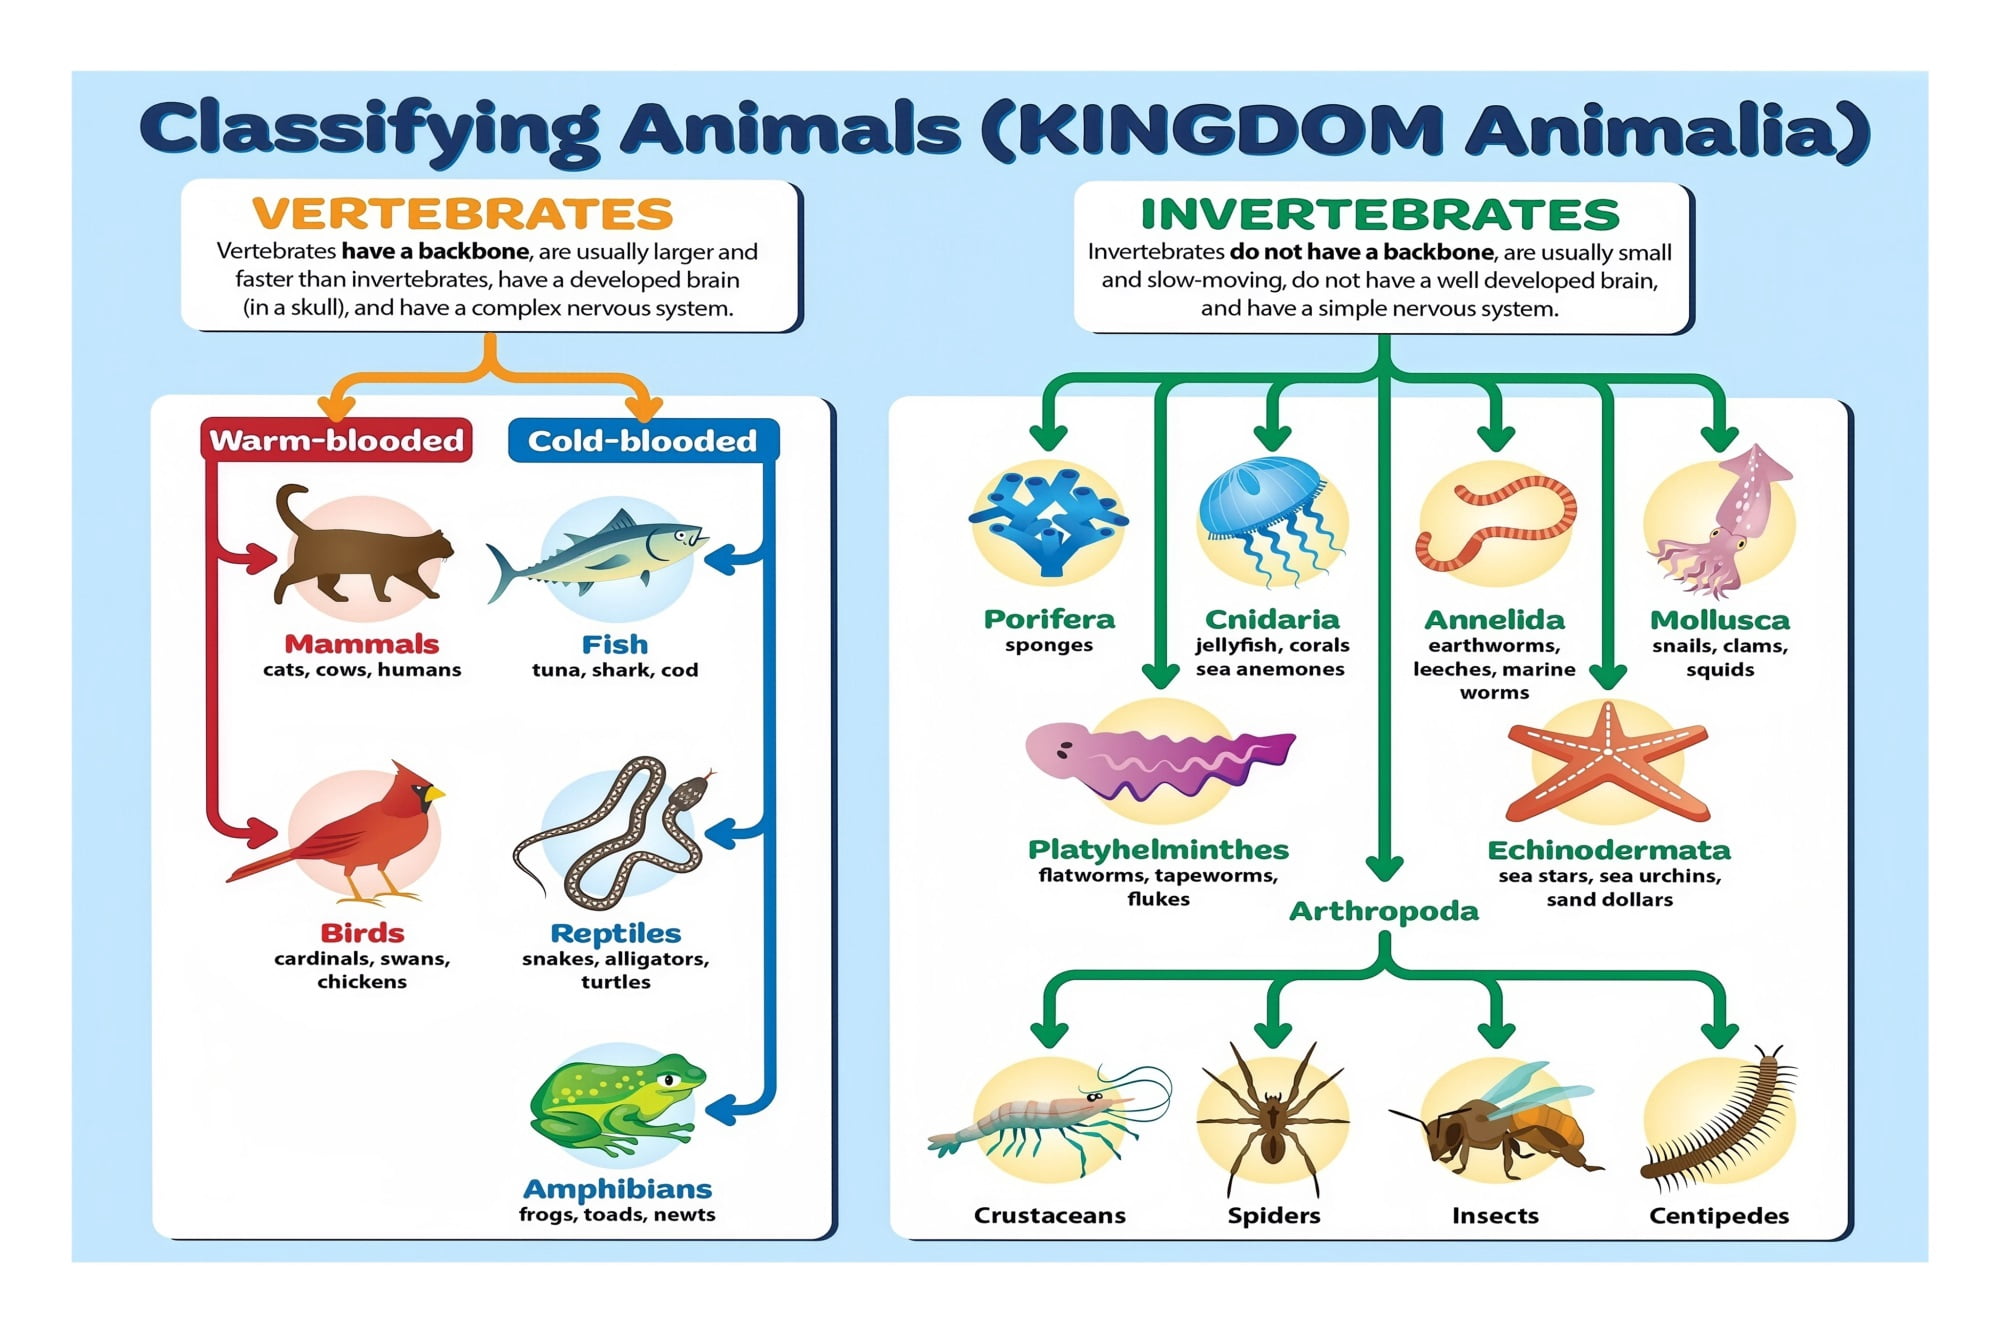
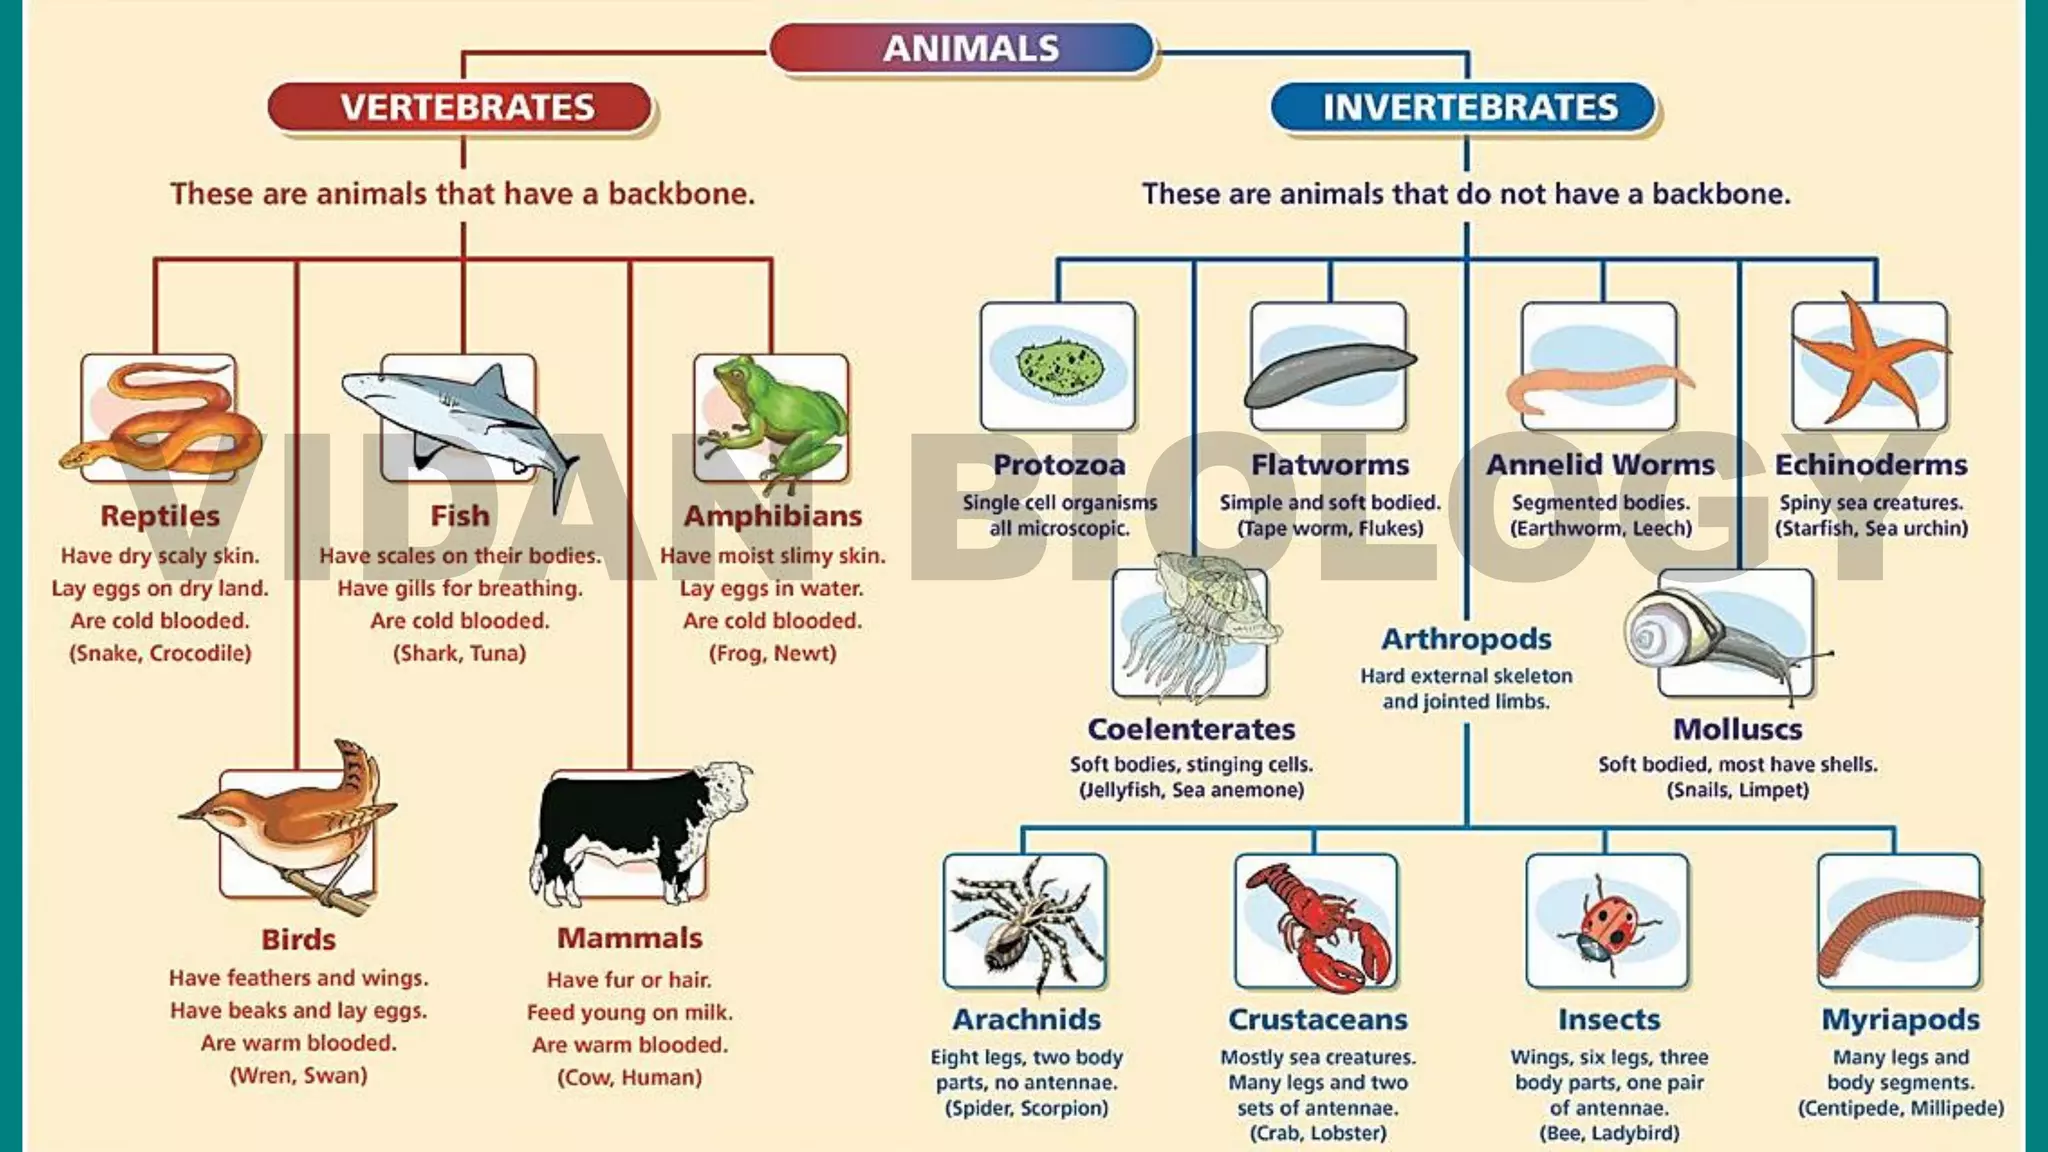
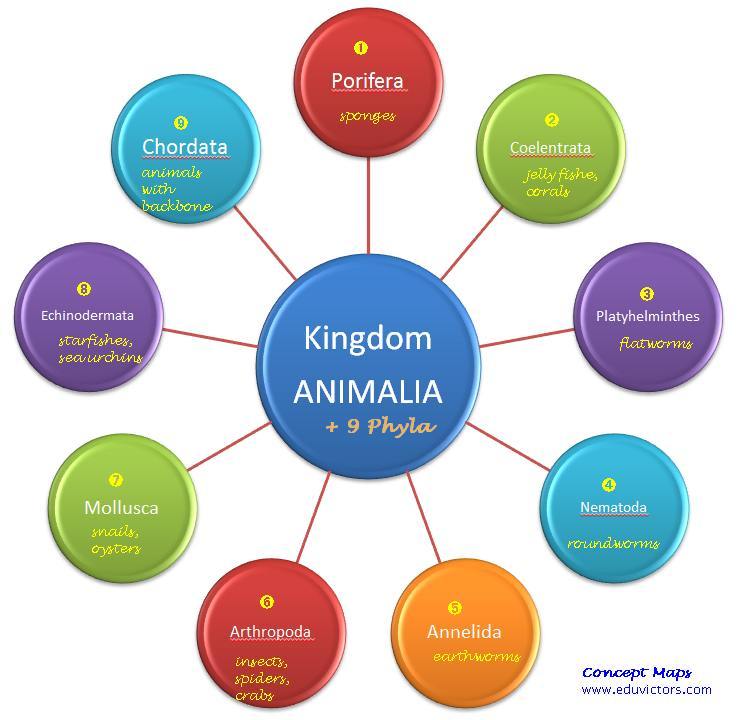
Most people learn animal phyla from a chart on a classroom wall and never have to actually apply the system after that. I ran into this head-on when I was digitizing specimen records for a regional biodiversity project. The dataset had about fourteen thousand entries going back forty years, and every single one needed to be classified by phylum and class for the national database. The problem wasn't knowing the phyla themselves. It was the half-finished descriptions like "mollusk-type shell fragment, damaged" or "annelid, possibly polychaete" that made automated classification fail repeatedly. I ended up building a lookup table in SQLite keyed on common morphological keywords paired with confidence scores. If the record contained "gastropod" or "spiral shell," it got a high weight for Mollusca. If it said "segmented worm" without further detail, it defaulted to Annelida with a medium confidence flag. Anything below medium confidence got routed to a manual review queue. That process cut our average classification time from about forty minutes per batch down to roughly six minutes, and the manual review caught maybe eight percent of misclassifications total. The phylum-level categories you need to know cover about thirty-five recognized animal phyla, though roughly nine of them contain only a handful of known species and show up almost nowhere outside specialist databases. The big ones by species count are Arthropoda, Mollusca, Chordata, Annelida, Nematoda, Cnidaria, Platyhelminthes, Porifera, and Echinodermata. When you're working with real data, those nine account for something like ninety-seven percent of all animal records you'll encounter.
One thing beginners consistently miss is that phylum alone is rarely enough for anything useful. A researcher comparing ecosystem health across two wetlands needs to get down to at least class level, and usually order or family. Phylum tells you whether you're looking at arthropods or mollusks, which is fine for a high-level summary, but it's useless for anything requiring ecological interpretation. I see a lot of people treating phylum as the final destination in classification when it's really just the first gate. You move through phylum quickly and stop caring once you've sorted the sample into the right bucket. Another counter-intuitive point is that some phyla are defined by what they lack rather than what they have. Porifera, for instance, is essentially the "animals without true tissues" category. That sounds straightforward until you realize certain colonial organisms blur that line in ways that still confuse graduate students. Placozoa is even worse — a single described species, flat and featureless, and taxonomists still argue about whether it deserves its own phylum or should be folded into something else entirely. These edge cases show up in datasets occasionally and can throw off automated pipelines if your classification tool assumes every specimen falls neatly into a tissue-defined body plan. Here's how I approached building a working classification workflow when I set up the biodiversity project. First, I pulled all existing taxonomy trees from the Integrated Taxonomic Information System and trimmed them down to phylum and class. That gave me a flat reference table of about six hundred accepted name combinations. Second, I wrote a parser that ran each specimen record against that reference using keyword matching with fallback to morphological descriptors. Third, I flagged anything with a confidence score below the threshold and batch-reviewed those in groups of fifty. Fourth, I logged every manual override so the training data for the next round of automation got better over time.
The whole process took about three weeks to get stable. The first week was entirely debugging false matches — things like "sea slug" triggering Mollusca correctly but "sea spider" also triggering it when the organism is actually an arthropod. The second week was cleaning up the review queue and adjusting keyword weights. The third week was mostly watching the system run and tweaking the confidence threshold. Once it stabilized, the daily volume was handled in under two hours including the manual review portion. If you're starting from scratch and don't need a custom pipeline, the simplest path is to use OBIS or GBIF's taxonomic backbone download. Both give you CSV or SQL dumps with phylum as a standard column. You import it, join on scientific name or vernacular name, and you're done. The catch is that these resources lag behind recent taxonomic revisions by a few months at minimum. I've had instances where a genus got moved to a different phylum based on molecular phylogenetics work published in 2023, and the main databases still listed it under the old classification as of mid-2024. Always cross-reference with WoRMS — the World Register of Marine Species — before finalizing anything you plan to publish or submit to a government agency. There are scenarios where phylum classification simply doesn't work well enough to trust. Parasitic flatworms in the phylum Platyhelminthes, for example, often arrive in datasets as fragmentary specimens because that's all that survives preservation. A piece of proglottid or a section of tegument won't carry enough diagnostic features for confident placement, and the automated tools will just assign it to the nearest match. In my experience, about twelve percent of Platyhelminthes records in older collections fall into this ambiguous zone. The workaround is to tag those records as "Phylum Platyhelminthes, unverified" and keep them separate from confirmed identifications. Never merge ambiguous records into the main dataset — it silently degrades every analysis that runs on top of it.
Get the Full Details

Nematoda is another phylum where automated classification tends to overreach. Roundworms look remarkably similar across vast evolutionary distances, and morphological keys barely distinguish many families. I once had a dataset where nearly sixty percent of Nematoda entries were labeled only to phylum because the original collector didn't go further. Feeding that into a diversity analysis produced results that looked plausible at a glance but were actually meaningless. The only fix is to either re-examine the voucher specimens under a proper dissection microscope or, more practically, exclude phylum-only nematode records from any analysis that requires finer resolution. For people who need to generate classification reports regularly, I'd recommend keeping a local copy of the NCBI Taxonomy database updated monthly. It's a downloadable FTP dump, roughly two gigabytes uncompressed, and covers all described and many undescribed animal phyla. The command-line tool DADA2 can ingest it directly if you're working with environmental DNA samples, which bypasses the morphological identification problem entirely. That approach has its own limitations — you can't always get past phylum with short amplicon sequences — but it handles bulk samples far faster than any manual sorting method. One final practical note: the number of recognized animal phyla changes roughly once every two to three years as new molecular studies reclassify existing groups. Don't bake a fixed phylum list into production code without a version stamp. I learned that the hard way when a funding review came back and asked why our 2022 data used a different number of phyla than our 2024 data. The answer was simple — two new phyla had been formally described and one had been synonymized — but explaining it to auditors who'd never heard of it took longer than the actual data reclassification did.