Working With Vintage Physiology PDFs
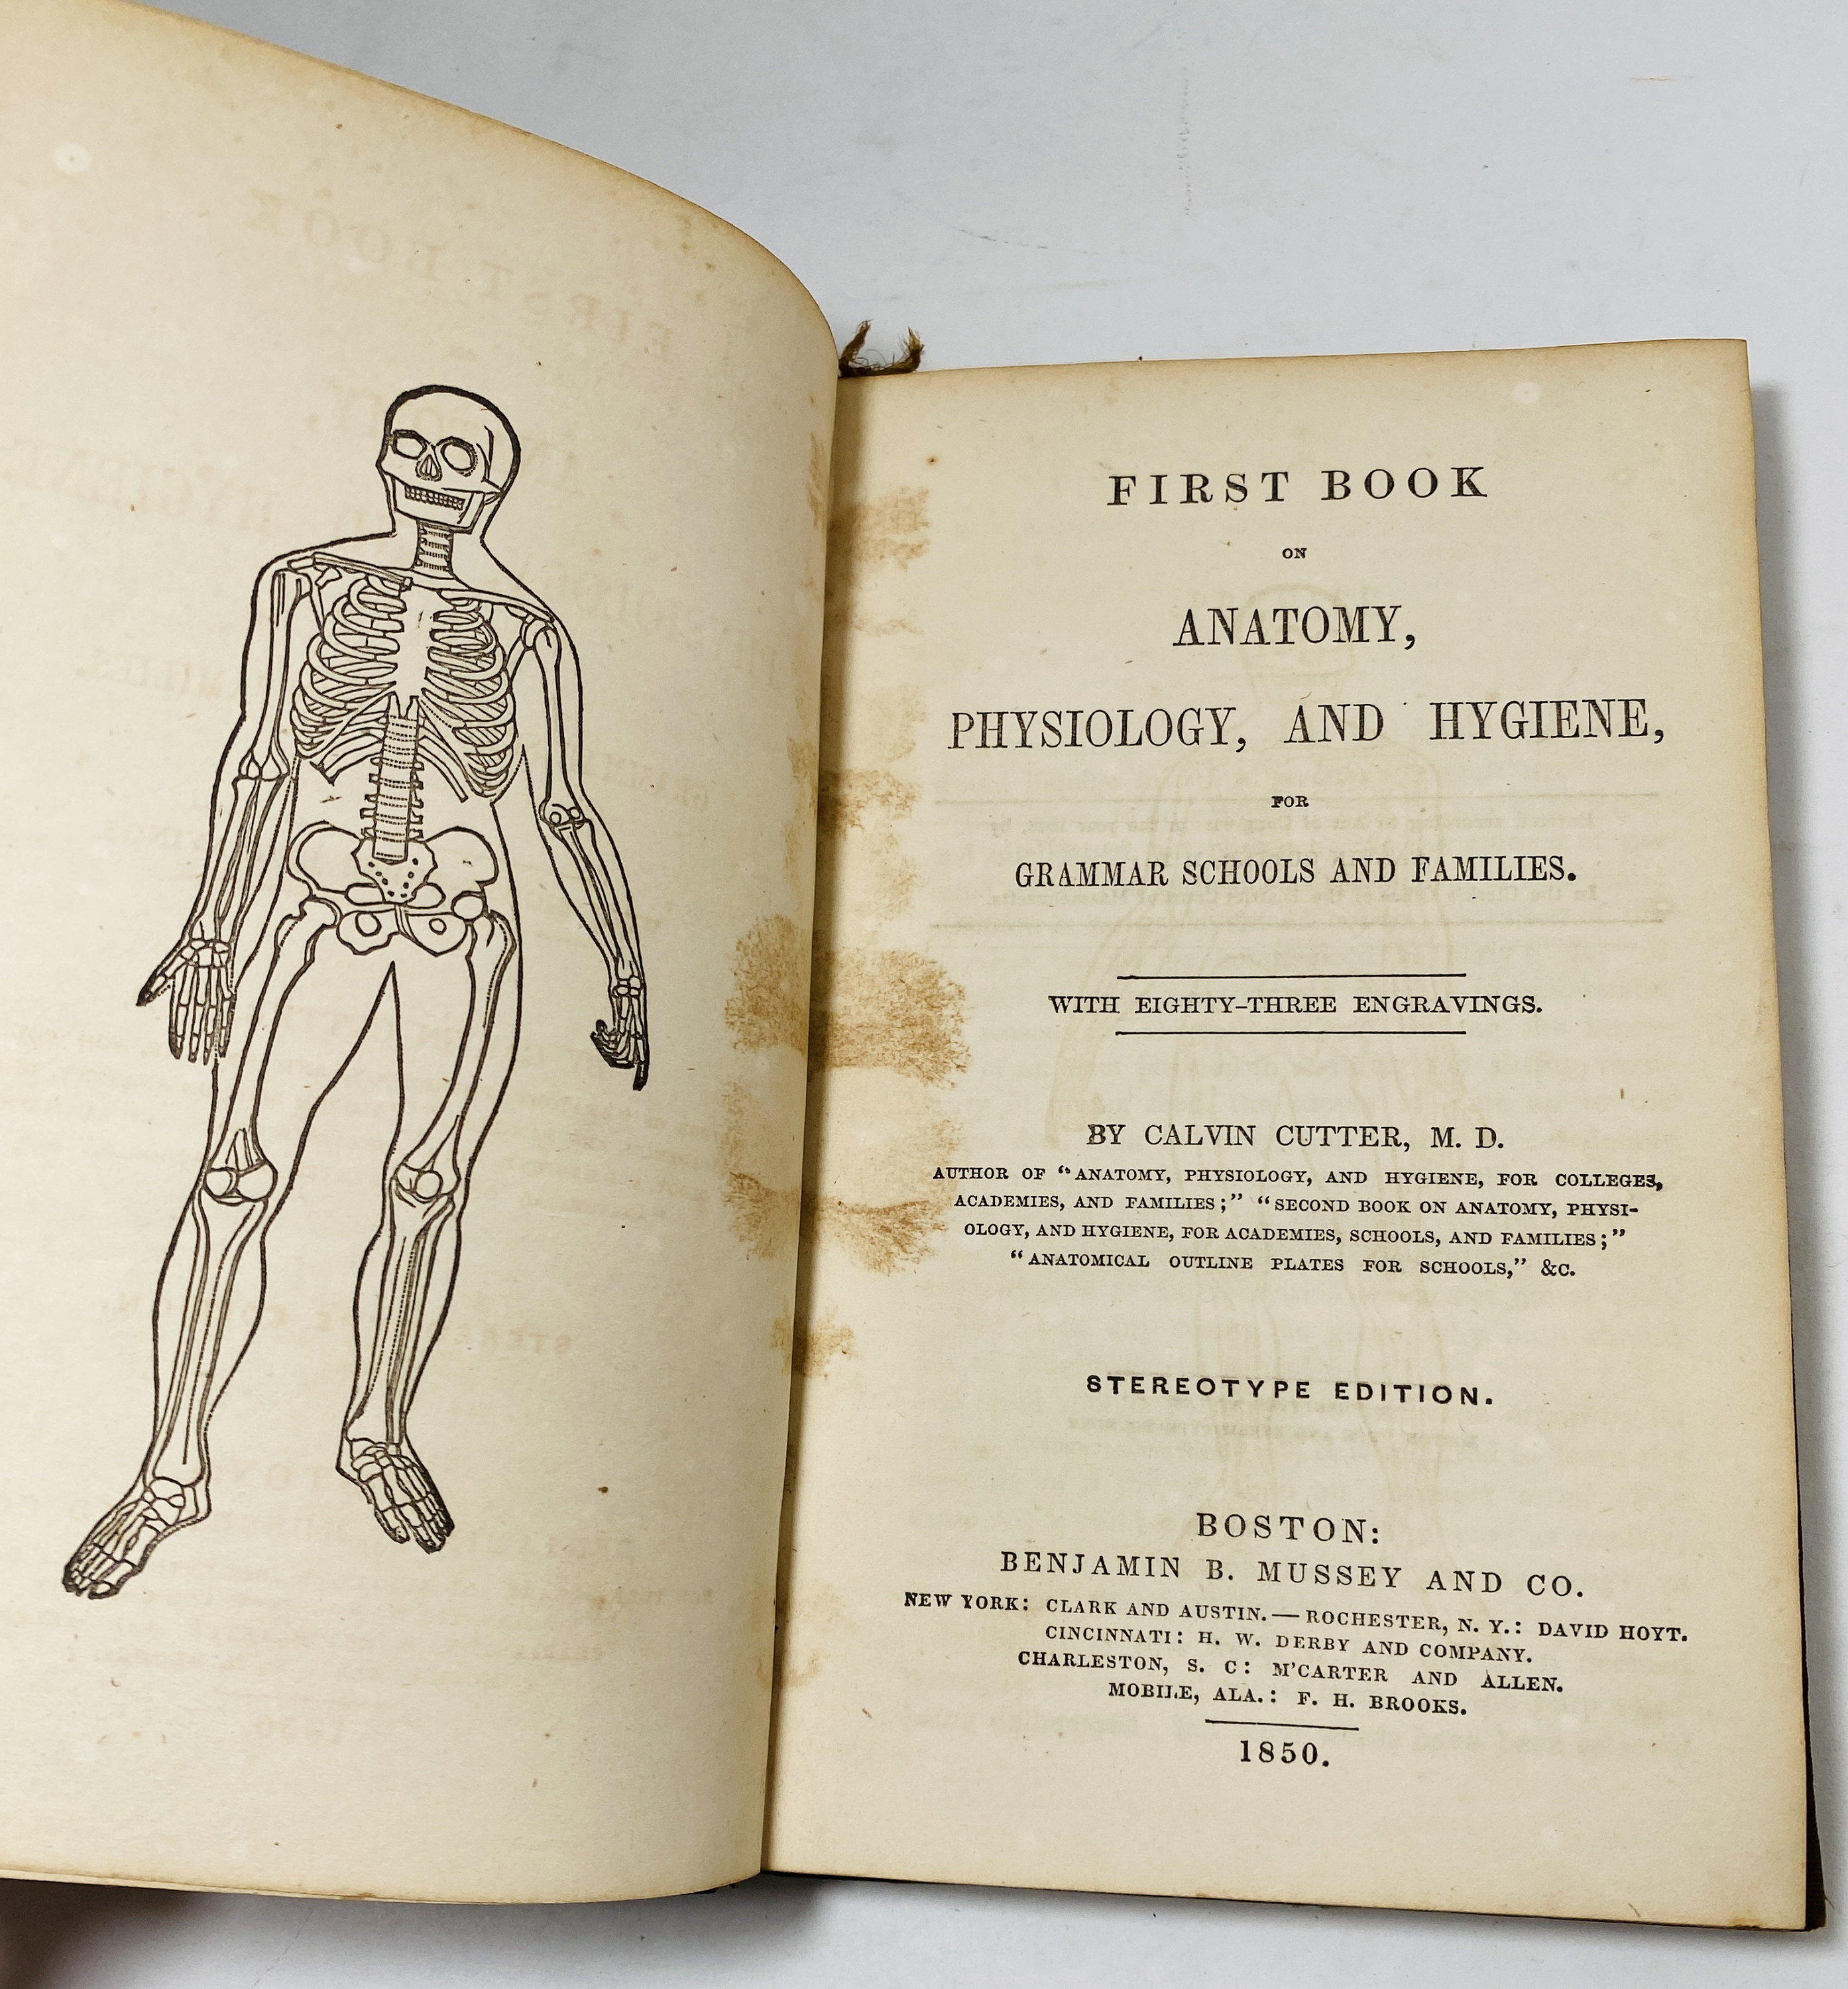
I spent a few years tracking down and organizing digitized physiology material from the early 2000s. What you end up with is usually a mixed bag. The original scans came from physical copies that libraries had sitting on shelves for decades, and whoever ran the scanner back then wasn't thinking about readability. Text looks fine until you try to search it. Then the whole thing falls apart. The problem isn't just scan quality. It's the metadata. Most of these files have no proper table of contents structure, no tagged headings, and the OCR layer often misreads old serif fonts as completely different characters. I found a Guyton & Hall reprint where every instance of "mmHg" got recognized as "rnmHg." That ruins your search string instantly. You can fix this with a regex find-and-replace script in something like Calibre or Adobe Acrobat Pro, but you have to know the exact patterns beforehand.
Physiology Pdf Vintage sourcing and quality
The real vintage stuff — things like older editions of Ganong, Berne & Levy, Vander's Human Physiology — tends to show up on archive.org, Sci-Hub mirrors, and various university digital repositories. The quality range is wild. Some are 600 DPI black-and-white scans that are essentially book-perfect. Others are 150 DPI color photocopies where the ink bled through from the opposite page and you can barely make out the diagrams. I stopped asking about file size and started checking the DPI of the first page before downloading anything larger than 50 MB. My own workhorse setup involved taking the raw PDF, running it through OCRmyPDF with the hocr option to rebuild the text layer, then feeding it into a Python script that cross-referenced a list of known OCR error patterns from older physiology terminology. Things like "ml" becoming "rnll" or Greek letters in equation numbering getting stripped entirely. The script replaced them and saved a cleaned version. Cuts your post-processing time from roughly three hours per file down to about twenty minutes if you've already got the pattern list built.
Where the system breaks down
Here's what nobody warns you about: vintage physiology PDFs from the pre-2005 era frequently contain halftone images of graphs and data tables that have absolutely no embedded text. The curves in a dose-response chapter are pictures, not data. If you need to pull numbers off those for a literature review or a reproduction attempt, you're stuck. I ran into this specifically with an old edition of West's Respiratory Physiology where the oxygen-hemoglobin dissociation curves were pure bitmap. There was no way to extract the axis values without manually digitizing each point, which took me about four hours for one figure. Another issue is the font embedding. Many of these PDFs were created with PostScript printers that didn't embed fonts properly. Open one in a modern reader and the text renders differently depending on your system. A paragraph that looks tight and readable on one machine might render with wild kerning on another. This matters if you're citing page numbers or quoting directly. The pagination shifts. For color diagrams, the issue gets worse. Vintage medical illustrations used color separation printing techniques that don't translate cleanly to digital. Greens look yellow, reds look orange, and the distinction between a sympathetic pathway and a parasympathetic one in a nervous system diagram becomes guesswork unless you have the physical book to compare against.
Get the Full Details
What actually works for retrieval
If you need the content rather than just the pages, OCRmyPDF with the --force-ocr flag will re-scan the entire document even if it already has a text layer. This catches cases where the existing OCR is so bad that native search returns zero results for terms you know are on the page. Pair that with pdfgrep for command-line searching across a batch of files. It's faster than opening each PDF individually and running a find. A typical search across a folder of twelve vintage physiology PDFs takes about forty seconds with pdfgrep versus thirty minutes doing it by hand. I also keep a small reference sheet of common OCR artifacts from old medical texts. "l" becomes "1", "O" becomes "0", "S" becomes "5", and compound words get split by hyphens at line breaks. Having that sheet means you can predict what to search for instead of randomly trying variations. The alternative when the PDF is beyond repair is scanning it fresh. A flatbed scanner at 400 DPI with a proper book cradle will beat any pre-made vintage PDF for most purposes, though it takes about four hours for a standard 800-page text. The tradeoff is clean text, accurate colors, and proper metadata you control. I usually recommend the fresh scan route when you need the material for publication or formal citation. For personal study or quick reference, the existing vintage PDF with a cleaned OCR layer is sufficient.