Why Your Shop Floor Is Always Late And How To Fix It
I spent about four years wrestling with planning and scheduling systems before I realized the problem wasn't the software. It was what people fed into it. The gap between what a planner thinks is happening and what actually happens on the floor is usually huge. Getting them closer together is the real work. At its core, planning decides what needs to be done. Scheduling decides when it gets done. You separate these two steps because combining them prematurely will break your schedule every single time. I've seen people try to run finite-capacity scheduling directly from raw demand without first doing a proper resource-capacity check. That just creates a fantasy schedule that collapses on day two when a machine breaks or a material delivery is late. The practical approach starts with a master production schedule. This is a time-phased list of what you intend to produce or deliver, built against your known constraints. In manufacturing, constraints are usually machines, labor, and materials. In services, constraints shift to people, rooms, equipment, and regulatory windows. The method is the same. The data just changes shape.
Here is what I actually do. First, I pull the last ninety days of actual completion data. Not the planned completion dates. The real ones. Then I calculate a utilization factor for each work center or team. If your CNC cell is planned at 85 percent but averages 71 percent in reality, you need to know that number before you commit to any new schedule. Without it, you are guessing. And in this business, guessing is expensive. I remember a specific case at a mid-size contract manufacturer. They were committing to promised dates that were systematically two weeks late. Their ERP showed 92 percent capacity utilization across all work centers. The math said they should have been fine. They were not. I spent a week tracking down where the hidden slack was hiding. It turned out to be changeover time between jobs on three specific press lines. The ERP assumed twenty minutes per changeover. In practice, it averaged forty-five. That discrepancy alone inflated their effective capacity by roughly eighteen percent. Once I updated the standard times with actuals, the schedule immediately became realistic, and on-time delivery went from about sixty-four percent to eighty-nine percent within two months. The same principle applies to services. A staffing firm I worked with was overbooking consultants because they scheduled based on billed hours rather than productive hours. They assumed a consultant could bill forty hours in a forty-hour week. Nobody can. After accounting for admin, internal meetings, and context switching, the realistic figure is closer to thirty focused billable hours. Adjusting the scheduler to use that number fixed their chronic overallocation within a week.
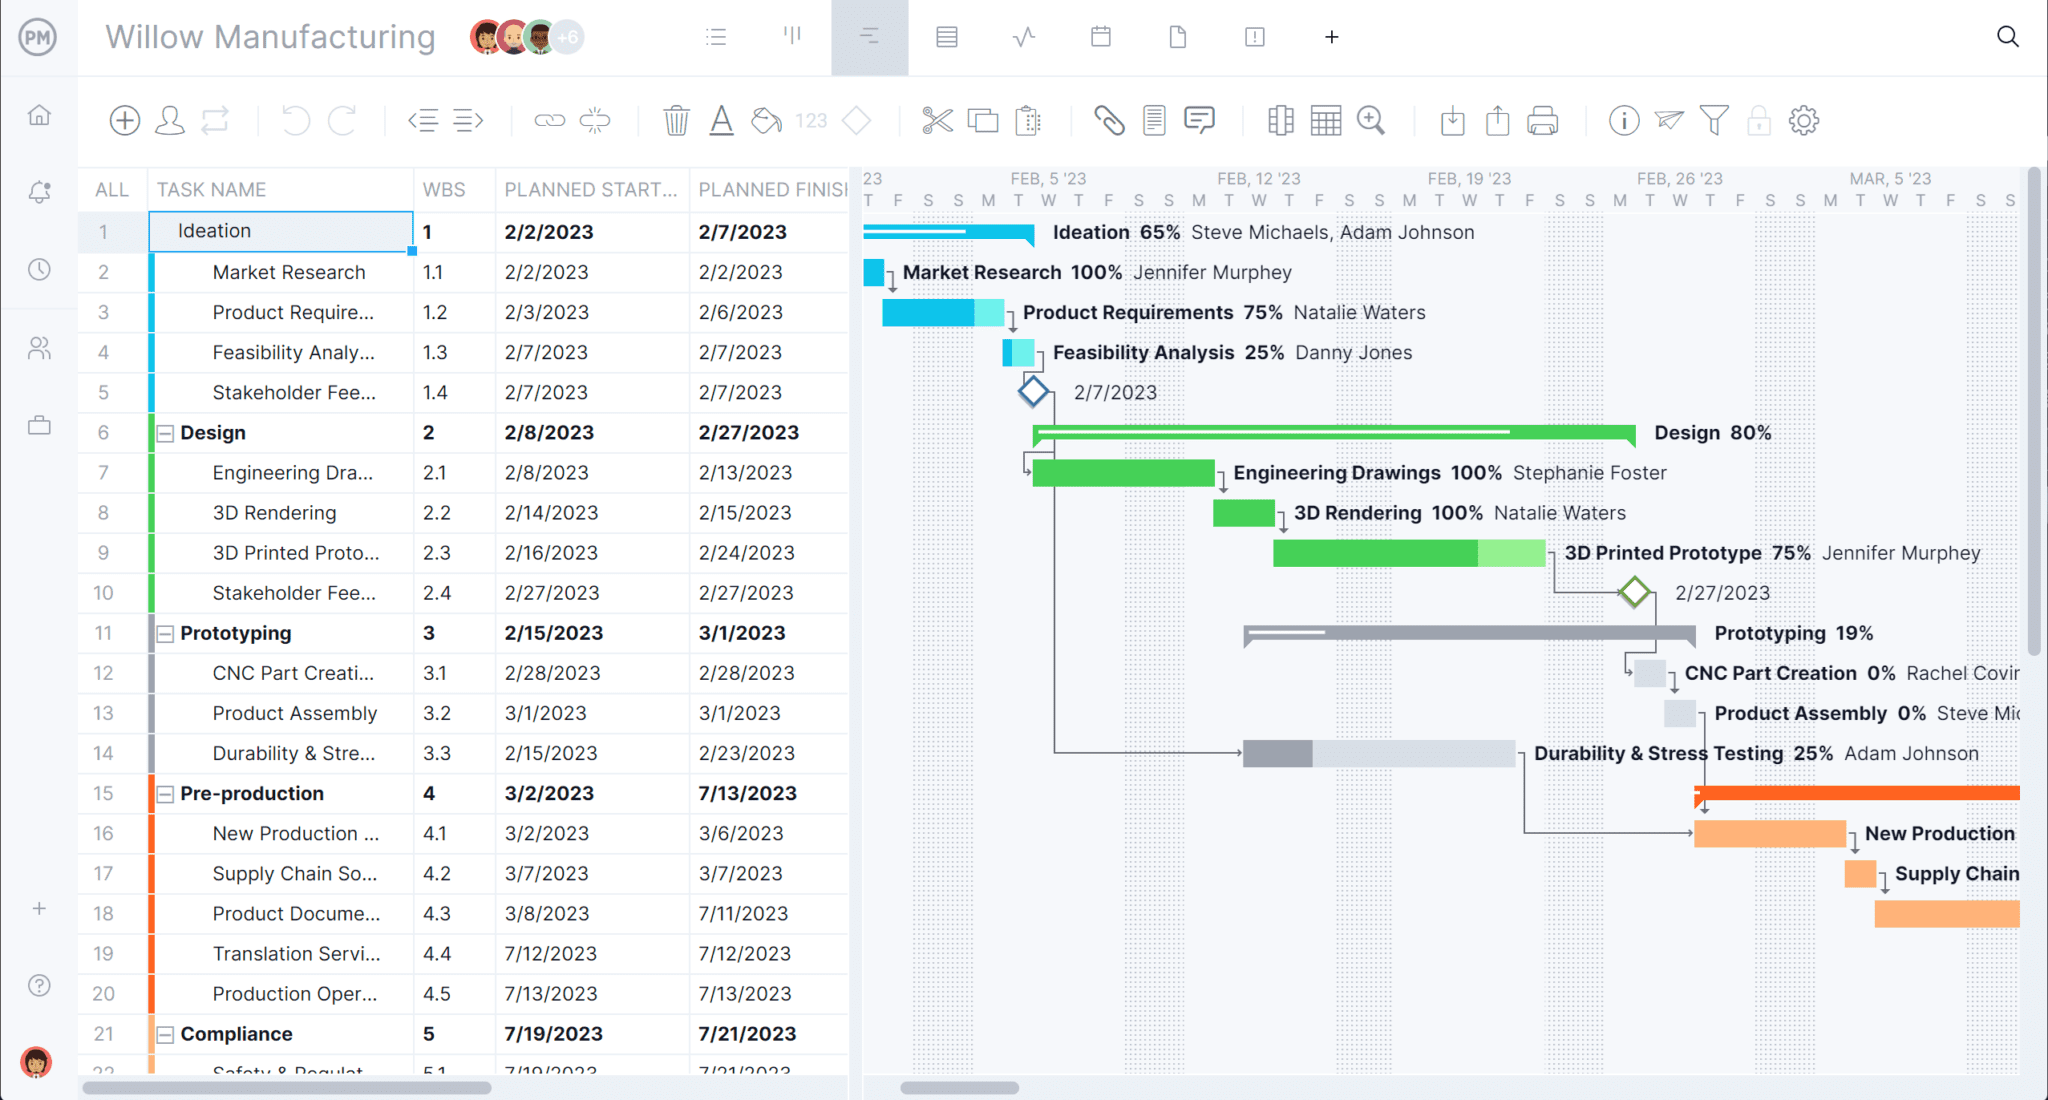
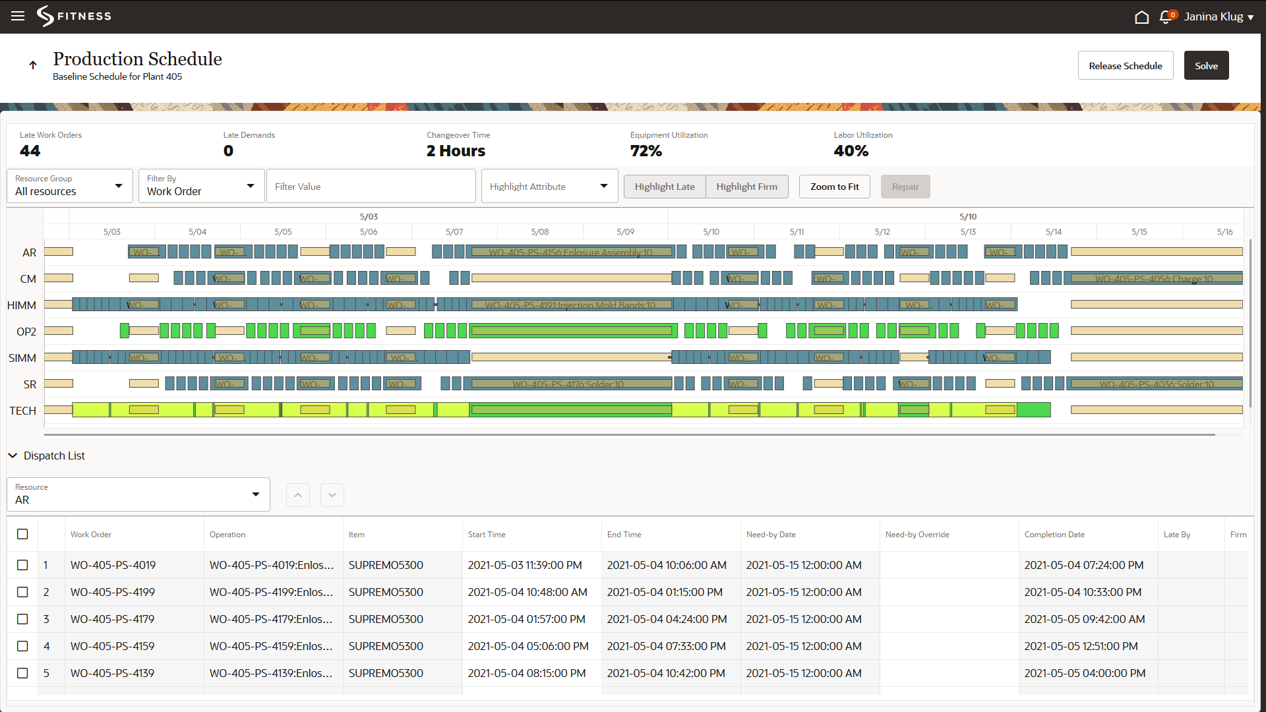
Now let me talk about tools. Most small manufacturers I deal with still run scheduling on spreadsheets and whiteboards. That is not a moral failure. It is a stage you move past when the complexity exceeds what a human brain can hold simultaneously. The trigger point is usually around fifteen to twenty concurrent work orders with multiple operations each. Before that threshold, a well-organized spreadsheet with conditional formatting is faster than any system you will buy. After that, you need finite scheduling logic. For manufacturing, look at systems that support backward scheduling from due dates and forward scheduling from material availability. These two modes handle different situations. Backward scheduling tells you when to start so you finish on time. Forward scheduling tells you the earliest you can finish given current load. Running both simultaneously on the same data reveals bottlenecks that one mode alone will hide. In services, the scheduling problem is often a resource allocation problem wrapped in calendar notation. Hospital imaging departments, repair dispatch, and professional services firms all face this. The key insight most people miss is that service scheduling requires buffer time built into every slot. Manufacturing can absorb a ten-minute overrun on a machine cycle without cascading effects. Service work does not work that way. A consultation that runs five minutes long pushes the next appointment back, and that back pressure compounds through the entire day. Build in twelve to fifteen percent buffer by default and measure the variance after three weeks of actual use.
Get the Full Details
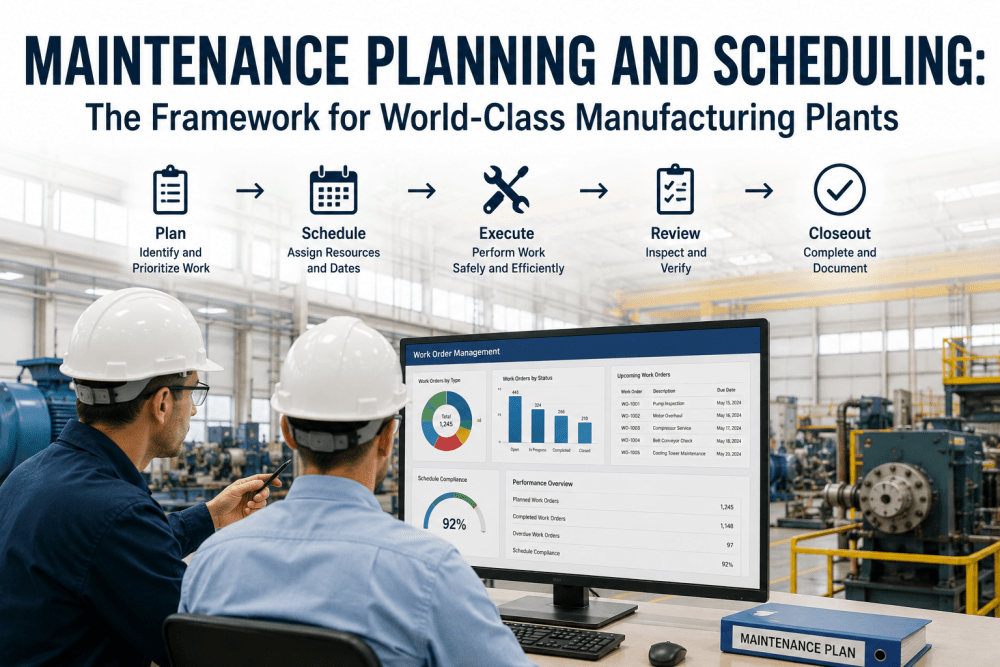
One more thing that trips people up: scheduling around skill sets rather than just headcount. A team of five technicians sounds adequate on paper. But if three of them can only work on Tier 2 repairs and two handle Tier 1 and Tier 3, your schedule needs to respect that distribution. I once saw a field service company burn through two weeks of overtime because the scheduler assigned three complex installs to the only two senior techs available, while the junior staff sat idle on simple replacements they could have taken if the allocation had been balanced properly. The fix was simply adding a skill tag to each worker and letting the scheduler enforce the constraint rather than the planner making manual overrides. Integration matters more than features. A scheduling tool that lives in a silo between your ERP and your floor will generate more problems than it solves. You need a two-way data flow. Work order statuses, actual start and end times, scrap reports, and material consumption all need to feed back into the schedule automatically. If your planners are manually updating schedules after every status change, you are introducing latency that makes the schedule stale within hours. Automation of that feedback loop typically cuts the weekly planning workload by about sixty percent. There are scenarios where even a well-tuned scheduling system will underperform. If your supply chain is highly variable with lead times that swing by fifty percent or more, no scheduler can compensate for that reliably. In those cases, you build safety time into the schedule rather than trying to optimize around uncertainty. Similarly, if your product mix is truly custom with no repeat jobs, finite capacity scheduling adds overhead with limited return. Those situations call for a drag-and-drop Gantt interface with manual override capability. Do not force complex optimization logic onto a environment where customization is the norm.
If you are starting from scratch, I would recommend beginning with a simple database table that maps work orders to resources with start dates, end dates, and actual completion timestamps. Run it for ninety days. Calculate the gaps between planned and actual. Use those gaps to build your buffers and standard times. Then migrate to a dedicated scheduling tool with the numbers you already trust. Skipping that calibration step means importing garbage into a more expensive system, which is functionally the same problem at a higher cost. The bottom line is that planning and scheduling is mostly about data quality and honest capacity assumptions. Any tool will do what its inputs allow it to do. Garbage in, garbage out applies here with rare exceptions. Spend the time getting your standard times, yield rates, and resource constraints right before you spend money on software that promises to fix everything else.