Why most technology plans fail before they start
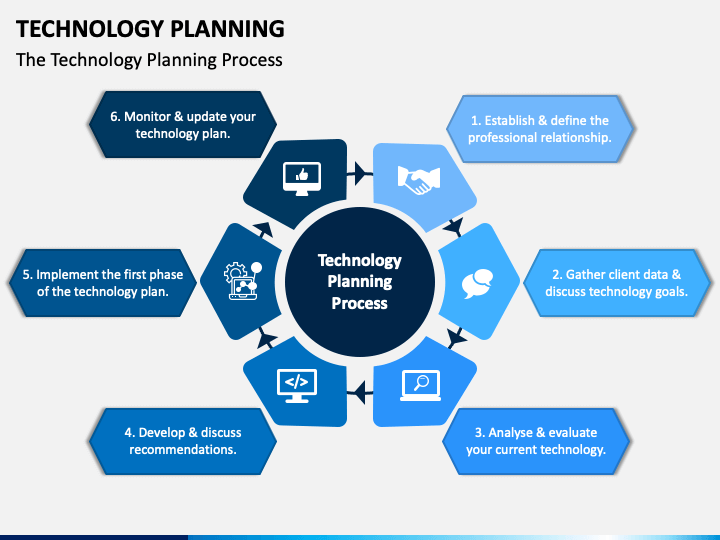
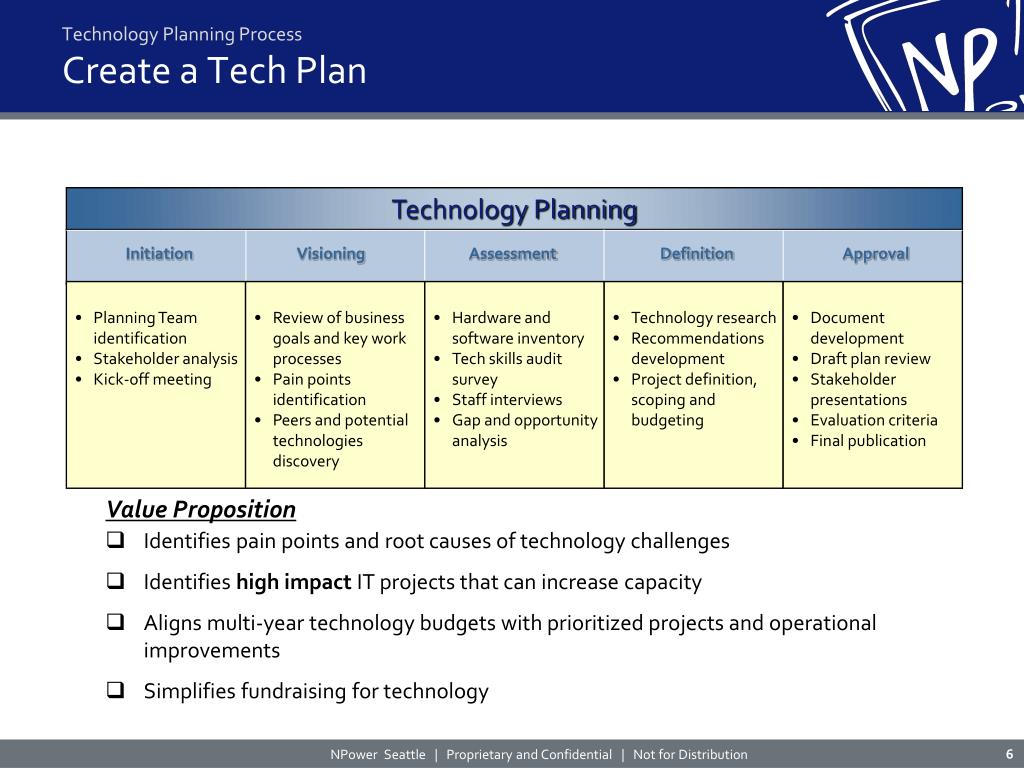
I spent years watching companies build elaborate technology roadmaps that never made it past the first quarter. The issue isn't the tech itself. It's how people frame the plan around it. When you treat technology as a separate line item instead of an embedded operating system for your operations, everything downstream gets messy. That is something I learned the hard way during a mid-2010s digital transformation where we budgeted $400,000 for a new inventory system and completely forgot to account for the three months of parallel-running data migration that should have happened before go-live. The project bled an extra 87,000 dollars in overtime and consultant fees because nobody had planned for the ugly middle section. The framework starts with what most people skip: mapping every existing process that the technology will touch before you pick a single tool. I usually draw this out on a whiteboard or in a spreadsheet with five columns. Process name, current step count, average time per transaction, pain points, and which team members are involved. That last column matters more than anything else because adoption dies when the people who actually do the work feel like the technology is being imposed on them rather than built around them. Once you have that map, you layer in technology requirements in a specific order. Infrastructure first. Data architecture second. User interface and workflow third. This sequence prevents the common mistake where a company falls in love with a sleek dashboard and then realizes six months later that their database schema cannot support the reporting they just committed to building. I have seen this repeatedly with CRM implementations where the sales team wanted gamification features before anyone verified that the legacy data could even be cleaned into the new system in the first place.
The technical specifications should be written by someone who will actually work with the system daily, not by a procurement team that evaluated it based on a vendor demo. Vendors optimize demos for fifteen minutes of perfect data and smooth performance. Real usage looks nothing like that. Your technical specs need to include worst-case scenarios: what happens when the system handles ten times the normal load, what happens during a power outage, what happens when three people try to edit the same record simultaneously. These edge cases are what separate a plan that survives from one that collapses under actual conditions.
The hidden cost nobody factors in
Every plan I have ever reviewed missed one specific cost category. Change management fatigue. People can handle a new tool. They cannot handle a new tool while their existing workflows are being rearranged simultaneously across multiple departments. The burnout sets in around week four and productivity drops by roughly thirty percent for the affected teams. I started tracking this explicitly after a warehouse management system rollout where our initial projections assumed a two-week adjustment period. Reality took eleven weeks because supervisors were already juggling three other operational changes at the same time. The workaround I settled on was staggering technology rollouts by department with mandatory cooling-off periods between each launch. You cannot stack them. At least six weeks of stable operations between major system changes. This is not optional if you want people to actually use the technology properly. Rushed adoption creates workarounds around your technology, which means your data becomes unreliable and your plan was effectively useless from day one. There is also the maintenance burden that nobody includes in initial projections. Software licensing, security patches, integration updates, and annual compliance reviews. A typical mid-size technology stack runs about twelve to eighteen percent of its original implementation cost per year in maintenance. I usually factor that into the plan as a standalone line item so leadership does not treat it as a surprise later. When it appears unannounced on a quarterly budget review, people tend to cut corners on security updates to absorb the cost, which introduces risk that compounds over time.
Get the Full Details

Measuring whether your plan is actually working
Most organizations measure technology plans by whether the system launched on time and on budget. That is the wrong metric. The right metric is operational velocity measured against the baseline you established in your process mapping phase. If the technology does not make a specific process measurably faster or more accurate within ninety days of launch, you have a configuration problem, not a technology problem. The tool is fine. You configured it for the wrong workflow. I track three specific numbers after any technology deployment. Transaction throughput, error rate, and user override frequency. Throughput tells you if the system is handling volume. Error rate tells you if the process design is sound. Override frequency is the most important one because it reveals where human workers are circumventing the technology rather than using it. An override rate above five percent means your plan needs revision. It means the technology is getting in the way more than it is helping, and no amount of additional training will fix that. The workflow itself needs to change. Data integrity checks should run weekly for the first three months after go-live and then shift to monthly. Automated validation scripts catch most issues before they compound. I usually write these scripts to compare input records against expected output patterns and flag anomalies for manual review. This catches the kind of problem where a quantity field defaults to zero instead of carrying over from the legacy system, which would silently corrupt your entire inventory count for a quarter if nobody noticed.
When technology plans are the wrong solution
Sometimes the answer is not to build a plan at all. If a process takes less than five minutes per transaction and is performed fewer than fifty times per week, investing in custom technology is almost always a net negative. The development time, maintenance burden, and training overhead outweigh any efficiency gains. In those cases, you document the process with standard operating procedures and move on. I see this mistake constantly in small operations where the founder assumes that any repeatable task deserves automation. It does not. Not everything needs a system behind it. The real limit of Plans That Incorporate Technology shows up when the underlying business model is still unstable. If you are pivoting your product offering every six months, building a custom technology plan around your current operations is throwing money at a moving target. In that scenario, you use off-the-shelf tools that require minimal configuration and can be reconfigured quickly. A shared spreadsheet with clear columns beats a half-built custom application every time during periods of rapid change. Custom plans require stability. Stability requires a proven model. If you do not have a proven model yet, stop trying to digitize the chaos and figure out what actually works first. Security compliance adds another layer of complexity that most plans underweight. Depending on your industry, you may need SOC 2 Type II, HIPAA, PCI DSS, or GDPR compliance baked into your technology architecture from the start. Retrofitting compliance controls into an existing system costs roughly three to five times more than building them in during the initial design phase. I once worked with a fintech startup that launched without payment card compliance because their initial plan assumed they would never process enough volume to trigger the requirement. They hit that threshold within fourteen months and had to pause all new feature development for six weeks while a compliance audit ran. Revenue loss during that window exceeded the original compliance budget by a factor of four.
Vendor lock-in is another structural weakness in most technology plans. When you commit to a single vendor ecosystem, switching costs grow exponentially over time. This is not theoretical. I have seen companies pay exit fees equal to eighteen months of subscription costs and spend another three months rebuilding integrations because their original plan did not include an exit strategy clause. The fix is straightforward. Write data portability requirements into every contract. Require API access to all critical data. Mandate that data exports follow open standards like CSV or JSON, not proprietary formats. These requirements add maybe five percent to your initial evaluation time and save you months of headache if you ever need to leave. Integration debt accumulates silently across most technology stacks. Each new tool you add connects to two or three existing systems. Those connections degrade. APIs change. Authentication methods update. Someone leaves the company and takes institutional knowledge of how the integrations were wired together. The average mid-size organization accumulates enough integration debt within eighteen months to warrant a dedicated cleanup sprint. Budget for that. Plan for it. Treat it the same way you would treat technical debt in your codebase because it is exactly the same problem expressed through a different layer of the stack. The people side of technology plans deserves more explicit attention than it typically gets. You need to identify champions early, not after launch. Champions are not managers. They are the people who actually run the processes you are trying to improve. Give them access to the technology two weeks before the rest of the team. Ask them to break it. Their feedback during that trial period catches issues that no project manager would ever anticipate because those issues only appear during actual usage, not during testing with test data and test scenarios. I used to skip this step because it felt like delaying launch. Launching early without champion input caused more delays later because the system required two or three redesign cycles after rollout. The two-week early trial typically saves three to four weeks of post-launch firefighting.
Finally, document everything in a way that survives the people who wrote it. Runbooks, architecture diagrams, decision logs, and change histories are not optional extras. They are the minimum infrastructure required to maintain a technology plan beyond the first year. I keep a living document for each system that records every configuration change, every incident, every workaround, and every decision rationale. This document becomes the primary knowledge source for anyone who inherits the system, including your future self. Six months after a project ends, you will not remember why you made half the choices you made. The documentation does that remembering for you.