Working With Point Patterns in R
Spatial point pattern analysis is one of those topics that sounds more complicated than it needs to be once you actually sit down and use it. The main package people reach for is spatstat, and it handles most of the heavy lifting for you. You give it a set of x-y coordinates, tell it what your study window is, and from there you can compute intensities, run tests for randomness, fit models, and generate simulations. The learning curve is real but not brutal if you approach it in the right order. The first thing you need to do is load the data into the correct format. spatstat expects an "owin" object for the window and an "ppp" object for the points. Loading a CSV with two columns, x and y, takes about three lines of code, but getting the window right is where most people hit their first wall. If your data comes from a bounded area like a forest plot or a transect, you need to define that boundary precisely. A rectangle is straightforward — just specify the x and y ranges. Anything more complex requires an owin object with polygonal boundaries, and spatstat provides functions like readpol for reading in shapefiles. I spent an afternoon once debugging a K-function result that looked completely wrong, only to realize the window polygon had a self-intersecting segment. spatstat didn't throw an error, it just silently computed over a malformed region and produced garbage output. I ended up rewriting the boundary using polyclip to clean it up first. That's something the documentation won't warn you about directly because it's an edge case that rarely comes up in tutorials.
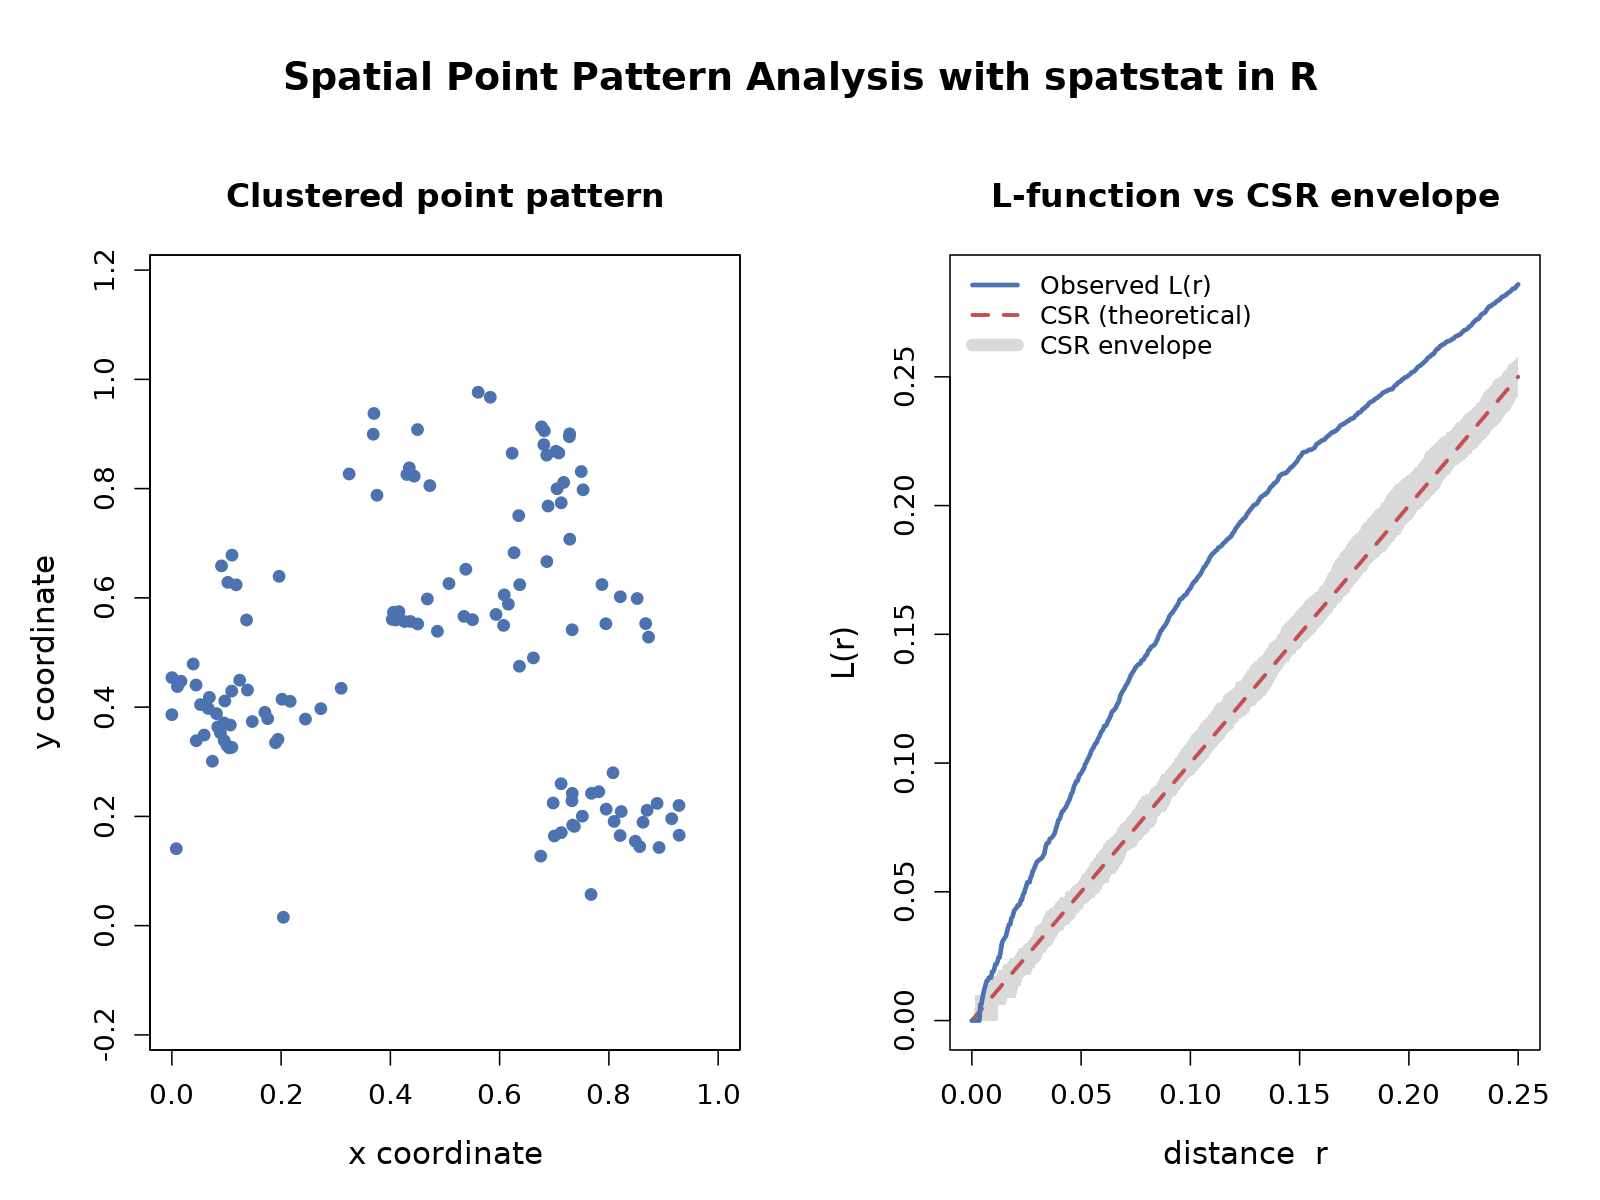
Once your objects are set up, the most useful function to start with is Kest. It computes Ripley's K function, which tells you whether your points are clustered, dispersed, or randomly distributed at different distance scales. The default output gives you an observed K value and a simulated envelope based on the theory-driven expectation under a homogeneous Poisson process. If the observed curve stays within the envelope, you have no evidence against complete spatial randomness. If it rises above, you're looking at clustering. If it falls below, regularity or inhibition is at play. Here's what that looks like in practice: library(spatstat)
mydata <- read.csv("my_points.csv")
window <- owin(xrange=c(0,100), yrange=c(0,50))
points <- ppp(mydata$x, mydata$y, window=window)
kresult <- Kest(points, edges="border")
plot(kresult)
That gives you a basic plot. The "edges" argument controls how edge corrections are handled, and the default "border" method tends to be conservative. For large datasets with many points near the boundary, "Ripley" or "translation" corrections often give less biased estimates. You choose this based on your data density and window shape. One counter-intuitive thing about K-function analysis that people miss is that you can have a pattern that looks clustered at short distances and random at longer distances, and that doesn't necessarily mean anything dramatic is happening. It usually means your points are grouped into small clusters that are themselves randomly placed across the study area. The K function aggregates across all distances, so the signal from the clustering gets diluted as r increases. Checking the L-function, which is just a variance-stabilized version of K, makes this easier to see because it straightens out the expected growth curve. If you want to model the underlying intensity rather than just test for randomness, you can use the ppm function. It fits Poisson point process models where the log-intensity is modeled as a function of covariates. The syntax mirrors glm, which helps if you're already familiar with generalized linear models:
Get the Full Details
model <- ppm(points ~ elevation + vegetation, data=your_covariates) The key thing to remember here is that ppm assumes the study window is known and fixed, which sounds obvious but trips people up when they try to combine point data from multiple irregularly shaped plots. You need a single unified window, not separate windows per plot, unless you explicitly define that in the owin object. For simulation-based inference, which is where point analysis in R really shines, you can use envelope to generate Monte Carlo confidence bands around any summary function. The standard approach is to simulate under the null hypothesis — usually complete spatial randomness — and compare your observed statistic against the distribution of simulated values. Running 99 simulations gives you roughly a 95 percent confidence envelope, and increasing to 199 gives you a bit more resolution. The trade-off is computation time. On a moderate dataset of 500 points, 99 simulations typically take 10 to 30 seconds depending on your machine and the complexity of the summary function.
A word on computational limits: spatstat is single-threaded for most operations. If you're working with datasets larger than about 50,000 points, functions like Kest and envelope start taking minutes instead of seconds. I've had to switch to the cluster R package for parallel processing on larger datasets, but you lose some of the convenience of the built-in functions. There are workarounds involving splitting the data and combining results, but those introduce their own biases around boundary handling. Another thing that catches people off guard is edge correction. The border correction removes points within distance r of the window edge before computing distances, which reduces bias but also reduces effective sample size. For small windows with many points, this can noticeably shrink your dataset and inflate variance in your estimates. The translation correction is less biased but can produce negative estimates for K(r) at larger distances, which then get truncated to zero in plotting functions. Neither is perfect, and the choice matters more than most guides acknowledge. If you need to export your results for publication, the plot functions in spatstat are decent but basic. Most people end up piping the output to ggplot2 for formatting. You can extract the raw K-values from the result object and replot them however you want. The same applies to simulation envelopes — they're just numeric matrices that you can manipulate directly.
There are other packages worth knowing about. splancs is an older alternative that predates spatstat and uses a different approach to edge correction and simulation. It's less maintained but still functional for basic analyses. spatstat.data has helper functions for loading and manipulating spatial data. And if you're working with marked point patterns — where each point has an associated attribute like species type or diameter — spatstat handles that natively with the "marks" argument, and most functions extend to marked patterns without requiring special setup. The biggest limitation of point analysis in R, honestly, is that spatstat's documentation assumes a level of statistical literacy that many users don't have yet. Reading the help file for Kest won't tell you why your result looks weird or how to interpret a borderline envelope. You learn that by running the same analysis on synthetic data with known properties and seeing what the functions actually do under different conditions. I recommend generating 10 or 20 synthetic patterns — some clustered, some regular, some random — and walking through the full pipeline on each one before trusting it on real data. For getting started, the spatial patterns chapter in R Spatial: Models and Methods for Geographical Information Science by Michael Bivand covers the fundamentals well and pairs nicely with the spatstat handbook available at spatstat.org. The vignettes included with the package are also worth reading, particularly the ones on simulation envelopes and point process models.