How to Use Point Biserial Correlation for Exam Item Analysis
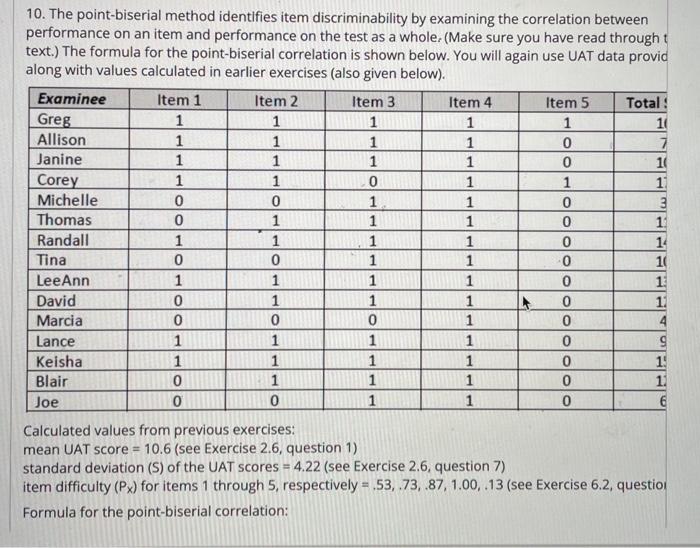
Point biserial correlation is one of those statistics that shows up in every classroom evaluation report but most people compute it wrong because they don't understand what it's actually measuring. It measures the relationship between a dichotomous variable and a continuous variable. In exam terms, that means it tells you whether students who got a particular question right actually scored higher on the overall exam compared to students who got that question wrong. That sounds obvious but the way it is used and interpreted in real testing situations has some quirks that matter. The formula looks like this: rpb = (M1 - M0) / S * sqrt(p * q), where M1 is the mean score of students who answered correctly, M0 is the mean score of students who answered incorrectly, S is the standard deviation of all exam scores, p is the proportion of students who answered correctly, and q is 1 minus p. Most people just plug numbers into this and move on without checking whether the assumptions hold. That is where problems start.
Common Point Biserial Exam Questions and What They're Really Asking
When you see Point Biserial Exam Questions on a certification exam or a graduate methods course, they are rarely testing whether you can recite the formula. They are testing whether you understand what a high versus low point biserial value actually indicates about an item. The tricky ones throw in scenarios where the discrimination looks good numerically but the item is fundamentally flawed in other ways. I ran into this last year when I was reviewing a licensing exam that had passed all standard item analysis thresholds. The item difficulty was around 0.65, the point biserial values were all above 0.30, which is generally considered acceptable discrimination. Everything looked fine on paper. Then I cross-referenced the response data and found that students in the top quartile were getting the question wrong at nearly the same rate as students in the bottom quartile, but the point biserial was still coming out positive because of how the mean difference interacted with the standard deviation. The item was essentially random noise with a slightly inflated discrimination coefficient. I ended up flagging it for revision and switching to a combination of point biserial plus a two-parameter IRT model for future items. That one experience changed how I approach item analysis entirely. The formula assumes that the continuous variable is approximately normally distributed and that the dichotomous variable is truly random and not artificially created. When you are working with exam data, the continuous variable is usually the total test score. If the test is too easy or too hard, the distribution of total scores becomes skewed and the point biserial loses its interpretability. A negatively skewed distribution, which happens when a test is very easy, will artificially depress point biserial values even for well-constructed items. The opposite happens with very difficult tests.
Another thing most people miss is that point biserial is sensitive to the range of scores in your sample. If you restrict the ability range by only looking at high-performing students, the point biserial will drop because there is less variability in the continuous variable. I have seen test developers panic over point biserial values below 0.20 and discard items that were actually perfectly fine, only to realize later that their sample was too homogeneous. The fix is to check the standard deviation of total scores first before judging discrimination. If the SD is unusually low, that is your red flag, not the point biserial itself. Interpreting the values follows a general convention that most textbooks will tell you. Values above 0.30 indicate good discrimination, values between 0.20 and 0.29 are marginal and may need revision, and values below 0.19 suggest the item is not measuring what it should. But here is the part nobody emphasizes enough: these thresholds were derived from educational testing contexts with large sample sizes and normally distributed scores. If you are working with fewer than 50 students or a highly skewed score distribution, those cutoffs are basically meaningless. I usually tell people to treat any point biserial below 0.15 with suspicion regardless of the textbook threshold, especially in small sample situations. There is also the issue of negative point biserial values. A negative value means students who got the question wrong actually scored higher on the overall exam than students who got it right. This is almost always a sign of a problematic item. The most common causes are a flawed correct answer key, a question that is ambiguously worded so that stronger students overthink it and choose a distractor, or a question that taps into a skill unrelated to what the exam is supposed to measure. I once spent three weeks tracking down a negative point biserial on a medical board exam and it turned out the question had a typo in the stem that made the intended correct answer actually incorrect. The strongest students caught the typo and marked it wrong, while weaker students just guessed the intended answer. That is the kind of thing that only shows up through item analysis, not content review.
Get the Full Details

If you need to compute these values yourself, most people use SPSS, R, or a basic spreadsheet. The R code is straightforward. You run a cor.test function with the item response coded as 0 or 1 and the total score as the continuous variable. The output gives you the correlation coefficient, the confidence interval, and the p-value in one go. I prefer R because it handles missing data more gracefully than most GUI-based tools. SPSS gives you the item-total statistics automatically under the scale menu, which is faster if you are analyzing a full test rather than individual items. The shortcut many people take is to rely solely on item-total correlation instead of point biserial. For dichotomous items, they are mathematically equivalent, so either works. But when you have polytomous items with multiple score levels, point biserial does not apply and you need to switch to something like the polychoric correlation or IRT-based discrimination parameters. I see this mistake regularly in exam development meetings where someone will insist on using point biserial for Likert-scale items and wonder why the results look wrong. One practical workflow I recommend is running the point biserial analysis alongside difficulty indices and distractor analysis in a single pass. Difficulty tells you whether the item is appropriately hard. Point biserial tells you whether the item discriminates between high and low performers. Distractor analysis tells you whether the wrong answer choices are actually functioning. All three together catch problems that any single metric misses. Doing them separately just creates gaps where errors hide.
For people studying for exams that include Point Biserial Exam Questions, the most important thing to internalize is that this statistic is descriptive, not diagnostic. It tells you something is off, but it does not tell you why. The follow-up work, reviewing the item text, checking the answer key, examining the response patterns, that is where the actual quality control happens. Memorizing the formula gets you through the multiple choice section. Understanding what happens when the assumptions break gets you through the actual job. There is no single downloadable tool that does everything correctly out of the box because the interpretation always depends on your sample characteristics and your testing context. The closest thing to a standard resource is the Educational Testing Service handbook on item analysis, which covers the limitations and edge cases more honestly than most academic textbooks. For a practical guide that walks through computation and interpretation with real exam data examples, the book "Measuring Psychological Variables" by Anderson covers this in more depth than the typical methods course. If you are designing an exam and want to set up item analysis that actually catches problems before you publish, start with a pilot sample of at least 100 students before you calculate any discrimination indices. Below that sample size, the point biserial values become unstable enough that you are making decisions based on noise rather than signal. I have seen entire test editions revised based on item analysis from samples of 30 students and then re-administered with 200 students where half the "bad" items looked perfectly normal. The lesson there is straightforward: small samples make point biserial unreliable, and acting on unreliable statistics is worse than not acting at all.