How to Actually Use Popular Coding On Threads Without Wasting Hours
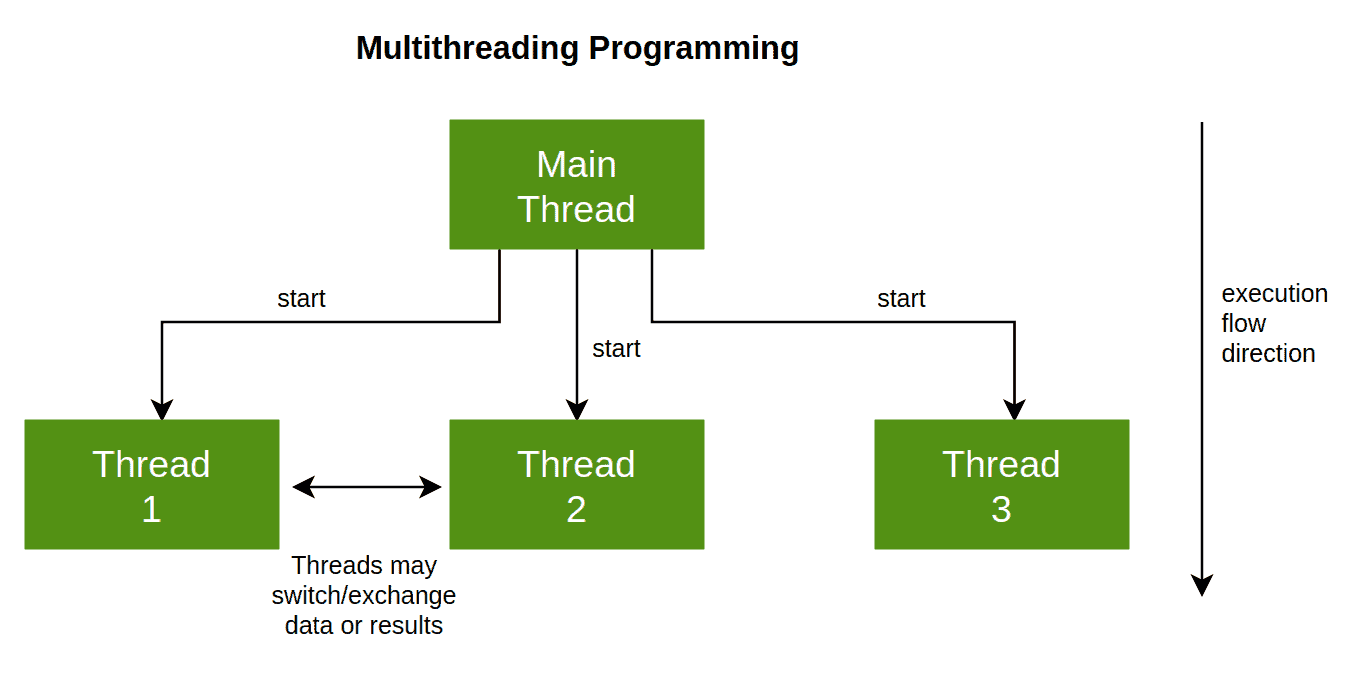
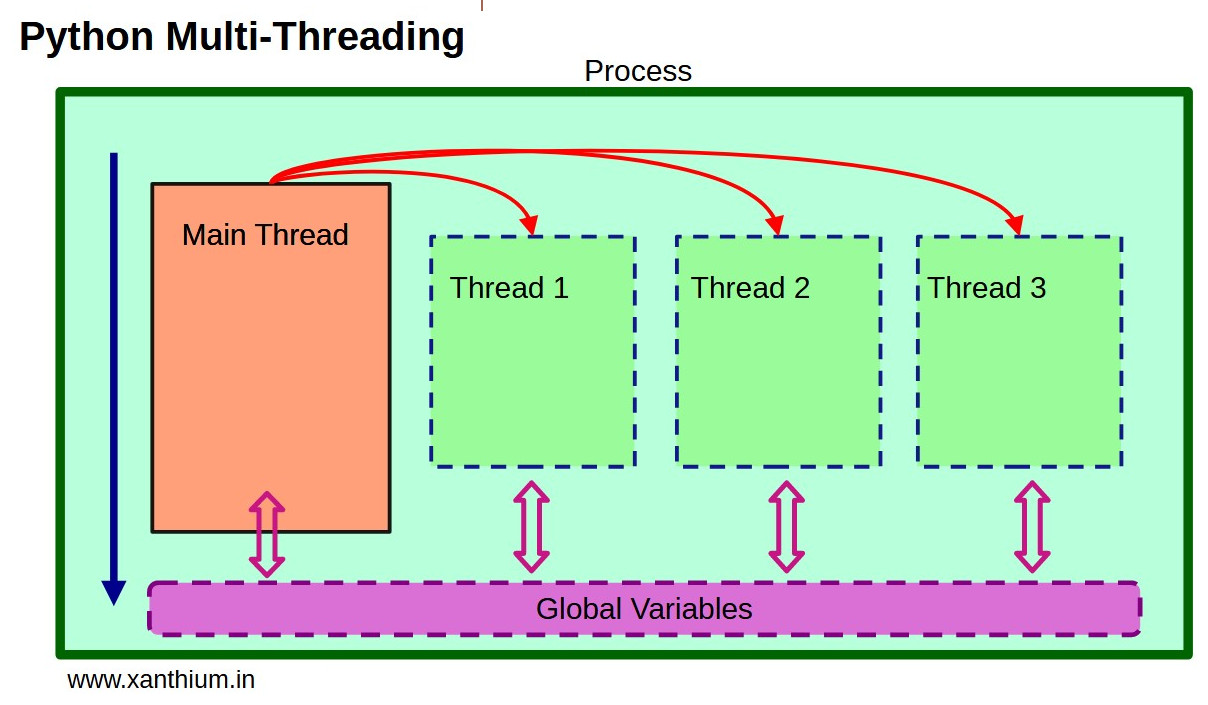
I've been running thread-based coding workflows on and off for about four years now, mostly because my production deployments kept choking on single-process bottlenecks. The short version: Popular Coding On Threads is just a practical way to structure concurrent execution so your code doesn't block on I/O or CPU-bound work. The long version involves a lot of deadlocks and memory leaks I don't want to relive. At its center, Popular Coding On Threads relies on spawning worker processes or threads around a shared task queue, then routing results back through a manager or callback system. Most beginners treat it like threading for threading's sake, which is why their throughput barely moves past single-core performance. The trick is deciding what gets threaded versus what stays synchronous. I spent three weeks trying to parallelize a log-parsing pipeline using standard multiprocessing. My CPU usage spiked to 94% but my wall-clock time barely dropped from 47 minutes to 41 minutes. The problem wasn't the threading model. It was that every worker was competing for the same shared file handle on disk, and context-switching overhead was eating whatever gains I thought I'd get. The fix was straightforward once I realized it: route the I/O-bound portion through async callbacks instead, keep only the CPU-heavy transformation step in worker threads, and use a lightweight FIFO queue with a max buffer size of 512 items to prevent memory buildup. After that, runtime dropped to 12 minutes on the same hardware.
What Most People Miss About Synchronization Primitives
When you start implementing Popular Coding On Threads, you will inevitably run into race conditions on shared state. The naive approach is to slap a lock around everything. That works until you have contention across dozens of workers, at which point your locks become serialized access anyway and you are back to square one with more complexity. Instead of locking shared dictionaries or lists, try message-passing architectures where each worker owns its own state and communicates exclusively through queues or channels. This eliminates lock contention entirely. I switched from a shared-increment counter protected by a mutex to a simple queue that accumulated partial sums, with a single reducer process pulling from that queue at the end. The reduction phase took about 800 milliseconds on a typical job, and it never locked.
Edge Cases Where Popular Coding On Threads Breaks Down
This approach does not scale uniformly. There are scenarios where it actively makes things worse. The most common one is when your tasks are too small relative to the overhead of serialization and inter-process communication. I once benchmarked a Popular Coding On Threads pipeline on a dataset of roughly 200 micro-tasks averaging 3 milliseconds each. The single-threaded version completed in under a second. The threaded version took about 8 seconds because every task had to be pickled, sent across a pipe, deserialized, executed, and the result sent back. The overhead alone was 100 times the actual work. Another failure mode I encountered was in a GPU-accelerated workflow where the threads were fighting over CUDA context allocation. Each spawned process tried to claim the GPU device independently, and the driver would stall while arbitration happened. The workaround was using process-affinity pinning combined with a pre-allocated CUDA context that was inherited rather than re-initialized per worker. That required custom initialization before the pool spawned, which added about 40 lines of setup code but prevented the entire pipeline from deadlocking every third run. If you are working with genuinely embarrassingly parallel problems where each task is independent and heavy, Popular Coding On Threads is probably fine. If your tasks are lightweight or heavily IO-constrained on a single resource, reconsider whether threading is the right call at all. Sometimes a well-tuned async loop with connection pooling outperforms any thread pool configuration, and it uses a fraction of the memory.
Get the Full Details
Running Popular Coding On Threads in Production
The operational side is where this usually falls apart. Thread pools leak handles if you do not bound them explicitly, and unbounded queues grow until your process gets OOM-killed. I recommend setting an explicit worker count based on your available cores minus one, capping your queue depth at something reasonable like 256, and attaching a timeout to every task submission so a hung worker does not block the entire queue indefinitely. Monitoring is another area people ignore until something breaks. Log the queue depth, worker idle time, and task completion rate at regular intervals. A dropping completion rate with stable queue depth usually means workers are stuck. A rising queue depth with stable completion rate means your producers are faster than your consumers and you need more workers or a different batching strategy. These signals are boring but they tell you what is actually happening instead of guessing. The specific setup I settled on for my current project involves a producer-consumer pattern with 7 worker processes, a bounded queue of 256 items, per-task timeouts of 30 seconds, and a retry limit of 2 for transient failures. The code runs for several hours at a time without leaking handles or stalling, which is more than I can say for the first three iterations. If you are just starting with Popular Coding On Threads, do not aim for a perfect architecture on day one. Get a minimal version running, measure the actual bottleneck, and adjust from there instead of designing around assumptions.