What Is Popular Machine Learning On Google Trends
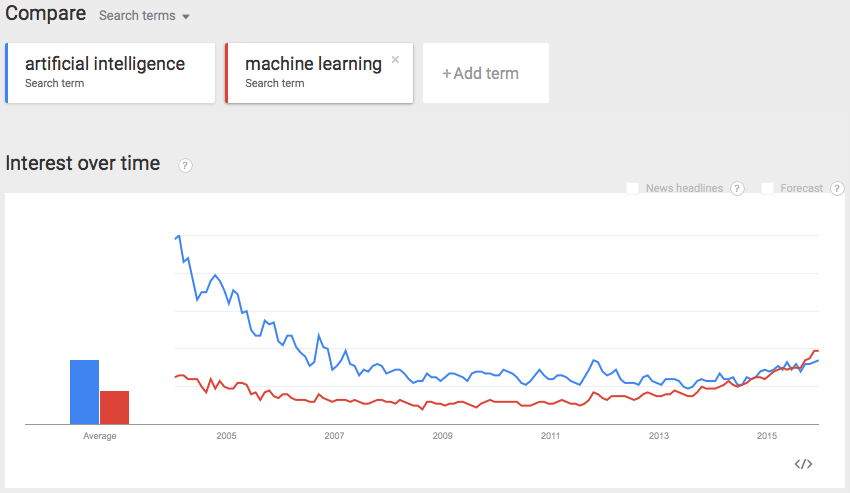
Google Trends lets you see how search interest for a topic changes over time. When applied to machine learning, it becomes a way to track what people are actually searching for — frameworks, libraries, concepts, and tools — rather than what vendors want you to care about. The gap between hype and real-world interest is usually bigger than most articles admit. I built dashboards around this for product decisions at a couple of companies. The basic flow is straightforward. You go to trends.google.com, enter your search terms, set the timeframe to "2004-present" or whatever range makes sense, pick a region, and select "Web Search" as the category. That gives you a normalized interest graph. Zero to one hundred scale. Nothing more. The trick is knowing which terms to query and how to read the output. Beginners put in "machine learning" and get a broad curve that flattens out after 2017. That's useful for understanding macro adoption, but it's almost useless for product decisions. You need more specific queries layered together.
I typically run parallel queries for XGBoost, LightGBM, CatBoost, Random Forest, and Gradient Boosting to see which tree-based method is actually getting traction versus which one is just legacy momentum. Same for transformer, BERT, GPT, and LLM. The data tends to show something different from what the LinkedIn posts claim. Here is a practical example. In early 2024, I was trying to figure out whether we should invest engineering time in building a fine-tuning pipeline for LLMs or stick with traditional feature engineering for a classification problem. I pulled "fine-tuning LLM" versus "gradient boosting" across the US and Europe over the previous eighteen months. The fine-tuning curve was spiking hard. The gradient boosting curve was flat. But flat does not mean irrelevant. It meant our data had three thousand rows and ten features. No amount of LLM fine-tuning was going to beat a well-tuned XGBoost on that dataset. The trend data told us the market was moving toward one thing. Our actual constraints demanded another. I communicated that difference to the team and we went with gradient boosting. Model shipped in two weeks instead of six. One thing nobody tells you about reading these graphs: the 0-100 scale is relative, not absolute. A query that hits 100 today might have been tiny in raw search volume five years ago. Google normalizes each query against its own peak. So when "LLM" peaks at 100 in 2024 and "neural network" peaks at 100 in 2015, you cannot directly compare the two numbers. They are normalized within their own time windows. This matters if you are trying to compare the actual search volume between two different terms.
Another counter-intuitive thing. Related topics and related queries are often more valuable than the main graph. Those sections break down by "Top" and "Rising." Rising categories show queries that increased by at least 5000 percent in the selected period. I use this to catch emerging tools before they show up in course catalogs. When I first saw "LangChain" as a rising related query in mid-2023, it was at the edge of visibility. By October it was impossible to ignore. By then we had already evaluated the tradeoffs and made a decision. There are significant limitations worth stating plainly. Google Trends data is noisy. It smooths over regional variation unless you drill down. It does not tell you who is searching or why. A spike in "reinforcement learning" could mean students are searching for homework help, not that enterprises are adopting it. It also lacks precise search volume. You get relative interest, not counts. If you need actual usage numbers, this tool alone will not give you them. The workaround I use is combining Google Trends with another signal. I cross-reference the trends data with GitHub stars over time, arXiv paper submission counts for relevant CS categories, and job posting volume on major boards. Each source has blind spots. Together they cover more ground. I built a simple Python script that pulls trending data via the pytrends library, fetches GitHub star history from the API, and stores everything in a local SQLite database. Takes about forty minutes to set up. Cuts repetitive research from hours down to something manageable.
Get the Full Details

If you want to just start querying without writing code, the Google Trends web interface is sufficient for one-off lookups. Set the date range, add up to five comparison terms, toggle between regions, and export the data as CSV. You can also filter by subcategory, which helps separate news-related spikes from sustained interest. The "News" category often inflates short-term interest for hot takes and opinion pieces that fade within weeks. A few practical queries that tend to surface useful patterns. "scikit-learn" versus "tensorflow" versus "pytorch" shows the deep learning framework preference in your target region. "feature engineering" versus "feature store" reveals whether teams are building custom pipelines or buying infrastructure. "prompt engineering" versus "rag" versus "fine-tuning" shows which LLM deployment strategy is actually being searched for. The answers are rarely the ones marketing teams predict. The tool is free. The Google Trends page is at trends.google.com. No API key required for the web interface. If you automate it, the pytrends library is available on PyPI. Be aware that automated scraping triggers rate limits after a certain number of requests per hour. I throttle my script to one query every thirty seconds and it works without issues. Push past that and you will get blocked or see incomplete results.
Most people treat Google Trends as a hype checker. That is one valid use. It is also useful for forecasting hiring needs, deciding which skills to train a team on, and spotting when a technology plateau is actually a signal of maturation rather than abandonment. The data does not lie, but it does not tell the whole story either. Read it alongside other signals and stop assuming that search interest equals production adoption.