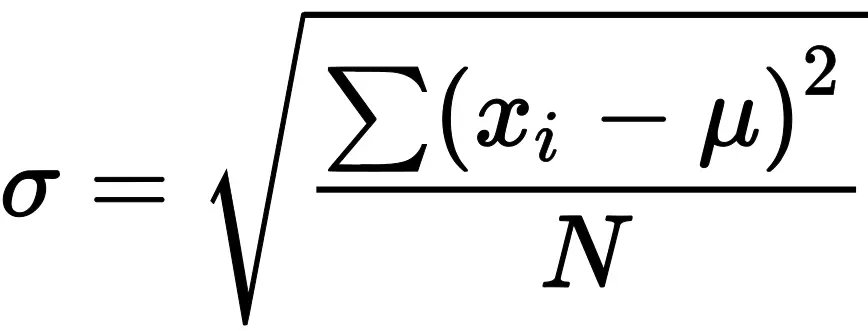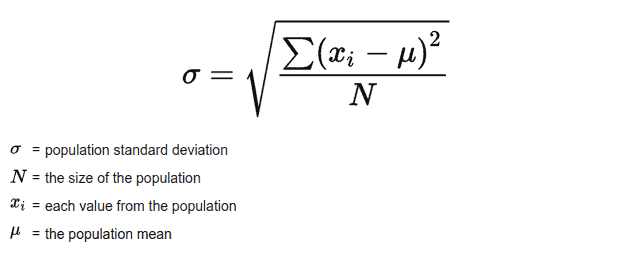
What the Population Standard Deviation Equation Actually Does
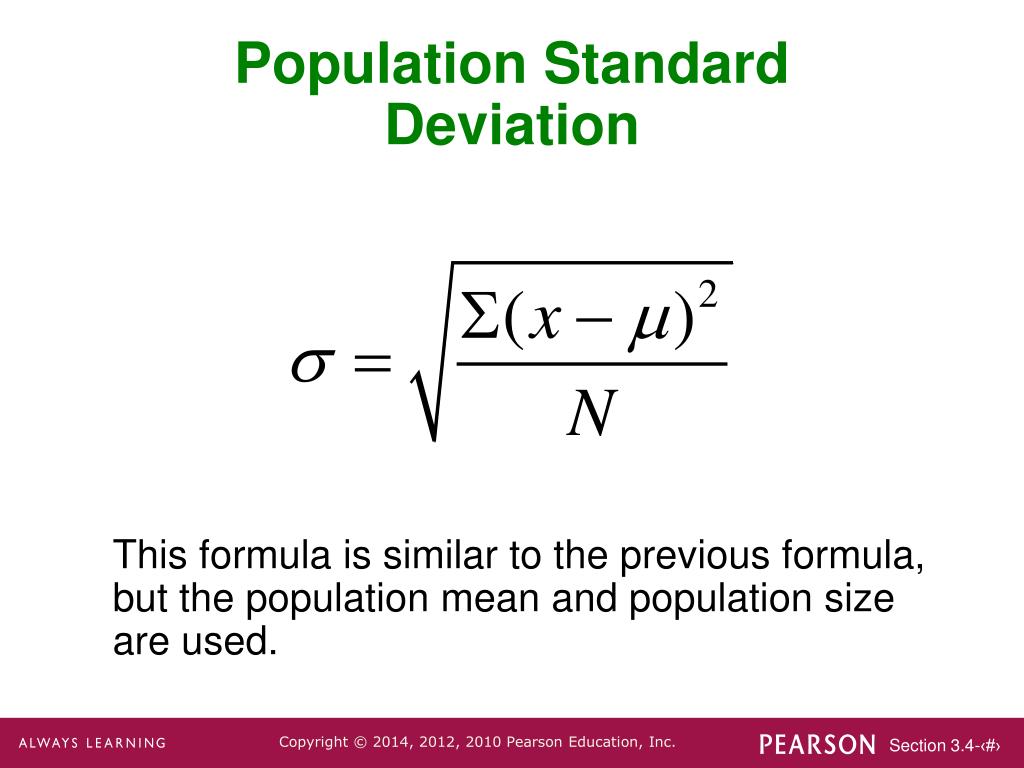
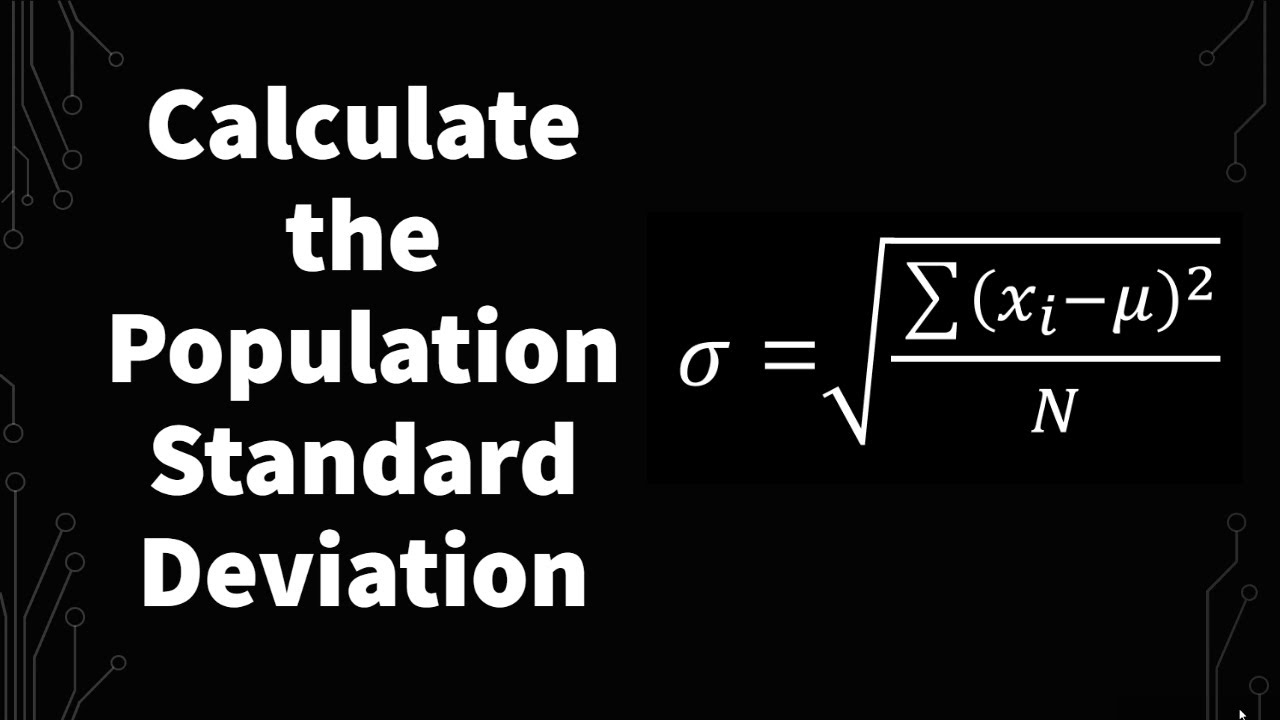
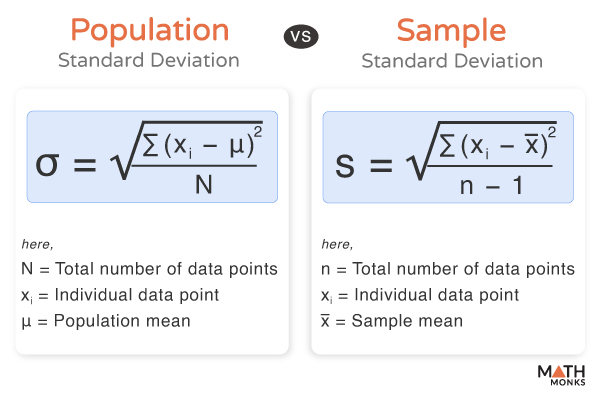
You probably learned it in stats class and then immediately forgot it. I get it. The equation itself is straightforward enough — you're measuring how spread out every value in a dataset is from the mean. The confusion comes from the symbols, not the concept. Here it is written out cleanly: = [ (x - )² / N ] Where is the population standard deviation, x represents each individual data point, is the population mean, means sum across all data points, and N is the total number of observations in the population.
I've seen people trip over this equation in real projects because they mix up population and sample versions. The sample standard deviation uses N-1 in the denominator (Bessel's correction). The population version uses N. If you're working with an actual complete population — which is rarer than people think — you use the N version. If you're estimating from a sample, switching to N gives you a biased result that underestimates the true spread. Let me walk through a concrete example because abstract formulas don't stick. Say you have a small population of five test scores: 8, 12, 15, 20, and 25. First step is calculating the mean. Add them up — that's 80. Divide by 5, you get = 16. Now subtract the mean from each data point and square the results:
(8 - 16)² = (-8)² = 64
(12 - 16)² = (-4)² = 16
(15 - 16)² = (-1)² = 1
(20 - 16)² = (4)² = 16
(25 - 16)² = (9)² = 81 Sum of those squared deviations: 64 + 16 + 1 + 16 + 81 = 178. Divide by N (which is 5): 178 / 5 = 35.6. Take the square root: 35.6 5.97. That's your population standard deviation. I worked on a quality control project a few years back where we were monitoring the diameter of machined shafts. We had measurements from every single unit produced in a batch — roughly 12,000 parts. Someone on the team ran the sample standard deviation formula by mistake, dividing by N-1 instead of N. With a population that size, the difference between dividing by 12,000 versus 11,999 is negligible, but it still gave us the wrong process capability index because we were plugging the biased sigma into our Cp and Cpk calculations. It cost us about two hours of rework to catch. Lesson learned: verify which formula applies before you pass data to anyone else.
Get the Full Details

Here's something most beginner guides won't tell you — the Population Standard Deviation Equation is extremely sensitive to outliers. A single extreme value can inflate dramatically because of the squaring step. I once saw a dataset where the standard deviation jumped from 3.2 to 14.7 because one sensor malfunctioned and logged a value that was fifty times normal. There's no built-in outlier protection in the equation itself. You have to handle that before you calculate, or the result becomes basically useless for decision-making. Another thing people miss: this equation assumes your data is interval or ratio scale. It doesn't work on ordinal data, and it's meaningless on nominal categories. You can't compute a standard deviation for customer satisfaction ratings labeled "low," "medium," and "high" unless you've assigned numerical values first. Even then, the numbers you choose affect the result, and there's no universal correct mapping. I've watched engineers plug Likert-scale survey data into this equation without questioning whether that was appropriate. The output looked precise — it wasn't. For calculation, you don't need fancy software for small populations. A basic spreadsheet handles it fine. In Excel or Google Sheets, the function is STDEV.P() — the .P explicitly denotes population. The older STDEV.S() applies Bessel's correction for samples. On a larger dataset where you need batch processing, Python's numpy library gives you np.std(data, ddof=0) for population standard deviation, where ddof=0 means delta degrees of freedom is zero (no correction applied).
The real limitation of this equation isn't mathematical complexity — it's the assumption that you actually have the full population. In practice, that's almost never true outside of controlled manufacturing or defined administrative datasets. When you use it on a sample thinking it's a population, you systematically underestimate variability. That underestimation propagates into confidence intervals, hypothesis tests, and any model that depends on variance estimates. The error shrinks as your sample grows, but it never fully disappears. For most real-world situations where you're sampling from a larger unknown population, the sample standard deviation with Bessel's correction is the appropriate tool. There's also a computational consideration worth noting. If your data values are very large numbers — say measurements in the millions — the intermediate squared deviations can cause floating-point overflow in some programming environments. I encountered this when processing financial transaction amounts where the mean was in the hundreds of thousands. The squared terms exceeded the precision limits of standard double-precision arithmetic. The workaround was centering the data first by subtracting the mean before squaring, which keeps the intermediate values manageable without changing the final result.