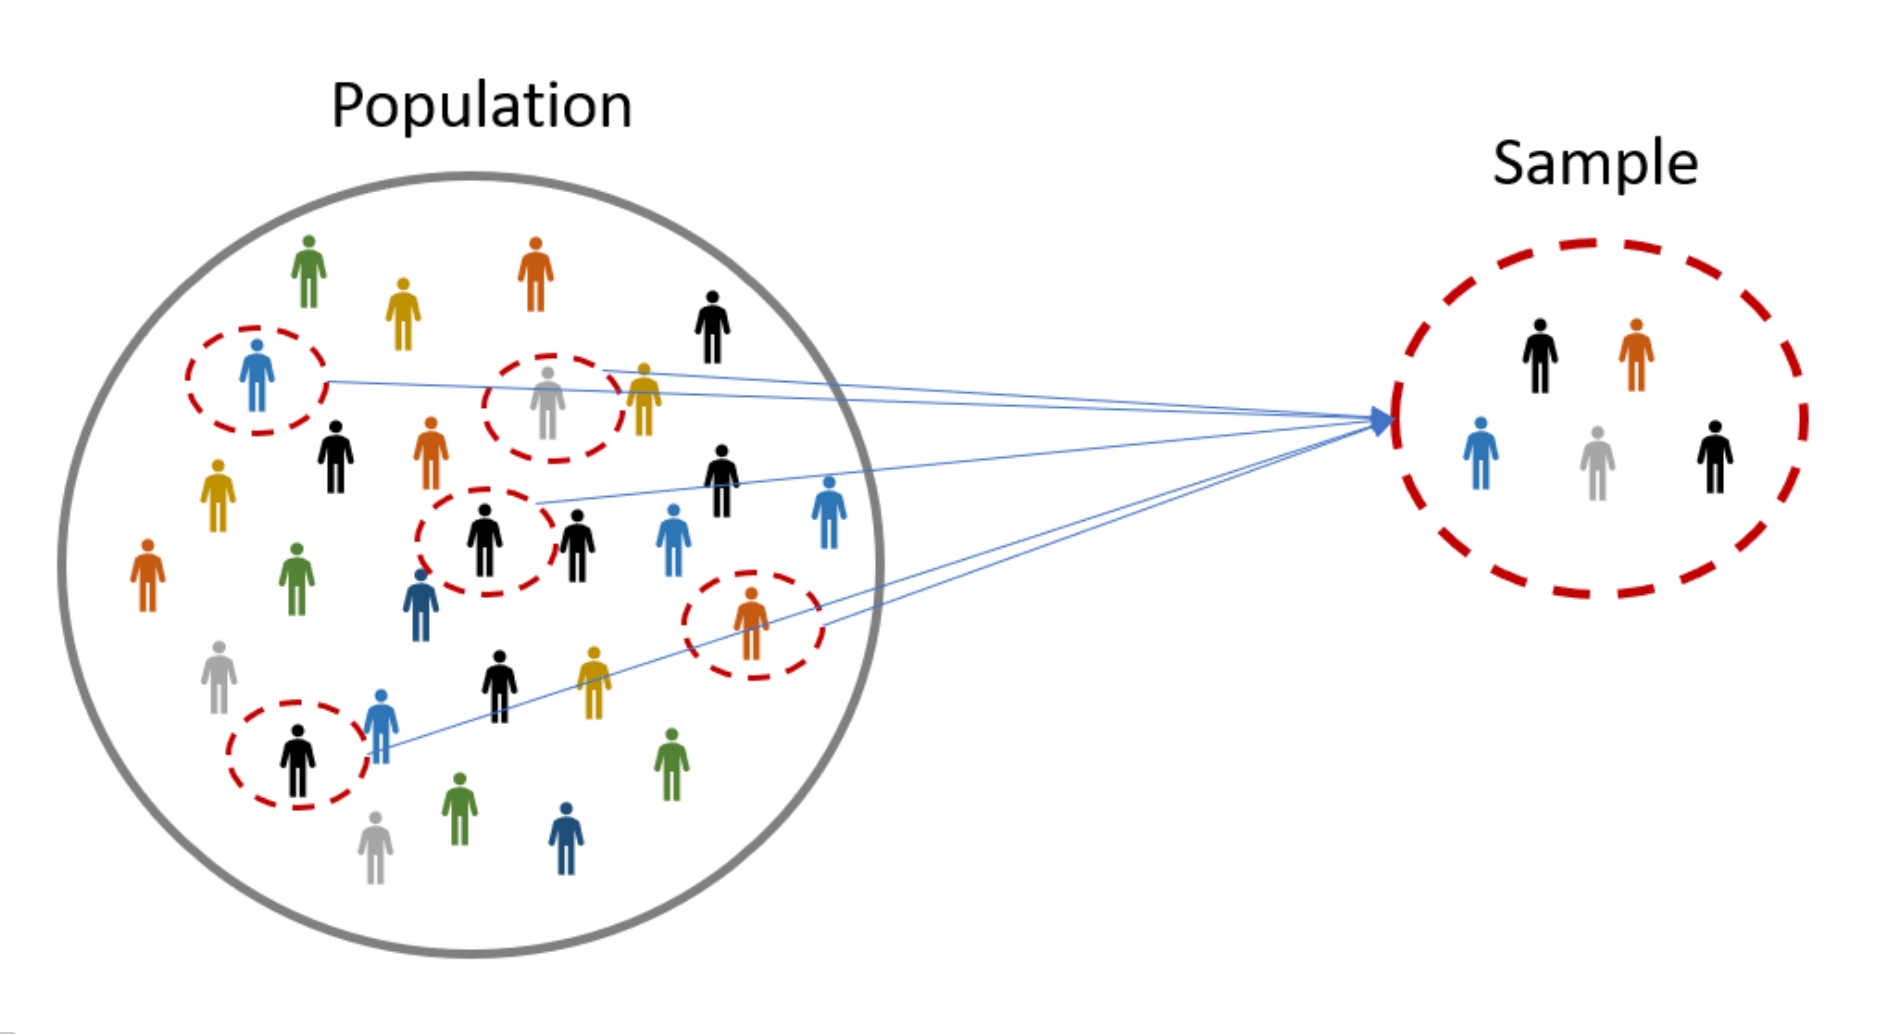
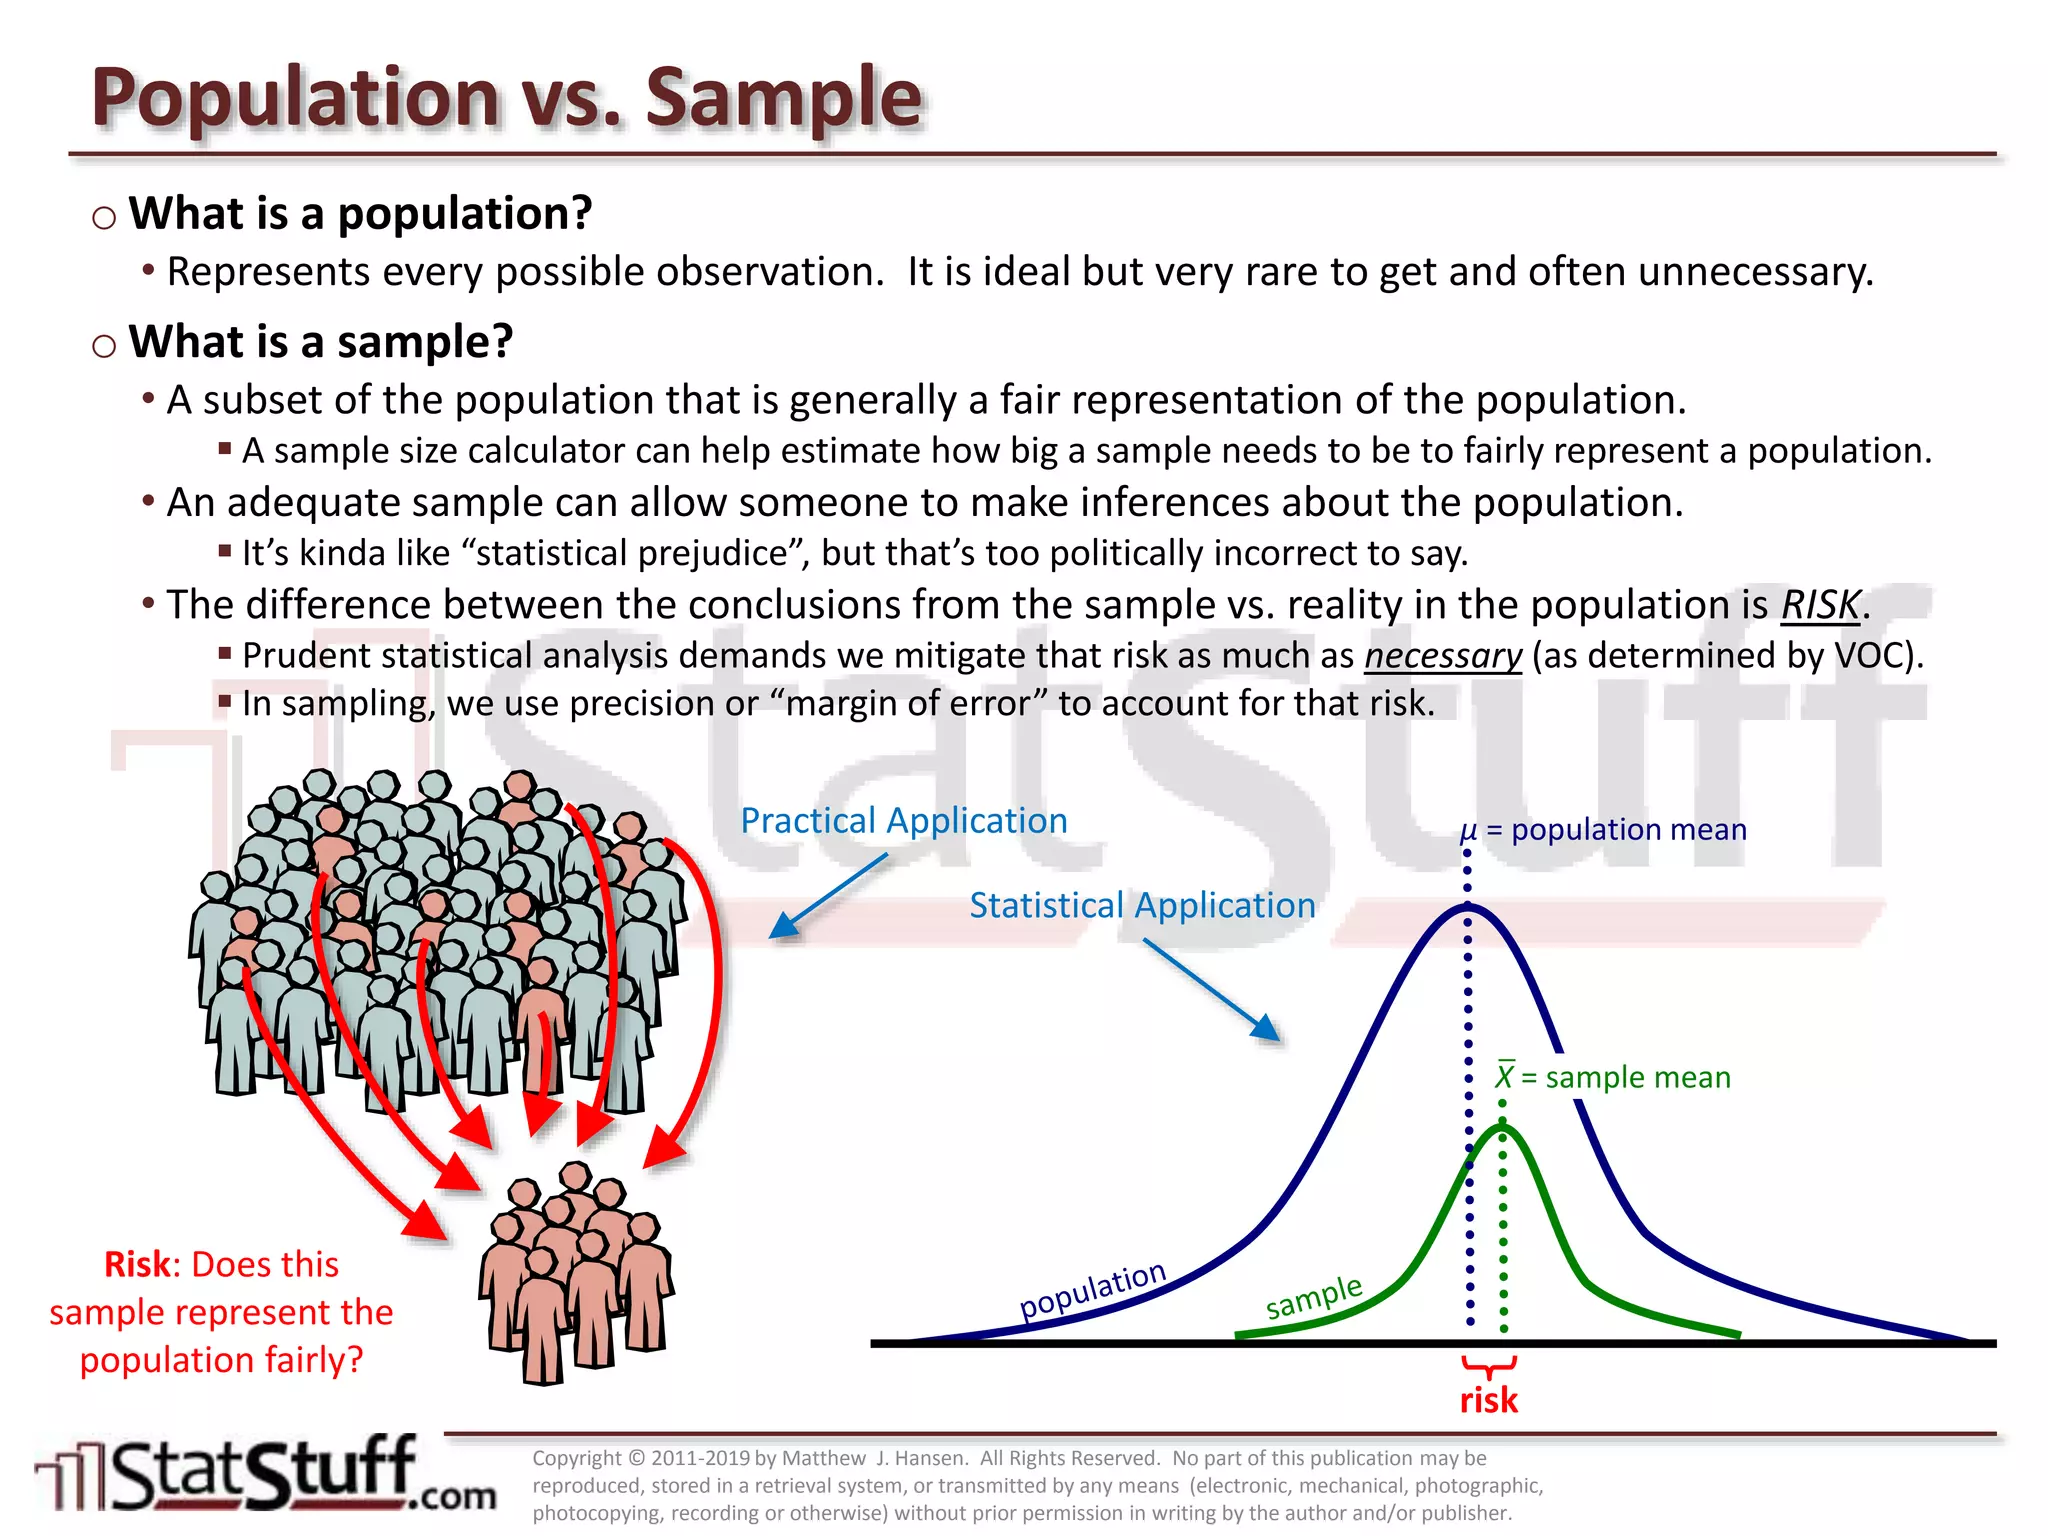
The difference between population and sample statistics matters more than most people think
I learned this the hard way during a quality audit at a manufacturing plant about seven years ago. We were sampling batches of circuit boards from a production run of roughly 40,000 units. The sample mean defect rate came in at 2.3 percent, which looked fine on paper. But the standard deviation across different sample groups was wildly inconsistent. Someone had used the sample standard deviation formula instead of adjusting for the finite population, and that threw off every confidence interval we calculated. We ended up having to pull the raw data from three separate shifts and recalculate everything by hand because the automated spreadsheet formulas had baked in the wrong variance estimator from the start. That process took about six hours. It would have taken twenty minutes if we had caught it during setup. Population statistics describe an entire group. Sample statistics estimate characteristics of that group based on a subset. That sounds simple but the operational difference changes how you calculate variance, how you construct confidence intervals, and whether your results are actually defensible when someone asks questions about the methodology.
Population Vs Sample Statistics in Practice
When you have the full population, you calculate the population mean as the sum of all observations divided by N, where N is the total number of elements. The population variance divides by N. With a sample, you divide by n minus one, not n. This is Bessel's correction and it exists because a sample tends to underestimate the true population variance. Dividing by a smaller number pushes the estimate upward to compensate for the bias that comes from selecting only part of the group. Most beginners miss something important here. The n minus one correction assumes you are sampling with replacement or from an effectively infinite population. If you are sampling without replacement from a population where your sample size is more than five percent of the total, you need the finite population correction factor. Without it, your standard errors are too large and your confidence intervals are unnecessarily wide. I once worked with a team that sampled 800 employees from a company of exactly 1,200. They reported a confidence interval that was 40 percent wider than it needed to be because they never applied the FPC. The actual margin of error should have been around 2.8 percent. Theirs came out to 4.1 percent. That difference changed the entire recommendation they gave to leadership about a workplace policy change. The formulas themselves are straightforward enough but the choices you make around them compound quickly. When you compute a sample proportion, the standard error is sqrt[p-hat times 1 minus p-hat divided by n]. For a sample mean, it is s divided by the square root of n. Both of these assume random sampling. They also assume the data approximately follows a normal distribution or that n is large enough for the central limit theorem to kick in, which typically means 30 or more observations depending on how skewed your underlying distribution is.
There is a common misconception that sample statistics become useless once your sample exceeds a certain threshold. That is not true. Sampling variability decreases as your sample grows, but it does not disappear. A sample of 5,000 from a population of 50,000 still carries uncertainty, and you need to show that uncertainty with proper confidence intervals rather than just reporting point estimates. Conversely, a sample of 200 from a population of 2 million and a sample of 200 from a population of 50,000 have nearly identical margins of error because the finite population correction barely matters at those scales. The sample size matters more than the population size in most real-world situations. Another thing people overlook is the difference between descriptive and inferential use. Population statistics are descriptive by nature. They tell you what happened. Sample statistics are inferential. They let you make claims about the larger group with a quantified level of uncertainty. Mixing these up leads to statements like claiming a sample proportion of 15 percent is the true proportion in the population with no range attached. That is not how statistics works. Even when you survey the entire population, measurement error and non-response can introduce bias that no formula corrects for. Here is a scenario where sample statistics completely break down and you should recognize it before you waste time running the analysis. If your sampling frame is biased because the list you are drawing from excludes a significant segment of the population, no amount of sample size increase will fix it. A political polling firm once ran a model based on landline phone numbers during the 2016 election cycle and consistently missed the mark because younger voters had largely abandoned landlines. They could have taken a sample ten times larger and still gotten the same wrong answer because the frame itself was misaligned with the target population. Weighting adjustments can help somewhat but they cannot recover people who are entirely absent from the frame.
Get the Full Details
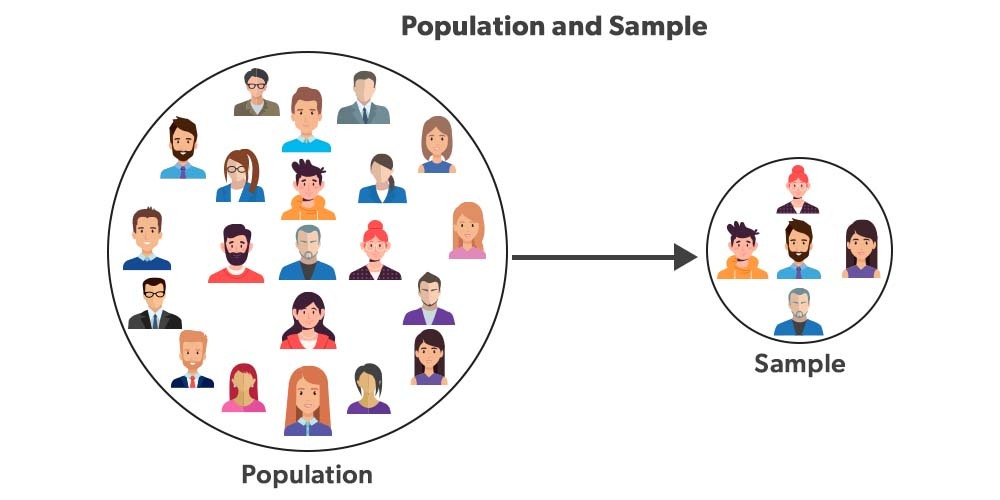
When deciding between using population parameters versus sample estimates, ask yourself whether the full population data is actually accessible and complete. In many cases, what looks like a population dataset is really a convenience sample with missing records. Healthcare data is a common example. Hospital records exist for patients who showed up, but they do not capture people who never sought treatment. Treating that dataset as a population gives you false confidence in the numbers. If you need to calculate this manually, start by identifying whether your data represents the entire population or a drawn subset. Then determine your parameter of interest, whether it is a mean, variance, proportion, or something more complex like a ratio estimator. Apply the appropriate formula with the correction factors that match your sampling design. If you are using software, verify that the function you are calling uses n minus one for sample standard deviation and check whether it applies finite population correction automatically. Most basic functions do not. The key takeaway is that the distinction between population and sample statistics is not just a mathematical detail. It determines whether your conclusions are valid, whether your confidence intervals are correctly sized, and whether you can defend your methodology under scrutiny. Get the distinction wrong at the start and every calculation downstream inherits that error.