The Basics Nobody Gets Right
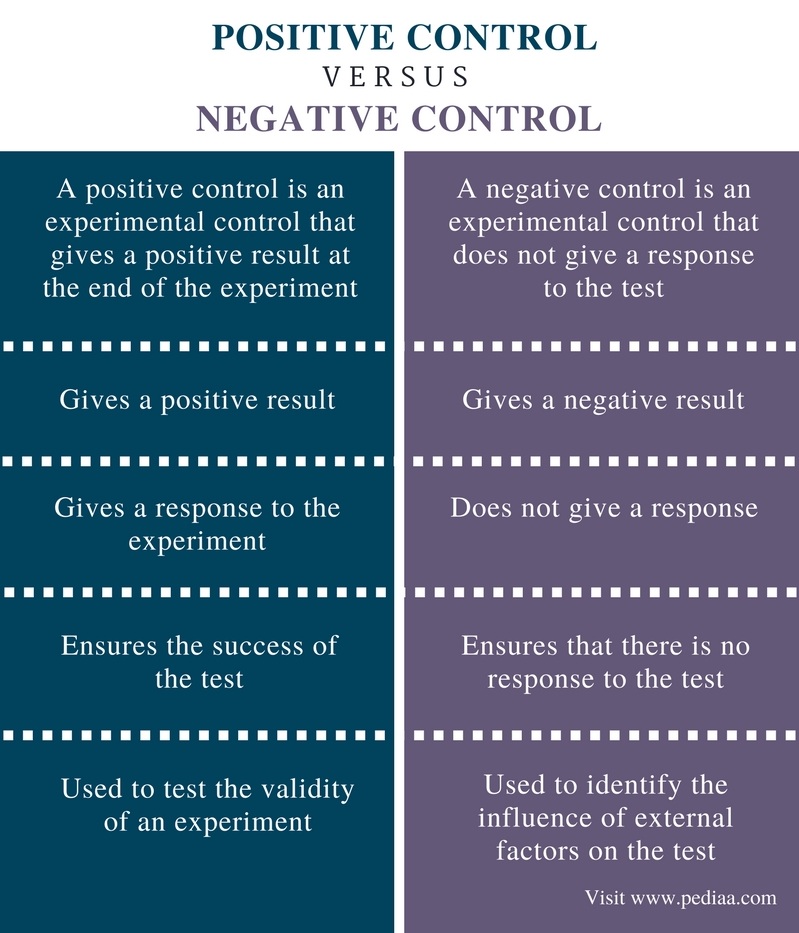
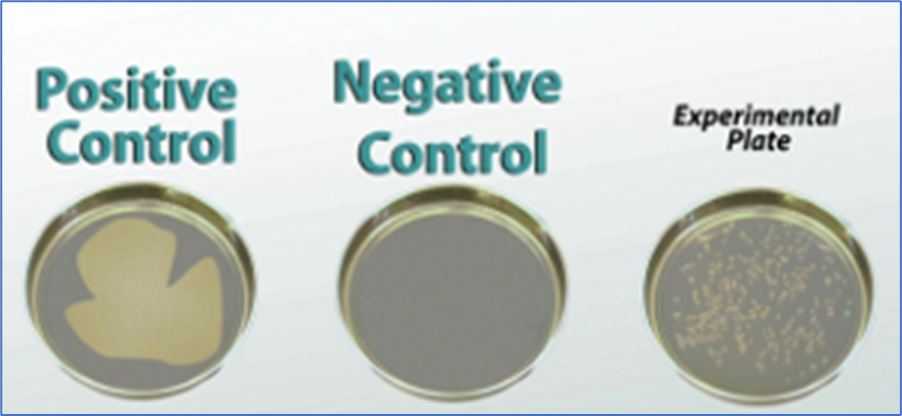
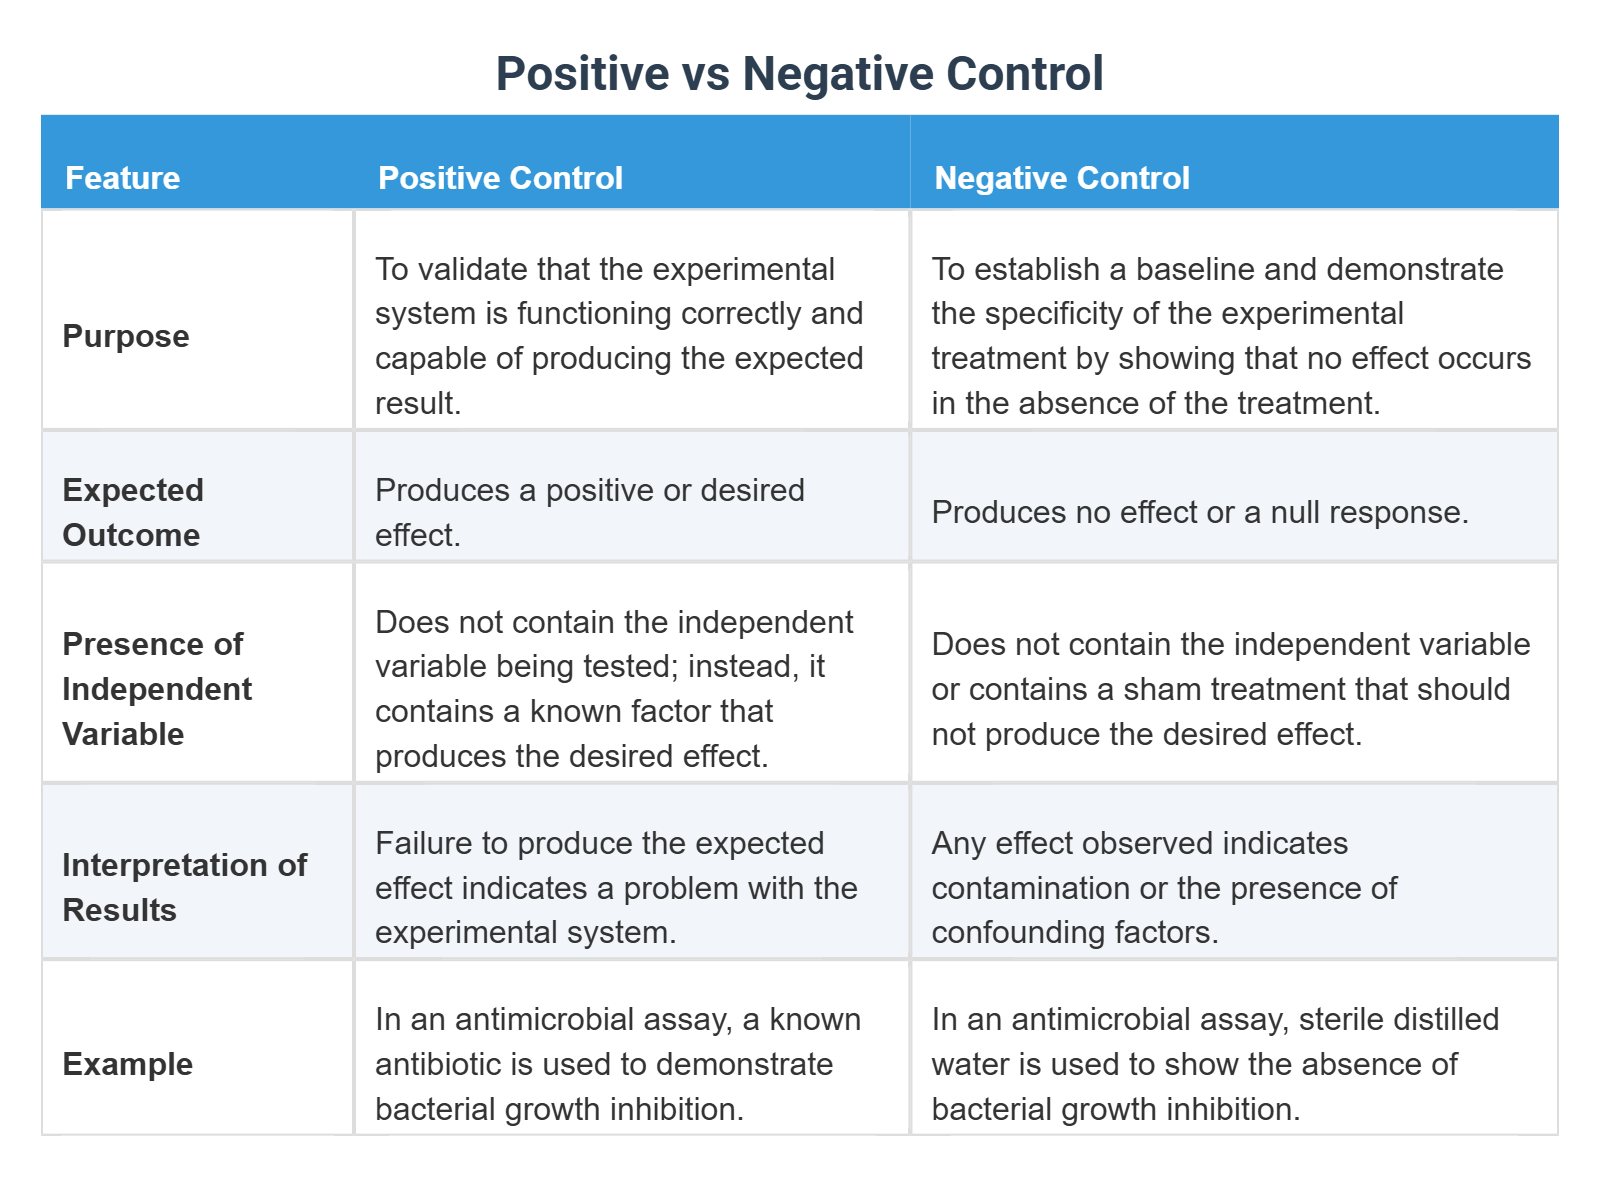
Positive and negative controls are the foundation of any reliable experiment, but most people treat them as afterthoughts. They run assays for weeks, get data that looks fine, then realize they have no idea if it actually means anything because they forgot to validate the control framework. A positive control confirms your experiment can detect what you expect it to detect. It proves the system is working. A negative control confirms it cannot detect something when nothing should be there. It proves you are not getting false signals. Both serve different purposes, and they are not interchangeable. Let me give you the straight version. When I was running qPCR assays in a lab, I once designed a whole validation study with only a negative control. Big mistake. The amplification curves looked clean, the melt curves were sharp, and the Ct values were consistent. Everything appeared normal. Then I realized the positive control sample — which I had skipped to save time — would have shown that my primers were degrading. The enzyme was nearly inactive. My negative control worked perfectly because there was genuinely nothing to amplify, but I had no way of knowing the reaction itself was failing. That run took three days to redo.
The workaround I use now is non-negotiable: every plate or batch gets both controls running simultaneously. If your plate reader, PCR machine, or whatever platform you are using allows it, include the controls in triplicate. Not once. Triplicate. You want to catch edge cases where a single well behaved oddly due to pipetting error or air bubble. I have seen it happen enough times that skipping triplicate controls feels like gambling with data I will have to explain later.
Setting Up Controls That Actually Tell You Something
Most people pick the wrong controls without realizing it. Here is what matters. For a positive control, use the exact sample type you expect to see a signal from under ideal conditions. If you are testing a drug assay, use a known active compound at a concentration in the middle of your dynamic range, not at the ceiling. Ceiling responses saturate the detector and give you a false sense of confidence. A mid-range positive control stresses the system more realistically and reveals linearity problems you would otherwise miss. For a negative control, use the matrix without the analyte. If you are working in cell culture media, use media alone, not just water or buffer. Water has very different physical and chemical properties compared to actual biological matrices, and components in the media can interfere with detection in ways that a water-based negative control will never show you. I ran into this specifically with ELISA workflows where the plate-blocking step behaved differently in buffer versus in serum-containing media. The buffer negative control looked pristine, but the serum-based negative control showed background drift that would have corrupted half my samples. Switching to matrix-matched negatives cut my false-positive rate from roughly eight percent down to under two.
Get the Full Details

Here is a detail beginners consistently overlook: your negative control should contain every reagent except the thing you are testing for. That means the same volume of DMSO, the same incubation times, the same buffer conditions. If your positive control requires a solvent vehicle and your negative does not, the two are no longer comparable. The vehicle itself might suppress or enhance signal. Match everything except the target analyte.
When Controls Fail and What to Do About It
Controls fail sometimes, and the failure mode tells you something important. A negative control giving a positive signal is worse than a positive control failing outright, and here is why. A dead positive control at least warns you the assay is broken. A contaminated or leaky negative control gives you clean-looking data that is completely unreliable. You might spend weeks publishing results built on baseline noise. If your positive control consistently underperforms, check these in order: reagent expiry dates, pipette calibration, thermal cycler or incubator temperature uniformity, and primer or antibody degradation. I recently had a situation where the positive control worked fine in a fresh plate but dropped significantly in older plates stored at room temperature. The antibodies on the plate were stabilizing poorly after day seven. Switching to freshly coated plates resolved it, but I lost a week of data to the problem before catching it. If your negative control shows signal, you have contamination, autofluorescence, nonspecific binding, or cross-reactivity. Run a no-template control if you are doing PCR. Run a secondary-only control if you are doing immunofluorescence. Isolate the source before you proceed. Do not discard anomalous negatives and move on. That is how you lose integrity.
Structural Considerations
Position your controls strategically within the experimental layout. Edge effects in microplates are a real problem, especially with evaporation. Place controls in center wells where temperature and humidity are most stable, not on the perimeter unless you have filled those outer wells with sterile water to buffer evaporation. This single adjustment changed reproducibility for me almost immediately. Include controls in every experimental batch, not just the first and last. Batch-to-batch variation in reagents, especially antibodies and enzymatic reagents, is significant enough that a control from Monday does not validate a plate run on Thursday. Run your controls alongside every set of samples you process.
Limitations You Should Accept
Controls do not fix everything. A well-designed control framework will tell you whether your assay is working, but it will not correct for biological variability between samples, operator technique differences, or instrument drift over long runs. Controls are a diagnostic tool, not a guarantee of validity. If your biology is noisy, controls will confirm the noise is there, and that is valuable information on its own. In some cases, positive controls are impractical or unethical to include. Preclinical work with certain compound classes, exploratory omics studies where no reference standard exists, or field studies with variable environmental conditions may make a traditional positive control unfeasible. In those situations, you can use internal reference genes, spike-in standards, or replicate measurements as partial substitutes. They are not as clean as a proper positive control, but they give you a fraction of the confidence you would otherwise lack. Better than nothing, and significantly better than running blind. The entire conversation around Positive Control Vs Negative Control usually devolves into definitions, but the real question is whether you have designed your controls to answer the specific failure modes your experiment is most likely to encounter. Most experiments fail silently, not loudly. The controls that matter are the ones you set up before you know the outcome, not the ones you add when the data looks suspicious.