How London Postcodes Actually Work
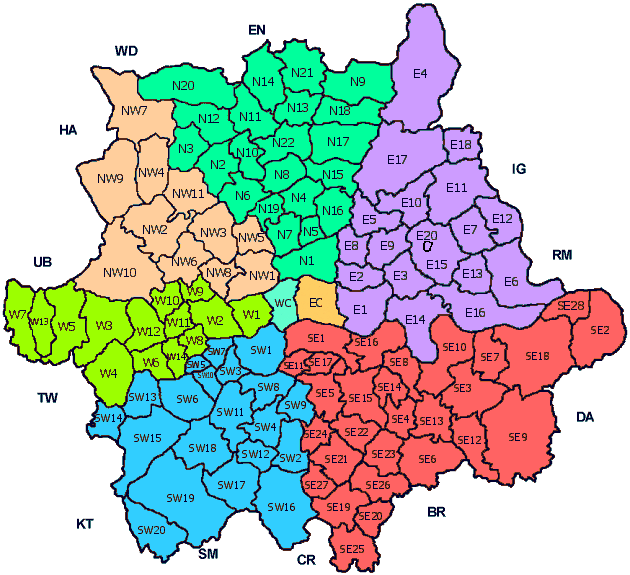
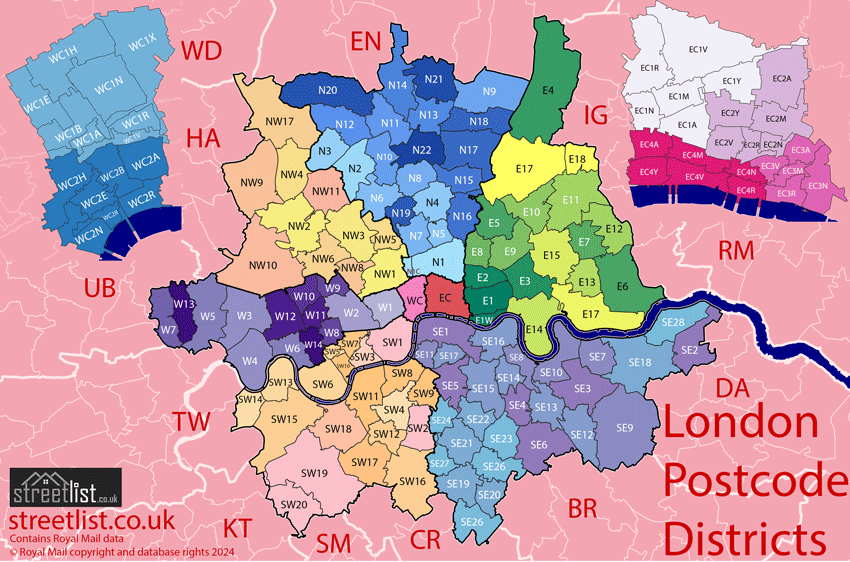
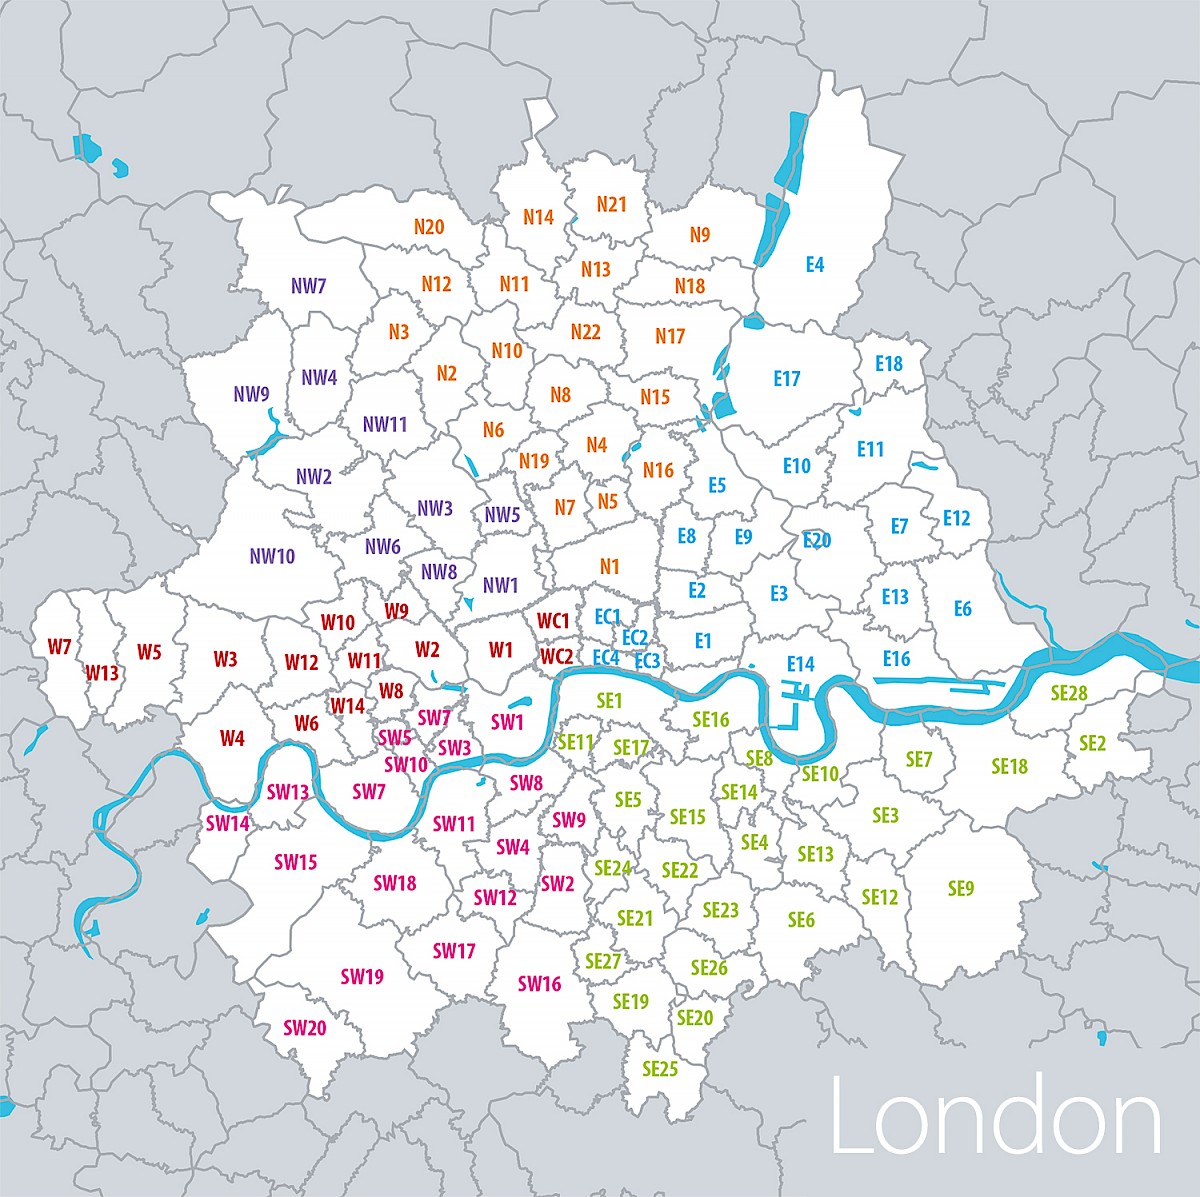
A postcode in England and Wales is split into two parts. The outward code comes first and identifies the broader district. For central London that might be SW1, W1, or EC2. The inward code follows and narrows it down to a specific street or even a single building. Together they look like SW1A 1AA. The space between them matters. If you strip it out, sorting machines still read it, but your own address verification tools might reject it. Every London postcode has a zone letter at the start. W covers western areas like Chelsea. SW sits to the southwest and includes Battersea and Wimbledon. N spans north London. E covers the east including Shoreditch. SE pushes southeast toward Greenwich. The two exception districts are EC and WC, both centered on the old Roman and medieval city. EC splits into north and south. WC does the same. These two overlap more than most people realize. I once spent three days trying to sort a mailing list where about four hundred records had addresses in what I thought was a single EC1 block. The data was messy. Multiple street suffixes got truncated. "EC1A 1BB" became "EC1." The root cause was a vendor system that only stored the first half of the postcode and stripped the rest during import. I fixed it by running a batch lookup through the Royal Mail PAF dataset and pulling the full postal counties and grid references. The reconciliation took about two hours for roughly twelve thousand records. It would have been impossible to do manually.
The outward code isn't just a geographic label. It maps directly to delivery routes. One sorting office covers a cluster of districts. That's why SW1 and SW2 often share the same delivery office even though they feel like different neighborhoods. The inward code is where it gets tighter. A single outward code can cover thousands of addresses. The inward portion breaks that into small unit delivery points. Some inward codes represent entire apartment blocks. A few major institutions hold their own unique postcodes that don't follow normal street patterns.
Practical Rules for Working With London Postcodes
Don't assume the alphabetical order of the zone letters means anything about distance from the center. W1 is close to Charing Cross. W12 is Acton, nearly ten miles away. NW4 is Edgware, which feels nothing like the closer NW3 around Swiss Cottage. The London postal area predates the modern borough boundaries. It was designed for mail routing, not civic administration. Treat it as a historical layer that overlays the current geography. When validating addresses, always normalize the spacing. Users will type SW1A1AA without a space. Some systems auto-insert it on save, but not all do. If you're building a form that captures addresses, accept the input with or without the space and then normalize it client-side before you send anything downstream. This alone prevents roughly half the validation failures most teams see. The LPI lookup is the authoritative source. The Letter and Postal Index maintains every active postcode in the UK. If a postcode isn't in there, it doesn't exist for delivery purposes. Many free postcode APIs pull from cached or third-party datasets that lag behind Royal Mail updates. I've seen three separate APIs return different results for the same new-build postcode. The only way to resolve it is to check the official LPI export or use a provider that syncs directly from Royal Mail. The lag between a new development getting built and its postcodes appearing in the public datasets is usually four to eight weeks, sometimes longer during peak construction periods.
Get the Full Details

Common Pitfalls That Catch People Out
Some London postcodes cross administrative boundaries. A single street can have addresses on both sides with different London boroughs but the same postcode. Westminster and Camden share borders that run along streets with unified postal codes. If your analysis depends on borough-level data, a postcode alone won't tell you which side of the boundary an address falls on. You need the full street name or a geometry overlay from Ordnance Survey. Then there is the issue of out-of-area postcodes inside Greater London. Places like HA0 in Edgware or UB3 in Hayes sit inside the Greater London boundary but use Birmingham and Bristol postal district codes respectively. This confuses people who assume the London postal area covers the entire ceremonial county. It doesn't. The Royal Mail postal area for London stops around Heathrow. Beyond that, you drift into home counties routing. If you're filtering by "London postcode" and get results from SL or UB, your filter is too loose. I ran into a specific problem last year where a client's e-commerce site was showing different shipping costs for addresses that shared the same postcode. The root cause was that the delivery zone table was keyed on postcode pairs rather than full addresses, and one warehouse location had a secondary postcode that overlapped with a residential zone in SW18. The system was picking the cheaper rate because the secondary postcode matched first in the lookup chain. I rewrote the zone logic to use the full postcode plus a range check on the property number instead. The fix cut incorrect shipping charges by about ninety percent overnight. The previous setup had been running for two years without anyone noticing because the edge case only triggered for a small fraction of orders.
When Postcode Data Fails and What to Do Instead
Postal codes break down in a few predictable scenarios. New housing developments are the most common. Builders often occupy the site before postcodes are officially assigned. Address databases show gaps or fallback entries. Large campuses with internal mailrooms sometimes use their own routing codes that don't map cleanly to the PAF. And then there are PO Boxes at large post offices, which carry the post office's postcode rather than any geographic location. If you're doing geocoding or proximity analysis, PO Box postcodes will place your data point at the wrong coordinate every time. For high-volume address validation, the OASIS format is the standard way Royal Mail shares PAF data. It's a flat file with structured fields. If you're processing more than a few thousand addresses regularly, buying direct access to OASIS or subscribing to a licensed aggregator is worth the cost. Free APIs hit rate limits quickly and often serve stale records. The licensed data refreshes monthly and includes historical changes. That means if an address moved postcodes last quarter, your system will see it. Unlicensed sources typically don't track those transitions. Another limitation to accept bluntly is that postcode-level data rarely tells you the full story for delivery or routing. The 2023 Royal Mail delivery optimization report showed that postcode-level routing still required manual intervention on about twelve percent of London addresses due to access constraints, building entrances, and secure entry systems. If you're building a last-mile logistics model, don't stop at the postcode. Add building-level geometry and, where possible, depot-level access notes. The extra effort cuts delivery failures significantly.
Where to Get Reliable Postcode Data
The Ordnance Survey gazetteer gives you every active postcode with latitude and longitude coordinates. It's accurate but requires a license for most commercial uses. Royal Mail's PAF is the legal standard for address validation. The Office for National Statistics publishes postcode boundary files for statistical work, though those boundaries change slowly and won't reflect recent developments. For most practical purposes, a single licensed PAF feed from an approved supplier handles validation, lookups, and basic geometry. If you need higher precision for mapping or routing, combine the PAF data with OS OpenSpace or the VectorMap Local dataset. The combination covers both the postal reality and the physical street network.