Power Sets Are Simple Until You Try to Use Them
I ran into a real problem last year when a client asked me to generate all possible groupings of features in their config system. Thirty-seven feature flags. They wanted every valid combination to test against. The mathematical answer is a power set, and the mathematical answer is also a memory impossibility. 2^37 is over 137 billion subsets. I had to find a different approach, and that experience shaped how I think about this problem now. Let me back up and explain what is actually going on here before I get into the implementation stuff, because a lot of people try to skip the theory and then hit issues they don't understand when they scale up.
Power Set Of A Set Explained
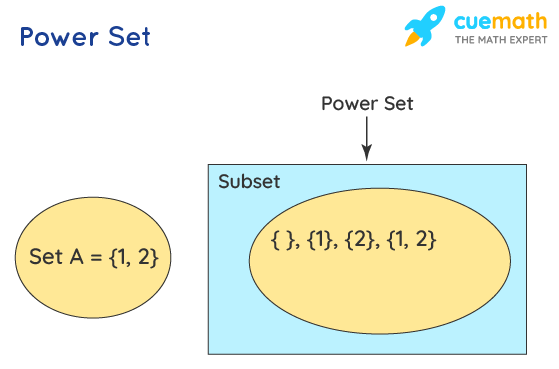
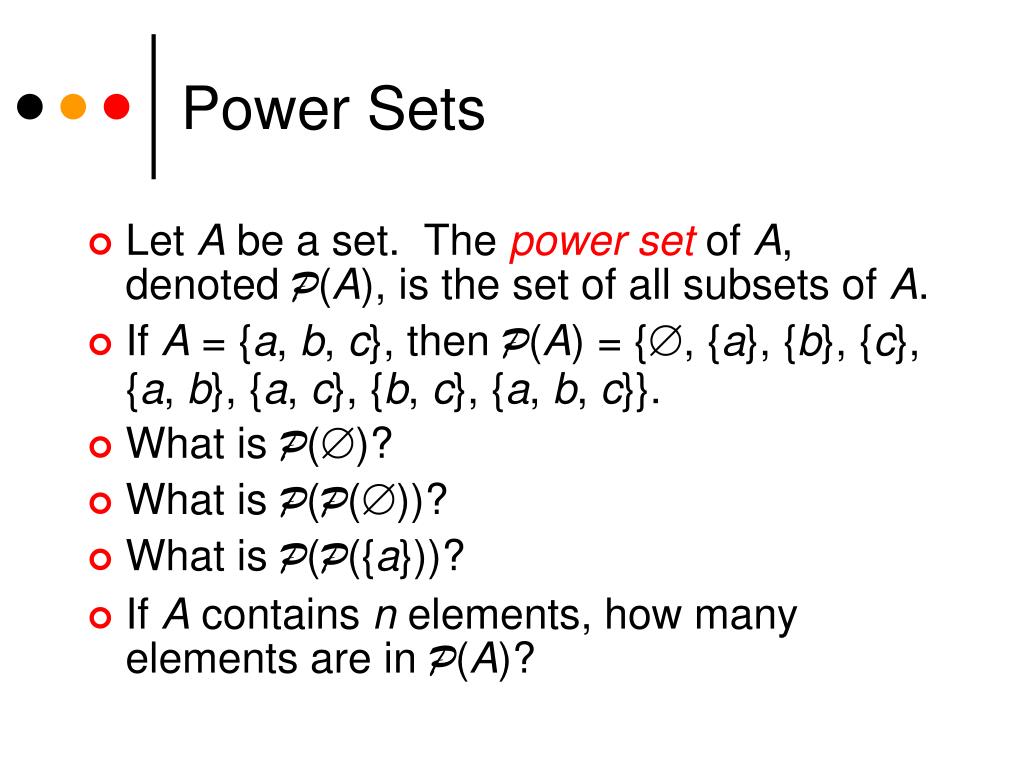
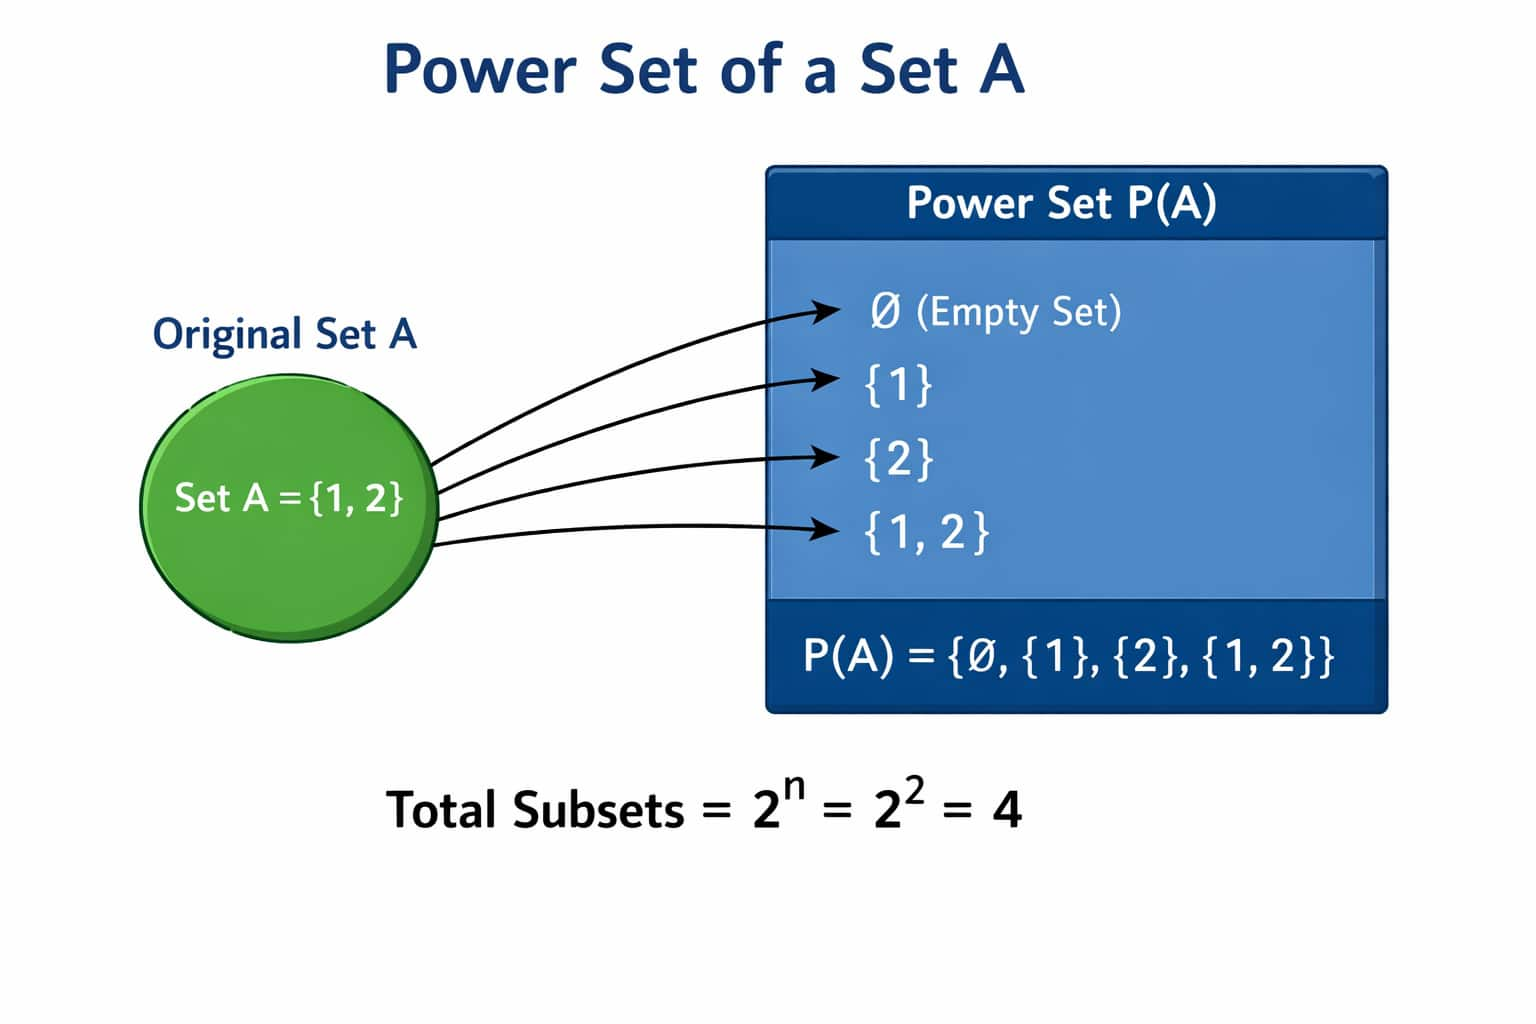
A power set is simply the collection of every possible subset of a given set, including the empty set and the set itself. That's it. If your set is {a, b, c}, the power set is {{}, {a}, {b}, {c}, {a,b}, {a,c}, {b,c}, {a,b,c}}. Eight subsets for three elements. The pattern is always 2^n, where n is the number of elements in your original set. Each element either is or isn't in a given subset, so you have two choices per element, multiplied together. The notation is P(S) or 2^S. The 2^S notation comes directly from that binary choice per element. It's not notation for exponentiation in some mysterious way. It's literally counting all the functions from your set to a two-element set, which corresponds one-to-one with all the subsets. Here's a practical example I use when I'm explaining this to junior team members. Say you have a database table and you want to audit every possible combination of column restrictions. With five columns, that's 32 query patterns. Manageable. With ten columns, that's 1024 patterns. Still okay if you're smart about it. With fifteen columns, that's 32,768. The numbers grow fast enough that most people stop at twelve or thirteen before they realize the problem has changed nature completely.
How to Generate a Power Set in Practice
There are two standard approaches, recursive and iterative, and I'll walk through both. The recursive version is usually the first one people write because it maps directly to the definition. The iterative version using bit manipulation is what I actually use in production code most of the time. Here's the recursive approach in Python: def power_set(s):
if len(s) == 0:
return [[]]
first = s[0]
rest = s[1:]
subsets_without = power_set(rest)
subsets_with = [[first] + sub for sub in subsets_without]
return subsets_without + subsets_with
Get the Full Details
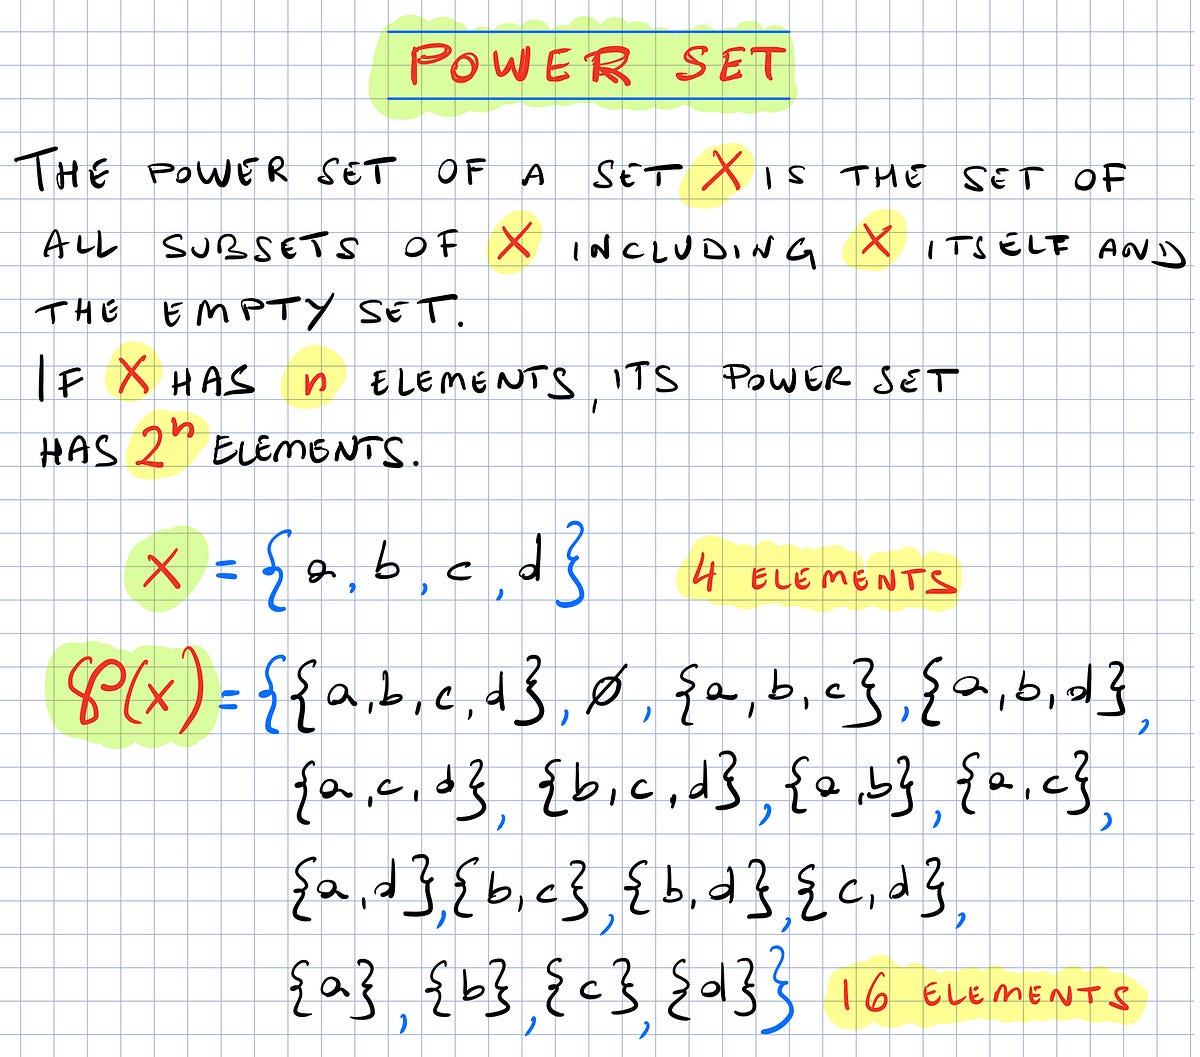
This works correctly. For a set of four elements it produces 16 subsets. For a set of twenty elements it produces over a million. For a set of thirty elements it produces over a billion, at which point you are holding roughly fifty gigabytes of list objects in memory depending on what those elements are. That's when the recursive version becomes a problem even before you count the recursion stack depth, which hits Python's default limit around 1000 frames anyway. The iterative bitmask approach avoids the recursion limit and is generally faster: def power_set_iterative(s):
n = len(s)
result = []
for i in range(2 n):
subset = []
for j in range(n):
if (i >> j) & 1:
subset.append(s[j])
result.append(subset)
return result
Each number from 0 to 2^n - 1 represents one subset. The binary representation tells you which elements to include. Number 5 in binary is 101, so you include the first and third elements. This is cache-friendly and doesn't depend on recursion depth. The inner loop is tight enough that C-style implementations can process millions of subsets per second on a modern CPU, but you are still bound by the 2^n ceiling no matter how optimized the inner loop is.
When the Naive Approach Breaks and What to Do Instead
Back to my original problem with those thirty-seven feature flags. I couldn't generate all 137 billion subsets. What I actually needed was every minimal subset that caused a conflict, not every possible subset. This is a fundamentally different question, and the answer requires constraint solving rather than brute force enumeration. I ended up using a SAT solver to find the minimal unsatisfiable cores instead. The runtime went from "would never finish" to about twelve minutes on a single core. For cases where you genuinely need all subsets but the set is moderate-sized, there are optimizations worth knowing about. If you're working with bit-vectors rather than arbitrary objects, representing each subset as an integer mask lets you skip the inner loop entirely. In C or C++, you can generate all 2^32 subsets in roughly forty seconds on a modern processor, compared to several minutes with the naive Python approach. The difference isn't the algorithm. It's the overhead per subset. Another thing people miss is that you often don't need the full power set. If you only care about subsets of a certain size, that's a combinatorics problem, not a power set problem. C(n, k) is much smaller than 2^n for any reasonable k. Generating combinations instead of all subsets is the workaround I reach for most often. itertools.combinations in Python will give you all subsets of size k in O(C(n,k)) time and space, which is exactly what you want when you're testing interaction effects between features rather than every possible configuration.
Common Pitfalls with Power Set Of A Set
The biggest issue is people underestimating the size of the output. You think you have a small set and then suddenly you're allocating hundreds of gigabytes and wondering what went wrong. Always estimate 2^n before you commit to generating the full power set. If n is above 25, assume you need a different strategy unless you have substantial memory and you're willing to wait. A second pitfall is duplicate elements. Sets by definition don't have duplicates, but if you're reading data from a CSV or a database query result and feeding it into a power set generator without deduplicating first, your "power set" will contain duplicates and your subset count will be wrong. The mathematical definition assumes a proper set, so validate your input before you start generating. A third issue I see regularly is treating the power set as a flat list when it should be treated as a lattice or Hasse diagram. The structure of subset inclusion has useful properties if you need them for things like monotone Boolean function evaluation or closure computation, and flattening it into a list loses that structure. Use a proper data structure if you're going to be traversing the subset ordering.
Implementation Notes for Different Languages
In Rust, you'd use an iterator-based approach that yields subsets lazily. This is the cleanest way to handle large power sets because you never materialize more than one subset at a time. The standard library doesn't have a built-in power set iterator, but crates like itertools provide this. A lazy iterator means you can pipe the output through filters and only pay the cost for the subsets that survive filtering. In JavaScript, you can write a similar recursive generator function, but the language's handling of arrays and objects means memory usage per subset is relatively high compared to a compiled language. If you're doing this in a browser context, you'll want to be especially careful about memory pressure. Web workers and chunked processing help, but the fundamental 2^n explosion is still there regardless of how you parallelize it. In Go, the idiomatic approach is a byte slice for small sets and a custom type with lazy evaluation for anything larger. Go's garbage collector handles the allocation pattern reasonably well for moderate sizes, but again, the algorithmic bound is the same. If you're processing more than about 2^24 subsets, reconsider whether you actually need all of them.
The Honest Limitations
There is no way around the exponential growth. Any method that claims otherwise is either approximate, constrained in some way you haven't noticed, or lying. The power set of a set with n elements always has exactly 2^n elements. That's a theorem, not a suggestion. If someone tells you they computed the power set of a fifty-element set and gave you all the results, they didn't. They gave you something else. For sets larger than about twenty-five elements, the only practical approaches involve constraints, sampling, or reformulating the problem entirely. Constraint-based approaches like the SAT solver I mentioned can find the subsets that matter without enumerating all of them. Monte Carlo sampling over the subset space can give you estimates of aggregate properties. Reformulating the problem to avoid enumeration is usually the best outcome but requires understanding what you're actually trying to compute rather than just following the textbook definition blindly. If you need to work with power sets regularly and you're doing it in Python, I'd recommend looking at the more-itertools library, which has a powerset function that yields subsets in order of increasing size. It's not faster in terms of asymptotic complexity, but the implementation is optimized and the ordering is useful when you're processing subsets incrementally. Here's the usage: from more_itertools import powerset. Then you iterate over powerset(your_set) and get subsets starting from the empty set through the full set, one at a time.

The takeaway is that power sets are straightforward to understand and implement, trivially hard to use at scale, and often unnecessary if you frame the actual problem more carefully. Most of the time when someone says they need a power set, they need something narrower and more tractable than the full enumeration. Figuring out what that narrower thing is is usually where the real work happens.