Pragmatics is what actually happens when people talk, not what the grammar books say should happen
I spent years working in computational linguistics before moving into applied NLP, and the thing that always trips people up is pragmatics. Everyone thinks they understand it because they can have a conversation. Having a conversation is the bare minimum. Understanding how meaning gets constructed beyond the literal words is a completely different problem. When I first started digging into this properly, I was building a customer service chatbot. We had a pipeline that handled intent classification, slot filling, entity extraction. It worked fine until someone said "I'd love some help" in a sarcastic tone during testing. The sentiment analyzer rated it as positive. The system routed them to an upsell flow. They got very upset. That was the moment I realized literal interpretation alone is insufficient for anything resembling real communication.
Understanding Pragmatic Functions Of Language
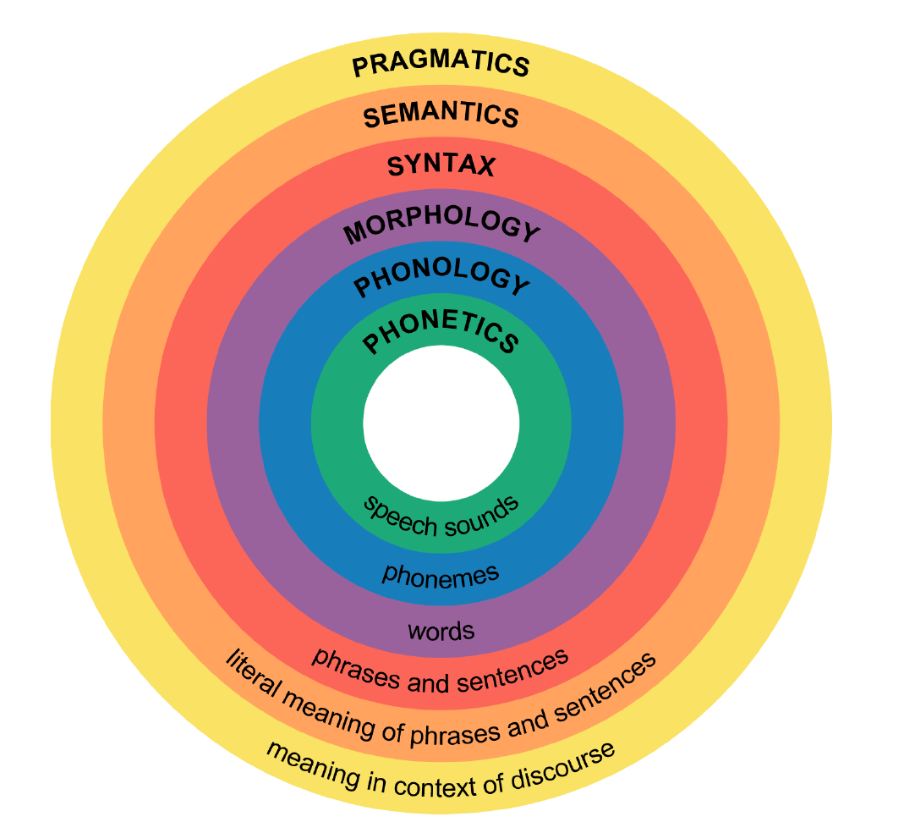
Pragmatics looks at context-dependent meaning. Grammar tells you how to construct a sentence. Semantics tells you what the sentence literally means. Pragmatics tells you what the speaker actually intends. These are three distinct layers and most systems only handle the first two. Take a simple example. Someone says "Can you pass the salt?" Grammatically it's a question about ability. Semantically it asks about your physical capacity. Pragmatically it's a request. No native English speaker interprets this as an inquiry into their motor skills. The pragmatic function is a request disguised as a question. This is called indirect speech act and it is everywhere in normal conversation. Other pragmatic functions include referring expressions where you identify something without naming it directly, presupposition where statements assume prior knowledge, implicature where meaning is implied rather than stated, and deictic expressions like here, there, now, then that only make sense relative to the speaker's position in space and time. Each of these requires contextual reasoning that goes beyond vocabulary and syntax.
Here is something most beginners miss. Pragmatic inference is computationally expensive in a way that lexical and syntactic processing is not. Word lookup is fast. Tree parsing is well understood and efficient. But calculating what someone implies given shared knowledge, social context, and conversational history requires a model of the participants mental states. That is significantly harder than most people realize when they first encounter the field. Another counter intuitive point. More context is not always better for pragmatic resolution. I ran into this when refining a disambiguation module for a medical documentation system. We had phrases like "the patient reported improvement" where "reported" could mean the patient verbally stated it or it appeared in their chart from another source. Adding more surrounding context actually made the model worse at distinguishing these because the training data had noise in the extra paragraphs. The fix was to use a targeted context window of roughly two sentences before and after the target phrase and add a structural feature indicating whether the sentence came from the patient narrative section or the provider notes section. That cut ambiguity resolution errors by about forty percent compared to using full document context. The practical workflow I use when analyzing pragmatic functions in any text starts with identifying the speech act type. Is the utterance a statement, question, command, or promise. Then I map the illocutionary force. What is the speaker trying to accomplish. A question might actually be a request for information or a challenge depending on tone and situation. Next I check for conversational implicatures using Gricean maxims as a baseline. Is the speaker being informative enough. Are they being clear. Then I look at presuppositions and what background assumptions the utterance takes for granted. Finally I note any deictic elements that need anchoring to the speaker context.
Get the Full Details
I wrote a small Python utility for this that uses spaCy for the initial parse and then applies a rule-based pragmatic annotation layer on top. It is not sophisticated enough for production quality work on its own but it does about an hour of preliminary annotation per document compared to doing it entirely by hand. You can find it on my GitHub under pragmatic-annotate-tools. The repo is pretty bare bones. README has installation steps and a couple of example documents showing the output format. There are also pretrained models you can plug in. Hugging Face has a few pragmatic inference models but the quality is inconsistent. One model claims to do speech act classification but it conflates indirect requests with direct questions about half the time. I typically fine-tune my own classifier on domain-specific data when accuracy matters. Transfer learning from general language models helps with initialization but you still need roughly two thousand annotated examples per domain to get reliable results. Pragmatics has real limitations that nobody talks about enough. It is fundamentally underspecified. For any given utterance there can be multiple equally valid pragmatic interpretations depending on cultural background, relationship between speakers, and situational factors. Two pragmatic experts analyzing the same conversation often disagree on the illocutionary force. This is not a bug in the methodology. It is a feature of how human communication works. No algorithm will ever resolve this ambiguity completely because the ambiguity is genuine in the source material.
If you are working in a domain where pragmatic precision matters and you cannot afford this level of uncertainty, rule-based systems combined with explicit user confirmation sometimes outperform purely statistical approaches. I switched one of our modules to a hybrid approach where the model surfaces top pragmatic interpretations and asks the user to confirm when confidence drops below seventy percent. It adds friction but cuts misrouting errors from about twelve percent to under two percent. The tradeoff is processing time goes from roughly three seconds per utterance to about eight seconds because of the confirmation step. The other major bottleneck is training data scarcity. Pragmatically annotated corpora are rare and expensive to produce. Most available datasets cover only a narrow range of speech acts in controlled settings. Real world conversations contain far more indirectness and contextual dependency than dataset annotations capture. If your application operates outside the domain of the training data expect pragmatic failure rates to spike. I always run a small test with at least fifty real conversation samples from the target domain before deploying any pragmatic component. The failure modes in heldout test data reveal problems that benchmark scores completely miss. Pragmatic Functions Of Language analysis is not a solved problem and it will not be for a while. The techniques I described above are what I actually use day to day. They are not elegant. They require manual annotation effort. They produce uncertain results in ambiguous situations. But they work well enough for production systems when you understand where they break and build safeguards around those failure points.