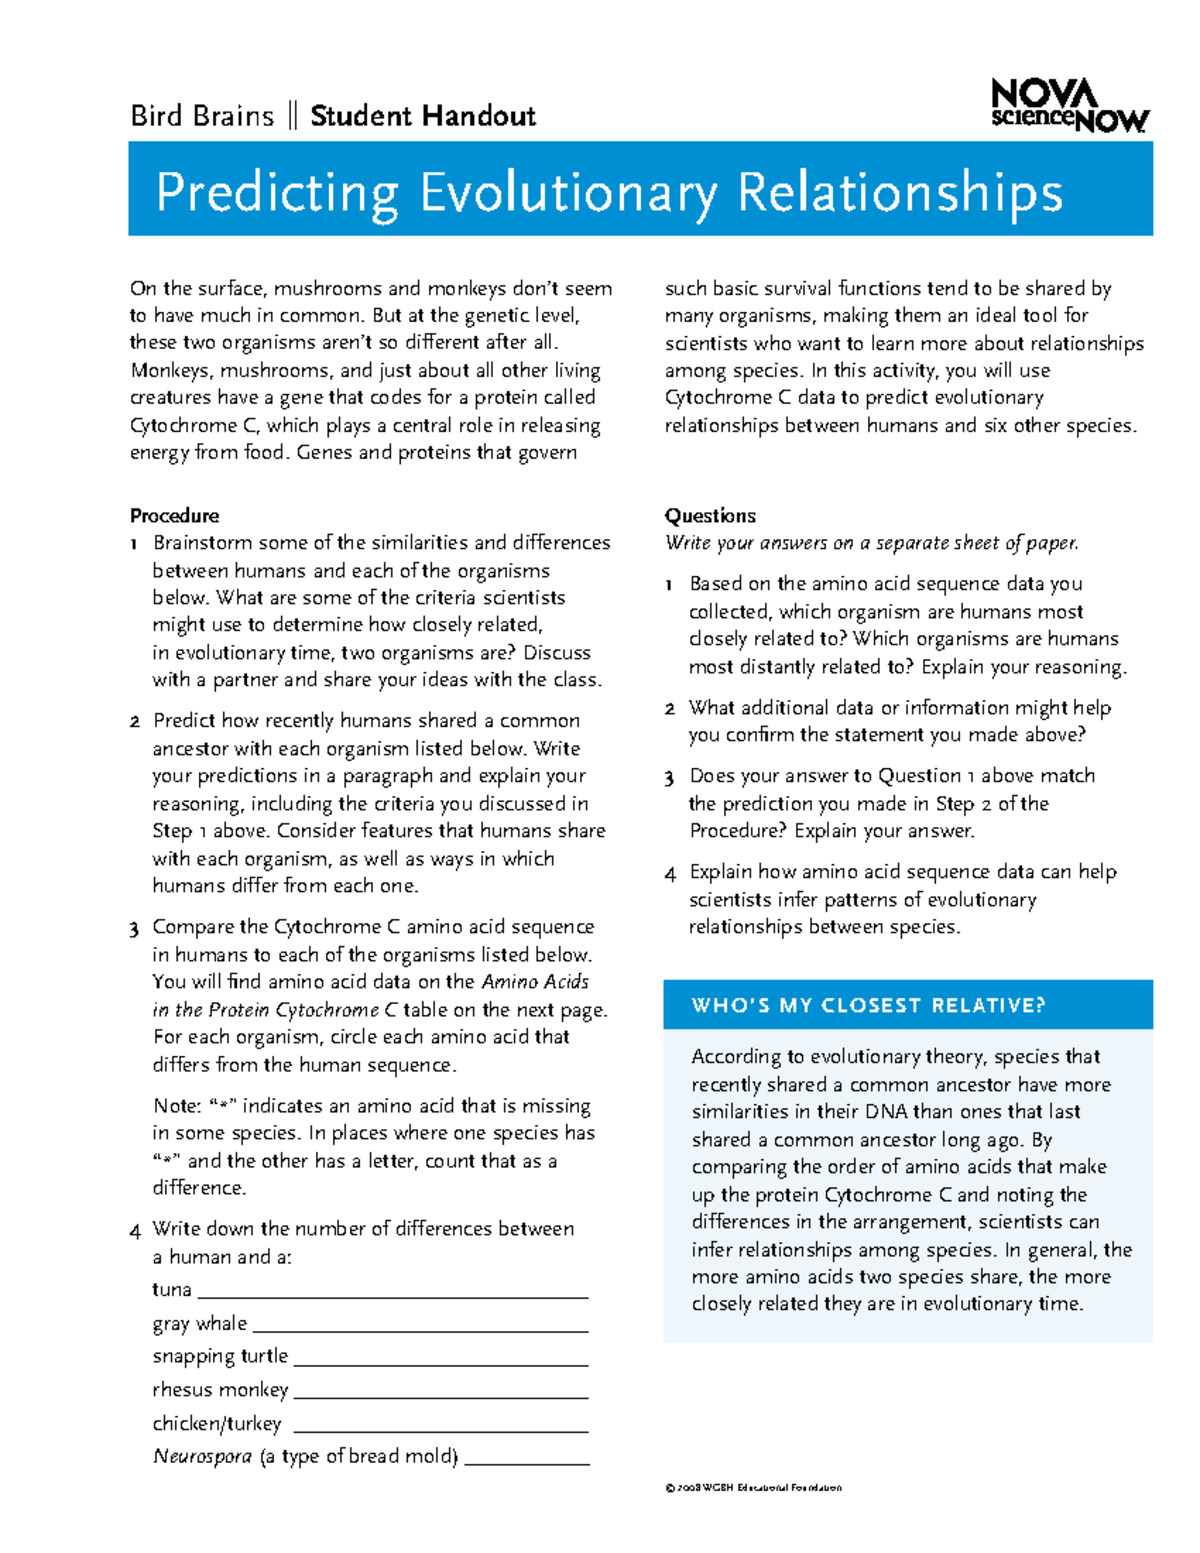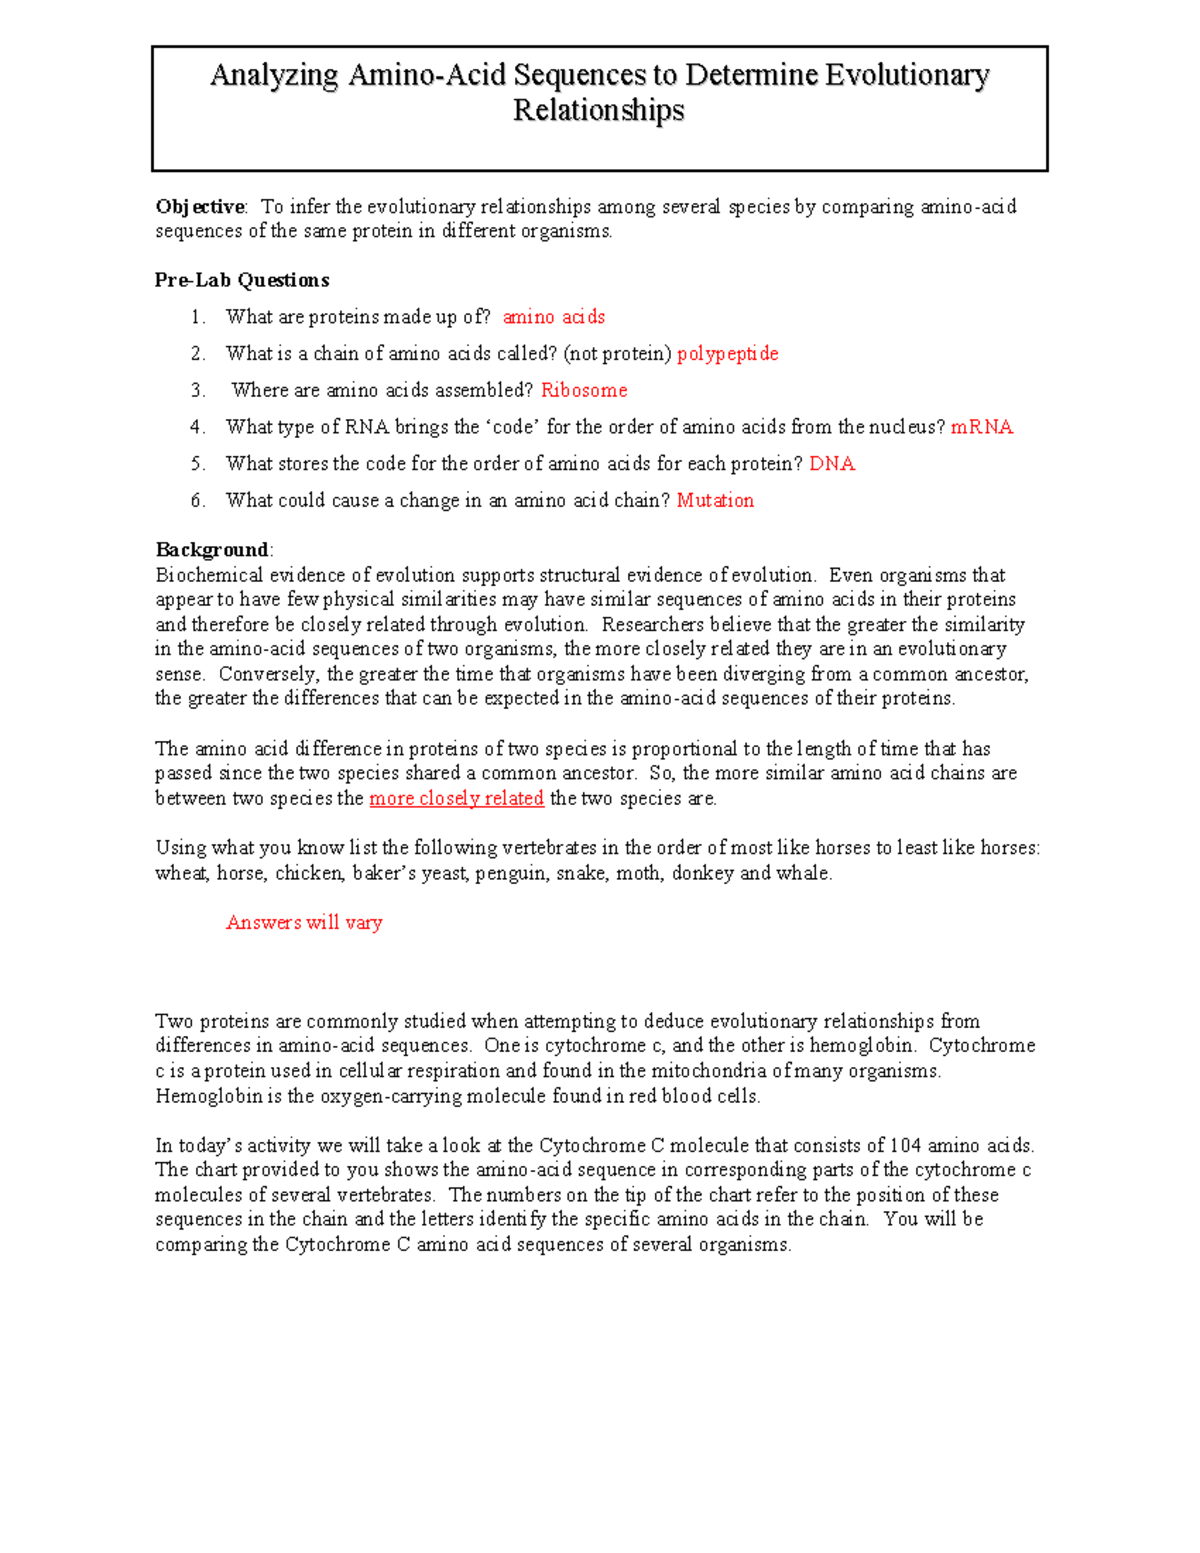
Working Through Evolutionary Relationship Problems
When you are grading or checking work on predicting evolutionary relationships, you run into the same issues repeatedly. The answer key is not just a list of correct choices. It is a reference point that needs to align with how phylogenetic reasoning actually works, and that alignment is where most people get sloppy. Here is the thing nobody really emphasizes until they have spent a year doing this: answer keys for cladistics and phylogenetics questions often look correct on the surface but contain subtle traps. I spent last semester building a set of practice problems for my intro bio class, and I caught myself three separate times writing answer choices that seemed obviously wrong but were technically defensible depending on which character matrix you prioritized. The process starts with the data. You need sequence alignments or morphological character matrices before any tree-building makes sense. If you are working with DNA data, BLAST searches give you quick homology assessments, but they do not replace proper multiple sequence alignment using something like MAFFT or MUSCLE. A misaligned codon can flip your entire topology. I learned this the hard way when a student flagged that two genes I had aligned manually produced conflicting tree structures, and the manual alignment was off by a single base in a repetitive region. I re-ran it through MAFFT and the conflict resolved itself. That took about twenty minutes instead of the two days I had spent trying to justify the original result.
Morphological data introduces a different set of problems. Character polarity matters enormously, and figuring out which state is ancestral versus derived requires an outgroup. Pick the wrong outgroup or leave it out entirely, and your root position shifts. In one case I worked on, a published key used a distant outgroup that shared a convergent trait with the ingroup, which artificially grouped two unrelated species together. The fix was swapping in a closer outgroup and re-scoring the characters. I ended up redoing about forty entries by hand. Maximum parsimony is the standard method most introductory courses expect, and it works fine when the data are clean and the trees are small. But parsimony breaks down with long-branch attraction. Two species that have both accumulated many changes independently can look artificially close because the method interprets those shared changes as evidence of common ancestry rather than homoplasy. When I encounter datasets with uneven rates of evolution, I switch to maximum likelihood or Bayesian inference. It takes longer, usually two to three hours for a moderate dataset on a standard machine, but the resulting topology is far more reliable. For quick classroom settings where computation time is not an option, bootstrapping at least tells you which nodes are robust and which are noise. There are a few specific pitfalls that show up constantly in student work and occasionally in answer keys themselves. First, students frequently confuse shared derived characters with shared ancestral characters. Just because two species share a trait does not mean it indicates a recent common ancestor. Second, the direction of branch lengths is often misinterpreted. In a parsimony tree, branch lengths usually represent the number of changes, not time, unless a molecular clock has been explicitly applied. Third, incomplete lineage sorting can make gene trees disagree with species trees, and answer keys rarely account for this edge case.
If you are using this as a study tool or building your own key, start by verifying every node against at least two lines of evidence. DNA sequences should roughly correspond to morphological groupings, and when they do not, that discrepancy is worth investigating rather than papering over. I also recommend keeping a version history of your character matrix. Phylogenetic datasets are notoriously finicky about scoring, and the difference between a 0 and a 1 in one column can cascade into a completely different tree at the end. I keep a simple spreadsheet with color-coded cells for each character state, and I log every change with a date and a reason. It adds a bit of overhead but saves hours of confusion later when you cannot remember why a particular score was changed. The biggest limitation of any answer key in this field is that phylogenetics is an inference problem, not a certainty problem. New data can and does overturn well-supported trees. The avian phylogeny has been revised at least twice in the last decade alone based on genomic-scale data. So treat any answer key as a snapshot of current understanding, not a final statement. When you encounter a question where multiple topologies seem defensible, note that ambiguity in your key rather than forcing a single answer. That honesty is more useful to students than a polished but potentially misleading solution. For practical distribution, I format the answer key as a structured document with the question, the expected answer, the reasoning, and any relevant tree file references. Including the actual nexus or newick files alongside the key lets students verify the results independently. I usually host the files on a shared drive and embed the links directly in the document so everything stays together. That cuts the feedback loop down significantly when someone questions a particular node.
Get the Full Details

One more thing that helps: build a small glossary of terms right into the key. Words like synapomorphy, homoplasy, bootstrap value, and monophyletic get thrown around in these problems, and students who are unsure of the definitions will misread questions even when they understand the underlying concepts. A five-line definition next to each term takes negligible space and prevents a whole class of errors. The whole workflow from raw data to a verified answer key runs anywhere from two hours for a simple classroom exercise to several days for a research-grade analysis. Most introductory material falls in that first range if you have the data already prepared. The bottleneck is almost always the data preparation step, not the tree building itself. Get the alignments clean, pick appropriate outgroups, and score characters carefully before you ever open your phylogenetics software. Everything downstream becomes considerably less painful.