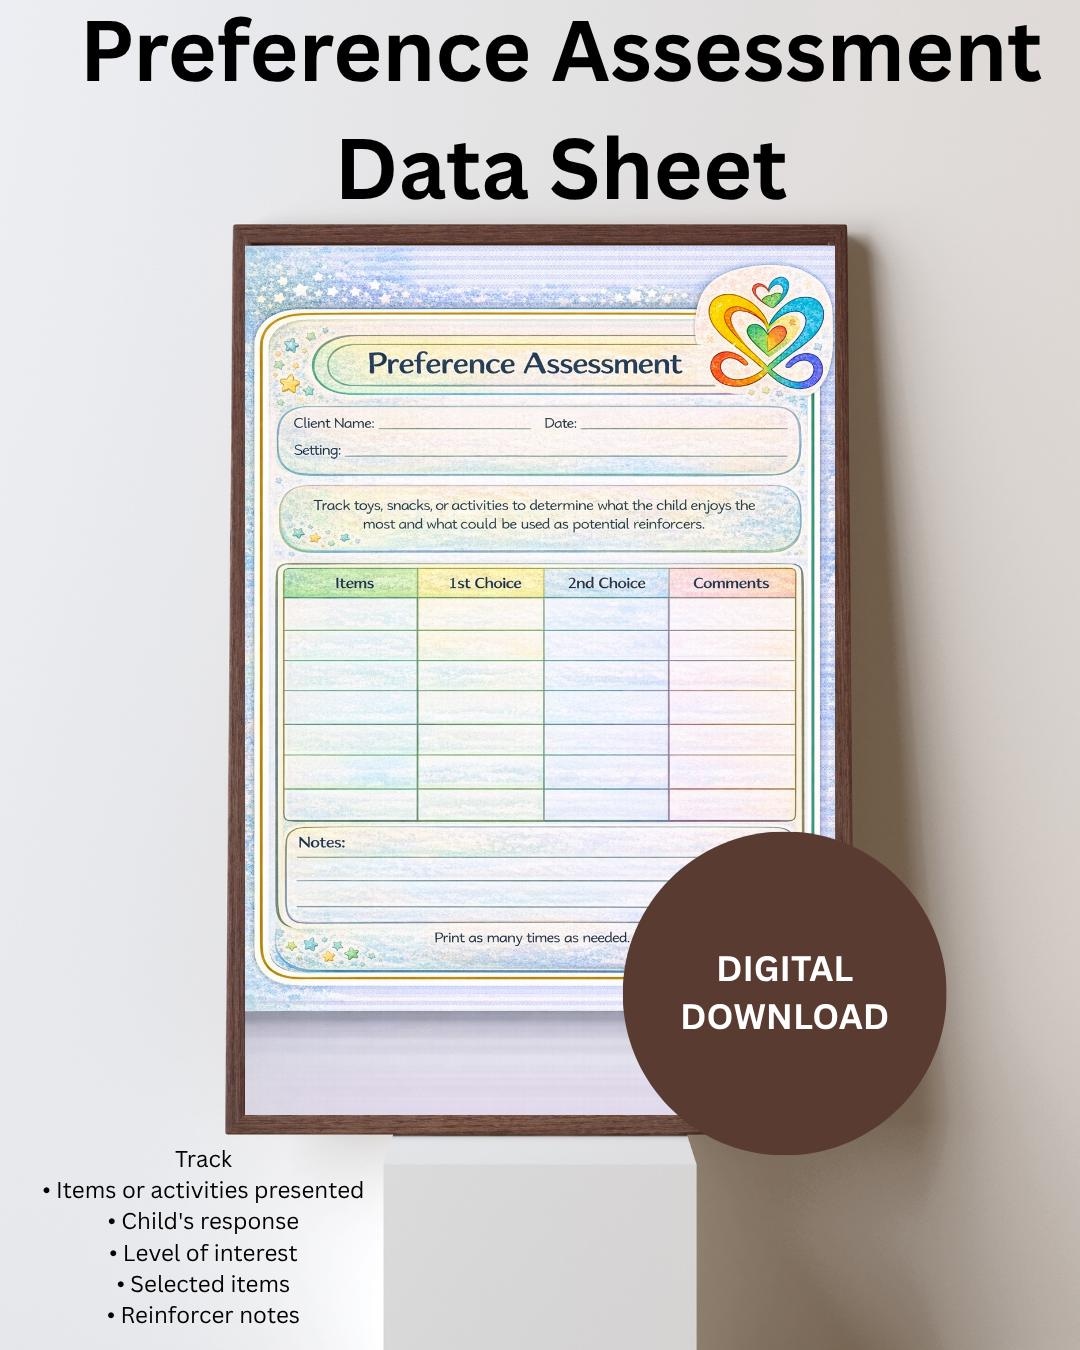
What actually happens when you run a preference assessment
I used to treat preference assessment data sheets like some kind of administrative chore. Fill in the boxes, record the choices, move on to writing the next goal. That changed when I realized most people were doing them wrong and then wondering why their behavior plans weren't working. A preference assessment is straightforward in theory but messy in practice. You present options, record what the person chooses, and use that data to figure out what actually motivates them. The data sheet is just the record-keeping tool for that process. The reason this matters is simple. If you pick reinforcers based on what sounds good or what you assume someone likes, you waste time and energy. A proper preference assessment cuts through that guesswork. It takes maybe twenty to thirty minutes to run a solid session, and the results stick around longer than you'd expect if you actually maintain the options that scored high.
Preference Assessment Data Sheet: what it looks like in practice
A basic data sheet tracks each trial of the assessment. You list every item available in a column, then record the choice made on each presentation round. Some people use checkmarks for selections and Xs for non-selections. Others use frequency counts or percentage calculations depending on the method they're using. The simplest version has the item names down the side, columns for each trial across the top, and a results summary at the bottom. There are four main methods and they each change how you set up the sheet.
Single-stimulus presentation
You show one item at a time. The person either accepts it or rejects it. This method is quick, takes about fifteen to twenty minutes, and works well for individuals who struggle with decision-making or have limited verbal skills. The downside is it measures approach behavior, not real preference. Someone might accept everything you put in front of them because that's what they've been taught to do. The data sheet here is dead simple: item name, accept or reject for each presentation. You present two items at once and record which one gets selected. This runs longer. Expect thirty to forty-five minutes depending on how many pairs you cycle through. It's more accurate than single-stimulus because it forces an actual choice between competing items. The data sheet gets a bit more involved. You need columns for each pair presented, a record of which position the items were in, and a way to track whether position bias crept in. Left-side choices versus right-side choices tells you something most people miss. This is the one I use most often. You lay out all the items, the person picks one, you remove it, then they pick again from what's left. You keep going until nothing is remaining. That's one full trial. You repeat the trial several times with the same items rearranged. The data sheet for this is where it gets interesting. You need to record the order of selection in each trial, calculate the positional advantage across trials, and compute a preference ranking based on how many times each item was chosen first. A typical session with ten items runs about twenty minutes. The result gives you a ranked list from most preferred to least preferred.
Get the Full Details

Same setup as MSWO but you put every item back after each selection. This method is useful when the person needs repeated access to high-preference items during the assessment itself, or when you're working with someone who has a history of losing reinforcing items and needs to see them remain available. The data sheet is nearly identical to MSWO except you're not tracking removal, just the sequence of picks per trial. I ran into a problem once that took me three weeks to figure out. I was doing a paired-choice assessment with a client who had intellectual disability and very strong left-side positioning bias. He chose the item on the left every single time regardless of what it was. My data sheet showed him consistently preferring things he genuinely didn't care about. The fix was switching to a counterbalanced design where I swapped positions every other trial and tracked position separately. The corrected data sheet clearly showed the bias and let me recalculate the actual preference scores. If you don't track which side the items are on, you're just making guesses dressed up as data.
How to build the data sheet yourself
You don't need fancy software for this. A spreadsheet works fine. Set up rows for each stimulus item. Create columns for each trial or presentation round. Add a summary section at the bottom that calculates selection frequency and ranking automatically if you know basic formulas. Here is what the core columns look like for MSWO: Column A lists the items. Columns B through F are Trial 1 through Trial 5. Each cell records the order the item was picked, or a dash if it wasn't selected in that trial. Column G calculates the average rank across all trials. The item with the lowest average rank is your most preferred. For paired-choice, the layout is different. Rows are individual trials. Each row has two columns for the left and right items, one column for the actual choice, and one for the position of the chosen item. You then tally position selections in a summary area. If left-side selections exceed about sixty percent of total choices, you have a position bias problem and need to adjust your procedure.
Common mistakes that ruin the data
The biggest issue I see is using items that are already available on demand. If the person has free access to tablets or snacks throughout the day, the assessment tells you nothing. They'll pick those items because they want them right now, not because the assessment revealed genuine preference hierarchy. Remove or heavily restrict access to all potential reinforcers for at least two hours before starting. Hunger and boredom make the data meaningful. Another mistake is running the assessment too fast. People rush through the trials and miss latency information. How long the person takes to make a choice matters. Fast selections usually indicate high preference. Hesitation or looking away before choosing can signal low interest or even avoidance. Write down the latency if you can, or at minimum note any obvious refusal behaviors. Some assessors stop after one trial in MSWO. That is not enough. One trial gives you a snapshot, not a reliable ranking. Run at least three trials, preferably five, and rearrange the item positions each time. This controls for positional bias and gives you a stable preference hierarchy.

When preference assessments don't work
They don't work when the person has severe motor impairments that prevent independent selection. They don't work well with individuals who have a long history of automatic reinforcement for a behavior, because the assessment tells you what they want but doesn't address the maintaining variable. And they absolutely fail when the environment is chaotic. If there is constant noise, movement, or interruption during the session, the data is unreliable regardless of how well you designed the sheet. In cases where the assessment fails, the alternative is a reinforcer survey completed by someone who knows the person well, combined with a trial-based assessment using a smaller set of likely items. It is not as thorough but it is often more practical. Surveys like the Reinforcer Survey Checklist or the Incentive Evaluation Checklist give you a starting list, then you validate it with a short paired-choice or MSWO session using only the top items from the survey.
Keeping the data sheet useful over time
Preferences change. What worked in September might not work in January. Update the assessment quarterly at minimum, or whenever you notice a change in responding that suggests the current reinforcers lost value. A preference assessment that is six months old is usually stale data that you are treating like it is fresh. Store the completed sheets in a consistent format. Label them with the date, the method used, the number of trials, and any notes about environmental conditions or unusual behaviors. When you come back to review the data later, those details matter. Without them you cannot tell whether a weird result was due to the procedure or something external that day.


