How to Actually Build a Preference Assessment Questionnaire That Doesn't Suck
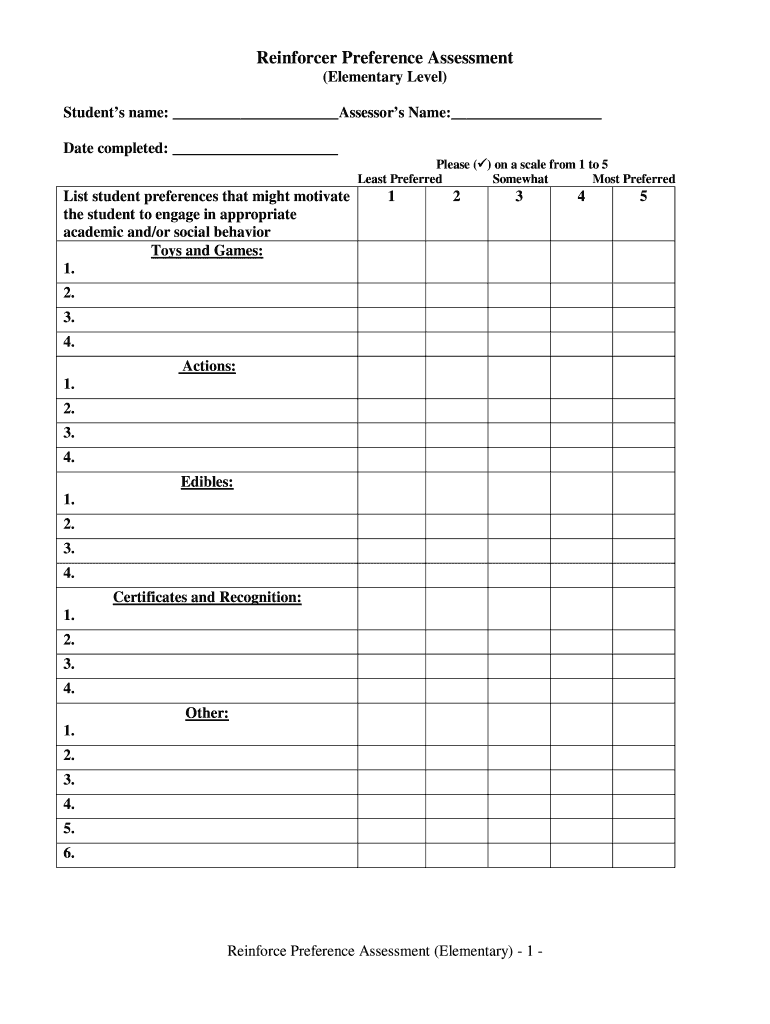
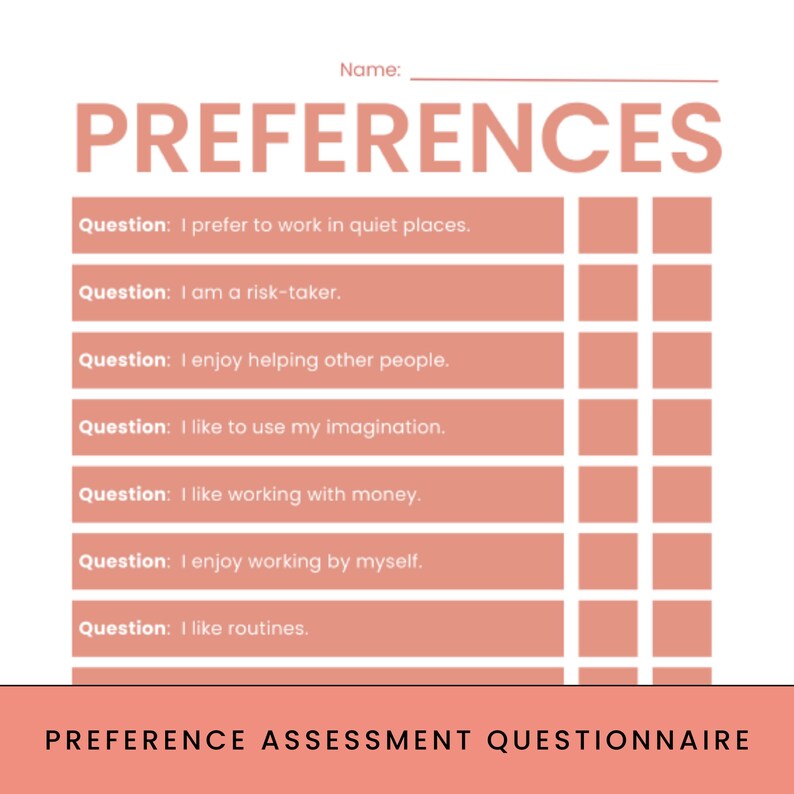
I spent way too many years watching people misuse these things. You'd be surprised how often a "preference assessment" is just a Google Form with five choices and a header that says "Please tell us what you want." That's not an assessment. That's a polite guess. A real Preference Assessment Questionnaire is a structured instrument designed to identify which stimuli a person consistently chooses when given access to multiple options. In clinical settings, it's often used to determine reinforcing items for behavioral interventions. In product research, it helps map what features actually move the needle. The format varies, but the underlying mechanics are the same: you present options, you observe what gets selected, and you don't pretend the data will write itself.
Setting Up a Preference Assessment Questionnaire
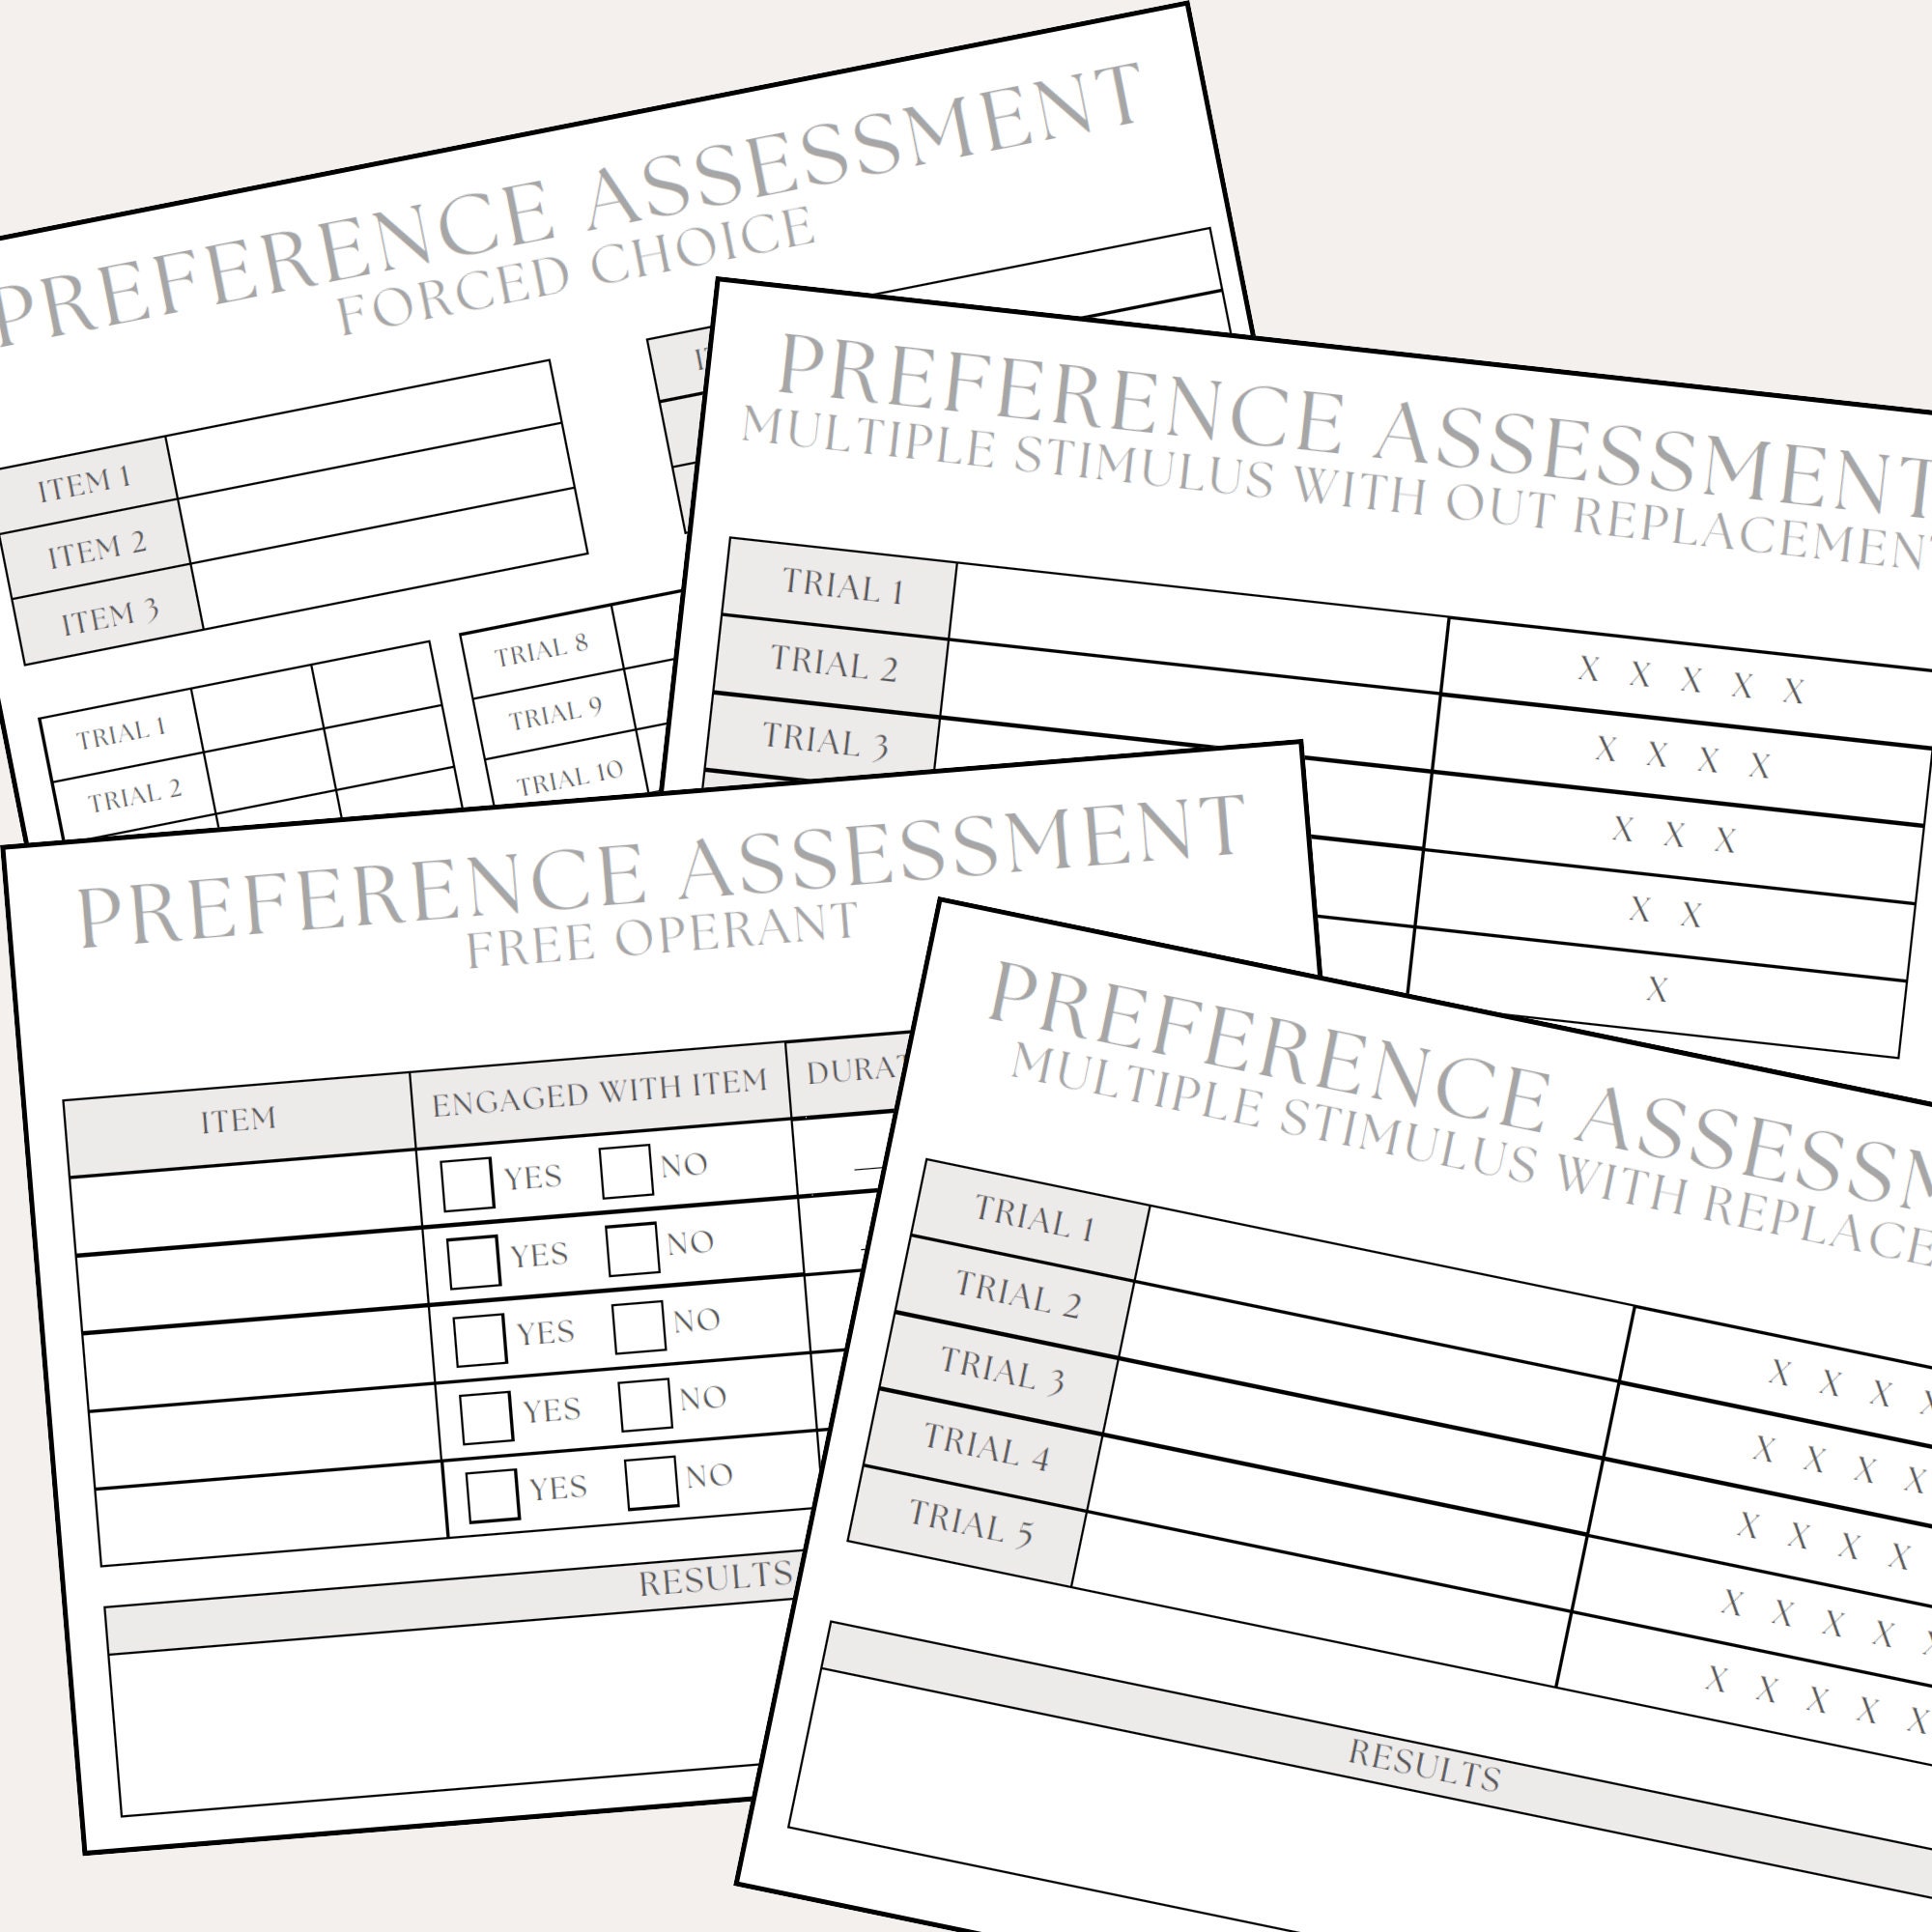
Start by defining what you're actually measuring. This sounds obvious, but most people skip straight to writing questions without deciding whether they want a single-item preference rating, a forced-choice ranking, or a multiple-stimulus without replacement setup. Each approach yields different data quality. Single-item ratings are fast but shallow. Forced-choice rankings create more signal but introduce order effects that mess with your results if you're not accounting for them. Here's the part nobody tells you: the number of items you present matters more than the wording of your questions. When I ran assessments with 8 or more stimuli simultaneously, respondent fatigue set in around item 5, and the last three options got selected at near-random rates. I started limiting my displays to 4 or 5 items maximum and running repeated trials instead. The data was cleaner, and the whole process took about the same total time because I wasn't re-reading sloppy responses from exhausted participants. You need to randomize presentation order every single trial. If you always put the same item in position one, position bias will creep into your results and you won't notice it until you've already made decisions based on corrupted data. I learned this the hard way during a product feature assessment where our top-ranked feature was consistently placed first in the display. It wasn't the most preferred feature. It was just the most visible one.
What the Data Actually Looks Like
A well-run preference assessment produces a ranking or frequency count, not a vague sense of direction. You're looking for clear winners, not consensus mediocrity. If every option scores between 3 and 4 out of 5 on a Likert scale, you haven't assessed preferences. You've confirmed that everyone is mildly indifferent, which is itself useful information but not what most people want to hear. The gold standard in behavioral contexts is the multiple-stimulus without replacement (MSWO) method. You lay out all available items, the participant selects one, you record it, remove it, and repeat until nothing is left. The resulting preference hierarchy is usually stark and reliable. Single-choice methods like the paired-stimulus procedure work too, but they take longer and require more setup. MSWO gives you a full ranking in a single session for most participants. In market research, things get messier because people lie to themselves and to you. They'll rank sustainable packaging as their top priority and then buy the cheapest option every time. A Preference Assessment Questionnaire can surface stated preferences, but it won't fix the gap between what people say and what they do. I've seen teams treat stated preference data as ground truth and launch products that flopped because the underlying behavior never matched the questionnaire results.
Get the Full Details
Pitfalls That Will Sink Your Assessment
The biggest mistake is assuming that a high preference score equals high motivation. Someone might rate chocolate cake as their top food preference but wouldn't actually choose it over a salad if you gave them both right now and had to eat it. Preference and motivation are related but distinct, and conflating them leads to bad interventions and bad product decisions. I've watched ABA therapists build reinforcement programs around items that scored high on a questionnaire but produced zero behavioral change during actual sessions. The fix was to switch to a live choice-based assessment instead of relying on the paper version. Another issue is novelty bias. New items get chosen more often simply because they're novel, not because they're preferred. If you're running an assessment on a regular schedule, rotate your items in and out so that novelty doesn't systematically inflate certain options. I keep a log of which items have been presented recently and flag anything that's appeared more than twice in the last three sessions for extra scrutiny. There's also the question of satiation. An item that dominates the preference hierarchy on Monday morning might drop to the bottom by Thursday afternoon if the participant has had enough of it. This is especially relevant in clinical settings where the same reinforcers are used repeatedly. My workaround is to run assessments at consistent times of day and to re-assess whenever I notice a sudden shift in responding that doesn't match any environmental change.
Sometimes the tool just doesn't work. If a participant has a severe cognitive impairment, limited motor ability, or communication barriers, a standard Preference Assessment Questionnaire may produce unreliable data regardless of how well you design it. In those cases, you fall back to indirect methods like caregiver interviews and observational assessments, or you adapt the format entirely. No amount of survey trickery fixes a fundamental mismatch between the tool and the person you're trying to assess.
When to Use It and When to Walk Away
Preference assessments are useful when you need to identify potential reinforcers or features quickly and with reasonable confidence. They're not useful when you need to predict complex real-world behavior, when your sample size is under 20 and you're treating individual variation as noise, or when the stakes are high enough that you should be running controlled experiments instead. A questionnaire tells you what someone chose when you offered them a handful of options in a controlled setting. That's valuable, but it's a specific kind of valuable, not a universal one. If you're building one from scratch, keep it short, randomize aggressively, and validate your results against actual behavior before you act on them. The tool works best when you treat it as a starting point rather than a conclusion.