What PCA Actually Does Before You Touch R
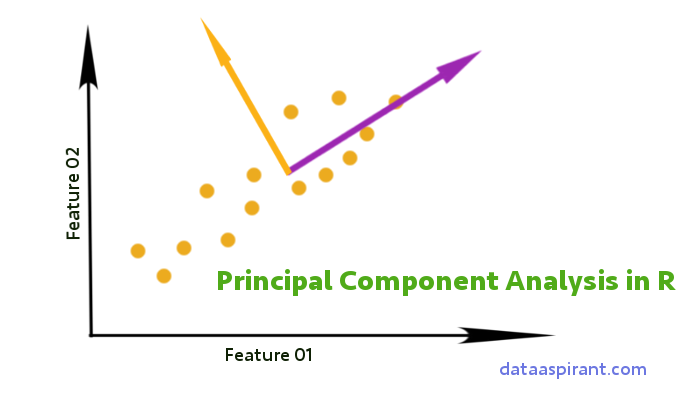
It takes your correlated variables and rotates them into a new coordinate system where the first axis captures the most variance, the second captures the next most, and so on. Everything is centered and often scaled. The output is a list of components you can project your data onto or use for downstream modeling. I learned this the hard way on a hospital dataset with 40+ lab values, many of which moved together because sicker patients tested more aggressively. Running pca() without thinking through scaling produced results that were mathematically correct but practically useless. The first component was essentially "total lab volume" driven by variables on different scales.
Getting Started With Principal Components Analysis In R
The base function is prcomp(). It's fast, numerically stable, and returns objects that are easy to work with. Load your data, make sure it's numeric, remove or impute missing values, then run the function. The summary output shows the standard deviation, proportion of variance, and cumulative proportion for each component. That last number is what matters when you decide how many components to keep. If the cumulative variance plateaus at three components, you have your answer. If it keeps climbing past ten, your data might be noisy or high-dimensional in a way PCA alone won't clean up. Not centering. Not scaling. Using categorical variables as if they're continuous. Forgetting that PCA is sensitive to outliers. Using the wrong function for the job. Each of these produces garbage results that look reasonable because the code runs without errors.
I once ran PCA on a dataset with a few extreme values from a sensor malfunction. The first component was basically an outlier axis. Removing those five rows changed everything. I still get that one wrong occasionally.
Get the Full Details

When Scaling Decides Your Result
Scaling changes the whole landscape. Without it, variables with larger ranges dominate. With it, you treat every variable equally. The choice depends on your goal. If you're trying to understand natural variance in the original measurement units, don't scale. If you want patterns that ignore unit differences, scale. There's no universal answer. Most published work scales. Most people who get weird results forgot to scale or scaled when they shouldn't have. Check your variable ranges before deciding.
Interpreting the Output Correctly
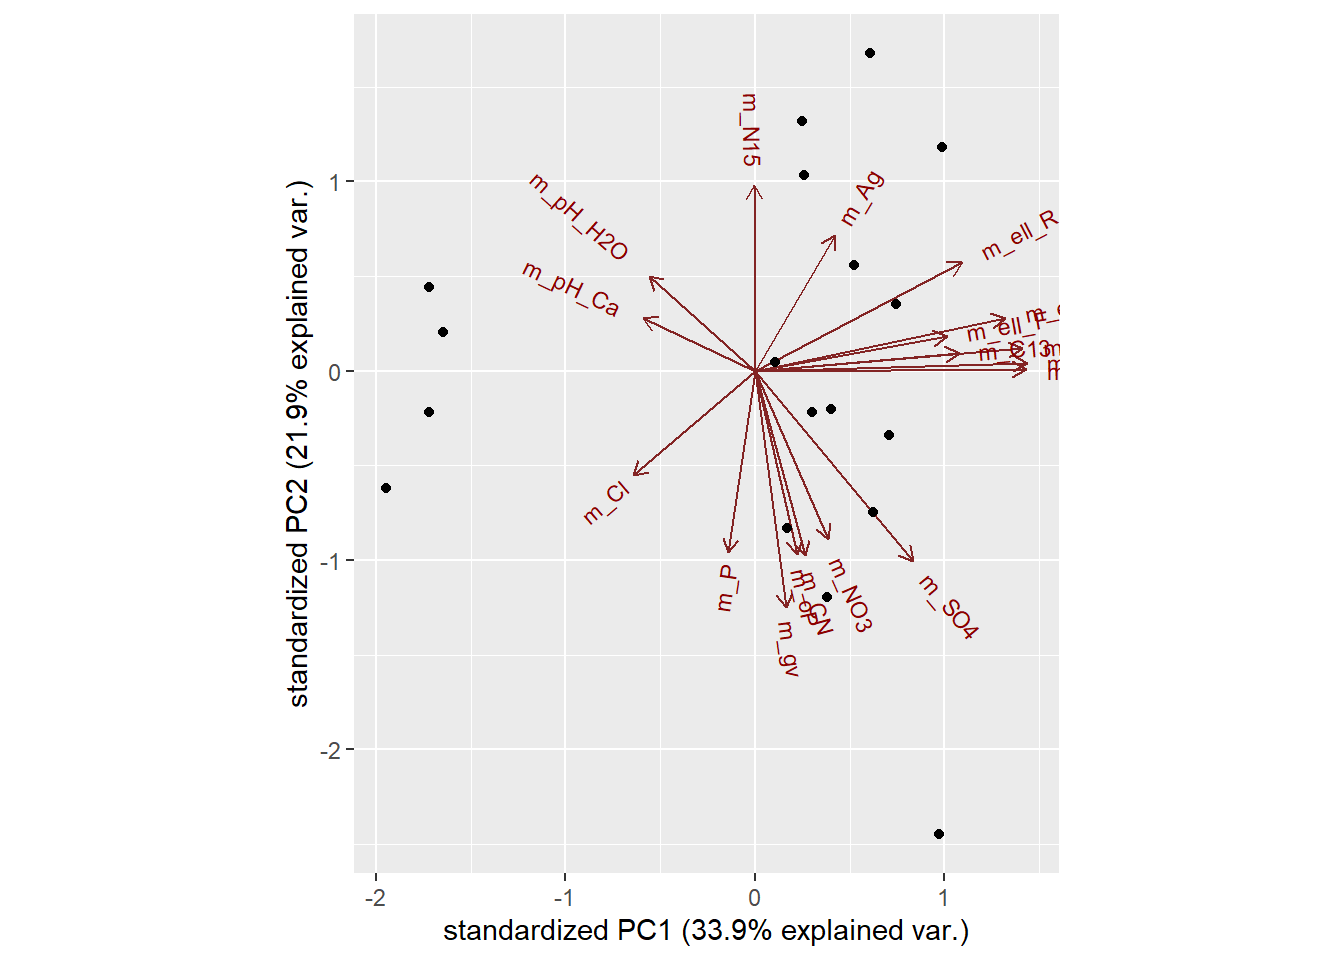
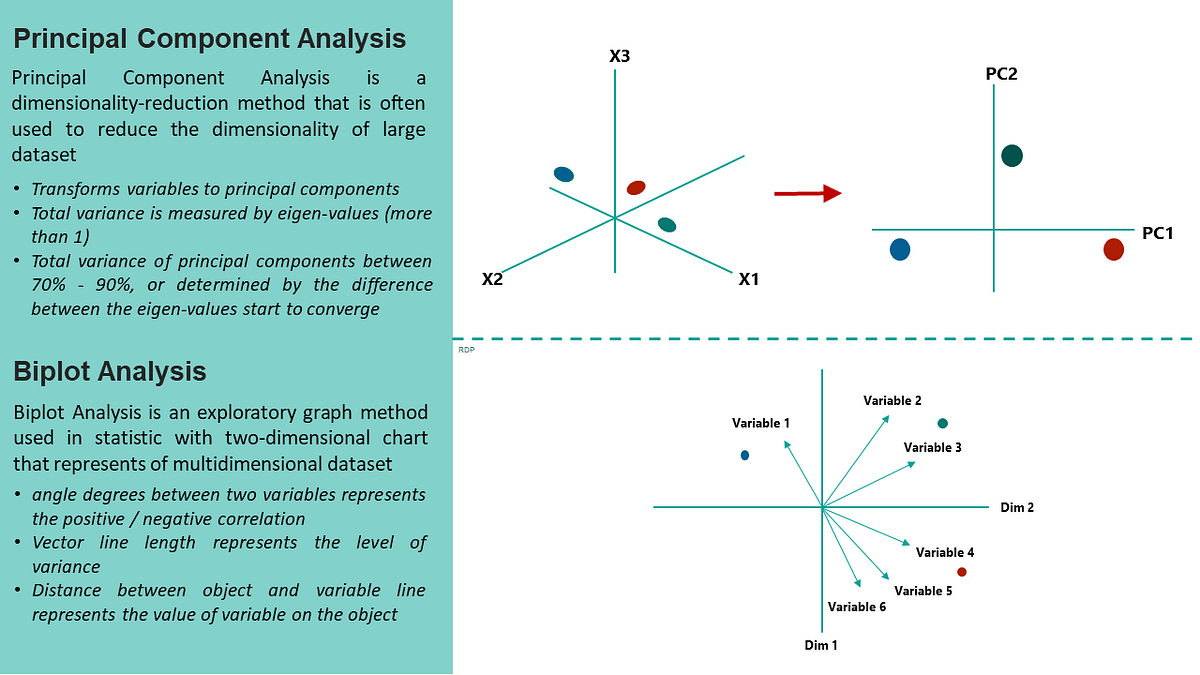
Look at the loadings. High absolute loadings mean that variable contributes strongly to the component. Negative loadings mean the variable moves opposite to the component direction. A loading near zero means the variable doesn't participate much. This tells you what each component actually represents. I had a marketing dataset where the first component had high negative loadings on ad spend and high positive loadings on organic reach. The component was basically "digital strategy balance." Naming it helped the team use it in regression models.
Choosing How Many Components to Keep
Two methods exist. The Kaiser criterion keeps components with eigenvalues greater than one. It's simple but often keeps too many. The scree plot shows a bend where variance gains diminish. You keep components before the bend. It's subjective but usually better. I use both and let the business question decide. If the goal is dimensionality reduction for modeling, I pick the elbow. If the goal is exploratory understanding, I look at interpretability.

Edge Cases and Workarounds
One time I ran PCA on a dataset with 500 observations and 450 variables. prcomp() completed but the results were unstable. The matrix was nearly singular. I switched to prcomp_irlba(), which uses iterative approximation, and the run time dropped from over an hour to about three minutes with identical-looking results. Another issue is missing data. prcomp() refuses to run with NAs. You can use mice() for imputation or svdImpute() from the amelia package. Both add their own assumptions. Test sensitivity by running PCA on multiple imputed datasets.
Downstream Use: Regression and Classification
PCA scores work as predictors. They remove multicollinearity and reduce dimensionality. The trade-off is interpretability loss. A regression coefficient on PC1 means nothing without the loading matrix. Write down what each component represents before model building. I've used PCA scores in logistic regression with good cross-validated performance. The model generalizes better than one with all original features. But I always keep the loading matrix in version control alongside the model artifacts.
Limitations You Should Know About
PCA assumes linear relationships. If your data has nonlinear structure, PCA will miss it. Kernel PCA or autoencoders handle that better. PCA is also sensitive to outliers. A single extreme point can distort components. Robust PCA exists but requires different tools. The method destroys the original variable meanings. You cannot reverse the transformation to get back interpretable features. If interpretability matters, consider factor analysis or selective variable removal instead.
Alternative Approaches Worth Knowing
For nonlinear data, try kernel PCA through the kernlab package. For very high-dimensional sparse data, try truncated SVD from the bigmemory ecosystem. For clustering prep, standardize first, then apply PCA, then cluster on the scores. The order matters more than most people realize. I use a quick preprocessing pipeline: clean data, handle missing values, scale, run PCA, check scree, select components, verify stability with bootstrapping if the sample is small. This takes about fifteen minutes for a typical dataset and prevents most common errors.
Package Recommendations
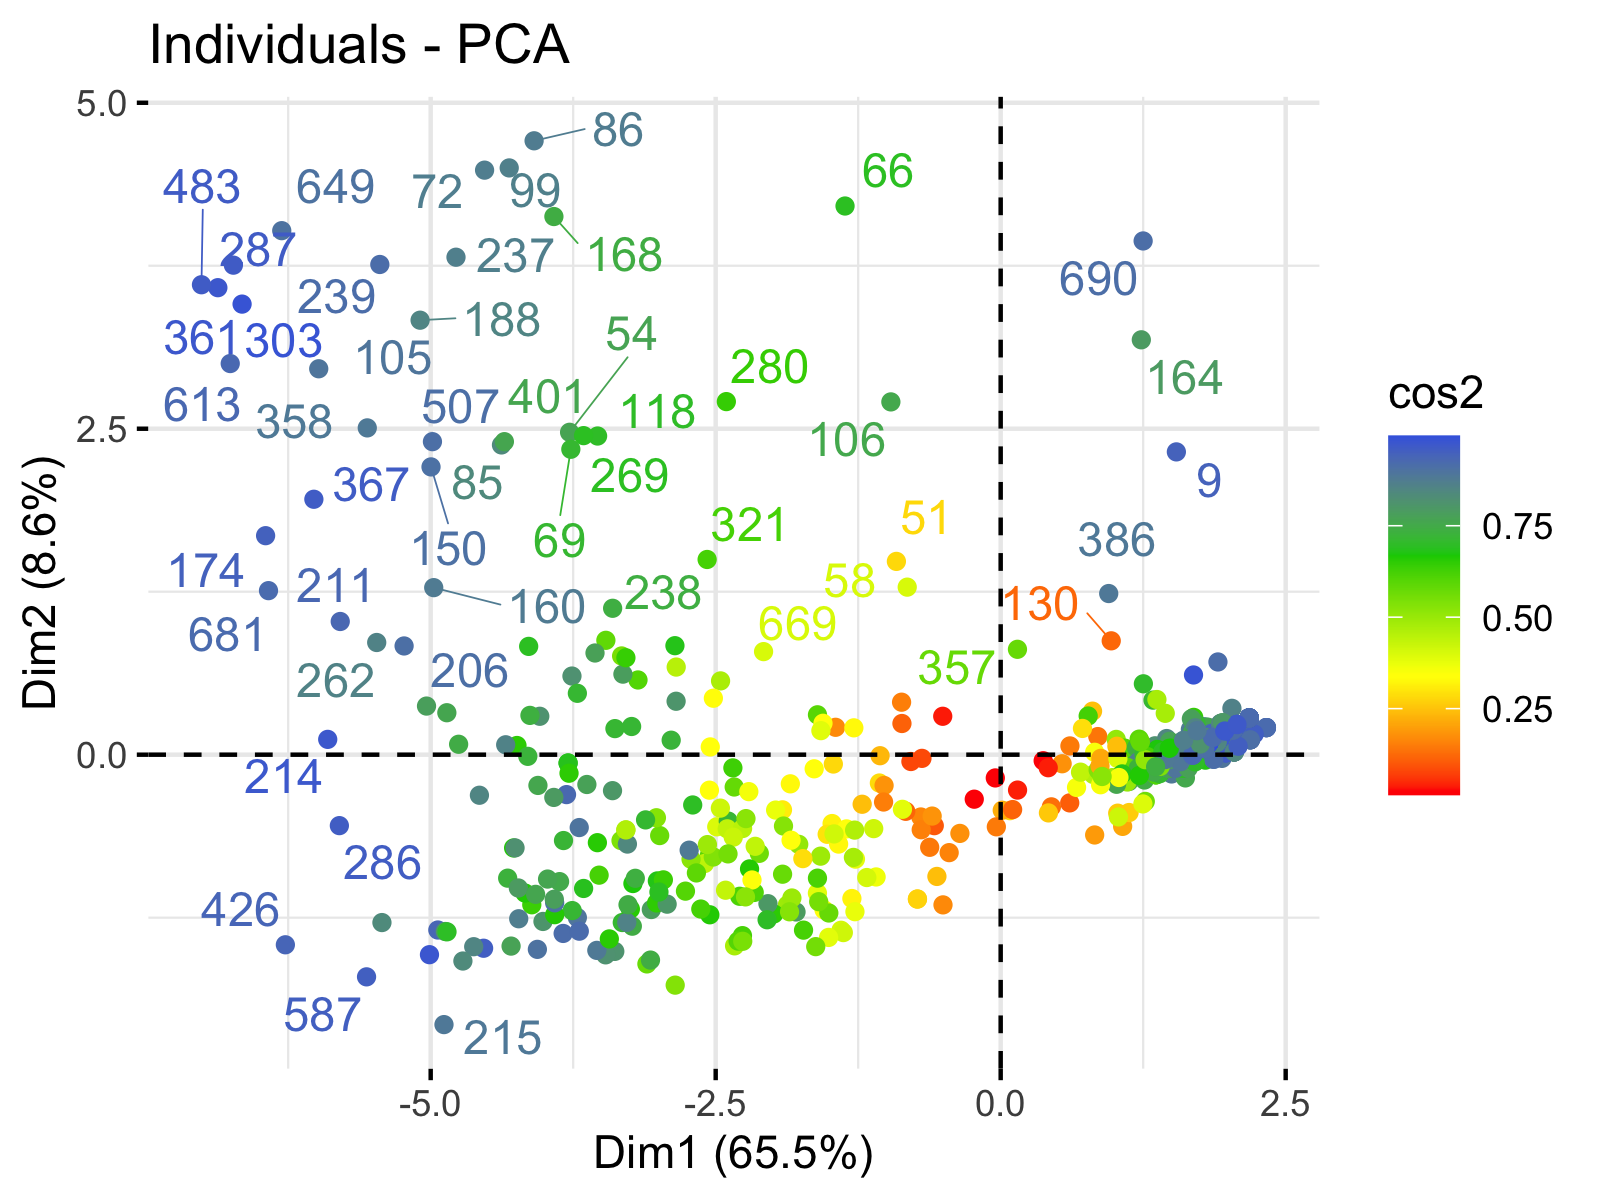
Base R is enough for most cases. FactoMineR adds nice visualization functions and cluster mapping. The ade4 package handles complex experimental designs. For interactive exploration, ggfortify makes autoplot() work on prcomp objects without extra code. I keep FactoMineR installed for biplots and contrib plots. The default base R plots are functional but theFactoMineR visuals communicate better to stakeholders who aren't comfortable reading loading matrices.