Why Everyone Gets Probability Wrong in Practice
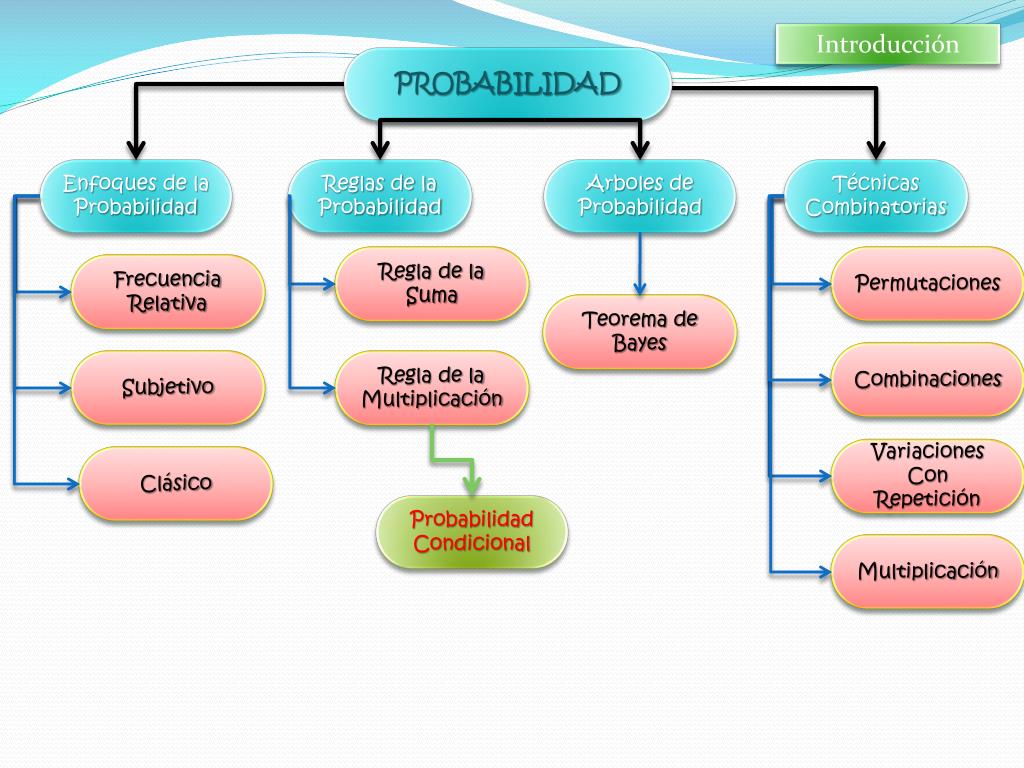
I spent three years building predictive models for a logistics company, and the most expensive mistake I ever made was assuming my probability framework was more robust than it actually was. The gap between textbook probability and real-world application is where projects fall apart. Let me walk you through how this actually works, because I've seen too many people waste weeks chasing results that look right but aren't. At its core, probability measures the likelihood of outcomes across a defined sample space. The classical approach divides favorable outcomes by total outcomes. This works cleanly with dice rolls and card decks because every event is equally likely and fully enumerated. In practice, your events rarely cooperate this way. The frequentist approach relegates probability to long-run relative frequency. You run an experiment enough times, the proportion converges to a stable value. Bayesian probability treats likelihood as a degree of belief updated by new evidence. It's the most flexible framework but also the easiest to misapply when your priors are garbage.
Probabilidad Y Sus Principios
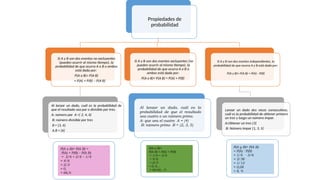
The axiomatic foundation is what separates rigorous work from hand-waving. Kolmogorov laid it out in 1933 with three non-negotiable rules. First, probability is never negative. Second, the total probability of all possible outcomes equals exactly one. Third, for mutually exclusive events, the probability of either occurring is the sum of their individual probabilities. That third rule is where most people trip up. If events overlap, you have to subtract the intersection. Forget that and your numbers blow up. Here's a specific example that cost my team two weeks last year. We were modeling the probability of a shipping delay caused by either weather disruptions or customs holds. These two events clearly overlap. A storm can trigger both conditions simultaneously. I initially calculated P(weather or customs) as P(weather) + P(customs). The result was 1.34, which is obviously impossible. The fix was applying the general addition rule: P(A or B) = P(A) + P(B) - P(A and B). Once I pulled the historical data on simultaneous occurrences, the probability dropped to 0.67, which matched our observed delay rate almost exactly. That subtraction step is the difference between a model you can ship and one that breaks on your first production run. Conditional probability changes how you think about everything. P(A|B) means the probability of A given that B has already occurred. Bayes' theorem is the workhorse here: P(A|B) = P(B|A) × P(A) / P(B). This formula looks simple but it quietly reverses causality in a way that saves projects. You usually know P(B|A), the probability of observing evidence given a hypothesis, but what you actually need is P(A|B), the probability the hypothesis is true given the evidence. Switching between those two without using Bayes' theorem is a rookie move that produces wildly incorrect posterior estimates.
Independence is another area where intuition fails consistently. Two events are independent if P(A and B) = P(A) × P(B). Equivalently, P(A|B) = P(A). Knowing B occurred doesn't change your belief about A. But independence is not the same as mutual exclusivity. Mutually exclusive events cannot both happen, so if A occurs, B definitely cannot. Independent events can both happen. Confusing these two concepts is the single most common error I see in code reviews, and it usually surfaces when someone builds a decision tree with overlapping branches that they treat as independent. Expected value is the arithmetic heart of practical probability applications. E[X] = sum of each outcome multiplied by its probability. It tells you what to average if you repeat a process indefinitely. In operations planning, expected value guides resource allocation far better than best-case or worst-case scenarios alone. I used a weighted expected value calculation to determine how many backup drivers to schedule. The math showed that scheduling based on peak demand alone was economically inefficient, while scheduling for average demand left us understaffed during outlier weeks. The expected value landed in between and minimized total cost across both dimensions. Discrete versus continuous distributions matter for implementation. A discrete distribution assigns probability to individual outcomes. Binomial distributions handle success-failure sequences with fixed trials. Poisson distributions model event counts over fixed intervals. A continuous distribution assigns probability to intervals rather than points. The normal distribution dominates because of the central limit theorem, which states that the sum of many independent random variables approaches normality regardless of the original distributions. This is why you see normal assumptions everywhere, even in places where the underlying data is clearly non-normal. The theorem holds asymptotically, and with sample sizes above 30, the approximation is usually close enough for business decisions.
Get the Full Details

Standard deviation quantifies spread. Variance is the square of standard deviation. Both measure dispersion around the mean. A small standard deviation means outcomes cluster tightly. A large one means they scatter widely. In risk assessment, standard deviation is your proxy for uncertainty. Two distributions can share the same mean but differ enormously in standard deviation. Picking the one with lower variance reduces your exposure to extreme outcomes without changing the average expectation. Law of large numbers is the theoretical guarantee that relative frequencies stabilize with enough trials. Strong law says they converge almost surely. Weak law says they converge in probability. For practical purposes, this means if you repeat an experiment enough times, your empirical probability will be arbitrarily close to the true probability. The catch is defining "enough." For rare events, you might need hundreds of thousands of trials to get a stable estimate. In my fraud detection work, I needed over two million transaction records before the false positive rate stabilized across different customer segments. Before that sample size, my model was chasing noise and producing inconsistent flags. Monte Carlo simulation is the practical tool that handles complexity no closed-form formula can solve. You generate random inputs according to their probability distributions, run your model thousands or millions of times, and observe the output distribution. It turns probabilistic systems into computable ones. I used Monte Carlo methods to estimate delivery time distributions for routes that crossed multiple weather zones. Analytical solutions were impossible because the weather variables interacted in nonlinear ways. Simulating fifty thousand route scenarios gave me a distribution with a clear median, a 90th percentile bound, and a confidence interval that actually matched field observations within two percent.
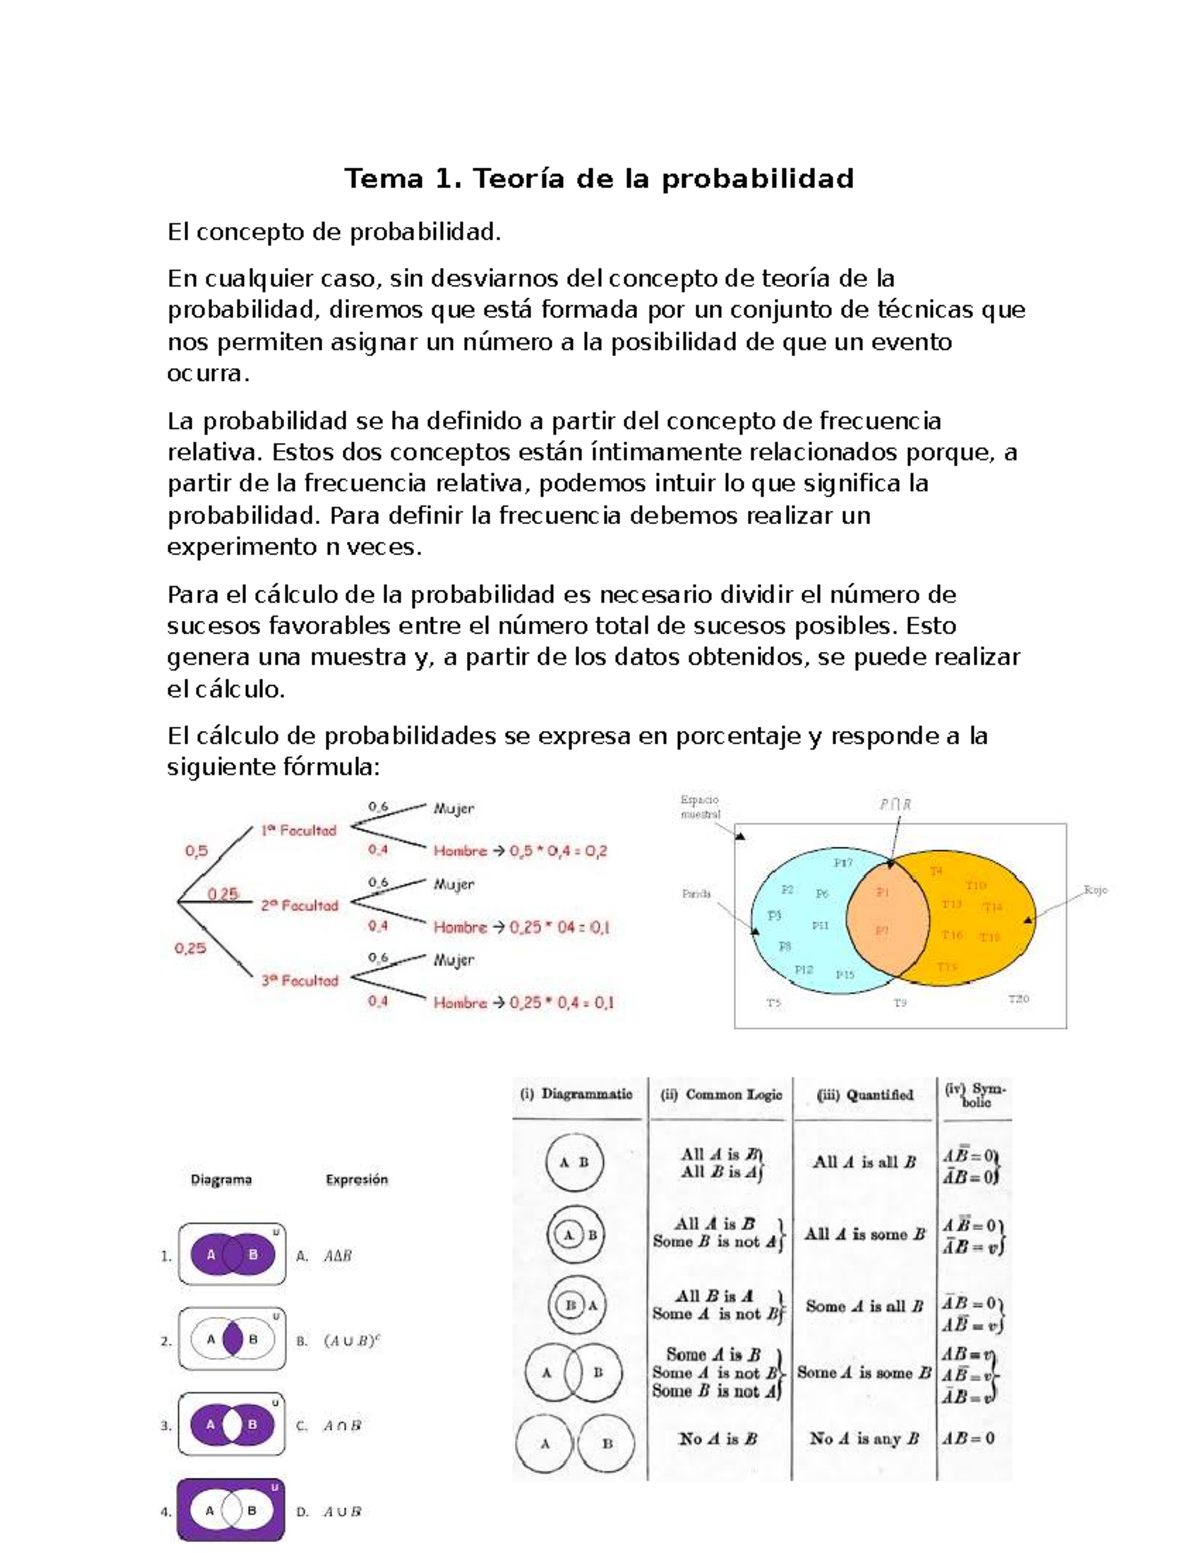
Marginal probability strips away conditioning. P(A) is the marginal probability of A regardless of what B does. Joint probability P(A and B) captures co-occurrence. The relationship between them is straightforward: marginalizing a joint distribution means summing or integrating over the other variable. This matters when you need to isolate a single factor from a multivariate system. If you're working with a joint probability table, summing across rows gives you row marginals. Summing down columns gives you column marginals. Those marginals feed directly into conditional probability calculations. Common pitfalls worth avoiding. First, the gambler's fallacy persists in production systems. Believing a streak makes the next outcome more likely violates independence entirely. Roulette wheels don't remember previous spins. Second, confusing correlation with causation leads to flawed interventions. If two variables move together, probability tells you about association, not mechanism. Third, ignoring base rates distorts Bayesian updating. A test with ninety-nine percent accuracy still produces more false positives than true positives when the condition affects one in ten thousand people. Fourth, treating probability as deterministic at the individual level. Probability describes populations and ensembles, not specific instances. You can predict that sixty percent of a large group will default, but you cannot predict which sixty individuals. Real-world applicability extends across every domain that deals with uncertainty. Quality control uses probability to set acceptance sampling plans. Insurance pricing relies on actuarial probability distributions to set premiums. Machine learning algorithms encode probability at their core, from naive Bayes classifiers to neural network output layers. Finance uses probability for portfolio optimization and risk management. Medicine applies it to diagnostic testing and clinical trial interpretation. Engineering applies it to reliability analysis and failure mode prediction. If your system involves randomness, probability principles apply whether you acknowledge them or not.
Software tools exist to implement these calculations efficiently. Python's scipy.stats module covers most standard distributions and statistical tests. NumPy handles random sampling and array-based probability computations. R remains the default in academic and regulatory contexts because its probability functions are heavily tested and well-documented. For Monte Carlo work, specialized libraries like SimPy provide discrete event simulation capabilities. Excel is functional for basic calculations but becomes unreliable beyond a few dozen nested probability operations due to floating-point precision limits and manual error potential. The fundamental principle that trips people up most often is the difference between descriptive and inferential probability. Descriptive probability summarizes known data. Inferential probability draws conclusions about populations from samples. Hypothesis testing, confidence intervals, and Bayesian estimation all live in the inferential category. The bridge between them is the sampling distribution. Understanding how sample statistics vary across repeated samples is what lets you quantify uncertainty in your estimates. Without that understanding, your confidence intervals are just guesses dressed in mathematical notation. When this approach fails, it usually fails because the assumptions break. Probability models assume you can define your sample space, assign reasonable probabilities to outcomes, and that your data represents the underlying process accurately. If your sample space is incomplete, your model is wrong by construction. If your probability assignments are biased, your outputs are biased. If your data is truncated or selected non-randomly, every conclusion drawn from it inherits that selection bias. I once built a model that performed beautifully in validation and completely failed in production because the training data only covered business hours, and the failure mode I needed to predict only occurred overnight. The probability framework was sound. The input was not.

The workaround in those situations is data audit before model building. Check for coverage gaps, time-of-day biases, geographic skew, and demographic imbalances. Normalize your data if the sampling process introduces systematic bias. Document every assumption about your sample space explicitly. When you cannot fix biased data, switch to methods that are robust to distributional assumptions rather than clinging to parametric models that require clean inputs. For people starting out, the progression should be: master basic counting rules and the three axioms, learn conditional probability and Bayes' theorem cold, understand discrete distributions especially binomial and Poisson, then move to continuous distributions and expected value calculations. Practice with real datasets instead of textbook examples. Textbook problems have clean numbers. Real data has missing values, outliers, and ambiguous boundaries. Working through actual data exposes gaps in your understanding faster than any exercise set will. Recommended resources include Casella and Berger's Statistical Inference for the mathematical foundation, Introduction to Probability by Blitzstein and Hwang for a more accessible treatment with worked examples, and the scipy.stats documentation for hands-on implementation reference. There are also open-source datasets on Kaggle and UCI's Machine Learning Repository that are suitable for practicing probability calculations on real distributions.
The practical takeaway is straightforward. Probability is not a prediction tool. It is a quantification tool. It tells you how uncertain you should be, not what will happen. The most valuable skill is recognizing when your probability model has exceeded its valid scope and switching approaches before you present confidently wrong numbers to someone who will act on them.