Working With Normal Distribution Probabilities in Practice
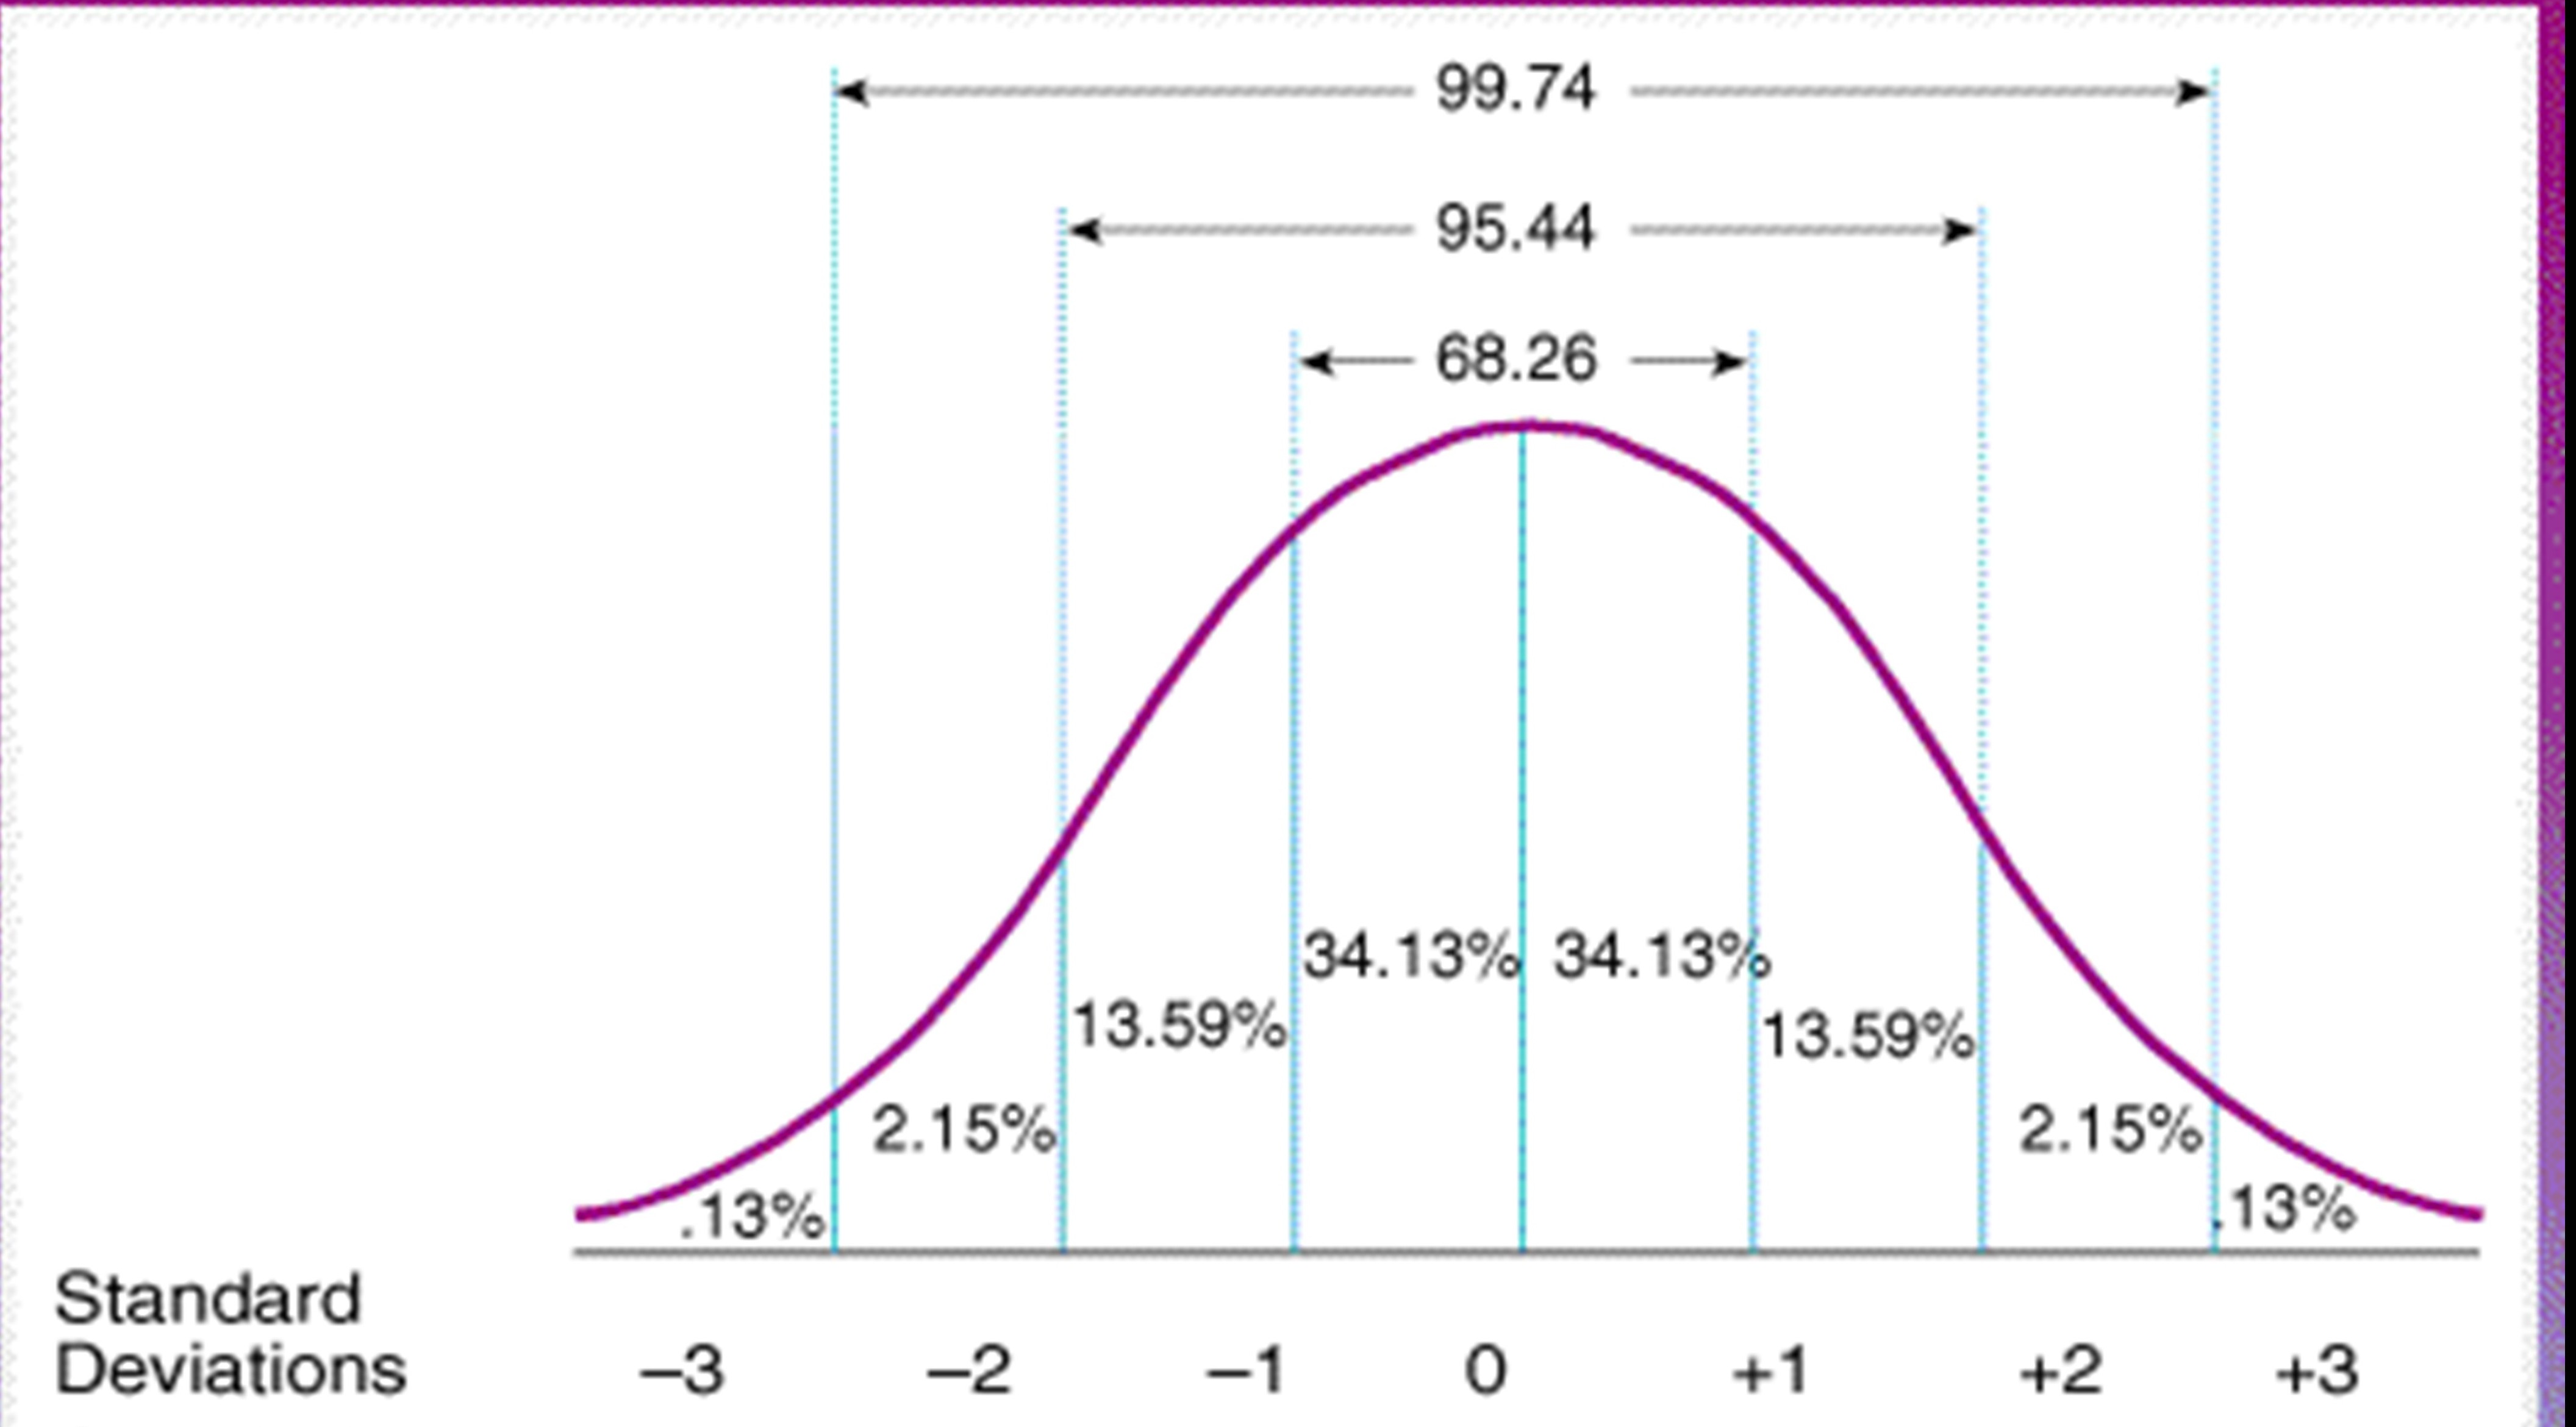
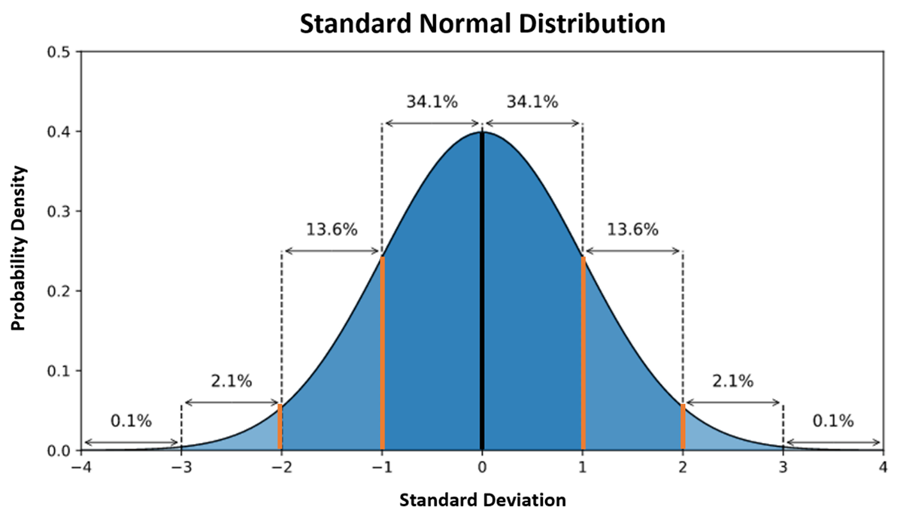
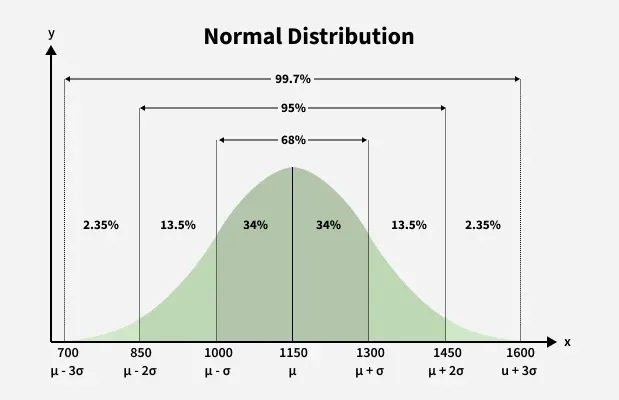
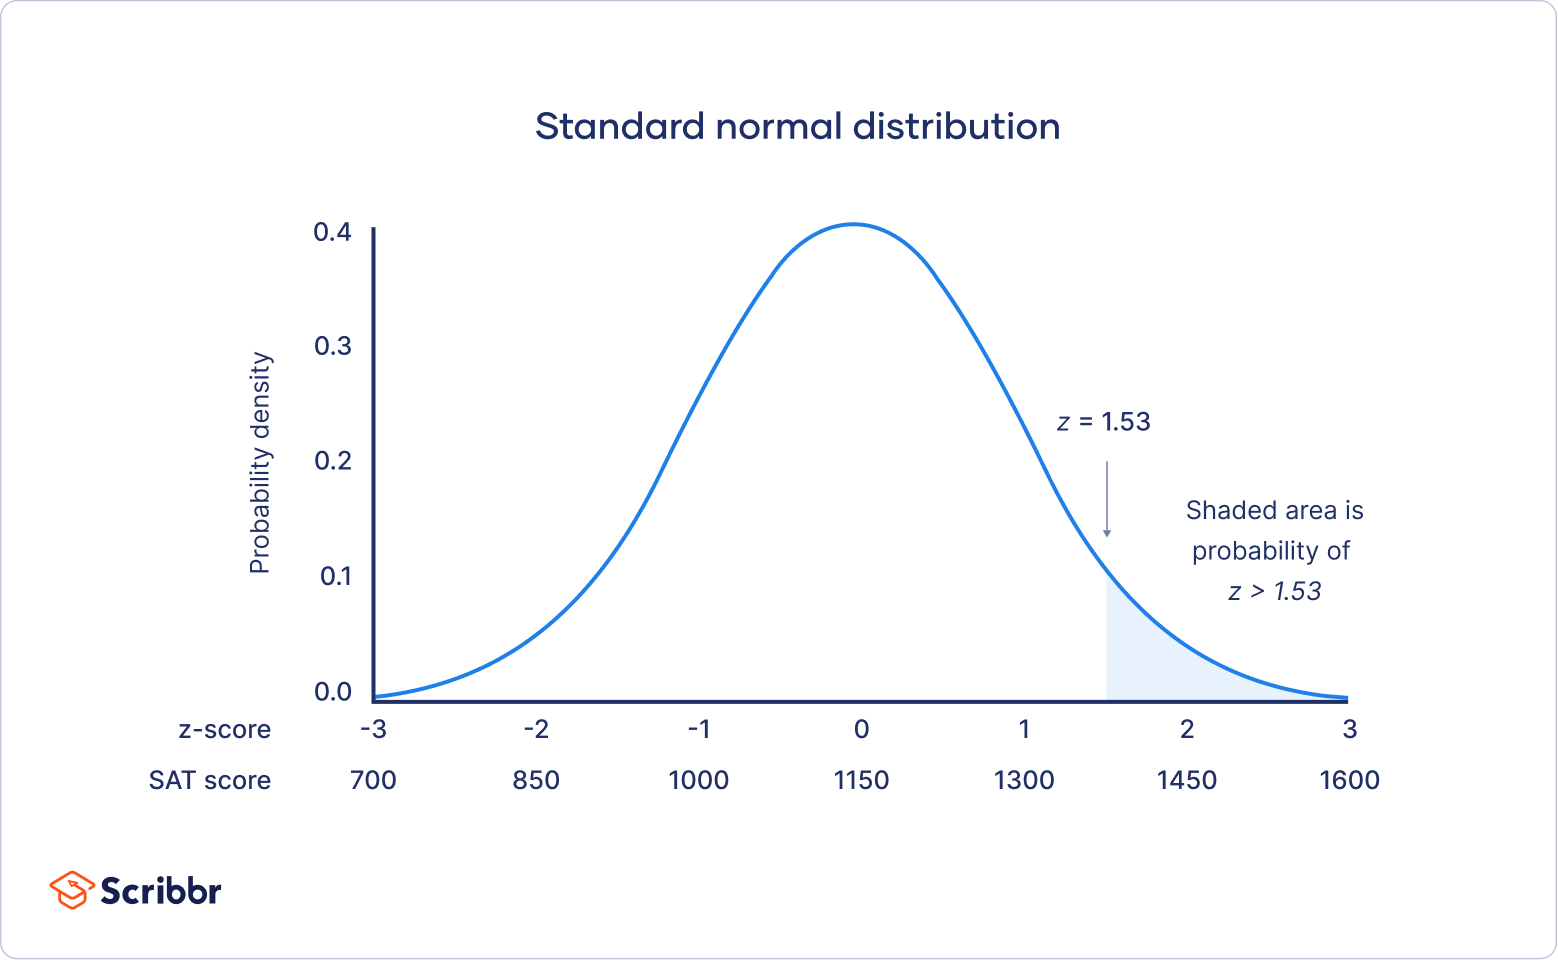
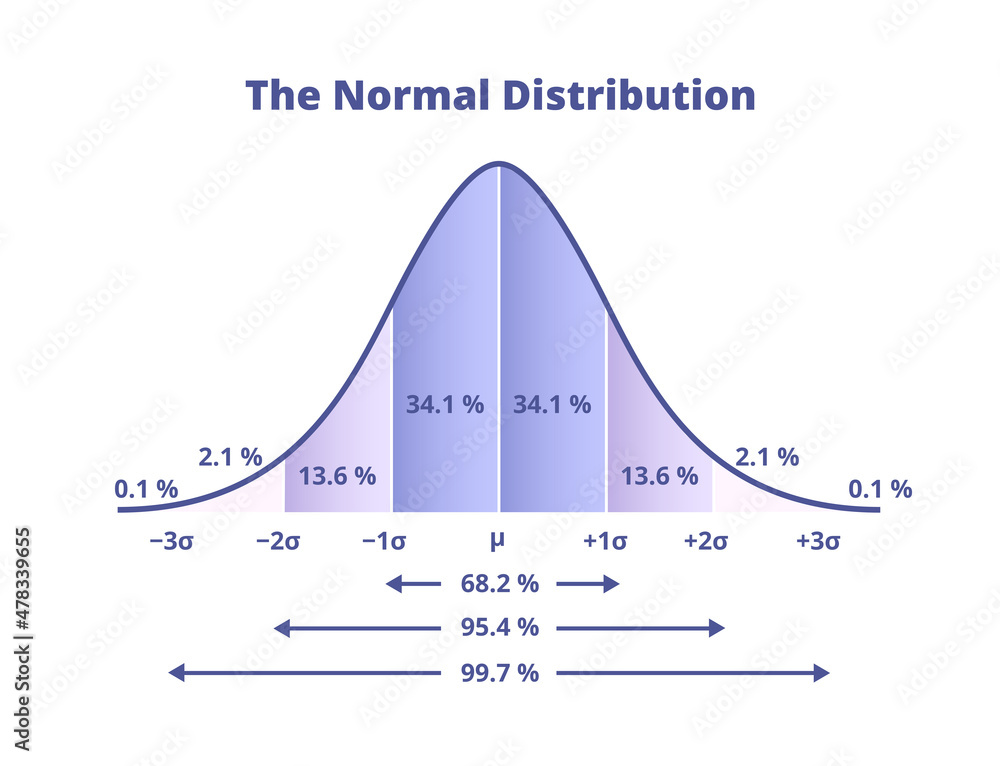
Most people learn about the normal distribution in a statistics class and think they understand it after memorizing the 68-95-99.7 rule. That rule is useful as a quick mental reference, but when you actually need to calculate probabilities for real data, it falls apart pretty fast. I spent years doing quality control work in manufacturing where we had to make these calculations weekly, and the gap between textbook examples and actual work is wider than you might expect. The normal distribution is a probability distribution defined by two parameters: the mean () and the standard deviation (). When we talk about probability in a normal distribution, we're asking what fraction of the total area under the curve falls between any two points. The curve itself has no hard boundaries—it extends infinitely in both directions—but the vast majority of real-world data clusters tightly around the mean. A standard normal distribution has = 0 and = 1, which is just a convenient reference point. Any normal distribution can be converted to it through the z-score formula: z = (x - ) / . Once you have your z-score, you look up the corresponding cumulative probability. Most people use tables, but in practice nobody uses tables anymore. You use a calculator, spreadsheet, or programming language. The process takes about thirty seconds once you know the steps, and I'll walk through exactly how.
The Practical Workflow
Let me give you a concrete example from actual work. We were monitoring bearing diameters on a production line. The specification called for bearings with a diameter between 50.0mm and 50.5mm. Our process mean was sitting at 50.25mm with a standard deviation of 0.08mm. I needed to know what percentage of bearings would fall outside spec, which meant calculating the probability that a randomly selected bearing was either below 50.0mm or above 50.5mm. First step: convert both limits to z-scores. The lower limit gives z = (50.0 - 50.25) / 0.08 = -3.125. The upper limit gives z = (50.5 - 50.25) / 0.08 = 3.125. Both limits are symmetric around the mean, which made this one simpler, but most real problems aren't that neat. Second step: find the cumulative probability for each z-score. Using a standard normal table or calculator function, P(Z < -3.125) 0.0009 and P(Z
3.125) 0.9991. The probability of being within spec is 0.9991 - 0.0009 = 0.9982, meaning about 99.82% of bearings would pass. The probability of being outside spec—either tail—comes to roughly 0.18%.
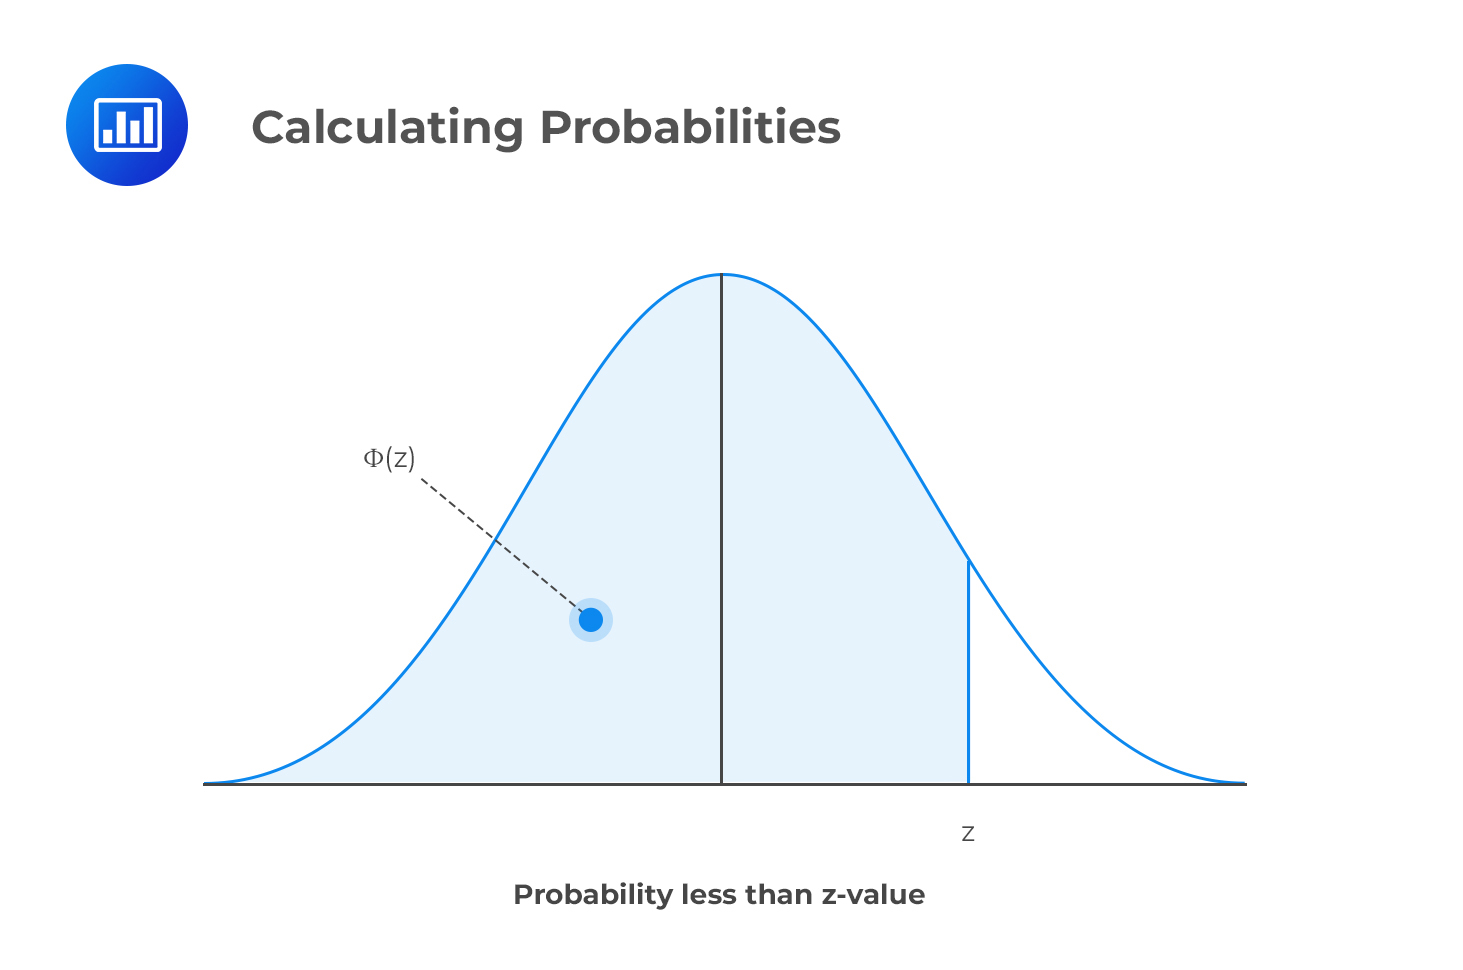
In Excel or Google Sheets, this entire calculation takes one formula: NORM.DIST(50.5, 50.25, 0.08, TRUE) - NORM.DIST(50.0, 50.25, 0.08, TRUE). That's it. If you're using Python, scipy.stats.norm.cdf does the same thing. R users would use pnorm(). The function returns the cumulative distribution function value, which is the area under the curve to the left of your point. For one-tailed questions, like the probability of exceeding an upper limit, you simply use the cumulative function directly or subtract from 1 depending on which tail you need. P(X > 50.5) = 1 - NORM.DIST(50.5, 50.25, 0.08, TRUE).
Get the Full Details
Things Nobody Tells You
The biggest mistake I see beginners make is assuming their data is normal without checking. I once inherited a dataset from a colleague who had calculated process capability indices for what he claimed was a normally distributed process. The Cp and Cpk values looked fine on paper. When I plotted the actual data as a histogram with a fitted normal curve overlaid, it was clearly skewed. The tails were asymmetric. Using the normal distribution assumption in that case had given us wildly inaccurate defect rate predictions—off by a factor of about four in the upper tail. We had been estimating a 0.01% failure rate when the real rate was closer to 0.04%. Always run a normality test before relying on normal distribution probabilities. The Shapiro-Wilk test is the standard for smaller datasets. For larger samples, a Q-Q plot is often more informative than any p-value. If the points on your Q-Q plot deviate noticeably from the reference line, especially in the tails, the normal approximation is not going to serve you well. Another counter-intuitive point that trips people up: the central limit theorem does not mean your data will be normally distributed. It means the sampling distribution of the mean will approach normality as your sample size increases. Your underlying data can be whatever it is. This distinction matters enormously when you're working with small samples or when you're trying to predict individual outcomes rather than estimate a mean.
Where The Normal Distribution Breaks Down
Let me be blunt about the limitations. The normal distribution is a poor model for any process where extreme events matter. Financial returns, earthquake magnitudes, and insurance claims all have what statisticians call "heavy tails"—events that occur far more frequently than the normal distribution predicts. If you're using a normal model to estimate the probability of a catastrophic failure, you are almost certainly underestimating it. I've seen this play out in engineering risk assessments where the normal assumption led to safety margins that were adequate for ordinary variation but insufficient for rare but plausible extremes. Another practical limitation: the normal distribution is defined on an infinite domain. If your variable has a natural boundary—a diameter can't be negative, a reaction time can't be negative, a proportion can't exceed 1—the normal distribution will assign non-zero probability to impossible values. For most well-behaved processes where the mean is several standard deviations away from the boundary, this is negligible. But when the mean is close to zero relative to the standard deviation, you should consider alternatives like the log-normal or beta distribution. When the normal approximation is inadequate, the most common alternatives are the t-distribution for small sample means (it has heavier tails and converges to the normal as degrees of freedom increase), the log-normal for positively skewed data where the logarithm of the variable is normally distributed, and the beta distribution for bounded variables. Each of these has its own cumulative distribution function available in every major statistical package.
Common Calculation Pitfalls
Here are the specific errors I've seen repeatedly in actual work. First, confusing variance and standard deviation. If someone tells you the variance is 0.08, you need to take the square root before using it in the z-score formula. The standard deviation is 0.08 0.283, not 0.08. I've corrected this mistake in other people's reports at least a dozen times, and honestly, I've made it myself too. Second, misinterpreting the output of cumulative distribution functions. NORM.DIST in Excel returns the area to the LEFT of your value, not the area to the right or the area between two points. If you need the area to the right, subtract from 1. If you need the area between two points, subtract the lower cumulative probability from the upper. Getting this wrong is easy and can swing your answer from nearly 0 to nearly 1. Third, applying the same standard deviation across different subpopulations without checking. In my quality control work, we once had a process that appeared normal when viewed as a whole, but splitting the data by shift revealed two distinct sub-populations with different means. The overall standard deviation was inflated by the between-shift variation, making the process look less capable than it actually was within each shift. This is called overdispersion, and it's a common reason why normal-based capability estimates are overly pessimistic.
A Quick Reference for the Calculations
To calculate P(a < X < b) for X ~ N(, ): convert both boundaries to z-scores, find the cumulative probability for each using your tool of choice, subtract the lower from the upper. To calculate P(X > x): find the cumulative probability and subtract from 1. To calculate P(X
x): just use the cumulative probability directly. For the reverse—finding a value given a probability—you use the inverse cumulative distribution function, which is NORM.INV in Excel or scipy.stats.norm.ppf in Python. The whole process, from raw data to probability statement, typically takes about five minutes in a spreadsheet for a straightforward calculation. More complex problems involving multiple constraints or parameter estimation will take longer, usually 15 to 30 minutes depending on how clean your data is. If you're doing this repeatedly across many variables, writing a small script or function to automate the z-score conversion and cumulative lookup will save you significant time over a week.