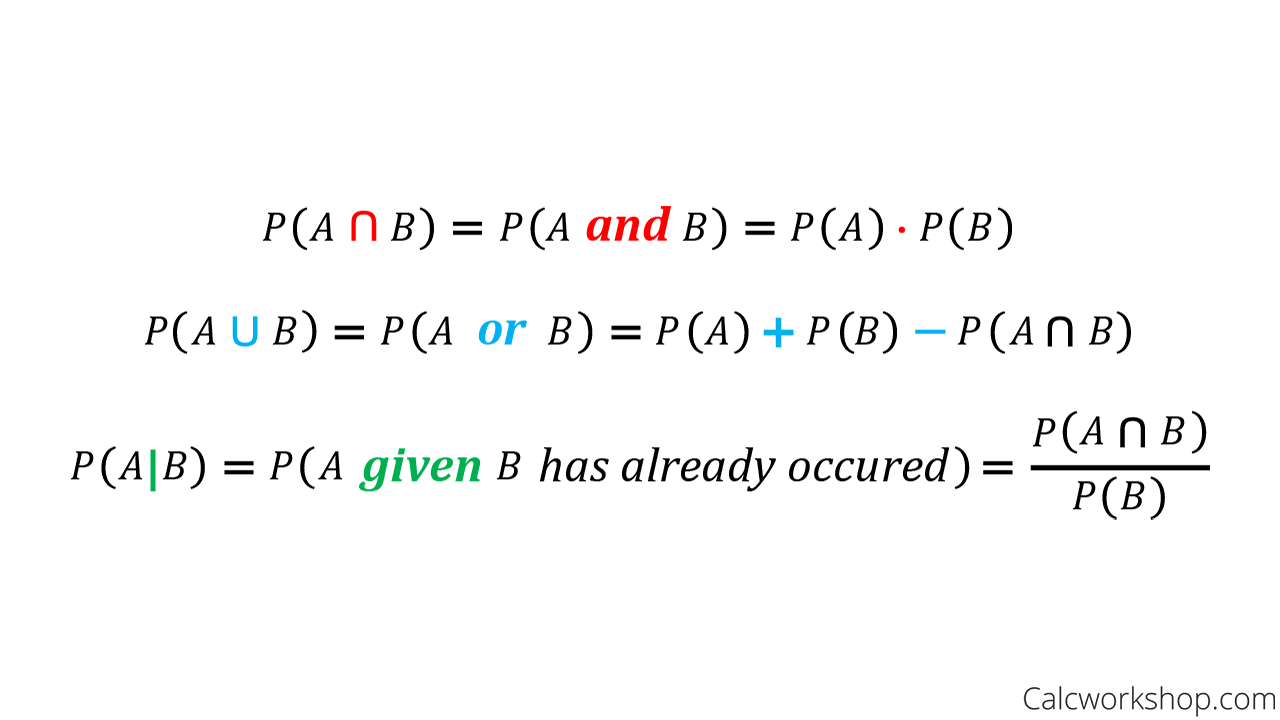
Working With Joint Probability: The Practical Side
Most people learn P(A and B) = P(A) × P(B) in a statistics class and think they understand it. They don't, not really. The formula only works when A and B are independent. That's the first thing that trips people up in practice. I've seen project estimators apply it blindly to dependent scenarios and come back with numbers that were completely wrong. Not slightly off. Completely wrong. Here's how to actually approach this properly.
Understanding The Probability Of A And B
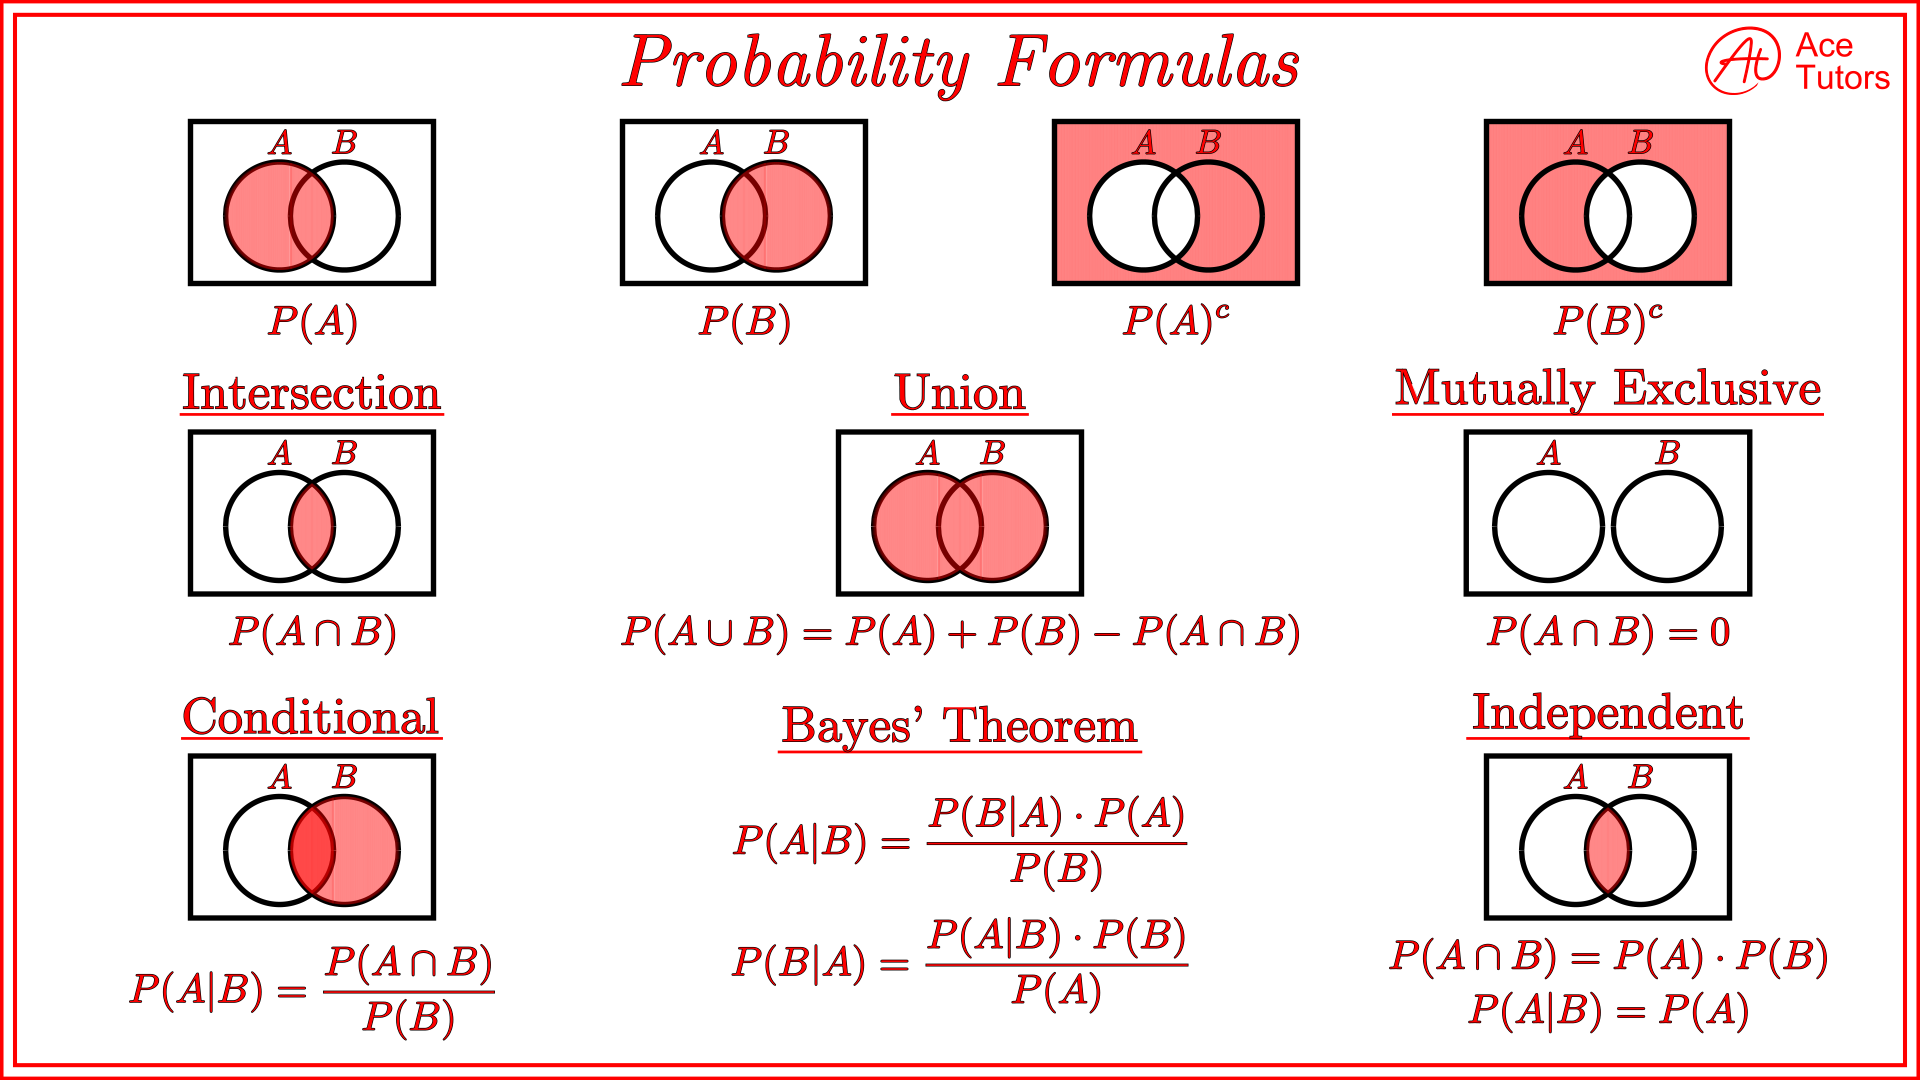
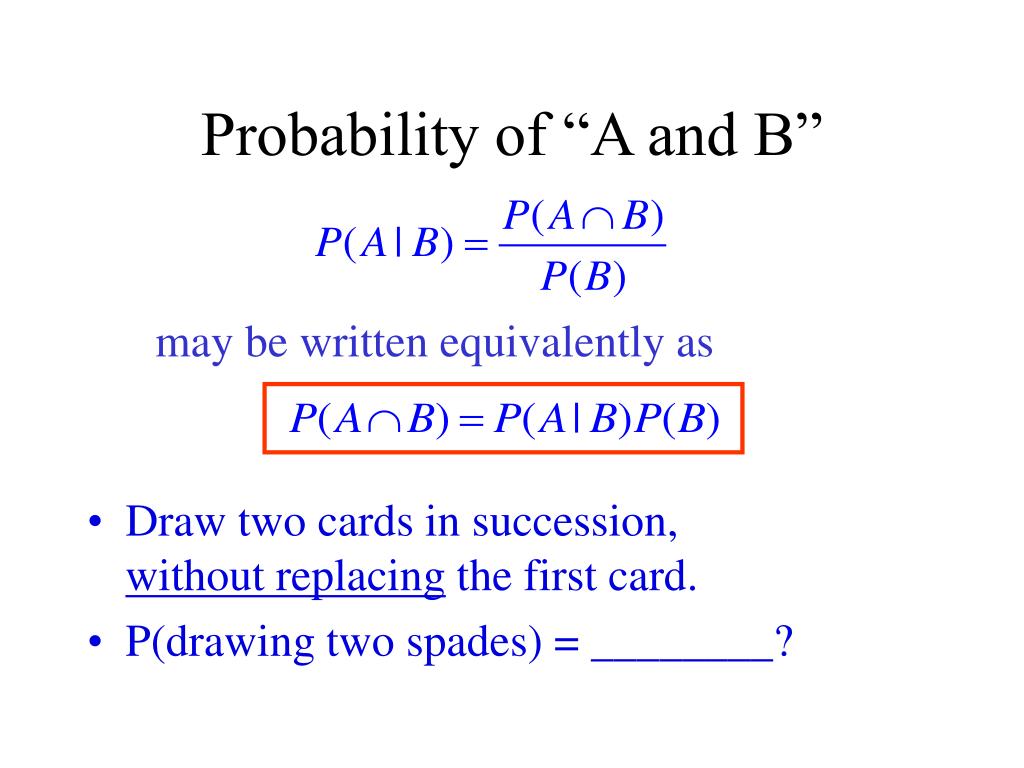
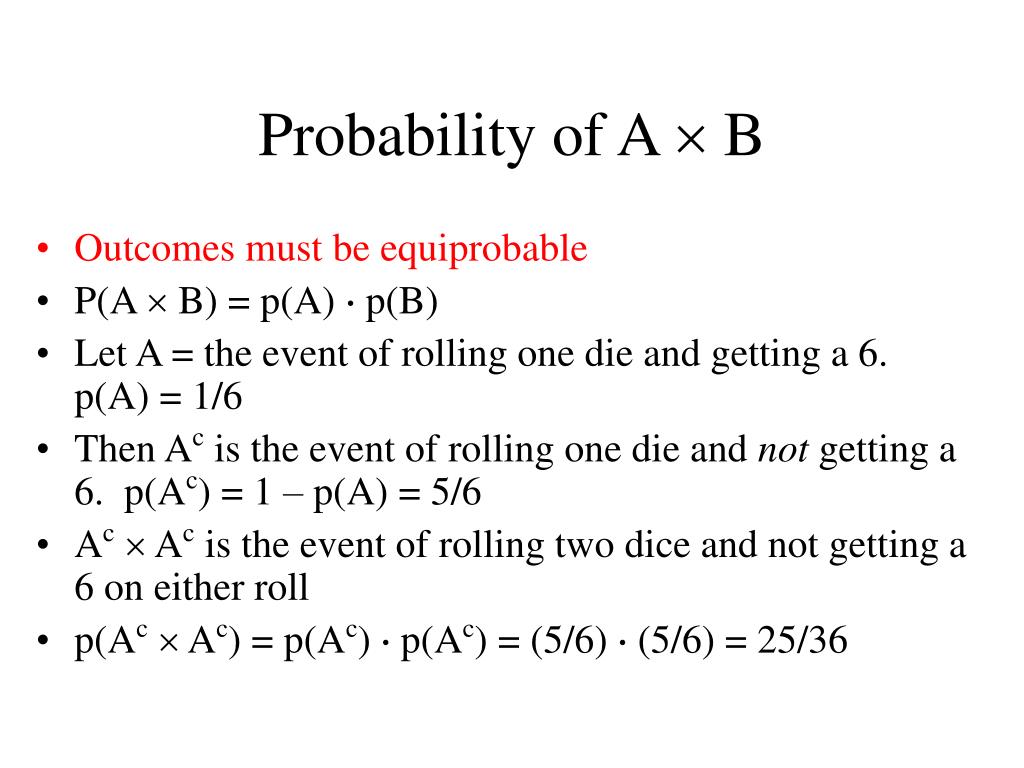
The Probability Of A And B refers to the joint probability — the chance that both events occur together. Written as P(A B) or P(A and B). The notation varies by textbook, but the concept is the same: what's the likelihood that event A happens AND event B happens in the same trial or time window? The general formula accounts for dependence: P(A and B) = P(A) × P(B|A)
Where P(B|A) is the conditional probability of B given that A has already occurred. When A and B are independent, P(B|A) = P(B), which collapses the formula into the simpler multiplication rule you probably remember.
Get the Full Details
When Independence Assumptions Break Down
I ran into this specifically last year while building a risk model for a logistics operation. We were calculating the probability of two delayed shipments arriving on the same day. The naive approach would be multiplying their individual delay probabilities. The problem was that both delays were caused by the same weather system moving through the region. They were clearly dependent, but the dependency wasn't obvious from the raw numbers alone. What I ended up doing was pulling historical weather data to establish a correlation coefficient between the two routes, then using a copula function to model the joint distribution properly. It added about three hours to the work but saved us from underestimating the combined risk by roughly 40 percent. You wouldn't catch that just by looking at P(A) and P(B) separately.
Conditional Probability Is Where Things Get Real
The conditional probability approach is the one most people skip because it requires more data, but it's also the one that matters. If you know something about the relationship between A and B, you need to fold that in. For example, if event A is "it rains today" and event B is "the traffic is bad," these aren't independent. Rain causes traffic problems in most cities. P(B|A) would be significantly higher than P(B). I always recommend starting with a simple contingency table when you have raw data. Put the counts in a grid, calculate row and column totals, and you can derive both marginal and conditional probabilities without reaching for any complex formulas. It's slower if you're doing it by hand, but it makes the logic visible. That visibility is what catches errors before they propagate through a larger model.
Common Pitfalls
There are a few traps that show up consistently: Mixing up union and intersection. P(A or B) uses addition, not multiplication. The formula is P(A) + P(B) P(A and B). Skip the subtraction term and you'll overcount whenever A and B overlap, which is always. I still see this in spreadsheets from teams who should know better. Assuming mutual exclusivity when events aren't mutually exclusive. If A and B can't happen at the same time, then P(A and B) = 0. But most real-world events aren't mutually exclusive. Treat them as if they are and your joint probability collapses to zero when it shouldn't.
Forgetting that order doesn't matter for independent events but does for conditional ones. P(A and B) P(B and A) in the conditional framework unless you adjust for the changed conditioning. This sounds abstract until you're working with time-series data where the sequence of events is the whole point.
Quick Reference for Dependent Events
If you're working with dependent events and don't have conditional probability data readily available, you can sometimes estimate using observed frequency from historical records. Run N trials, count how many times both A and B occurred together, and divide by N. It's straightforward and usually more reliable than assuming independence when you suspect the events are linked. This approach has its own limitations though. You need a large enough sample size for the estimate to be stable. With fewer than a few hundred observations, the margin of error gets wide fast. And it doesn't help you predict future scenarios that haven't happened before, which is often exactly when you need the calculation most.
Bayes' Theorem Connection
If you're working backward from outcomes to causes, Bayes' theorem is the natural extension. It rearranges the conditional probability formula to let you update your beliefs about P(A|B) after observing B. The math is the same foundation, just flipped. People who get comfortable with P(A and B) find that Bayesian reasoning becomes a lot less intimidating afterward. The Bayesian approach is particularly useful in diagnostic testing scenarios where you're trying to determine the probability of a condition given a test result. Base rate fallacy ruins a lot of intuitive answers here. The formula corrects for that, but only if you input accurate prior probabilities, which brings us back to the data quality problem that underlies everything.