Working Through Problem Solving Scenarios in Real Environments
You set up a fresh environment, run the test cases, and half of them pass while the other half produce errors that don't match the documentation. This is normal. Most people hit this wall within the first week. The core workflow involves three stages: defining the failure mode, isolating the variable that causes it, and building a reproducible path to a fix. The hardest part isn't the third stage. It's the second one. People spend 80% of their time there because they skip the first stage entirely. I've seen engineers jump straight to "fix it" mode when a service starts returning 503 errors under load. They restart containers, scale horizontally, clear caches. None of that helped in the cases I worked through last year because the actual problem was a connection pool exhaustion bug in the ORM layer, not the infrastructure. That distinction matters more than any tool you'll install.
The Method That Actually Works
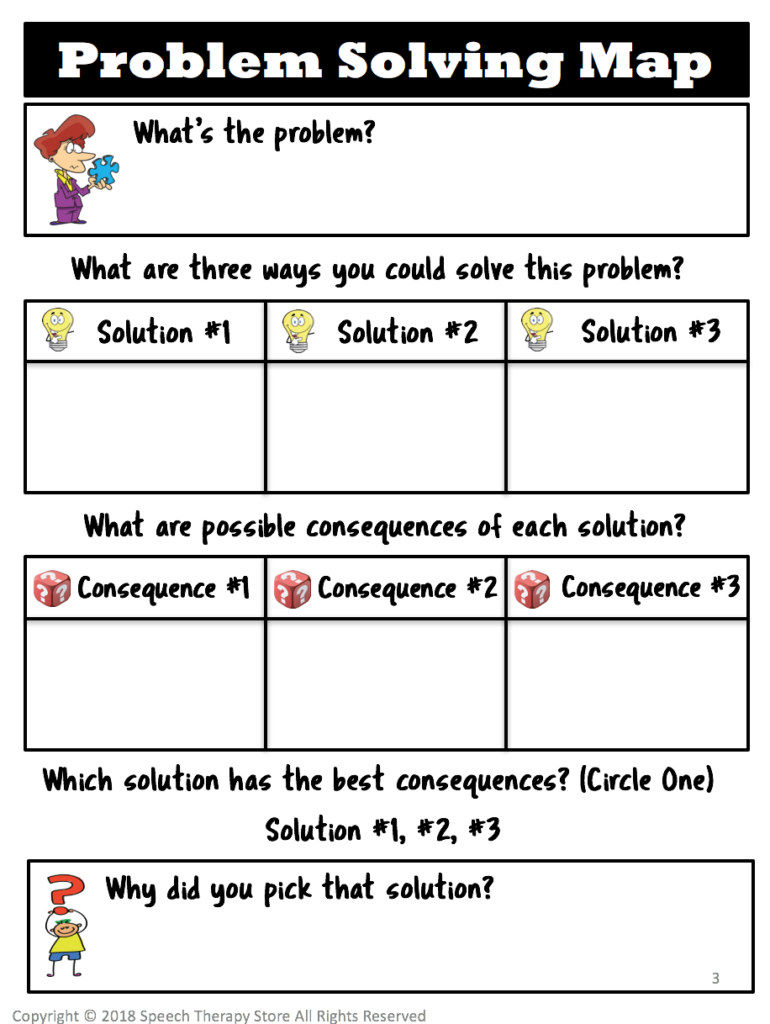
Start by writing down what you expect to happen. Then write down what actually happens. The gap between those two statements is where the problem lives. Most teams skip this and go straight to Googling error messages, which works sometimes but leaves you vulnerable to problems that aren't documented anywhere. Once you've mapped the gap, isolate one variable at a time. Change it. Observe. Don't change three things and hope for the best. I once spent six hours debugging a data pipeline because I updated a library version, changed a config file, and added a retry mechanism all in the same session. The actual bug was a timestamp formatting mismatch in the input data. Everything else was noise.
Tools and Where to Find Them
For lightweight scenarios, the standard debugging utilities in your language of choice handle most cases. Python's pdb and print statements work if you're willing to slow down. Node.js has --inspect for event loop analysis. Java's built-in profiler tools catch thread deadlocks that would otherwise take days to diagnose. When the scenarios get bigger, dedicated tracing frameworks help. Jaeger and Zipkin give you distributed tracing across microservices, which is essential when Problem Solving Scenarios span multiple services. These tools aren't free in terms of setup time. You're looking at roughly 2-3 hours of initial configuration before you get usable output. After that, each trace adds about 50-100ms of overhead to your requests, which matters if you're processing high volumes. There's no single download link that covers every situation because the ecosystem is fragmented. The closest thing to a standard toolkit is a combination of your language's native debuggers, a distributed tracing backend, and a structured logging pipeline. Set these up once and you'll save dozens of hours across future incidents.
Get the Full Details

Pitfalls That Waste Time
The biggest mistake is treating symptoms as problems. A timeout error isn't a problem. It's a symptom of a problem somewhere upstream. If you fix the timeout by increasing the threshold, you haven't solved anything. You've just pushed the failure downstream. Another common trap is over-engineering the solution. I worked on a project where the team built an entire event-driven architecture to handle what turned out to be a database query optimization issue. The real fix was adding an index that took 12 minutes to implement. The event-driven approach would have taken three weeks and introduced a whole new class of failure modes. A counter-intuitive insight: the most complex Problem Solving Scenarios are often the easiest to resolve because they have the most observable symptoms. Simple problems, like a misconfigured environment variable, can consume disproportionate time because there's almost nothing to work with. Learn to distinguish between complexity and ambiguity early on.
When This Approach Completely Fails
Structured problem solving breaks down in environments where you lack visibility. If you're working with proprietary systems that don't expose internals, if your logs are being dropped before they reach your monitoring stack, or if you're debugging a black-box third-party API with no support channel, none of this methodology helps. You're just guessing. In those cases, the practical workaround is building a proxy or middleware layer that sits between your system and the black box. Intercept requests and responses, log everything, and replay problematic interactions in a controlled environment. This adds latency and complexity but gives you the observability you're missing. It's not elegant. It works. I encountered a specific edge case with a payment gateway that returned vague error codes for every failure type. We couldn't tell if a transaction failed due to insufficient funds, fraud flags, or network timeouts. The workaround was creating a test suite that exercised every known failure condition against a staging endpoint, mapping each error code to its root cause through empirical testing. That took about a day of focused work and eliminated the guessing game permanently.
Building a Practical Workflow
Keep a running document of every problem you solve and the path you took to solve it. Not the final answer. The path. The failed attempts matter more than the success because they map the territory for the next person who hits the same wall. I maintain a personal wiki of these scenarios and it's saved me countless hours when similar issues resurface. Review your incident reports quarterly. You'll notice patterns. A particular service breaking under specific conditions. A recurring configuration mistake across teams. These patterns are higher-value than any individual fix because addressing them prevents entire categories of future incidents. The workflow doesn't have to be perfect. It just has to exist. Teams that never document their problem-solving process repeat the same mistakes indefinitely. Teams that document even imperfectly improve with every incident. The difference compounds over months and years.