Getting Project Data Analysis Right Without Losing Your Mind
Most people treat project data analysis as something you run once at the end of a project to fill a report. That approach fails almost every time. The reason is simple: project data is messy, fragmented across tools, and rarely consistent enough for meaningful analysis unless you invest time in cleaning and standardizing it before you even think about pulling insights.
I learned this the hard way on a commercial construction project where we were tracking schedule variance, budget burn rates, change orders, and resource allocation across twelve different work streams. The client wanted a unified dashboard showing projected completion dates and cost forecasts. What we actually had was Primavera P6 schedules, Excel spreadsheets for change orders, a cloud-based accounting system pulling invoice data, and random email threads with subcontractor confirmations that sometimes contradicted what was in the system. Three weeks into trying to merge all of that, I realized the data model itself was the real problem, not the analysis tools.
The Real Work of Project Data Analysis
The first step isn't about picking software. It is about deciding what questions you are actually trying to answer and mapping those questions to the data sources you already have. A lot of teams skip this and jump straight to building dashboards, which just means you end up with a lot of pretty charts that don't answer anything useful.
Start by listing every deliverable, milestone, and cost category your project tracks. Then identify where each piece of data lives. Is it in your ERP? A project management tool? Spreadsheets? Shared drives? Email attachments? Write it down. When I did this for that construction project, I discovered that change order data existed in at least four different formats depending on who submitted it. Some came as PDFs, some as Excel files, some as free-text descriptions in the accounting system. That mismatch between format and source was causing more errors than anything else.
The workaround I used was to create a single intake template with strict field definitions and a mandatory attachment policy for every change order. I also wrote a simple Python script that pulled data from our Primavera export and cross-referenced it against the accounting records to flag any line items that didn't match. It took about two hours to build, and it caught roughly sixty discrepancies in the first pass that would have otherwise gone into the final report unnoticed. The script was crude, but it saved us from presenting incomplete data to the client.
Data normalization is where most project data analysis projects stall. You have to decide whether a cost code in one system maps to the same cost code in another. You have to handle dates that are sometimes in MM/DD/YYYY and sometimes in DD/MM/YYYY depending on who entered them. You have to deal with resources that are listed under different names across departments. These are not edge cases. They are the baseline condition of any project that involves more than one team or one software tool.
One counter-intuitive thing I have noticed is that the people who seem to struggle most with project data analysis are the ones who know the software best. They get so focused on using advanced features in their analytics platform that they forget the quality of the output is entirely dependent on the quality of the input. A clean model with garbage data will always produce garbage results, and nobody spots it until the stakeholder asks a question the chart can't answer.
I recently worked with a team trying to use Power BI to analyze project performance metrics across multiple engineering departments. They spent three weeks building a beautiful report with custom visuals and drill-through pages. Then someone asked what the actual variance was between budgeted and actual labor costs by phase, and the report couldn't answer it because the labor cost fields used different naming conventions across departments. Two of the departments recorded overtime as a separate line item. Another department folded overtime into the base rate. The tool couldn't distinguish between them without a mapping layer that simply didn't exist. We ended up spending another two weeks just reconciling the source data before the dashboard was usable.
Practical Steps for Doing This Kind of Work
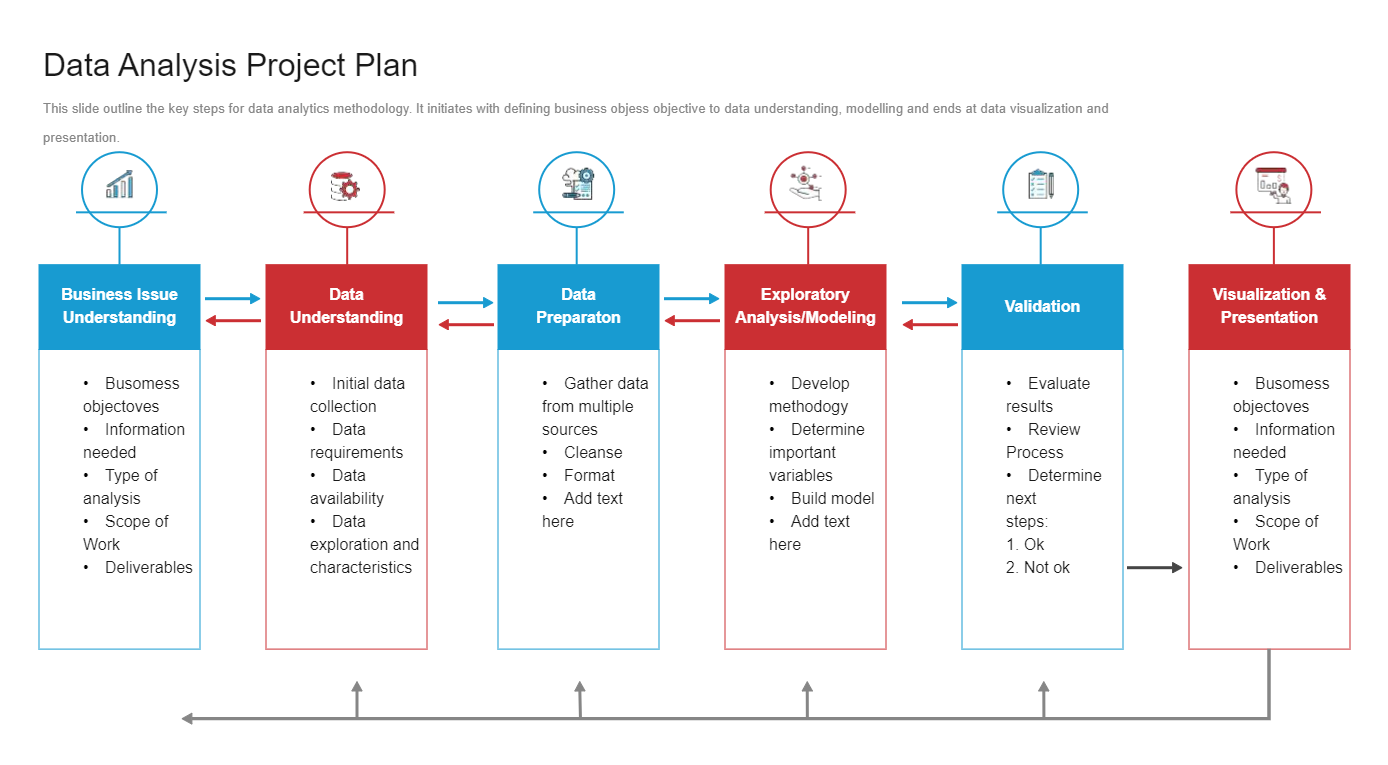
The process breaks down into stages that are less glamorous than they sound in training materials but more reliable if you respect the sequence.
Define the scope. What decisions will this analysis inform? If you cannot name three specific decisions, your analysis will drift and you will collect more data than you need. Scope creep in data analysis projects usually comes from stakeholders who say yes to everything because they do not want to appear unsupportive. They then get disappointed when the final deliverable is too broad to be actionable.
Inventory your sources. List every system, file, database, and person who holds relevant data. Don't guess. Actually check. The list I made for that construction project ended up being longer than I expected because the project controls team had their own spreadsheet that tracked something the main PM tool didn't. That spreadsheet turned out to be the only accurate record of actual costs. The Primavera numbers were estimates, not true-ups.
Build a data model before you build visualizations. This means creating tables that link the different sources together with a common key, like a project ID or a cost code. If your data doesn't have a reliable key, create one. It is easier to add an identifier now than to figure out why three reports are showing different totals for the same month.
Clean the data manually where automation fails. There is no way around this. Automated cleaning scripts will miss context-specific issues that a human eye catches instantly. When I was consolidating that change order data, the script flagged about forty percent of the entries correctly, but the remaining sixty percent needed human review because things like "miscellaneous site expenses" appeared under different cost codes depending on the superintendent who logged them.
Validate with a small sample before scaling up. Run your entire pipeline on a single phase or a single month of data and verify the numbers against the source. If the math checks out, then apply it to the full dataset. This step usually takes far less time than the alternatives and it prevents you from discovering errors after you have already built a massive report.
I should note that project data analysis has real limitations that people in this space rarely discuss honestly. It works well for structured data that follows consistent rules. It breaks down when your project relies heavily on informal communication, tribal knowledge, or systems that were never designed to integrate. If your organization does not have basic data governance, no amount of analysis software will fix the underlying problem. You will just get a more sophisticated way of producing unreliable numbers.
Another downside is that project data analysis assumes historical data is available and accurate. That is not always true. In government contracting and public-sector projects, funding changes mid-year, scope gets redefined by legislative action, and prior-period data gets revised after the fact. Your analysis will reflect whatever was recorded at the time, which may not reflect reality. I have seen teams present monthly burn rate analyses that were technically correct based on the recorded data but completely misleading because the project had already been authorized for a supplemental appropriation that nobody had entered into the system yet.
For smaller projects or teams without dedicated data engineering support, I usually recommend starting with something simpler than a full dashboard build. A well-structured Excel workbook with defined ranges, consistent date formats, and a separate reconciliation sheet will often serve you better than an expensive BI tool that requires ongoing maintenance. The investment in discipline is lower and the results are equally valid.
When I do recommend software, I look at the actual integration requirements first. If your project management tool, financial system, and reporting tool all support API access, a data pipeline is worth building. If they are all on different platforms with limited export options, you are better off spending your time on manual consolidation and clear documentation rather than chasing real-time automation that will likely fail when one of the sources changes its schema.
Gallery Project Data Analysis
Data Analysis Project Examples - PDF| ProjectPro
How to Build a Data Analysis Project: A Step-by-Step Guide
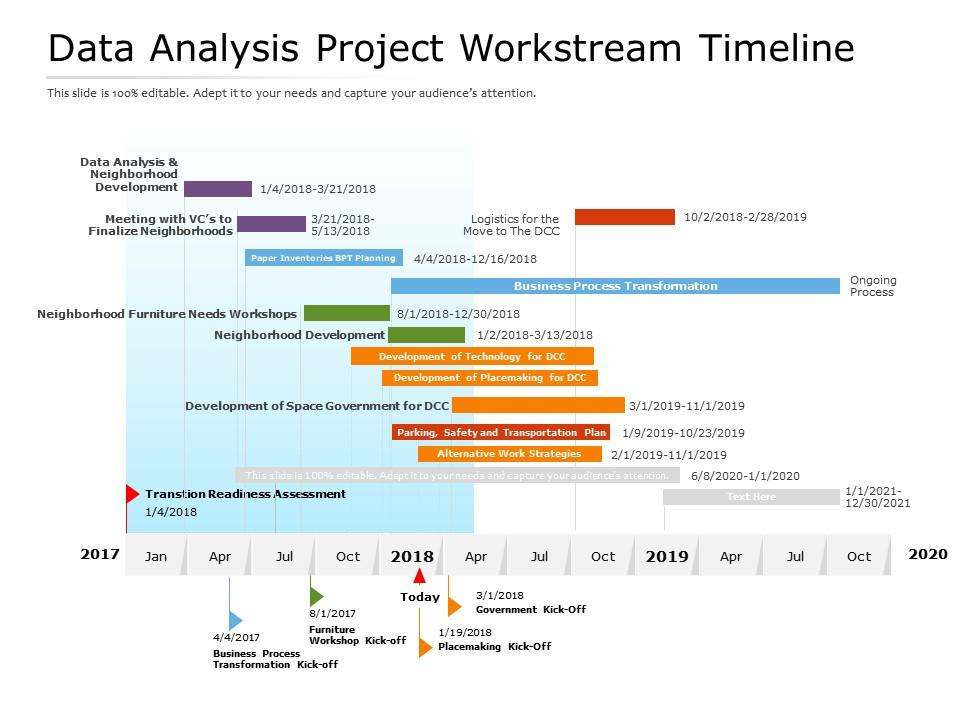
Data Analysis Project Workstream Timeline | Presentation Graphics | PowerPoint PPT Presentation ...
Free Project Data Analysis Templates For Google Sheets And Microsoft Excel - Slidesdocs
Power BI Projects - Data Analysis & Visualization