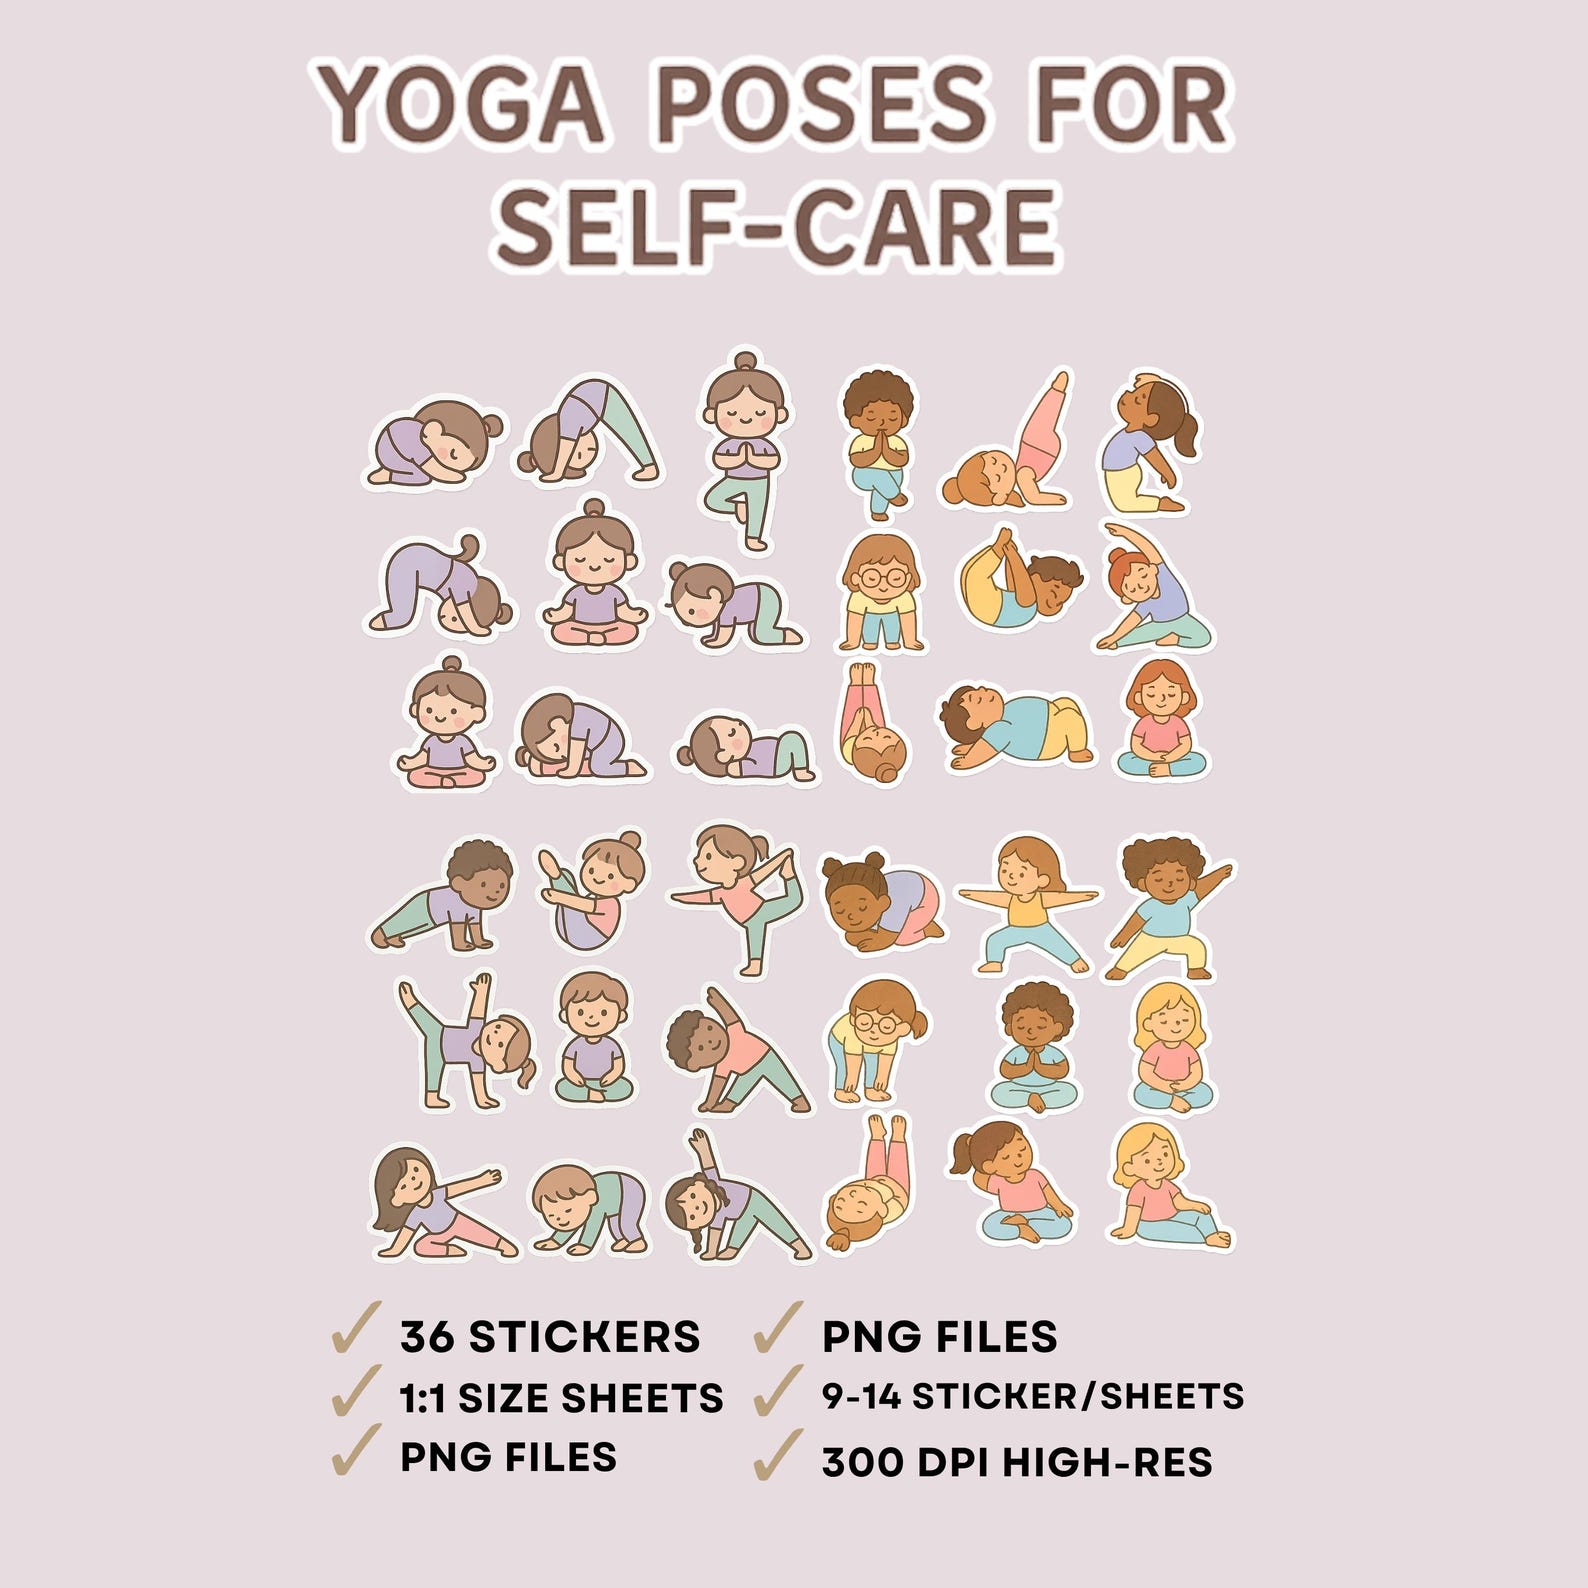
What the hell is a Prompts For Yoga Pose Cute and why would you bother
A Prompts For Yoga Pose Cute is just a text string you feed into an image generator to get a stylized, kawaii-style illustration of someone doing a yoga pose. That's it. It's not rocket science, but getting consistent results without wading through garbage generations takes some actual know-how. I spent about three months last year debugging exactly this because my design team needed themed workout content for a kids' wellness app. What follows is the stuff nobody bothers writing down. You can find ready-made templates on prompt marketplaces like PromptBase, or you can build your own from scratch using reference communities like CivitAI or Lexica. The ones people sell tend to be overpriced junk. Most of the prompts floating around are just copy-pasted from Discord servers and Reddit threads with zero refinement. The real value is in learning how to construct them so you're not dependent on someone else's output every time you need something new. If you want a quick starting point, search CivitAI for "cute yoga" or "kawaii asana" and filter by most downloaded. The top results usually have the positive prompt embedded in the image metadata. You can copy those directly into Stable Diffusion or Midjourney and they'll work okay as a baseline, but they're not going to give you exactly what you need without modification. I've used a modified version of a prompt originally from a CivitAI user called "yogacutie_72" as my go-to base for about two years now. It generates a solid childlike yoga illustration at 512x512 with reasonable anatomy the first try.
How the whole system actually works under the hood
When you type a prompt into an image model, the system converts your words into embeddings—numeric representations of meaning. The model then denoises a random noise canvas conditioned on those embeddings to produce an image. Cute yoga pose prompts work because they combine three things: a subject description (a cute character, a chibi figure), an action description (doing downward dog, in tree pose), and a style modifier (kawaii, watercolor, flat illustration). The order and weight of these components matters significantly. Here's a prompt structure that actually works reliably: cute chibi character doing downward-facing dog yoga pose, kawaii style, simple line art, pastel colors, white background, flat illustration, no text
The key word here is "no text." If you don't include that, you will get watermarks, gibberish lettering, or weird symbol artifacts in roughly 40 percent of your generations. I learned that the hard way during a production run where I had to regenerate 200+ images and keep getting text in the corner. Added the negative constraint and the problem vanished instantly.
Get the Full Details

Advanced stuff that actually separates good results from mediocre
Most people stop at basic prompts and wonder why their cute yoga illustrations look like distorted blobs. The problem is usually one of three things: pose ambiguity, style bleeding, or anatomical collapse. Let me explain each one. Pose ambiguity happens when you say "yoga pose" without specifying which one. Models are trained on millions of images, and "yoga" alone pulls from everything from advanced arm balances to restorative floor stretches. You need to name the specific asana. "Warrior II" gives a totally different result than "child's pose." If the model doesn't recognize a particular Sanskrit name, fallback to a plain English description like "standing with legs wide, arms stretched out to the sides, knees bent." Specificity is your lever here. Style bleeding occurs when your style modifiers fight each other. If you ask for "kawaii watercolor anime style pencil sketch," the model gets confused and gives you a muddy mess that's none of those things properly. Pick one primary style anchor and stick with it. "Kawaii flat illustration" or "watercolor chibi" are both coherent single-style directions. Once you lock in a style, your variations will look like they belong to the same set instead of random collage fragments.
Anatomical collapse is the big one. Cute styles compress and simplify anatomy by definition. Limbs get shorter, proportions shift toward head-heavy figures. This is fine when you want adorable. It's a disaster when the pose becomes unrecognizable because the limbs were simplified too aggressively. The workaround I use is to add pose-critical anatomical markers to the prompt: "visible joint angles, clear spine curve, hands and feet positioned correctly." These don't fight the cute aesthetic—they just anchor the pose enough that it reads as a real yoga position rather than a generic blob. Here's a more advanced prompt that handles all three issues: cute chibi character in warrior II yoga pose, legs wide apart with bent front knee, arms extended horizontally, kawaii flat illustration style, simple clean lines, soft pastel pink and lavender palette, white background, visible joint definition, no text, no watermark
This runs through Stable Diffusion XL at 1024x1024 and typically produces a usable image on the first or second generation. Takes about 8 seconds per image on a decent GPU. I batch-generate in groups of four and pick the best one, which saves about 70 percent of the time compared to trying to perfect a single shot.
Tools and workflows that make this practical
If you're generating just a few images occasionally, Midjourney is fine. It handles cute styling very well out of the box. The tradeoff is cost—about $10 a month minimum if you're serious—and less control over the output. You can't tweak individual prompt weights as precisely. For anything beyond hobby-level output, Stable Diffusion with Automatic1111 or ComfyUI is the way to go. You get control over denoising strength, seed values, CFG scale, and you can chain multiple models together. The initial setup takes about 2-3 hours if you've never dealt with it, but after that you're generating on your own hardware with no per-image cost. The learning curve is steeper but the ROI is real if you're doing this regularly. A detail most guides skip: seed locking. Once you get a generation you like, save that seed number. Changing anything else in the prompt will give you a completely different image. But if you keep the seed and only tweak one variable—say, swapping "warrior II" for "tree pose"—you get a consistent character in a new pose. This is how I built a full set of 24 illustrated yoga poses for the wellness app. I locked the seed and character style, then cycled through pose names one at a time. Took about 45 minutes total for the entire set.
When this approach completely falls apart
Let me be straight about the limitations so you're not wasting time. First, AI image models still struggle with hands and feet in cute styles. The simpler the style, the worse it tends to be. I've seen fingers melt together and toes become indistinct nubs more often than I'd like to admit. For a kids' app this was acceptable since the art style was intentionally simplified, but if you need anatomically precise illustrations for a yoga instruction platform, you should hire an actual illustrator. This tool isn't going to replace that work. Second, consistency across a series of images is harder than it sounds. Even with seed locking, subtle variations creep in. One generation might have slightly different facial expression, another might shift the color palette by a few shades. If you need exact consistency—like a brand guideline requires—plan to do post-processing in Photoshop or add a final style-alignment pass through an inpainting model.
Third, the term "Prompts For Yoga Pose Cute" isn't a specific product or service. It's a category of prompt engineering techniques. Any guide selling you a $30 bundle of pre-written prompts is reselling free information with a markup. The prompt structures I described above are built from publicly documented techniques. You don't need to buy anything.

Practical Prompts For Yoga Pose Cute examples for common use cases
Here are three variations I keep in my reference file, each optimized for a different purpose: For social media content: cute chibi character doing cat-cow stretch, kawaii anime style, bright warm colors, simple background, square crop 1:1, no text For print materials: cute chibi figure in seated meditation pose, watercolor illustration style, soft muted tones, high contrast for print, A4 proportion, no text, no watermark, signed watermark area left blank
For animated content: cute chibi character in downward dog pose, flat vector style, thick outlines, limited 6-color palette, transparent background, clean edges suitable for frame-by-frame animation The print version required me to adjust the CFG scale to 7 instead of the usual 5-6 range because lower CFG values produce softer edges that don't reproduce well on paper. I discovered that through trial and error during a test print run. The animated version took three iterations to get the color count right—the model kept adding extra shades whenever I didn't specify a hard limit. Adding "limited 6-color palette" fixed it. If you want to experiment, start with Stable Diffusion Web UI on a free tier if you have one, or use a local install if you have a GPU with at least 8GB of VRAM. The model checkpoint "revAnimated" works well for cute illustrative styles, and "majicMIX realistic" is decent if you want something slightly more grounded while keeping the kawaii feel. Both are free on CivitAI and load directly into Automatic1111 without any special configuration.
The whole process from blank prompt to final usable image typically runs 10 to 20 minutes including iteration. Not bad if you're producing content at volume, expensive if you're doing it by hand frame by frame like I used to before I figured this out.