How Proof Of Proof By Induction Actually Works
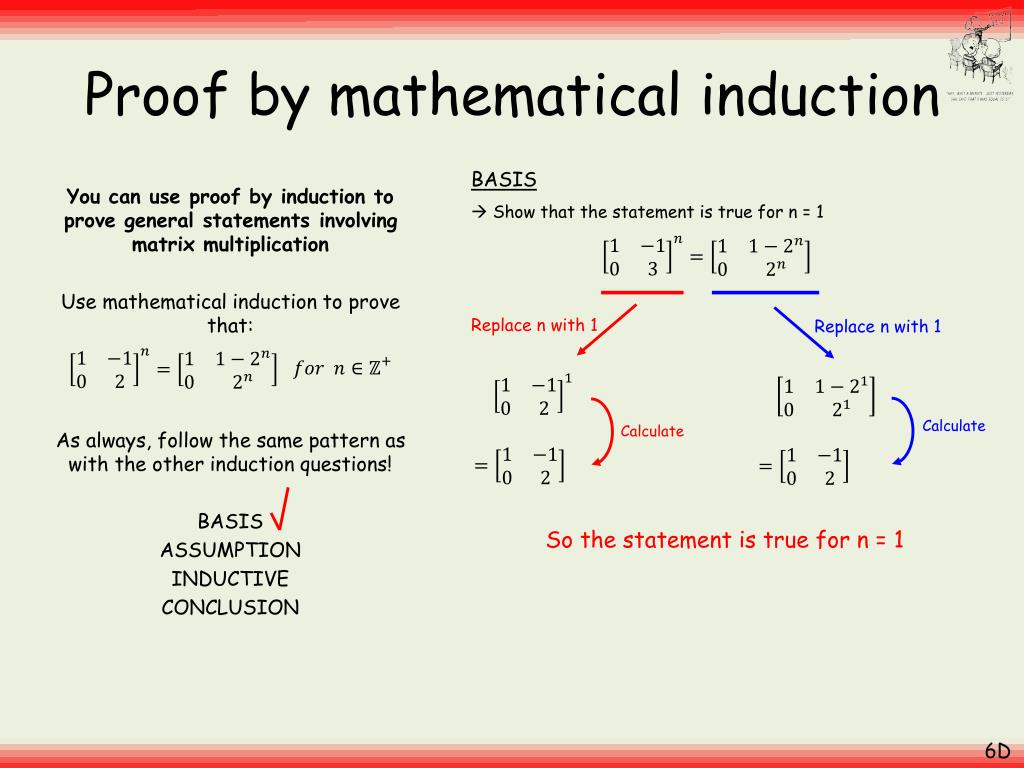
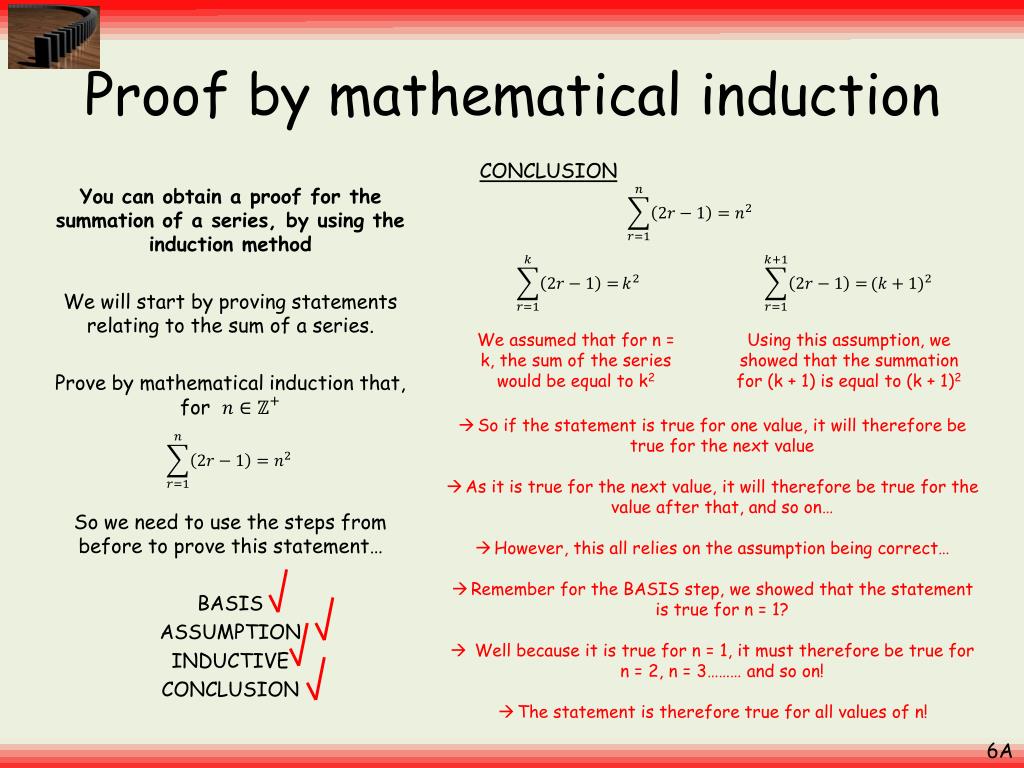
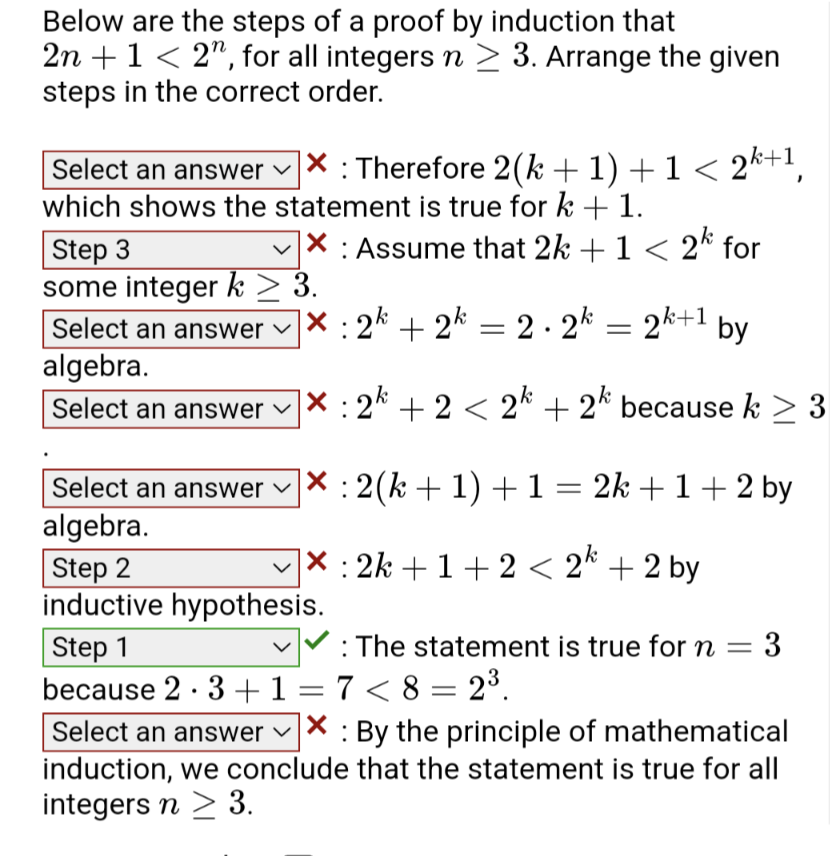
Proof by induction is a technique for establishing that a proposition holds for every natural number by reducing an infinite task to two finite checks. The first check verifies the base case, usually n equals 0 or n equals 1. The second check establishes the inductive step: assuming the proposition is true for some arbitrary k, you prove it remains true for k plus 1. This framework is standard across discrete math, computer science, and algorithm analysis. What people often miss is how the assumption layer works in practice, and where the method quietly breaks down. The inductive hypothesis is not a claim about truth. It is a conditional statement. You are not proving P(k) is true, you are proving that if P(k) is true, then P(k plus 1) must also be true. That distinction matters more than most textbooks suggest because conflating the two is how half the botched proofs on exam papers happen. Once that logic is clean, chaining it across all natural numbers follows automatically.
Proof Of Proof By Induction in Practice
I use this technique most often when verifying recurrence relations for algorithms. A typical example is proving that a recursive function computing a sum of the first n integers actually returns n times n plus 1 divided by 2. The base case is trivial. The inductive step is algebra. What makes it real work is reading the result correctly and not mistaking a pattern for a proof. Here is the structure you follow when writing one of these out: Step 1: State the proposition P(n) clearly. Write it in full. Do not use shorthand.
Step 2: Verify the base case. Pick the smallest n in your domain. Compute it directly. Step 3: Assume P(k). Write down exactly what P(k) says under that assumption. Step 4: Manipulate P(k plus 1) until it reduces to the expression from Step 3. Close the gap with algebra, not hand-waving.
Get the Full Details
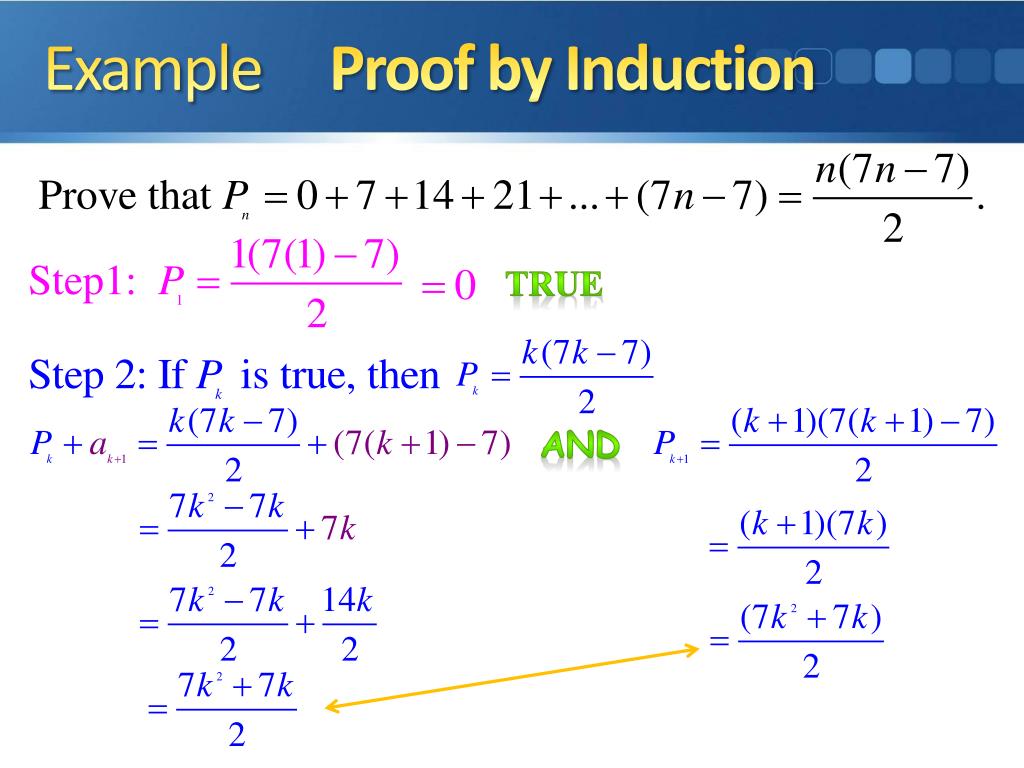
Step 5: Conclude. The two steps together cover all natural numbers above the base case. I once spent two days debugging a proof that looked correct until I noticed the inductive step relied on subtracting terms that were undefined at k equals zero. The base case was n equals 1, but the recurrence I was using required the proposition to hold at n equals 0 to perform the substitution. That mismatch invalidated the entire chain. The workaround was simple once I caught it, but the catch itself was hidden because the algebra looked clean. I switched the base case to n equals 0 and rewrote the inductive step to handle the subtraction explicitly. It added two lines to the proof and removed a silent failure mode. This kind of boundary issue comes up regularly when recurrences shift indices, so always verify that every term used in the inductive step is defined within your assumed domain before you commit to the proof. There are variants of this method worth knowing about. Strong induction replaces the single-k assumption with a hypothesis that P holds for all values up to k. This is necessary when the inductive step depends on more than the immediately preceding case. Nested induction stacks induction inside another proof by induction, which shows up in double recursions and certain complexity bounds. Well-ordering based proofs are structurally equivalent to induction but reframe the argument through the minimal counterexample principle, which sometimes clarifies edge cases that feel awkward under the standard format.
When This Method Is Not Useful
Induction fails or becomes impractical when the proposition does not naturally decompose across a well-ordered domain like the natural numbers. It is not suited for continuous domains without reformulation into a discrete lattice or an epsilon-based argument. It also struggles with propositions that involve unbounded existential quantifiers, where the construction required for the inductive step cannot be made uniform. In those cases, direct construction, contradiction, or a model-theoretic approach is usually faster. I have seen people force induction into problems it does not fit just to follow a template, and the resulting proofs are longer and less transparent than the alternatives.
Common Pitfalls
Skipping the base case. The inductive step can be valid while the conclusion is still false because nothing anchors the chain. Empty domain induction looks correct on paper and produces wrong results in practice. Assuming what needs to be proven. This appears as circular reasoning disguised as the inductive hypothesis. The hypothesis must be strictly weaker than the target conclusion for the current step. Overgeneralizing the inductive step. Using a substitution that is only valid for large k while claiming it covers all k is a frequent error in recurrence proofs. Always track the domain of each manipulation.

Misidentifying the recursion structure. If the problem has multiple interdependent sequences, a single-statement induction is insufficient. You need a joint induction over both propositions simultaneously, otherwise the proof stalls at the first coupled step.
Verification Tips
Run the proposition against small values of n before attempting the general proof. If it fails for n equals 2 or n equals 3, the inductive step will likely expose it immediately. Writing out three or four small cases usually takes less than five minutes and prevents hours of chasing a false lead. Check that the inductive step does not implicitly assume the result for k plus 2 or beyond. If it does, the proof is circular. You can catch this by tracking every occurrence of the proposition index through the derivation line by line.
Related Techniques
Structural induction extends the same logic to recursively defined data structures like trees and lists. Transfinite induction generalizes it beyond the natural numbers into ordinal spaces, which is relevant in set theory and certain areas of mathematical logic. Course-of-values induction is the formal name for strong induction and is often the version used in algorithm correctness proofs where earlier values are needed in non-contiguous ways. These variants share the same core mechanism: reduce an infinite verification task to a finite base and a uniform transition rule. The differences lie in the ordering relation used to define the successor step.