Why your uncertainty budgets keep falling apart
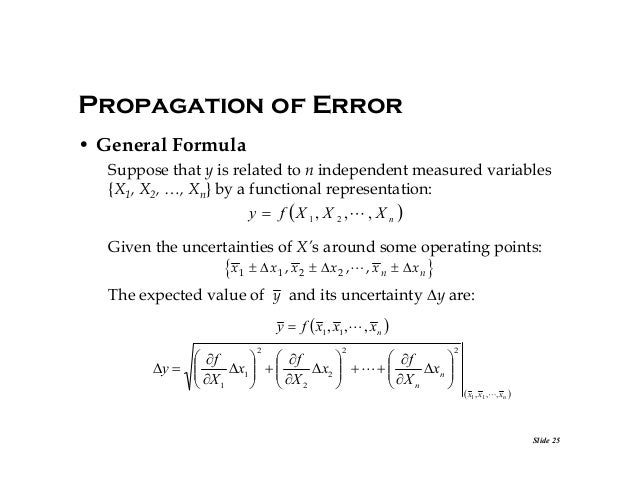
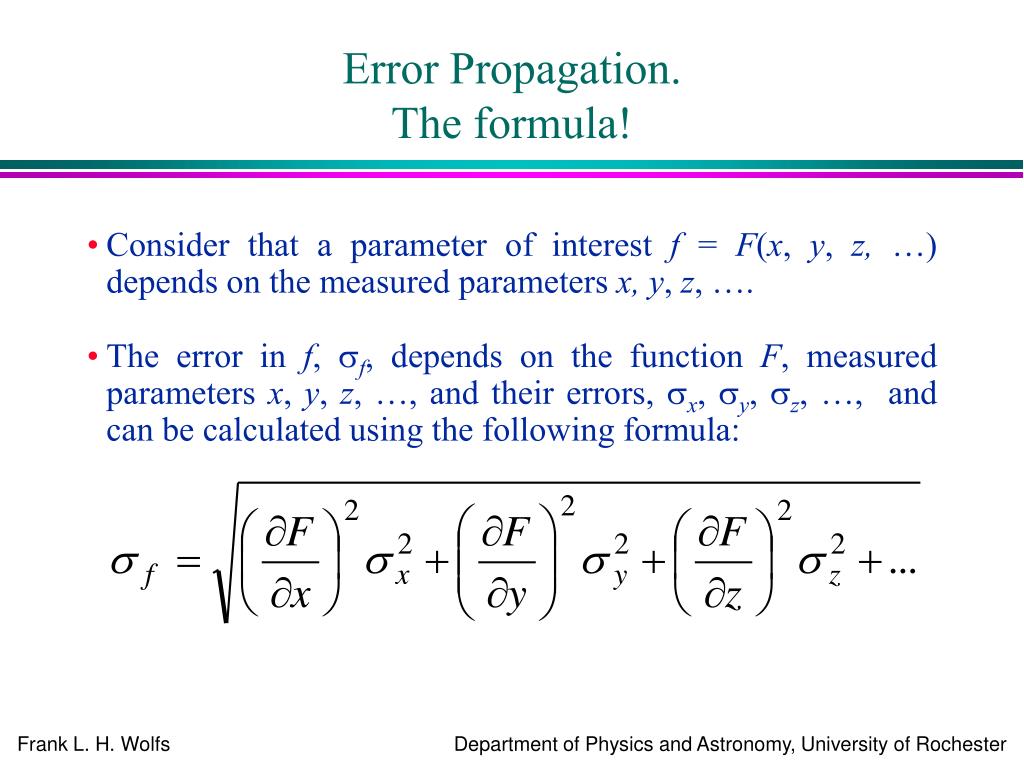
I ran a measurement campaign last year where we were combining five separate sensor readings into a single derived quantity. Each sensor had its own calibrated uncertainty. The propagated error came out to about twelve percent relative uncertainty. Then a reviewer pointed out we had used the first-order approximation everywhere, including for a term that was squared in the calculation. The real uncertainty was closer to eighteen percent. That was a painful lesson in when the standard propagation of error formula stops being trustworthy. The propagation of error formula is the tool you reach for when you need to estimate how uncertainty in measured quantities spreads through a mathematical function. It's not magic. It's calculus applied to uncertainty, usually in the form of partial derivatives. For a function f(x, y, z...) with uncorrelated input uncertainties, the combined variance is the sum of each partial derivative squared times the corresponding input variance. If your inputs are correlated, you add covariance terms. That's basically it. The rest is execution.
Propagation Of Error Formula
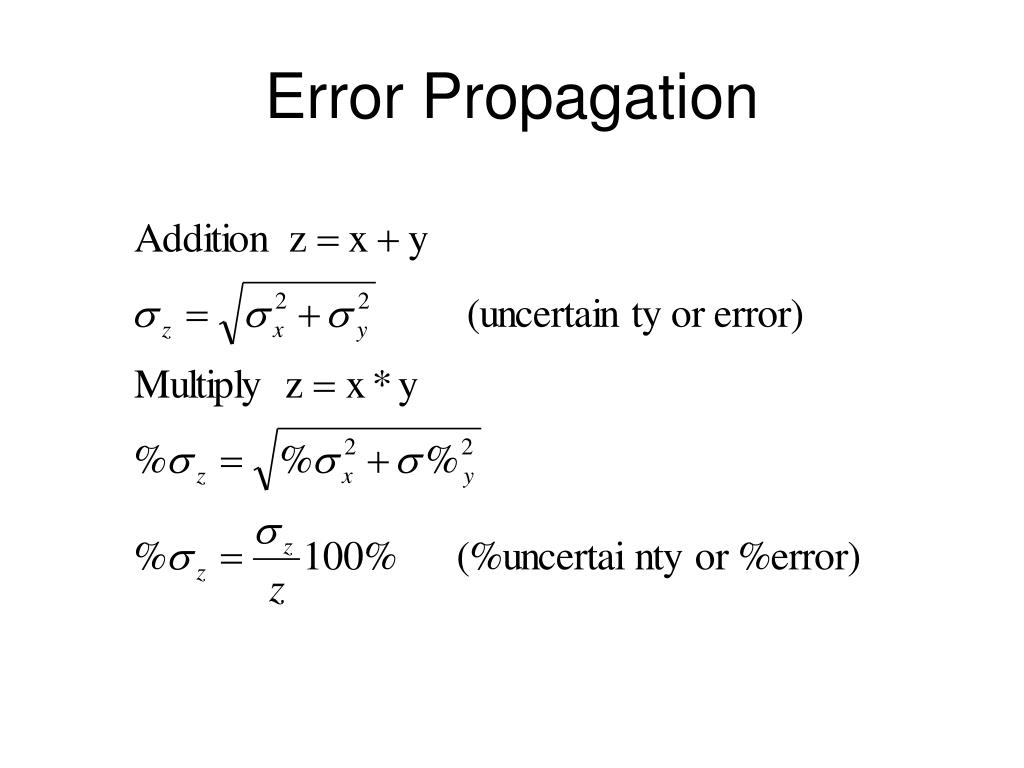
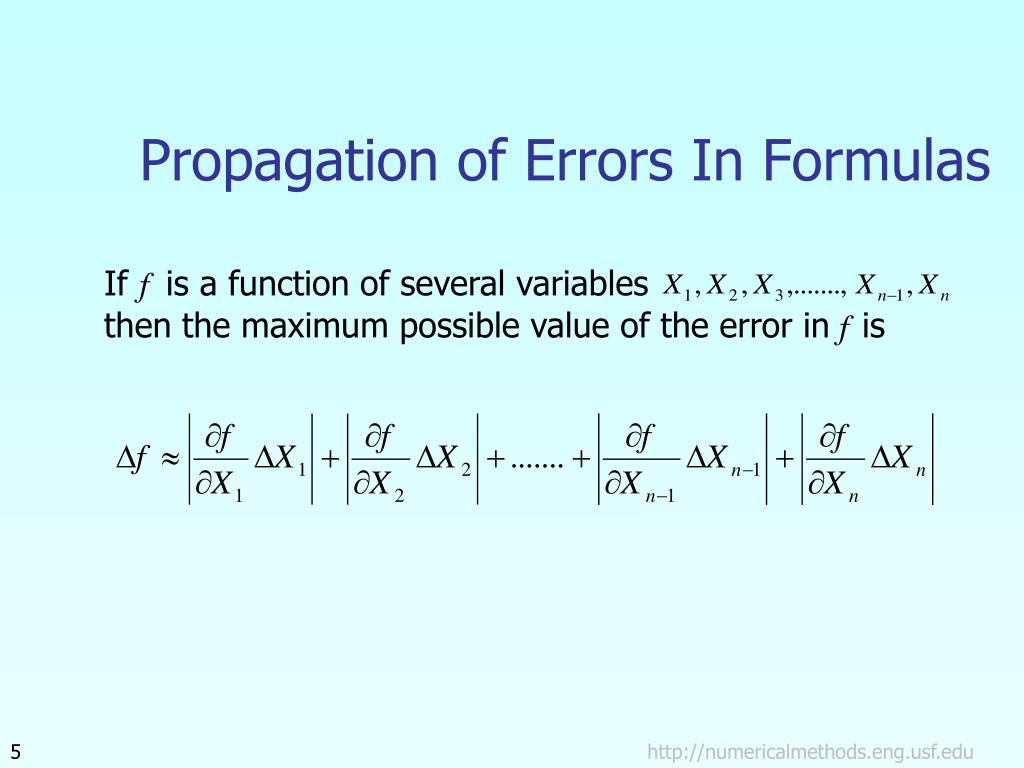
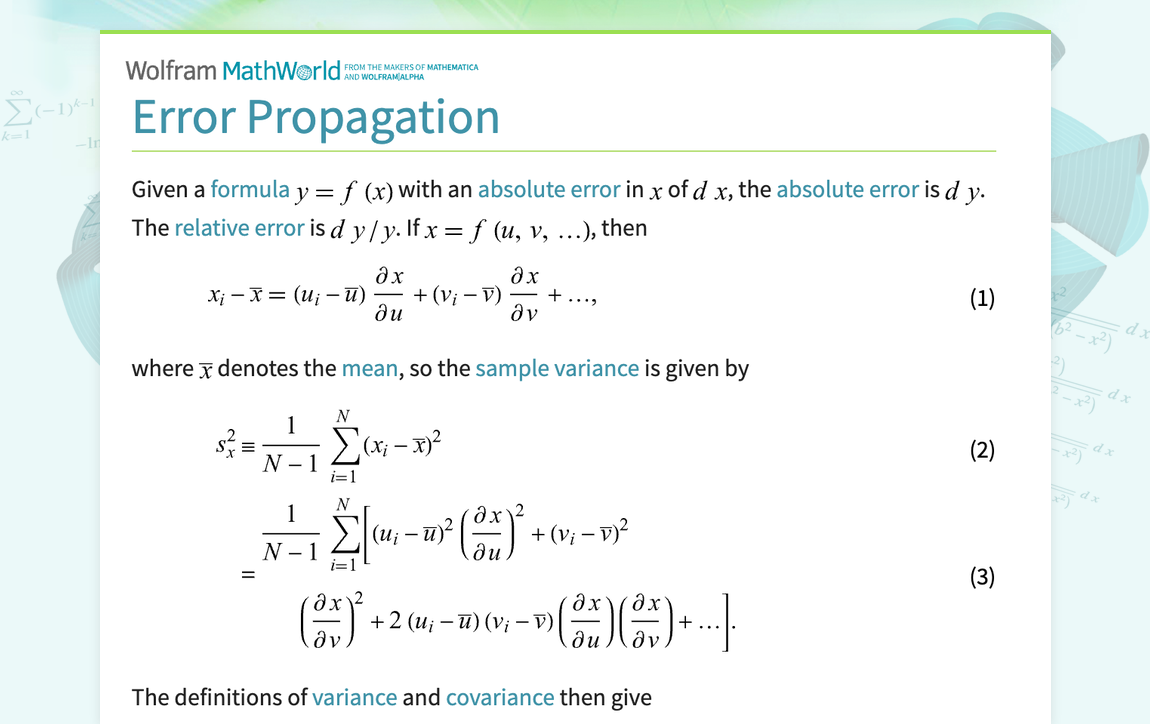
The general form looks like this: u_f² = (f/x_i)² · u_xi² + 2·(f/x_i)(f/x_j)·cov(x_i, x_j). When variables are independent, the covariance terms drop out and it simplifies to the root-sum-square of sensitivity coefficients times individual uncertainties. I usually write it as u_f = sqrt((f/x_i)² · u_xi²) for quick hand calculations. For correlated variables, the covariance terms can actually dominate, sometimes reversing the sign of the contribution. Here's a concrete example that comes up constantly. Say you're calculating power from voltage and resistance: P = V²/R. The uncertainty in V propagates with a sensitivity coefficient of 2V/R, and the uncertainty in R propagates with a sensitivity coefficient of -V²/R². If V has two percent uncertainty and R has one percent, the power uncertainty is roughly sqrt((2×2)² + (1)²) = sqrt(16 + 1) 4.1 percent. The voltage uncertainty gets doubled because it's squared in the equation. That's why small uncertainties in high-power terms blow up fast. One thing beginners consistently miss is that the propagation formula assumes linearity around the operating point. If your function is highly nonlinear over the range of uncertainty, the first-order Taylor expansion gives you a biased estimate. The second-order terms matter. I've seen people apply the standard formula to logarithmic and exponential relationships without checking the curvature. The results looked reasonable at first glance but were systematically wrong by fifteen to twenty percent.
Another counter-intuitive point: correlated inputs don't always make things worse. If two variables are positively correlated and their sensitivity coefficients have opposite signs, the covariance term subtracts from the total variance. I ran into this when measuring flow rate through a differential pressure sensor where both pressure taps shared a common temperature reference. The temperature drift induced correlated errors in both readings, but because the flow equation subtracts them, the correlation actually reduced the propagated uncertainty by about thirty percent compared to assuming independence. Ignoring that correlation would have given you a pessimistic uncertainty budget that looked safe but cost you instrument upgrade budget you didn't need. When I need to handle complicated functions or correlated inputs, I don't trust myself to do the derivatives by hand. I use Monte Carlo propagation instead. You sample from the input distributions, evaluate the function at each sample point, and build the output distribution empirically. It takes longer—maybe ten to fifteen minutes per iteration instead of seconds for the analytical formula—but it captures nonlinear effects and non-Gaussian outputs correctly. For a quick check against the analytical result, I run about ten thousand simulations. If the Monte Carlo standard deviation differs from the propagation formula result by more than five percent, I know the first-order approximation is breaking down and I should either add second-order terms or switch to simulation entirely. The main weakness of the propagation of error formula is that it only gives you a variance estimate. It tells you nothing about the shape of the output distribution. If your inputs are uniform or rectangular, the output isn't necessarily normal, even after propagation. Coverage factors based on the normal distribution become unreliable, and confidence intervals can be off by a significant margin. I've seen this bite people in calibration labs where rectangular uncertainty components from manufacturer specifications get fed through nonlinear functions, producing skewed output distributions that the standard GUM framework handles poorly.
Get the Full Details
Also, the formula breaks down when input uncertainties are large relative to the scale of the variable. The rule of thumb I use is that relative uncertainties should stay below about ten percent for the first-order approximation to hold without significant bias. Beyond that, the higher-order terms accumulate and the propagated uncertainty becomes systematically underestimated. There's no clean cutoff, and it depends heavily on the function shape, but ten percent is where I start checking with a second-order expansion or Monte Carlo. If your problem involves discrete data or you're working with experimental replicates rather than certified reference values, propagation of error is still applicable but you need to be careful about how you estimate the input variances. Sample standard deviations from small datasets underestimate the true population variance. A sample of ten measurements gives you a standard error on the standard deviation of roughly seven percent, which then propagates further. I usually inflate the input uncertainty by a coverage factor that accounts for the degrees of freedom, or I use the expanded uncertainty directly if that's what the calibration certificate provides. For most routine laboratory work, the first-order propagation formula is sufficient and far faster than alternatives. Just remember to check the linearity assumption, account for correlations when they exist, and verify with simulation when the math starts looking suspicious. The formula itself is straightforward. Getting the inputs right is where most people lose points.