The thing nobody tells you about content analysis
I ran a content analysis project last year for a media company that wanted to track how their competitors framed climate policy across 400 articles. It took me three weeks of actual coding work, not counting the setup time. Most people think content analysis is just reading things and making spreadsheets. That is wrong. It is a structured coding exercise that can get messy fast if you don't set up your framework before you open a single document. Let me start with the workflow because that is where everything lives or dies. You build a codebook. That is your dictionary of themes, categories, and rules for what counts as what. I once built a 47-code codebook for a political communication study, and by code 38 I realized two of my earlier codes were essentially duplicates. You catch that early or you waste days recoding. Here is the method. Define your research question first. Then develop your coding categories based on that question, not based on whatever patterns jump out at you after reading fifteen documents. That is the biggest mistake I see. People read first, build the framework later. They end up doing manual content analysis, which means open coding each document, then axial coding to connect categories, then selective coding to find the core theme. It works for qualitative work but it destroys throughput on anything over about fifty documents. Quantitative content analysis scales much better because you can automate the counting once your categories are locked down.
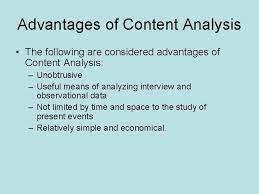
I use a hybrid approach for most projects. I do a small pilot with maybe twenty documents, manually coded, to stress-test the codebook. Then I switch to structured analysis with a tool like NVivo or even a well-built Excel spreadsheet if the data isn't massive. The pilot phase usually takes me about eight to ten hours for a standard project. After that, the actual coding runs much faster. The real advantage of content analysis is that it gives you something you can point at and defend. When someone says your finding is subjective, you can show them the codebook with inter-coder reliability scores. If your Cohen's kappa comes back above 0.80, you have quantitative backing for what you saw in the text. That matters in academic work and in boardroom presentations equally. There is also the matter of longitudinal comparison. Once you have a stable codebook, you can run the same analysis on data from six months ago and compare results directly. I did this for a brand perception study where we tracked sentiment shifts across quarterly campaigns. The before and after numbers were actionable in a way that casual reading never would be.
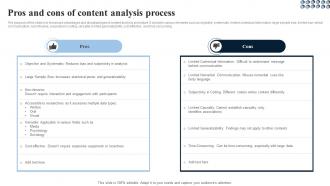
Now the downsides, and they are real. Content analysis reduces rich meaning to categories. A sarcastic tweet about a politician gets coded as negative sentiment, but the actual meaning is quite different from genuine negative opinion. You lose the nuance of tone, context, and cultural reference unless you build elaborate rules for it, and then your codebook becomes unmanageable. I spent two weeks trying to create a reliable code for irony in product reviews. It failed. Inter-coder reliability bottomed out at 0.31. I dropped irony as a category and used a separate qualitative review step for those edge cases instead. Another issue is that your categories are only as good as your assumptions going in. If you miss an emerging theme, you will either force it into an existing code or overlook it entirely. I ran into this with a healthcare content project where patients were using slang terms for medications that didn't appear in any medical literature. My initial codebook had no category for layperson drug names. I had to go back and add three new codes after I had already coded about sixty documents, which meant recoding everything. A simple reverse search through my exported data saved me from having to re-read every document manually. Scaling is expensive too. Manual coding at a professional rate runs roughly one to two hours per hundred documents depending on complexity. For larger corpora you need automation or a team, and both introduce their own problems. Automated text analysis tools like Python libraries for NLP can handle volume, but they require programming knowledge and they struggle with domain-specific language unless you train them properly.
Get the Full Details
Here is a counter-intuitive point that most guides skip. Your sample size matters less than your coding consistency. I have seen studies with a hundred documents and near-perfect reliability produce more credible findings than studies with five thousand documents and poor codebook design. Build a tight codebook with clear definitions and examples, get two coders to test it until kappa is above 0.75, and then proceed. That is more important than throwing raw volume at the problem. Another practical tip that saves real time. Export your coded data into a pivot table format as soon as you finish a batch. I use a simple CSV export from NVivo and then build pivot tables in Excel to cross-tabulate codes against metadata fields like date, source type, and author. This reveals patterns faster than any qualitative summary ever could. For example, I once discovered that a particular frame appeared exclusively in evening news broadcasts but never in morning shows. That finding would have taken weeks to surface through reading alone. If your project involves large-scale document sets, consider starting with a semi-automated approach. Train a basic classifier in a tool like RapidMiner or even a custom Python script with scikit-learn, then use it to pre-sort documents into your categories. You still manually review and correct the assignments, but you are working with a much smaller set of uncertain cases rather than reading every document from scratch. This typically cuts coding time by about sixty percent on datasets over five hundred documents.
The output of content analysis is usually a frequency table, a cross-tabulation, or a thematic map depending on your question. Report your reliability metrics alongside your findings. Without inter-coder agreement scores, your analysis is just an opinion with extra steps. Peer reviewers and stakeholders both expect to see that number. For anyone starting out, I recommend beginning with a modest project of about fifty to one hundred documents using a codebook with no more than fifteen codes. That is enough to learn the mechanics without drowning in complexity. Practice comparing your coding against a colleague's coding and discuss disagreements until your agreement stabilizes. Once you can reliably reproduce your own coding on a second pass, you are ready for larger projects. There is no free software that handles this perfectly. Open-source options like Taguette exist but they lack some of the reporting features that matter for publication or client deliverables. NVivo is the industry standard but the licensing cost is significant. If you are working with very small budgets, R packages like quanteda give you serious analytical power at no cost if you are comfortable with command-line interfaces.
The honest truth is that content analysis is neither magic nor obsolete. It is a tool with specific conditions where it works well and specific conditions where it produces misleading results. Use it when you need systematic evidence from text. Do not use it when the question requires deep contextual interpretation that cannot be captured in categories. Knowing which is which is the actual skill here.