What Actually Happens When You Run a Study
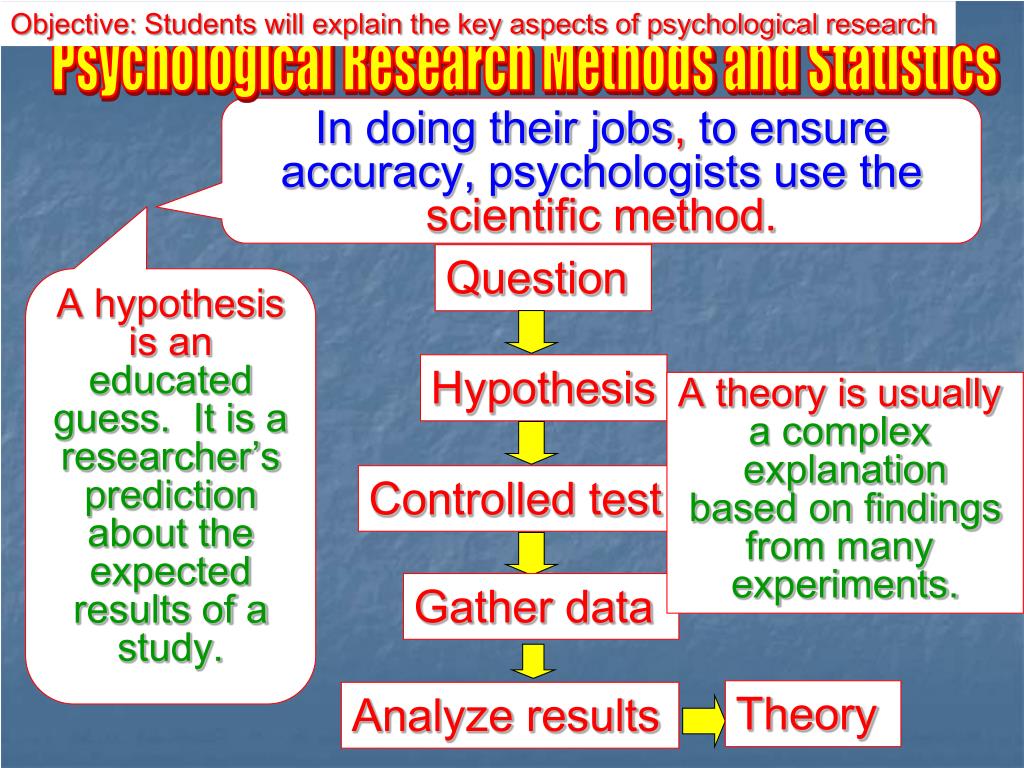
Most people think research methods and statistics are two separate subjects you take in different semesters. They aren't. In practice, they are the same workflow just described from different angles. You design something that can be measured, you collect numbers, and then you figure out whether those numbers mean anything beyond random chance. That is the entire loop. The textbooks make it look linear. Hypothesis, operation, data, analysis, conclusion. Anyone who has actually recruited participants and watched their software spit out an error at 2 AM knows it is messier than that. You will rework your design three times before you collect a single data point. You will delete half your dataset because someone didn't read the instructions. You will find out that your clean factorial design doesn't translate to the messy reality of human attention spans.
Psychological Research Methods And Statistics
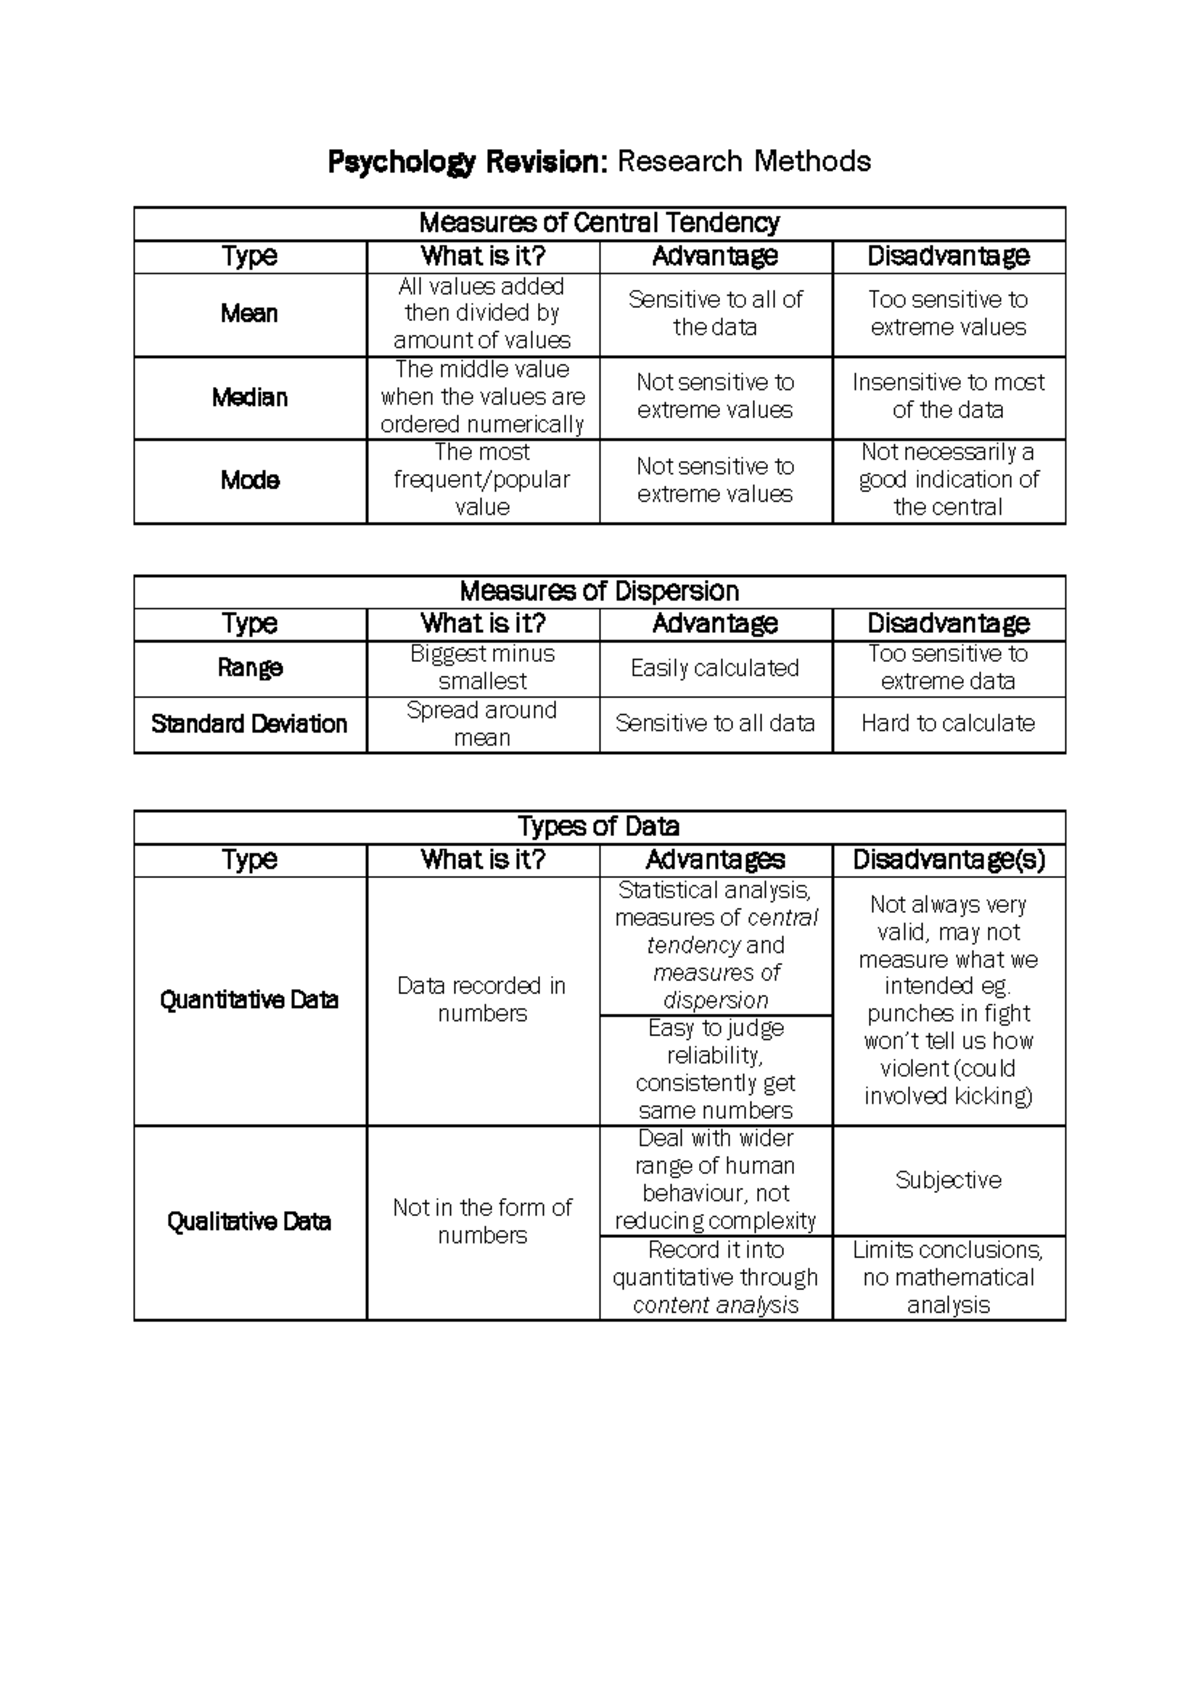
This isn't a theoretical framework. It is a set of procedures that exists to keep you from lying to yourself. That is the honest summary. Every survey you run, every reaction time you measure, every statistical test you choose is an attempt to produce evidence that is less contaminated by your own expectations than it would otherwise be. That sounds modest but it is actually the whole point. Beginners treat the methods section as an afterthought. They write it at the end and usually get it wrong because they describe what they did instead of what someone else would need to do to replicate it. A proper methods section lets another researcher gather the same data using the same parameters. If someone reads your description and has to guess about stimulus duration or exclusion criteria, your methods section has failed. This is not about being thorough for thoroughness sake. It is about whether your findings survive scrutiny. On the statistics side, the most common mistake is treating p-values as a binary gatekeeper. Pass the threshold and you have discovered something. Miss it and you have nothing. That framing destroys the actual work. Effect sizes matter more. Confidence intervals matter more. The distribution of your data matters more than any single significance test. I once spent six weeks troubleshooting why my regression model produced impossible standard errors, only to discover a single participant whose score was four standard deviations away from every other person in the sample. Not four percent. Four standard deviations. One data point was inflating my error terms enough to make the entire model unreliable. Winsorizing the distribution rather than deleting the participant entirely brought the standard errors back into a usable range and didn't require me to justify removal to reviewers later.
The Design Phase
You need to decide what question you can actually answer before you write a single hypothesis. This sounds obvious but most students skip it and jump straight to picking a statistical test. The test comes last. The question comes first. The design sits in between. Variables are the building blocks. Independent variables are what you manipulate or categorize. Dependent variables are what you measure. Control variables are everything else you hold constant or account for statistically. Confounds are the variables you forgot to control. The difference between a confound and a control variable is whether you knew it existed before the study started. If you knew about it and measured it, it is a control variable. If you didn't know about it until after you analyzed the data, congratulations, you found a confound and now you have to figure out whether it invalidated your results. Internal validity asks whether your manipulation actually caused the outcome. External validity asks whether the outcome would occur outside your lab. You rarely maximize both simultaneously. A laboratory experiment with tightly controlled stimuli has strong internal validity but weak external validity. A field study generalizes well but you can never be certain which factor produced the effect. This is not a flaw in research. It is a tradeoff you need to acknowledge explicitly in your discussion section.
Get the Full Details
Power analysis should happen before data collection, not after. G*Power is the standard free tool for this. You input your expected effect size, your alpha level, and your desired power. It tells you the minimum sample size. Most people skip this step and then wonder why their non-significant result could mean either that the effect doesn't exist or that the study was too small to detect it. Those are different conclusions and they require different designs to distinguish.
Measurement and Operationalization
A construct like anxiety means nothing until you decide how to measure it. Will you use a self-report scale? Physiological indicators? Behavioral observation? Each has different reliability and validity profiles. Self-report scales are quick and cheap but vulnerable to social desirability bias and mood-state effects. Physiological measures are harder to fake but expensive and often ambiguous in interpretation. A raised skin conductance response could mean anxiety, excitement, or the participant just walked past a bright light. Reliability is consistency. If you measure the same thing twice under the same conditions, do you get the same result? Cronbach's alpha above 0.7 is the standard threshold for acceptable internal consistency on multi-item scales. Validity is accuracy. Are you measuring what you think you are measuring? Content validity, construct validity, criterion validity. These are not alternatives to each other. A good measure has all three. I have seen researchers use scales that were validated on clinical populations with college students without checking whether the psychometric properties held. The factor structure collapsed. Item loadings shifted. The scale measured something different in that population. Running a confirmatory factor analysis on your own data before treating the scale as valid costs about two hours and prevents months of wasted analysis later.
Data Collection Realities
Pilot testing is where theory meets the constraint of human compliance. Your beautiful experimental design assumes participants will read instructions, follow directions, and remain attentive for forty minutes. The pilot tests that assumption. Usually the pilot reveals that your instructions are too long, your stimuli are ambiguous, or your dependent measure is too sensitive to random variation. Fixing these issues during the pilot phase saves more time than fixing them during the analysis phase because you avoid collecting unusable data in the first place. Exclusion criteria need to be predefined. If you decide to exclude participants after seeing the results, you are conducting data dredging and reviewers will identify it immediately. Pre-registration solves this problem by locking your exclusion rules before data collection begins. It also protects you from the temptation to quietly remove outliers that are inconveniently placed. I once had a reviewer ask me to justify removing five participants from my final analysis. I had predefined exclusion criteria for inattentive responding and failed attention checks. The five participants had failed two or more attention checks. The criteria were written in my pre-registration file. The reviewer accepted it without further question. If I had written the criteria after seeing the data, the same justification would have been flagged as questionable.

Choosing the Right Analysis
Statistical tests are not interchangeable tools you pick based on convenience. They are mathematical models with specific assumptions about your data. Violating those assumptions doesn't always invalidate your results but it changes the interpretation and sometimes the direction of the findings. A t-test compares two means. An ANOVA compares three or more. Both assume normality, homogeneity of variance, and independence of observations. When your data violate normality, you have options. Transform the data. Use a non-parametric alternative. Use a robust method that is less sensitive to violations. The choice depends on the severity of the violation and the sample size. Central limit theorem helps with large samples but most psychology studies don't have large samples. Regression models deserve more attention than they get in introductory courses. They are not just for prediction. They are for understanding relationships between variables while controlling for confounds. Hierarchical regression lets you test whether a new predictor adds explanatory power beyond existing predictors. Mediation analysis tests whether the effect of one variable on another operates through a third variable. Moderation analysis tests whether the relationship between two variables changes at different levels of a third variable. These distinctions matter for interpretation. A mediated relationship has a different causal story than a moderated one. Treating them as interchangeable leads to incorrect conclusions about mechanisms.
Multilevel modeling handles nested data. Students within classrooms. Patients within therapists. Trials within participants. Standard regression assumes independence of observations. When observations are clustered, that assumption is violated and standard errors are underestimated. Multilevel models account for the clustering by estimating variance at each level. This is not a minor technical detail. Ignoring clustering in a study with 200 participants across 20 classrooms can inflate your Type I error rate substantially. The analysis takes longer and requires more computational effort but the results are more accurate.
Common Problems That Appear During Analysis
Missing data is almost unavoidable in behavioral research. Participants skip questions. Devices fail to record. Attrition occurs in longitudinal studies. Listwise deletion removes any case with missing values on any variable. This is simple but wasteful and potentially biased if the data are not missing completely at random. Multiple imputation fills in missing values multiple times using the observed data distribution, analyzes each completed dataset, and combines the results. This preserves more information and produces less biased estimates when the missingness mechanism is plausible. It adds computational complexity and requires careful implementation but the time investment pays off in more defensible results. Multiple comparisons inflate your familywise error rate. Every test you run has a chance of producing a false positive. Run twenty tests at alpha 0.05 and you expect one false positive by chance alone. Bonferroni correction divides your alpha by the number of tests. It is conservative and reduces power but it is simple and widely accepted. False discovery rate control is less conservative and more appropriate when you expect some true effects among many tested hypotheses. The choice depends on your goals. Confirmatory research benefits from stricter control. Exploratory research can tolerate more liberal thresholds with appropriate acknowledgment. Publication bias skews the literature. Studies with significant results publish more readily than studies with null results. This creates a distorted evidence base where the true effect size appears larger than it actually is. Meta-analysis partially addresses this by combining results across studies but it cannot fully correct for the missing null findings. Registered reports solve part of the problem by peer reviewing study designs before data collection. Journals commit to publishing the results regardless of outcome. This is still relatively uncommon but it is the most effective structural intervention available.

Software and Practical Workflow
SPSS is the default in many programs because it is widely taught and has a point-and-click interface. R is the professional standard for reproducible research. JASP offers a free graphical interface with Bayesian analysis built in. All three handle standard analyses. The differences appear in flexibility, reproducibility, and cost. SPSS syntax can reproduce analyses but the workflow is less transparent. R scripts are fully reproducible by default but require programming knowledge. JASP sits between them with a GUI that also generates code you can reuse. Data management eats more time than anyone expects. Cleaning a dataset with 500 participants and 120 variables usually takes longer than running the analyses. Consistency checks, outlier detection, recoding reverse-scored items, handling skipped blocks in surveys. Building a clear codebook and keeping a raw copy of your data untouched are habits that prevent disasters later. I once discovered that a coding error in a merged dataset had flipped the sign of my key independent variable for half the participants. The error went unnoticed for three weeks because I hadn't kept an independent copy of the original file. This is avoidable with minimal workflow discipline.
What the Field Gets Wrong
Replication is harder than people admit. A successful replication requires matching the original study's conditions closely enough to detect the same effect but varied enough to test generalizability. Most replication attempts fail because of subtle differences in procedure, population, or timing. A study conducted in spring with undergraduate psychology majors may not replicate in fall with a community sample even when the statistical protocol is identical. This doesn't mean the original finding was false. It means psychological effects are context-dependent and replication is a test of boundary conditions, not just a pass-fail check. P-hacking is tempting when your career depends on it. Data peeking, optional stopping, selective reporting, trying different analytical approaches until you find significance. Each decision seems minor in isolation. Combined they produce results that look significant but are actually artifacts of the analytic flexibility. Preregistration and analysis plans reduce this temptation by committing to decisions before data collection. Even if you don't preregister, documenting your analytic decisions and reporting all tests you ran is better than reporting only the significant ones. Reviewers and readers can see the full picture and judge for themselves.
Where Methods Actually Break Down
Self-report measures are the workhorse of psychology and they are also the weakest link. People lie, misremember, answer in socially desirable ways, and interpret questions differently. No amount of statistical control fixes these problems at the source. triangulation across methods reduces reliance on any single imperfect measure. Combining self-report with behavioral tasks or physiological indices produces more confident conclusions than any single method alone. This is basic research design but it is frequently ignored because convenience drives methodology choices more than rigor does. Statistical significance is not practical significance. A study with 5,000 participants can produce a statistically significant effect that is so small it has no meaningful implication for theory or practice. Conversely, a study with 30 participants might find a large effect that is practically important but fails to reach significance. Reporting effect sizes with confidence intervals addresses this problem better than p-values alone. The numbers tell you the magnitude and precision of the effect. The p-value tells you whether the effect is distinguishable from zero given your sample and design. Neither alone is sufficient for interpretation. Correlation does not equal causation. This is stated in every introductory textbook and ignored in countless published papers. Longitudinal designs improve causal inference but they don't establish it. Experimental manipulation with random assignment is the gold standard for causality. Observational studies can only support associations. When researchers make causal claims from correlational data, they are making a logical leap that the statistics alone cannot justify. The design supports the claim, not the analysis.

The field is moving toward open science practices but adoption is uneven. Sharing data, sharing materials, preregistering studies, reporting null results. These practices improve credibility and reduce waste but they require institutional support and cultural change. Individual researchers can adopt them without waiting for journals to mandate them. The effort is real but the cost of not doing it is higher in the long run.