Understanding the Pumping Lemma for Context Free Languages
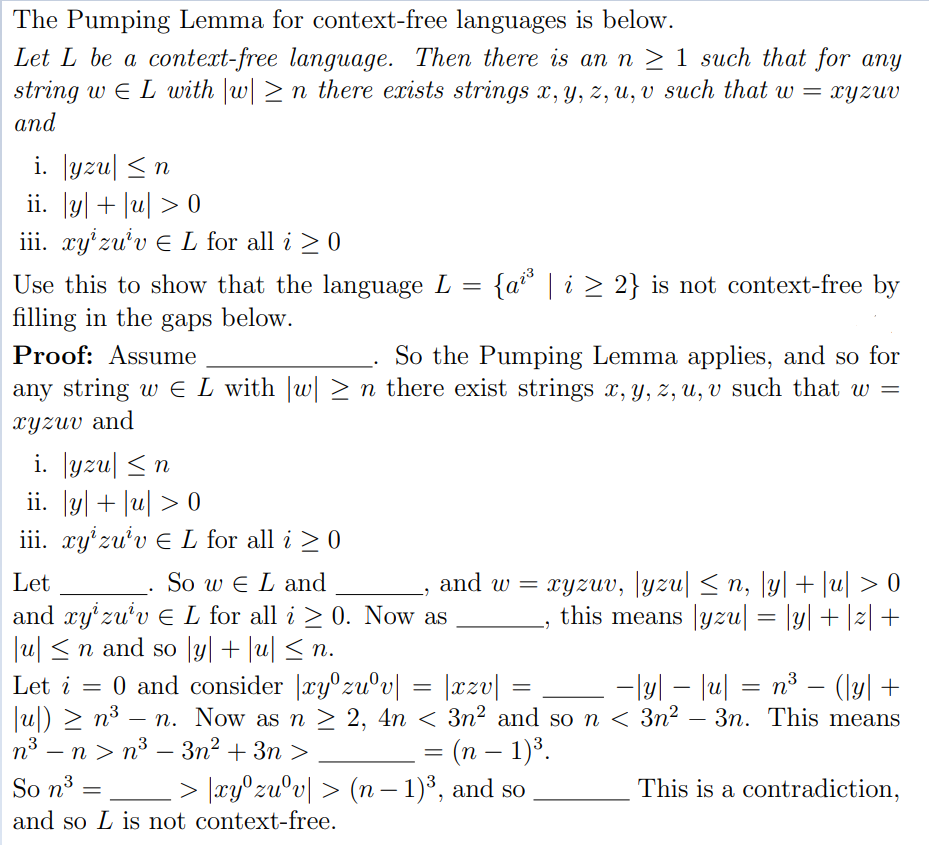
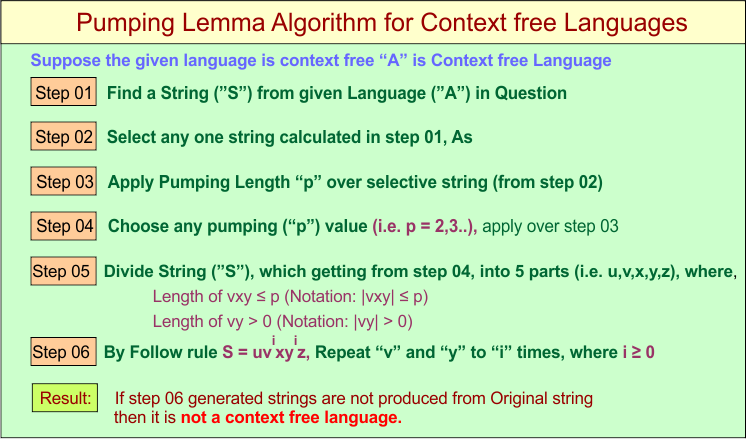
The pumping lemma for context free languages is a tool you use to prove that certain languages aren't context free. It works by showing that any valid pushdown automaton or context free grammar would have to "pump" a string in a way that breaks the language's rules. I've spent years watching students and even experienced engineers trip over this proof technique because the definition gets stated so abstractly that nobody actually knows what to do with it. Here's how the lemma works in practice. For a context free language L, there exists a pumping length p such that any string s in L with length at least p can be divided into five parts: s = uvxyz, where |vxy| p, |vy| 1, and for every i 0, the string uv^i xy^i z is also in L. The key constraint nobody emphasizes enough is that v and y together must contain at least one character, and the vxy portion has to fit within the first p characters of the string.
Pumping Lemma For Context Free Languages
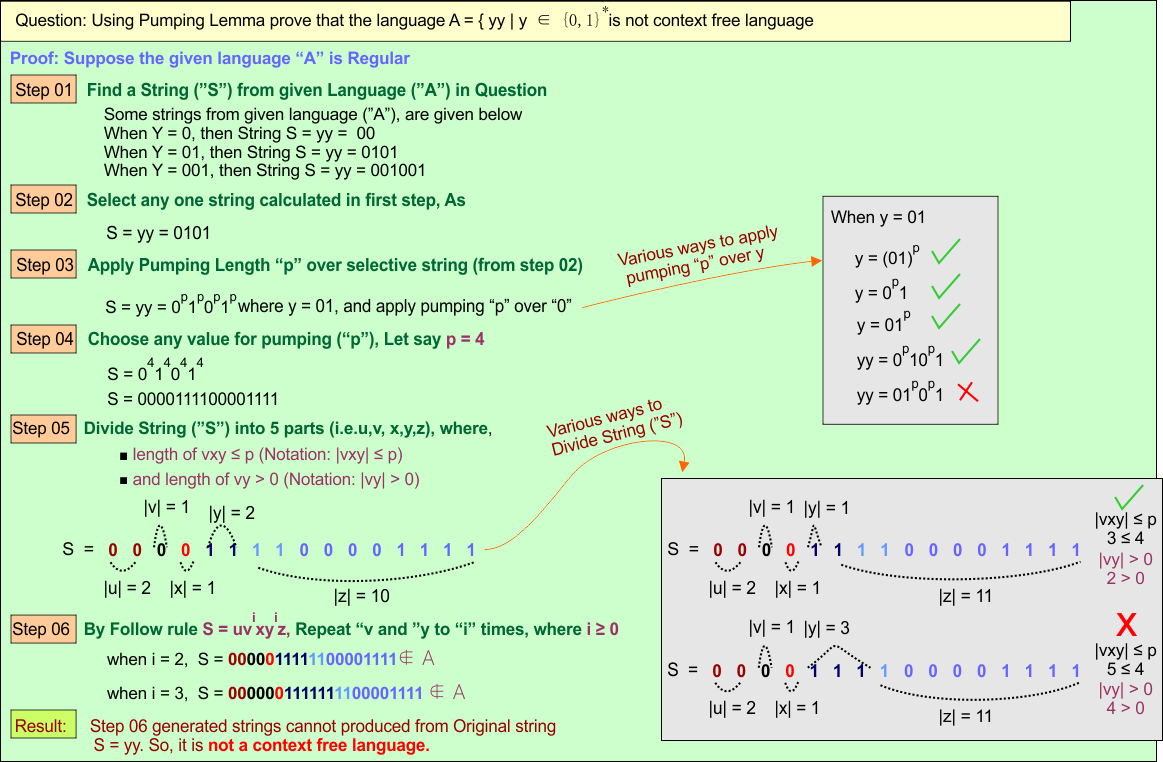
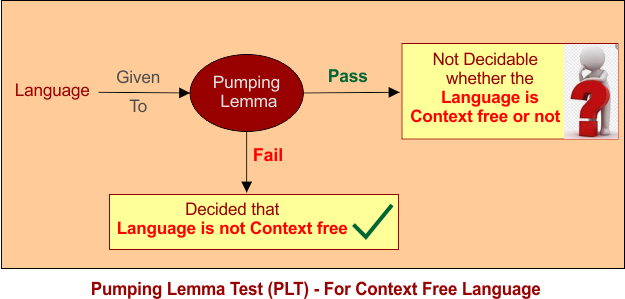
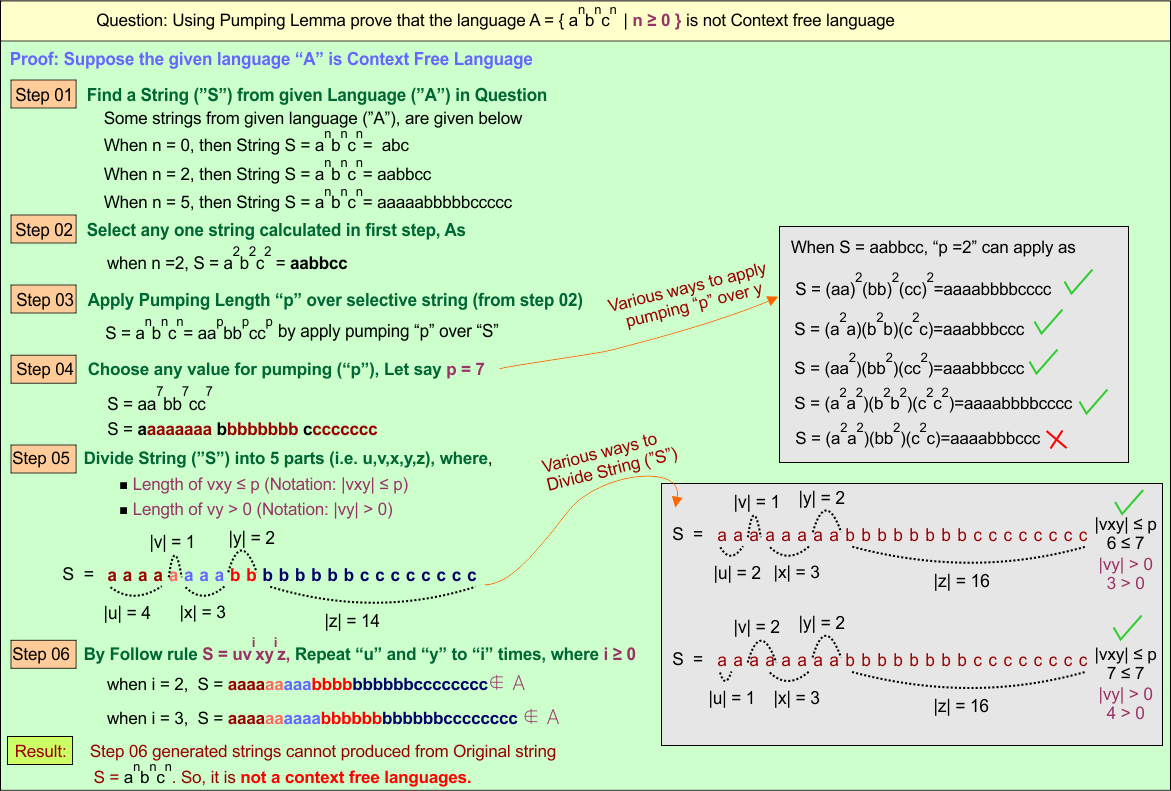
Let me walk through a concrete example. Take the language L = {a^n b^n c^n | n 0}. This is the classic non-context-free language. You pick your pumping length p, and then choose a string s = a^p b^p c^p. Now you try every possible decomposition into uvxyz. Since |vxy| p, the substring vxy can span at most two different character blocks. If vxy covers only a's and b's, then pumping v and y will increase the count of a's and/or b's without touching c's, breaking the equality condition. Same logic applies if vxy spans b's and c's, or sits entirely within one block. No matter how you split it, pumping produces a string outside L, which contradicts the lemma. Therefore L isn't context free. I ran into a real issue with this once while working on a parser generator validation project. Someone had claimed that the language {ww | w {a,b}*} — all strings that are some string concatenated with itself — was context free. The standard pumping lemma approach almost works here, but you hit a wall when trying to pick your initial string. If you use s = a^p b^p a^p b^p, the vxy segment could land entirely within the first half or the second half, and pumping might not obviously break the ww structure. I spent about three hours trying different string choices before switching tactics. The workaround was using Ogden's lemma instead, which lets you mark specific positions in the string. Mark the first a^p and the last a^p positions, and then vxy can't avoid spanning the boundary in a way that preserves the equal-halves property. Ogden's lemma is stronger and handles cases where the standard pumping lemma leaves you stuck. One counter-intuitive thing about the pumping lemma is that it only proves non-context-freeness in one direction. If a language satisfies the pumping lemma conditions, that doesn't automatically mean it's context free. The lemma gives you a necessary condition, not a sufficient one. There are actually non-context-free languages that happen to satisfy the pumping lemma constraints. I learned this the hard way when I was reviewing a colleague's proof that tried to use the converse as justification.
Another nuance that beginners miss is the choice of the string s. You get to pick s after the adversary picks p, but s has to be in the language and have length at least p. Picking s = a^p b^p c^p works for {a^n b^n c^n}, but for other languages like {a^i b^j c^k | i j or j k}, you need a different strategy. You'd typically pick s = a^p b^p c^{p+1} and then analyze where vxy can land. The structure of your chosen string determines how many cases you have to consider when you're trying to find the contradiction. The real bottleneck with this technique is the case analysis. For languages with multiple constraints, you can end up with four or five different regions where vxy might sit, and each region requires its own argument about why pumping fails. I've seen proofs that should have been straightforward run pages long just because the author didn't group the cases efficiently. A useful shortcut: if vxy spans exactly two adjacent symbol blocks, the pumping will unbalance those two counts. If it stays within one block, you're changing one count independently. These two categories cover most standard examples. If you're working with actual programming language syntax or compiler design, the pumping lemma is more of a theoretical check than a practical debugging tool. You won't be proving whether a language is context free in production code. But when you're designing a formal language specification or verifying a grammar, knowing when a language falls outside the context-free class matters because it tells you whether a pushdown automaton or LR parser will ever work for it. If it's not context free, you're looking at a more powerful parsing framework or a different language design entirely.
Get the Full Details
There are online resources where you can find practice problems and step-by-step worked examples. Some university course pages have detailed solution sets that walk through the decomposition logic in full. The process isn't fast — even for someone who does this regularly, a single proof with a tricky language can take twenty to forty minutes depending on how many cases you need to rule out — but it becomes much more mechanical once you recognize the common patterns.