When Your Automaton Theory Exam Won't Let You Sleep
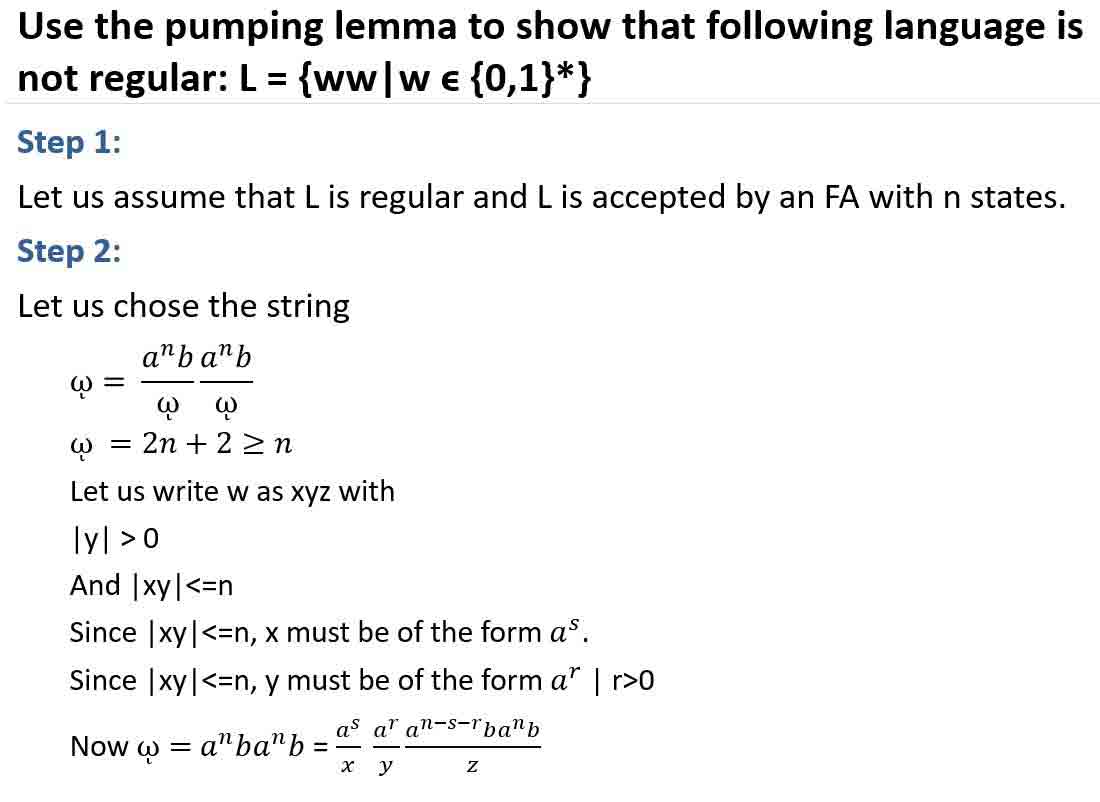
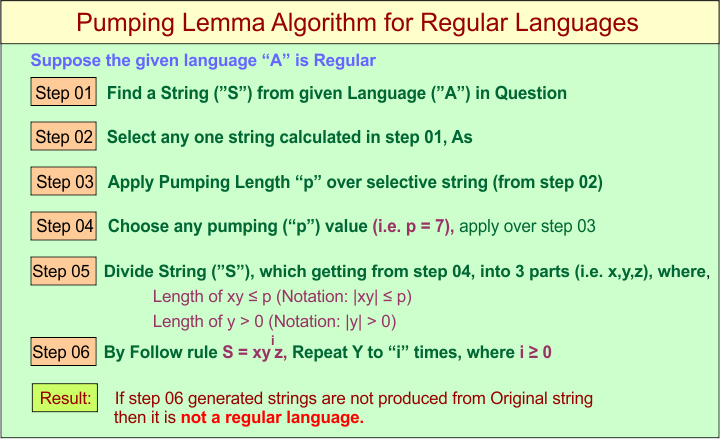
I learned the Pumping Lemma For Regular Languages during my undergrad because our professor insisted it was the most practical proof technique we'd encounter that semester. He wasn't wrong, exactly, but he also didn't prepare me for the fact that applying it correctly is a completely different skill from understanding what it says. The lemma itself takes about two minutes to state. Using it to actually prove something isn't regular takes significantly longer and involves a lot more care than most textbooks suggest. The standard approach is proof by contradiction, which means you start by assuming the language you're investigating IS regular, then you derive something impossible from that assumption. Here's the mechanical process: pick your language L. Assume L is regular. The lemma guarantees there exists a pumping length p. Then you choose a specific string s from L whose length is at least p. Next, the lemma says s can be split into three parts, xyz, where |xy| <= p, |y| > 0, and xy^iz is in L for every i >= 0. Your job is to show that for ANY possible split satisfying those constraints, there exists some i where xy^iz falls outside L. If you can do that, your assumption was wrong and L is not regular. The part nobody tells you clearly is that you don't get to choose how the string is split. The adversary picks the split. You only pick the string. This reversal of agency is what makes the proof technique feel unintuitive. You write "for all splits of s into xyz" and then you have to cover every possible way y could land within the first p characters. In practice this usually means you construct s so that no matter where y falls, pumping it breaks the language's structure.
Pumping Lemma For Regular Languages — Definition and Mechanics
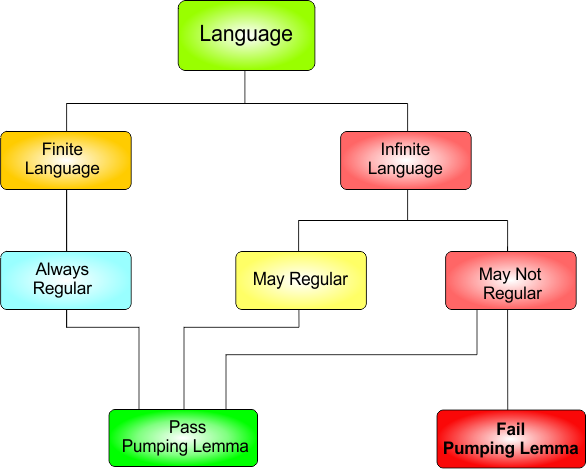
Here's the formal statement, stripped of unnecessary gloss: if L is a regular language, there exists a constant p >= 1 such that for every string s in L with |s| >= p, s can be written as xyz satisfying three conditions. First, |xy| <= p. Second, |y| > 0. Third, for all i >= 0, the string xy^iz is also in L. The constant p corresponds to the number of states in a DFA that recognizes L. The pigeonhole principle forces any accepted string longer than p states to revisit at least one state, creating a loop. That loop is y. You can traverse it zero times or a thousand times and still remain in an accepting configuration. The common mistake beginners make is trying to use the lemma to prove a language IS regular. It doesn't work that way. The lemma gives a necessary condition, not a sufficient one. A language can satisfy the pumping property and still not be regular. There are non-regular languages that pass the pumping lemma test. I ran into this when I was helping a graduate student debug a homework problem — she had a language that looked like it should fail pumping but actually didn't, and she spent two days convinced the answer was wrong before she realized the lemma simply wasn't applicable for disproving regularity in her case. The workaround was switching to the Myhill-Nerode theorem, which uses equivalence classes of indistinguishable prefixes and gives a strictly stronger characterization. Checking whether a language has finitely or infinitely many equivalence classes resolves questions the pumping lemma leaves dangling.
A Concrete Example Walkthrough
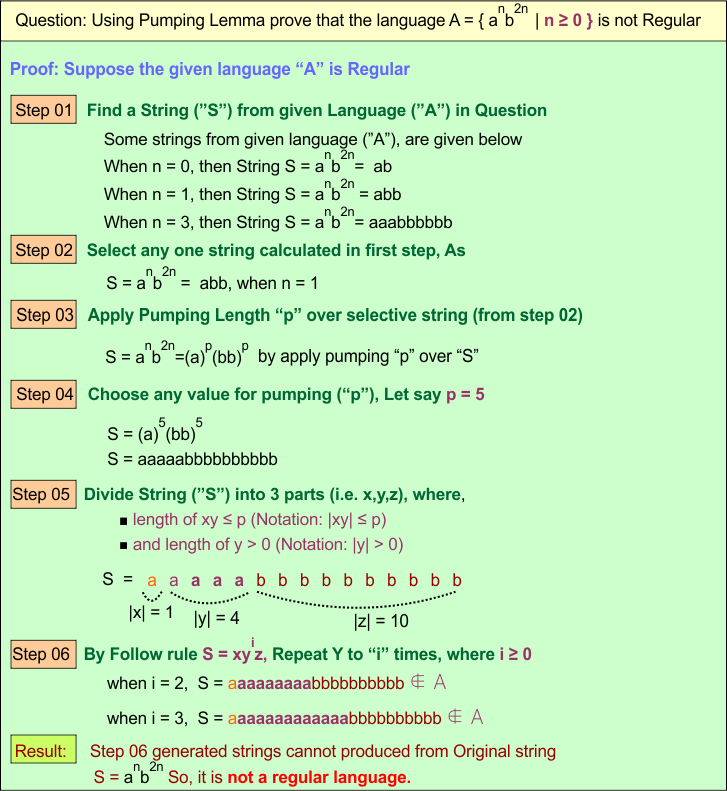
Consider the language L = {a^n b^n : n >= 0}. This is the classic non-regular language. Assume L is regular and let p be the pumping length. I choose s = a^p b^p. This string is in L and its length is 2p, which exceeds p. Now any valid split xyz must satisfy |xy| <= p and |y| > 0. Since the first p characters are all a's, both x and y consist entirely of a's. That means y = a^k for some k where 1 <= k
= p. When I pump with i = 2, I get xy^2z = a^(p+k) b^p. The number of a's is now p+k and the number of b's is still p. Since k is positive, p+k is not equal to p, so the pumped string is not in L. This contradicts the pumping lemma, so L is not regular. The edge case that trips people up involves choosing s too carefully or too loosely. If you pick s = a^p b^p c^p for a language that actually is regular, you'll waste time trying to force a contradiction that doesn't exist. The string needs to be in your language AND long enough AND structured so that y's position is constrained by the |xy|
= p condition. For languages over multiple alphabet symbols, the constraint on where y can fall becomes your main lever. You pick s so that whatever region y lands in, pumping it violates the language's defining property.
Get the Full Details
When the Lemma Fails and What to Do Instead
The pumping lemma has real limitations. It cannot distinguish between regular languages and certain context-free languages that happen to satisfy the pumping property. It also becomes awkward to apply when the language's structure doesn't create an obvious asymmetry that pumping would break. I once worked through a problem involving the language of all binary strings where the number of 0's is divisible by 3. A first-pass pumping lemma attempt failed because the language is actually regular — it's recognized by a 3-state DFA — so no contradiction exists. The exercise was useful only for confirming what we already knew, which is not particularly illuminating. For these situations, constructing the automaton directly or applying Myhill-Nerode is faster and more definitive. Building the DFA takes roughly 10 minutes for simple modular-counting languages, whereas wrestling with the pumping lemma through a false contradiction path can consume an hour or more with no productive output. Another limitation: the lemma provides no constructive method for finding p. In theory p equals the number of states in the minimal DFA, but for complex languages you might not have an obvious automaton to count. You can sometimes bound p by analyzing the language's structure directly, but this is case-specific and requires enough familiarity with the class of languages to recognize which structural features constrain the state space. Without that familiarity, guessing p leads to incorrect proofs or wasted effort.
Practical Tips That Actually Matter
Always verify your chosen string s is actually in the language before you begin the contradiction. I've seen students pump strings that weren't members of L and then wonder why their proof collapsed. Second, explicitly state which value of i you're using to break the language. i = 0 and i = 2 are the most common choices. i = 0 removes y entirely and is useful when y contains a crucial symbol. i = 2 adds a copy of y and is useful when the language requires exact counts. Pick the one that creates the clearest violation. Third, don't forget to handle the quantifier order correctly. You say "for all splits xyz" before you say "there exists an i." Flipping these changes the logical meaning entirely and invalidates the proof structure. When working with languages over {a, b}, the most reliable string template is a^p b^p or a^p b^{p^2} depending on what the language requires. The exponent on the second block should be large enough that removing or duplicating a chunk from the first block cannot be compensated by the second. For more complex alphabets, pad your string strategically so that the |xy|
= p constraint forces y into a region where pumping is destructive to membership. The technique is straightforward once you internalize the adversarial structure. You pick the string. The opponent picks the split. You find the pump that breaks it. If you follow that sequence rigidly and check each condition explicitly, most proofs resolve in under five minutes. The ones that don't usually involve a language that either passes the lemma genuinely or requires a different tool entirely.