Getting Your Head Around Flashblade Administration
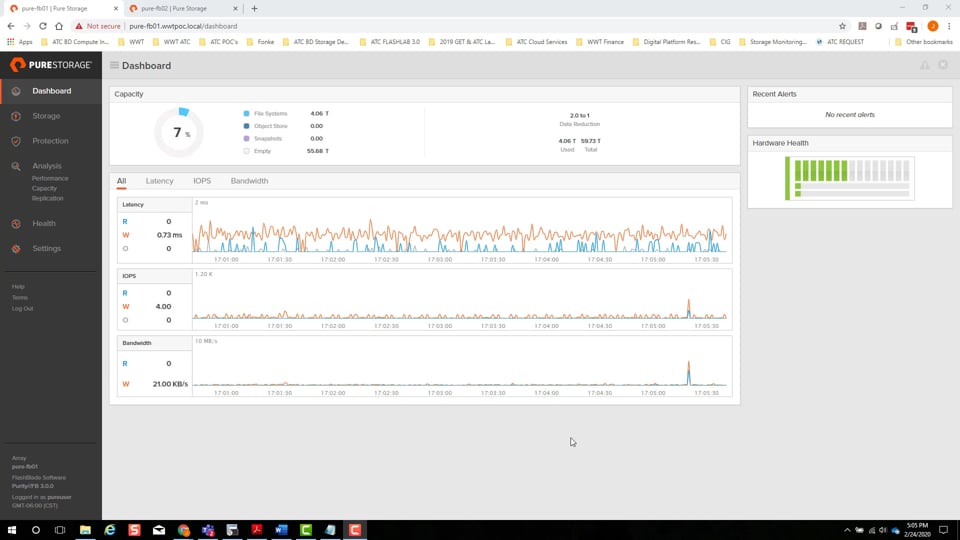
I've been working with HPE's Alluxio platform and Flashblade storage arrays for about four years now, and honestly the documentation situation has improved but still leaves gaps that will bite you if you're not careful. The Pure Flashblade Admin Guide is the official reference, but like most enterprise admin docs it's written by people who design the system, not people who keep it running at 2 AM when something breaks. I found myself reading the same section about namespace caching three different times before it finally clicked. The guide covers provisioning, performance tuning, S3 and NFS access configurations, LDAP/AD integration, and the usual operational tasks like firmware updates and alert management. But here's the thing nobody tells you - the sections that seem straightforward are where most problems hide. I spent a Tuesday afternoon chasing a latency spike that turned out to be caused by a metadata cache setting the guide mentions in passing but doesn't explain the interaction with concurrent NFS handles. The workaround was adjusting the per-client cache TTL from the default 60 seconds down to 15, which isn't intuitive because lower cache values usually sound worse for performance. In this case the high TTL was causing stale reads across our compute nodes. The admin documentation will walk you through the basic throughput and IOPS targets, but the real tuning happens in areas that get barely a paragraph. One counter-intuitive finding: enabling aggressive deduplication on Flashblade can actually degrade small-file write performance by 30-40 percent because the dedup engine competes for the same CPU cycles as the metadata path. For our HPC workloads with millions of sub-10KB files we turned dedup off entirely and gained more by optimizing the block size for our access pattern than we ever lost to raw capacity savings.
Another thing the guide doesn't emphasize enough is the relationship between Alluxio cache tiers and the Flashblade internal SSD cache. When you run both, they fight each other for the same data. I've seen setups where enabling L1 cache on the Alluxio side while also having the Flashblade SSD tier active resulted in slower overall performance than either alone, because of duplicate caching overhead. The fix was letting Alluxio handle the hot path and disabling the Flashblade SSD tier entirely for those workloads.
Common Pitfalls That Won't Appear in Any Documentation
LDAP integration is where I've lost the most hours. The guide shows you the basic bind DN and search base configuration, but it doesn't mention that if your AD has nested groups, the default search scope won't resolve them correctly and you'll get authentication failures that look like credential problems. Switching the group search to recursive scope fixed it, but you have to do it via the REST API, not the web UI. The web UI silently rejects the parameter and falls back to basic scope without any error message. Firmware updates are another minefield. The admin guide presents them as a straightforward rolling update process, but in practice I've seen cases where a dual-controller setup would come back from an update with one controller reporting a different firmware level than the other, causing asymmetric performance that's nearly impossible to diagnose. The workaround I use now is running a manual consistency check after every update and not declaring the operation complete until both controllers report identical firmware versions. This adds about 12 minutes to each maintenance window but saves me from overnight pages.
Get the Full Details

When the Guide Stops Being Useful
Here's where I need to be honest about the limitations. The Pure Flashblade Admin Guide is solid for day-to-day operations and initial deployment. It will get you through creating filesystems, setting up access endpoints, and configuring basic alerts. But once you hit anything beyond routine administration - performance debugging, cross-system integration issues, or recovery from unusual failure states - the guide becomes a starting point rather than a solution. For those situations you're better off with HPE's support channels or the community forums where engineers share actual playbooks for edge cases. Also worth noting: the guide assumes you're managing a single Flashblade system. If you're running multi-site configurations or integrating with cloud tiers through Alluxio, most of the advanced scenarios simply aren't covered. I ended up relying heavily on HPE's internal engineering notes and some third-party posts to fill those gaps, which isn't ideal but is the current reality of enterprise storage documentation.
Practical Tips I Wish the Guide Had Included
Set up alerting on namespace cache hit ratios early. The default thresholds are too generous and you'll miss the gradual degradation that precedes a full cache stampede. I configure mine to trigger at below 65 percent cache hit rate over a 15-minute window, which has caught three separate problems before they became user-facing incidents. Document your SMB and NFS mount options explicitly in your own runbook. The guide covers the protocol parameters but not the client-side tuning that matters. Options like hard mount, rsize/wsize settings, and TCP window scaling have a bigger impact on perceived performance than most of the server-side configuration. Keep a baseline. Run a standard benchmark suite after deployment and save the numbers. Six months later when performance seems off, you'll have actual data instead of a vague sense that something changed. Our baseline runs took about 20 minutes each but have saved us hours of investigation time when incidents occurred.