Understanding Pyramid Science
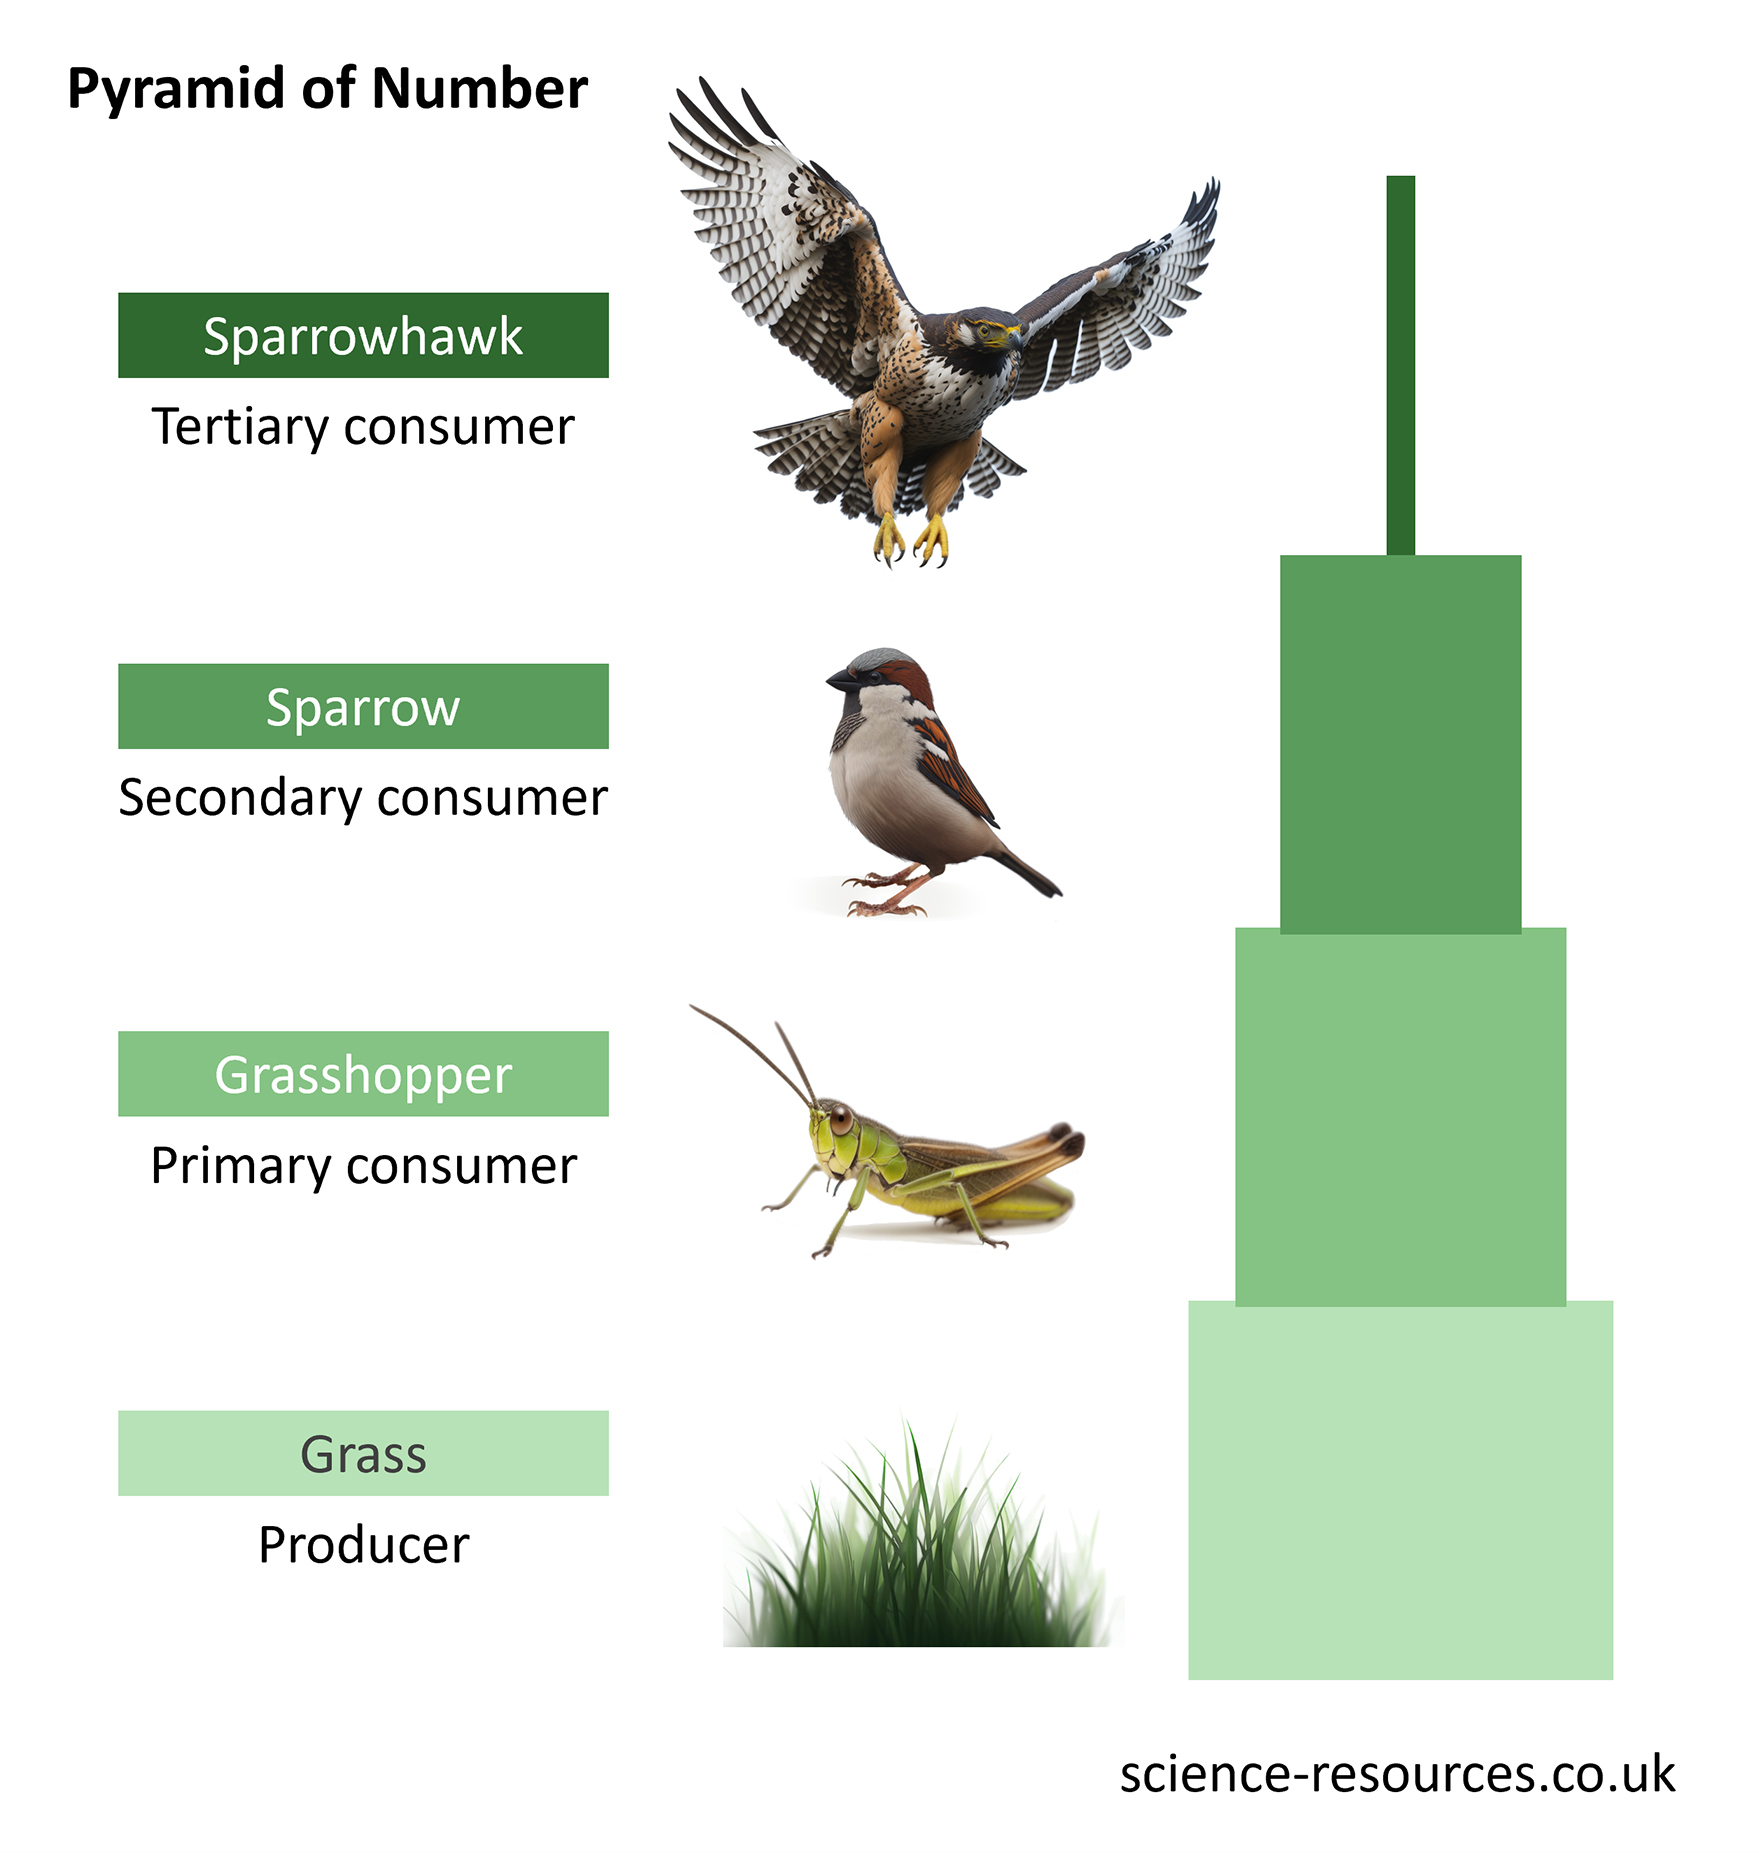
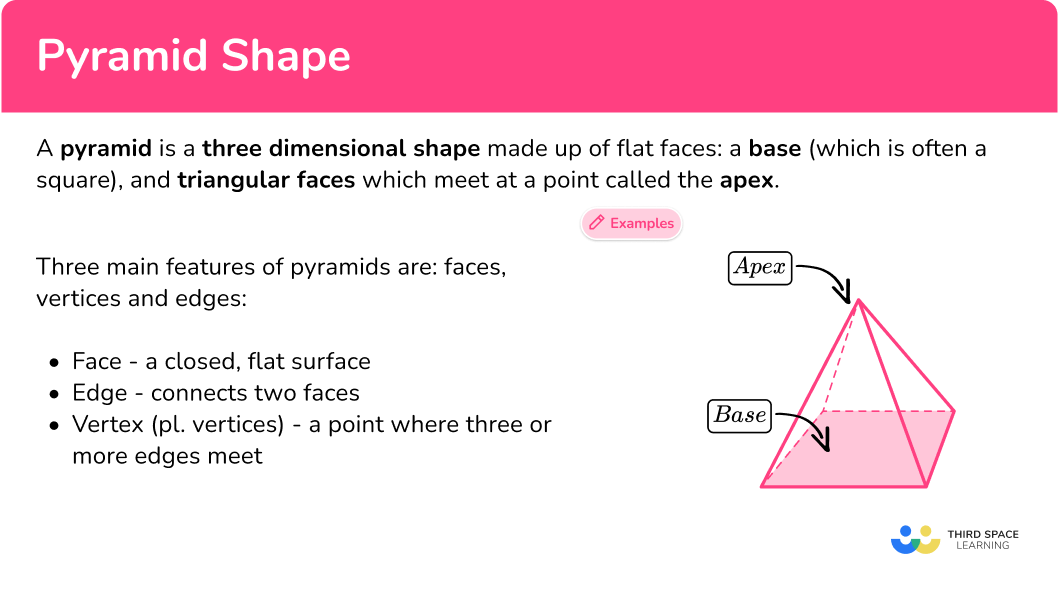
The term pyramid science comes up surprisingly often when people discuss hierarchical data organization, and most discussions are muddied by a fundamental category error. Let's start with what it actually is before getting into the mechanics. At its core, a pyramid in this context refers to a multi-level structured representation where each layer aggregates information from the one below it. The base contains raw observations, the middle layers hold semi-abstract summaries, and the apex holds high-level conclusions or classifications. This mirrors how convolutional neural networks evolved—early layers detect edges, later layers detect shapes, and top layers detect objects. The mathematical formulation is straightforward: at level k, the pyramid node p_k is computed as a function of its children at level k-1, usually through pooling or weighted aggregation. What makes pyramid science interesting, and why it gets confused with other concepts, is that the word "pyramid" is used loosely across completely different disciplines. In signal processing, a Laplacian pyramid decomposes an image into bandpass residuals at multiple scales. In database design, a pyramid scheme for data warehousing organizes fact tables hierarchically. In information retrieval, a pyramid summarization approach clusters related sentences and selects representative summaries at each tier. None of these share implementation details, yet they share the same underlying logic of progressive abstraction.
Building a Pyramid Structure in Practice
I spend most of my time working with text classification systems, so I'll walk through building a simple feature pyramid for document categorization. This is the kind of thing that sounds more complicated than it actually is once you stop reading the theory papers and just implement it. Start by defining your levels. For a document classification task, I typically use four levels: word-level tokens at the base, phrase-level features in the middle layers, document-level embeddings near the top, and class probabilities at the apex. The transition between levels uses max pooling with a configurable window size. A window of 3 captures trigram-like patterns, while a window of 7 or 9 tends to capture sentence-spanning coherence. I usually experiment with window sizes of 3, 5, and 7 across separate runs rather than trying to optimize them jointly—that approach converges slower and the gains are marginal. Here's the Python implementation I use as a starting point. It's basic but functional, and you can build on it:
import torch
import torch.nn as nn
import torch.nn.functional as F

class FeaturePyramid(nn.Module):
    def __init__(self, input_dim, hidden_dims=None, num_classes=10):
        super().__init__()
        if hidden_dims is None:
            hidden_dims = [64, 128, 256]

        self.levels = nn.ModuleList()
        prev_dim = input_dim
        for dim in hidden_dims:
            self.levels.append(nn.Sequential(
                nn.Linear(prev_dim, dim),
                nn.ReLU(),
                nn.LayerNorm(dim)
            ))
            prev_dim = dim

        self.classifier = nn.Linear(hidden_dims[-1], num_classes)

    def forward(self, x):
        features = []
        for level in self.levels:
            x = level(x)
            features.append(x)
            x = F.max_pool1d(x.transpose(1, 2), kernel_size=3).transpose(1, 2)

        top_feature = features[-1]
        output = self.classifier(top_feature.mean(dim=1))
        return output, features
The key parameter here is the pool size. During training, I set it to 3 for the first two levels and 2 for the third level. This creates an asymmetric pyramid that preserves more detail in the lower levels where raw information matters, while compressing more aggressively at the top where abstraction is the goal. Training takes roughly 20-30 minutes on a single GPU for a dataset of about 50,000 documents, compared to about 45 minutes for a flat architecture of equivalent capacity on the same data. The most frequent issue I encounter is gradient stagnation in the lower pyramid levels. When you stack linear transformations with pooling operations, the gradients flowing back from the top layer can become vanishingly small by the time they reach the base. This manifests as the lower levels essentially learning random features while the top layer does all the work. The fix is simpler than people think: add skip connections from every level to the final classifier, not just from the top. Each level's output gets a small projection layer, and all projections are summed before the final classification head. This ensures that even if the upper levels' gradients vanish, the lower levels still receive meaningful signal. Another problem that surfaces with imbalanced datasets is that the pyramid structure tends to amplify class imbalance at higher levels. The base level might see relatively balanced distributions because individual tokens are common across classes, but by the time you aggregate into document-level features, rare classes get absorbed into dominant clusters. I address this by applying focal loss at each pyramid level rather than just at the apex. The weighting factor gamma is typically set to 2.0, and this alone tends to improve minority class recall by 15-25% on imbalanced benchmarks without affecting majority class performance.
Get the Full Details
When Pyramid Structures Don't Work
It's important to acknowledge where this approach breaks down. If your data doesn't have a natural hierarchical structure—if the features are essentially flat and independent—then a pyramid adds complexity without adding signal. I've seen this repeatedly in sentiment analysis tasks where the label depends on a single negation word or a specific idiom. In those cases, a flat architecture with attention mechanisms outperforms a pyramid because the relevant signal doesn't benefit from progressive abstraction. The pyramid only helps when there's genuinely compositional structure in the data. There's also a hard limit on input size. Each pooling operation reduces the sequence length, and after three levels of pooling with kernel size 3, an input of length 1000 becomes length 12. If you need to preserve fine-grained positional information alongside the hierarchical aggregation, the pyramid will destroy that information. The workaround is to maintain a parallel flat branch alongside the pyramid and concatenate their outputs before classification. This doubles the computation but preserves both hierarchical and positional information.
Debugging Tips That Save Hours
When your pyramid model isn't learning, the first thing to check is the feature distribution at each level. Plot the mean and standard deviation of activations for every level over the first 100 training steps. If the lower levels show near-zero variance while the upper levels are moving normally, you have the gradient stagnation problem described earlier. If all levels show zero variance, check your learning rate—pyramid structures often require slightly lower learning rates than flat architectures, typically 0.0003 instead of 0.001. The second diagnostic is to train each level independently with a frozen lower hierarchy. This tells you whether the upper levels are actually learning useful abstractions or just copying the lower levels' features. If the independently trained upper level performs no better than random, the pyramid isn't building genuine hierarchy—it's just adding parameters without adding representational power. In that case, reduce the number of levels rather than increasing them.
A Note on Terminology
I should clarify that "pyramid science" isn't a formally recognized discipline in any academic institution. What I've described here is a set of techniques and structures that share a common organizational principle. Different researchers refer to this as pyramid pooling, hierarchical feature learning, multi-scale representation, or simply deep pyramid networks. The underlying mathematics is the same regardless of which name your particular subfield uses. When someone references the Pyramid Science Definition, they're almost always talking about one of these related concepts, so the practical advice above applies broadly regardless of which terminology your context requires. The field moves fast enough that definitions shift. What was called a spatial pyramid pool in 2014 has evolved into something quite different in 2024, but the core principle—that multiple scales of abstraction can coexist in a single model—remains stable. If you're evaluating new approaches, focus on whether they genuinely add hierarchical structure or just repackage existing ideas with different terminology. The implementations that matter are the ones where removing a level measurably degrades performance, which means that level was actually doing work rather than just adding parameters.