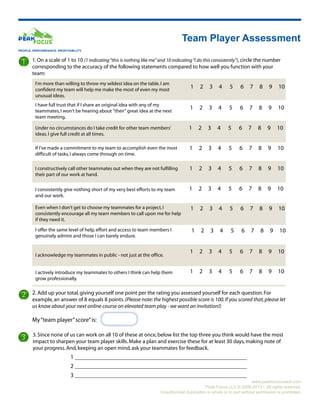
How to Actually Run a Qualities Of A Team Player Assessment Without Wasting Everyone's Time
The usual Qualities Of A Team Player Assessment gets run in a way that produces exactly zero actionable data. You send out a survey, everyone picks the middle option, and management files the results under "culture stuff" until the next hiring cycle. I watched this happen at a mid-size logistics company last year. They were trying to identify who should lead a cross-functional initiative and ended up promoting the person whose colleagues described them as "nice" and "responsive." That turned out to be the least effective leadership choice on the floor. What actually works comes down to three things: behavioral event sampling, forced discrimination in scoring, and source triangulation. Most organizations skip all three and wonder why the results look good on paper but fall apart in practice.
Qualities Of A Team Player Assessment: What It Should Actually Measure
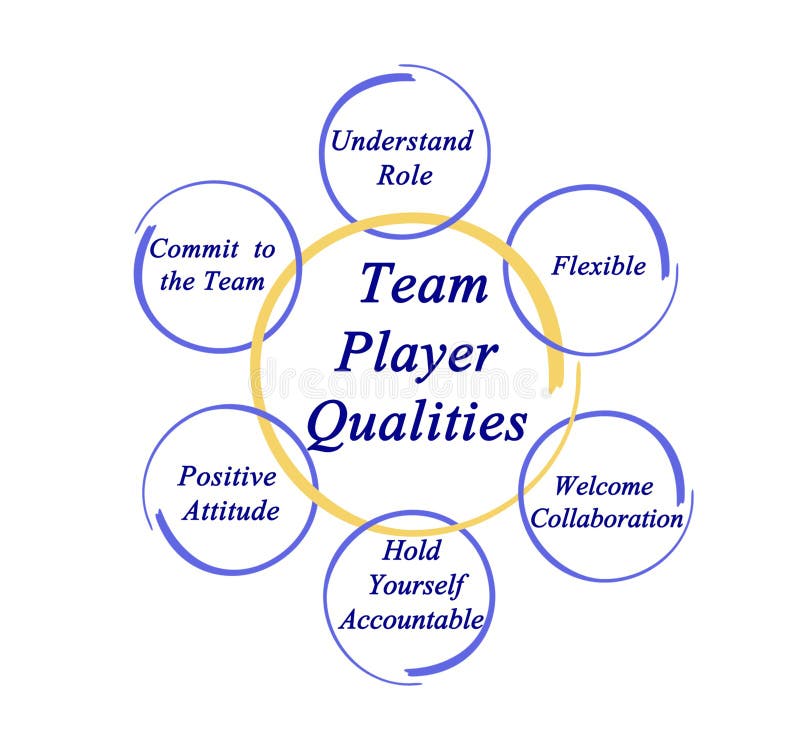
A team player isn't someone who is agreeable. Agreeableness is a personality trait. Being a team player is a set of observable behaviors that show up under specific conditions. The qualities that matter are conflict navigation, information sharing without being asked, willingness to absorb unplanned work, accountability when things break, and the ability to make other people on the team more effective without seeking credit for it. Here is the part people miss: low agreeableness does not equal poor team performance. I worked with an engineer who scored in the bottom quartile on every warmth metric but was consistently the most relied-upon person on the team because she never let ambiguity persist and would dismantle blockers before anyone else noticed they existed. If your assessment only measures how pleasant someone is, you are measuring the wrong thing.
The Method I Actually Use
The assessment I rely on is built around critical incident technique. Instead of asking "How often do you help others?" you ask respondents to describe three specific situations from the past quarter where a colleague's behavior directly affected the team's output, either positively or negatively. Then you code those responses against a rubric. The rubric has five dimensions: Information reciprocity: Does the person share relevant context proactively, or do they withhold it until asked? Information hoarding is the single strongest predictor of future team dysfunction that I have seen, and it rarely shows up on standard survey instruments.
Get the Full Details

Conflict orientation: When disagreements arise, does the person address the problem or sidestep it? People who avoid conflict entirely create more damage than people who engage poorly. Engagement, even when messy, keeps issues visible. Avoidance buries them. Workload flexibility: How does the person respond when assigned something outside their normal scope? This is not about compliance. It is about whether they evaluate the request against team priorities or treat everything as an interruption to their own work. Accountability framing: When failures occur, does the person default to external attribution or internal? This is different from blame-taking. People who absorb all blame become unreliable indicators because their self-assessment is corrupted by guilt. The useful signal is whether they can name their specific contribution to a failure without immediately pivoting to someone else's role.
Enablement behavior: Does the person actively remove obstacles for others? This is the quality that separates functional collaborators from cooperative performers. A cooperative performer does their part well. An enabler makes the people around them perform better. I score each dimension on a four-point scale. One means the behavior was absent or counterproductive across the incidents described. Two means it was inconsistent. Three means it was reliable. Four means it was the dominant pattern and extended beyond the required scope.
A Specific Problem I Ran Into and How I Fixed It
About two years ago, I was running this assessment for a client who was deciding whether to keep a senior analyst on a high-stakes project. The qualitative data from her peers was strongly positive. Her quantitative scores told a different story. She was averaging a two across five dimensions, which meant her behaviors were inconsistent but not systematically destructive. The discrepancy existed because she was operating in a matrix environment with competing managers. Her peers were describing her responsiveness to them specifically, while the rubric measures her contribution to the broader team system. When I pulled the raw incident descriptions and cross-referenced them with project timelines, the pattern emerged: she was highly responsive to her direct manager's requests and poorly responsive to cross-functional requests. Her scores were accurate. The initial reading was wrong because the data lacked context about reporting relationships. The workaround was straightforward. I added a contextual layer to the coding process that tagged each incident by whether it involved same-chain or cross-chain dynamics. Once that was done, the real issue became visible, and the client made a much better decision about role placement.
Common Pitfalls That Ruin This Kind of Assessment
Popularity bias is the biggest one. If you only collect self-assessments or single-source peer feedback, you are measuring social capital, not team contribution. Always use multi-source data. Direct reports, peers, and upstream stakeholders will give you three different pictures, and the gap between those pictures is where the actual insight lives. Recency distortion is the second one. People remember what happened in the last three weeks and weight it disproportionately. Require incidents from at least a ninety-day window and insist on specific dates. Vague references to "recent projects" get flagged and resubmitted. Leniency drift happens when the same group completes this assessment every quarter. Scores creep upward because people stop distinguishing between consistent reliability and occasional helpfulness. I reset the anchor examples every six months with fresh behavioral descriptions to keep the scale calibrated.
There is also a limit to what this tool can tell you. It does not predict cultural fit. It does not measure technical competence. It will not identify someone who is genuinely toxic if that person is skilled at managing up and curating their public interactions. I have seen people who scored in the bottom ten percent on this assessment still receive promotions because their visible output was strong and their managers had a confirmation bias toward keeping them. If your organization is using this assessment as a sole gate for promotion or termination decisions, you are exposing yourself to legal and operational risk. Use it as one input among several, alongside performance metrics, delivery records, and skip-level conversations.
What to Do With the Results Once You Have Them
Don't distribute individual scores. That creates defensiveness and destroys the psychological safety you are trying to measure. Instead, aggregate the data by team and present the patterns. Show where the team is strong and where it is thin. Then build development plans around the gaps, not the individuals. For people who score low on information reciprocity, the intervention is usually structural, not educational. They need clearer handoff points and shared documentation standards, not another workshop on communication. For people who score low on enablement behavior, the issue is often incentive misalignment. If their performance review is tied strictly to individual deliverables, no amount of coaching will change their behavior until the review criteria change. The assessment itself takes about twenty minutes to administer if you have a clean incident collection process. Coding takes longer, roughly an hour per fifteen respondents if you are doing it carefully. You can reduce coding time significantly by training two people to code independently and using inter-rater reliability checks to catch drift. A Cohen's kappa above 0.70 is acceptable. Below that, you retrain and recode.
This isn't a perfect tool. It won't capture everyone who is quietly holding a team together, and it will flag some people who are performing well within a narrow scope but don't operate effectively at the team level. But it is better than the alternatives, which are usually gut feeling and annual review cycles that nobody takes seriously.