Getting SPSS to actually do what you need
SPSS is still the default tool for a lot of social science and market research departments, even though half the people using it don't really understand what they're clicking through. The interface is dated, the menus are nested three levels deep, and if you've never used it before you will spend your first hour just trying to find where the recode function lives. But it handles a surprising amount of quantitative work without requiring you to write code, which is why it hasn't gone anywhere despite being around since 1968. I spent years running regression models and reliability tests in SPSS for organizational research, and the most frustrating part was always the same: the software would happily churn out output that looked correct until you actually read the fine print. I once ran a factor analysis that produced clean eigenvalues and a solid scree plot, only to realize I'd accidentally left a bunch of missing value codes in the dataset that SPSS was treating as actual data points. The whole solution shifted when I flagged those properly and re-ran it. That happens more often than people want to admit.
Quantitative Data Analysis With Spss
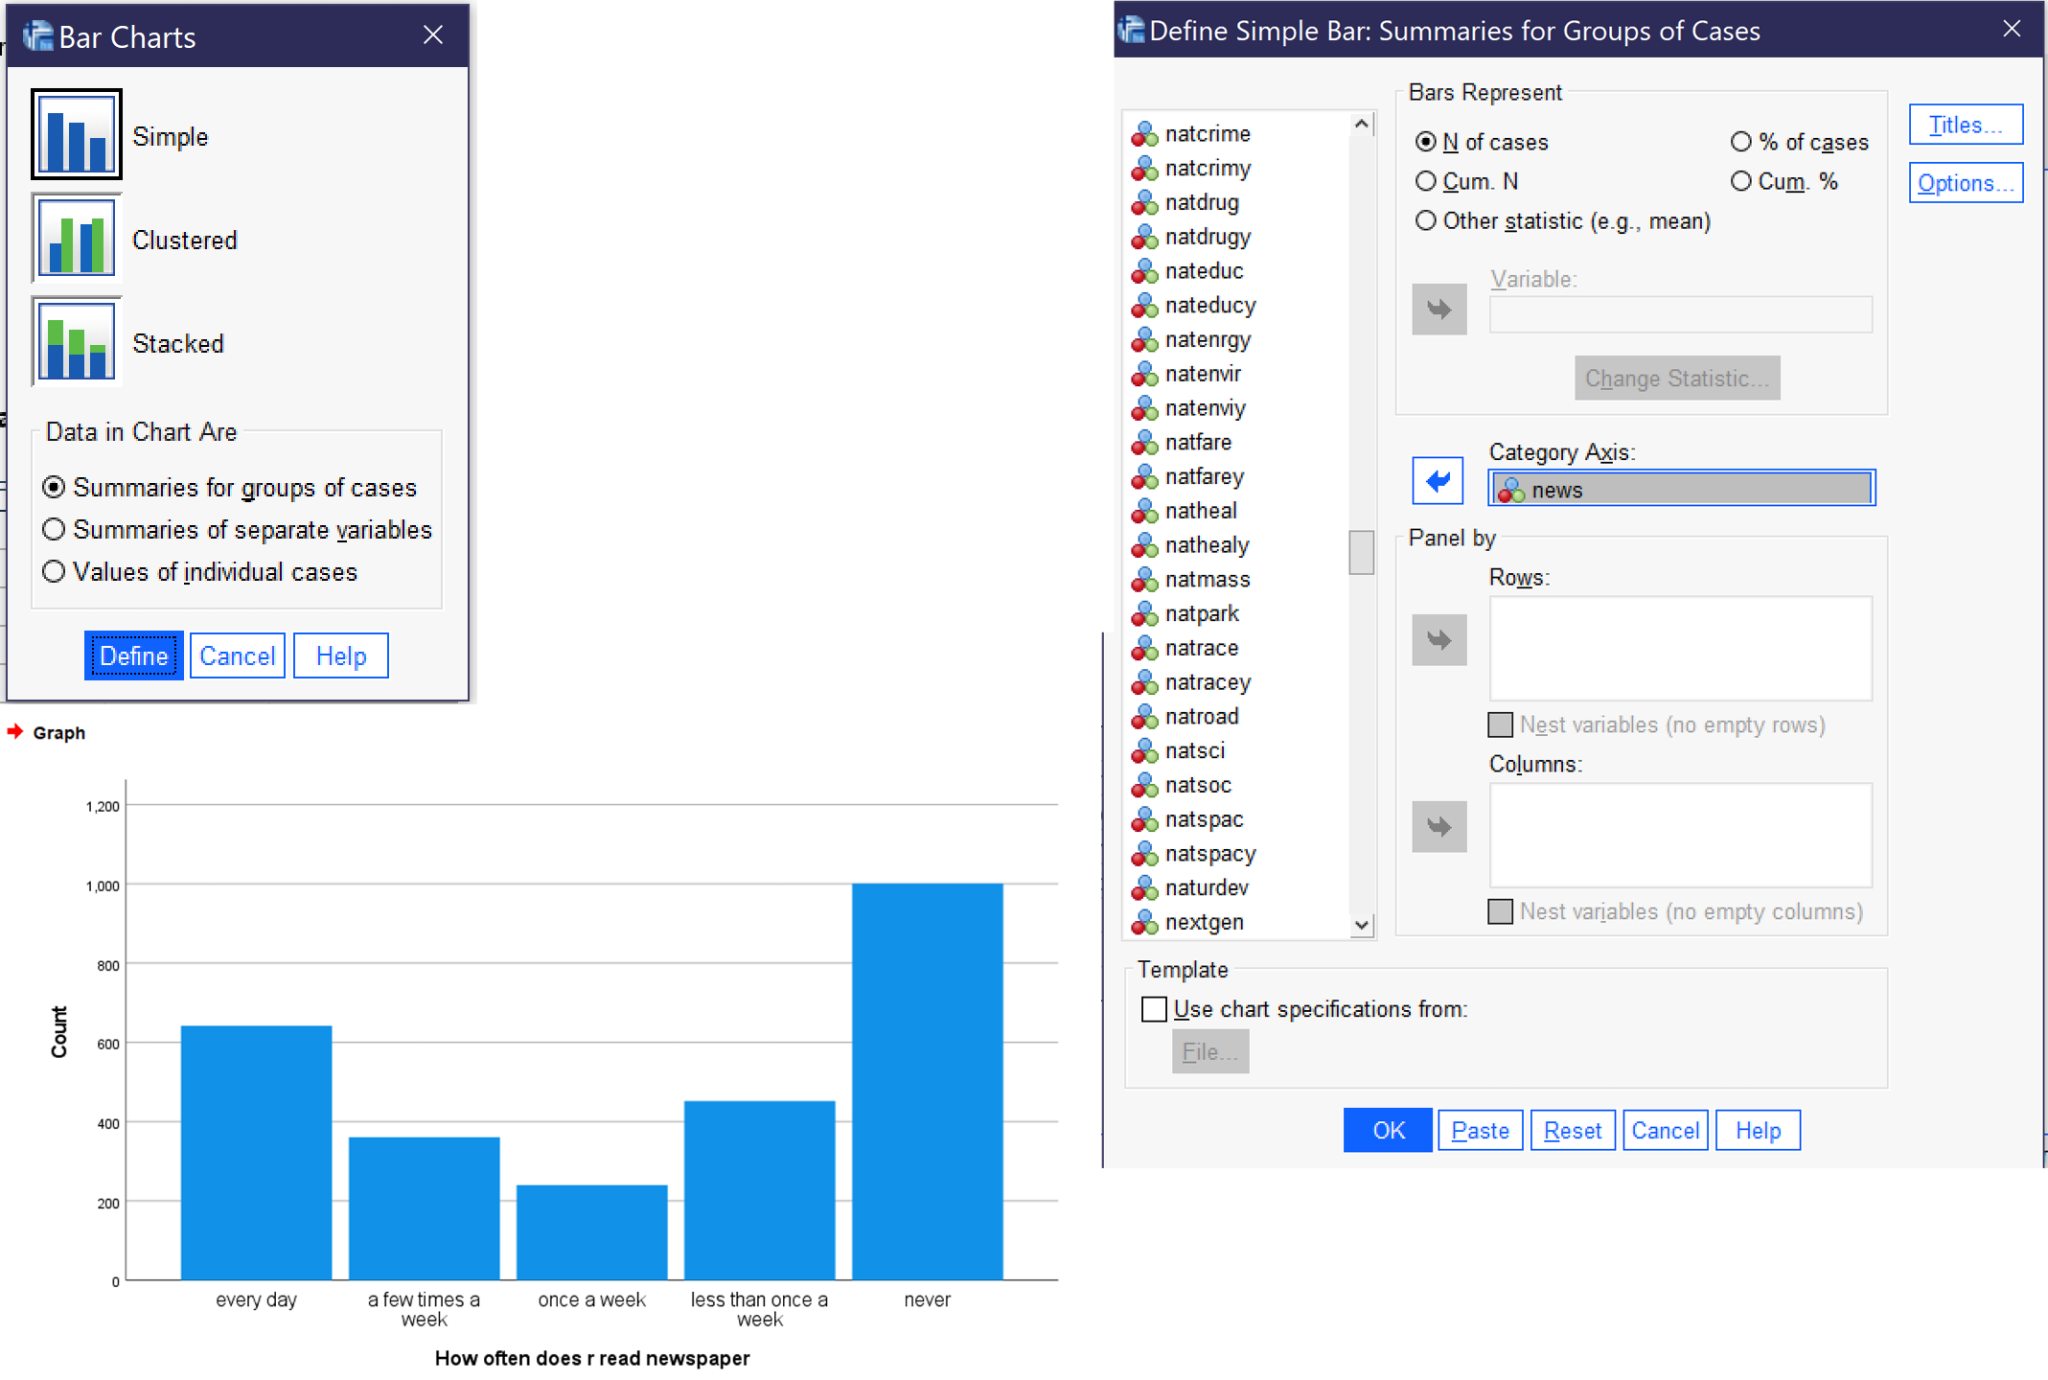
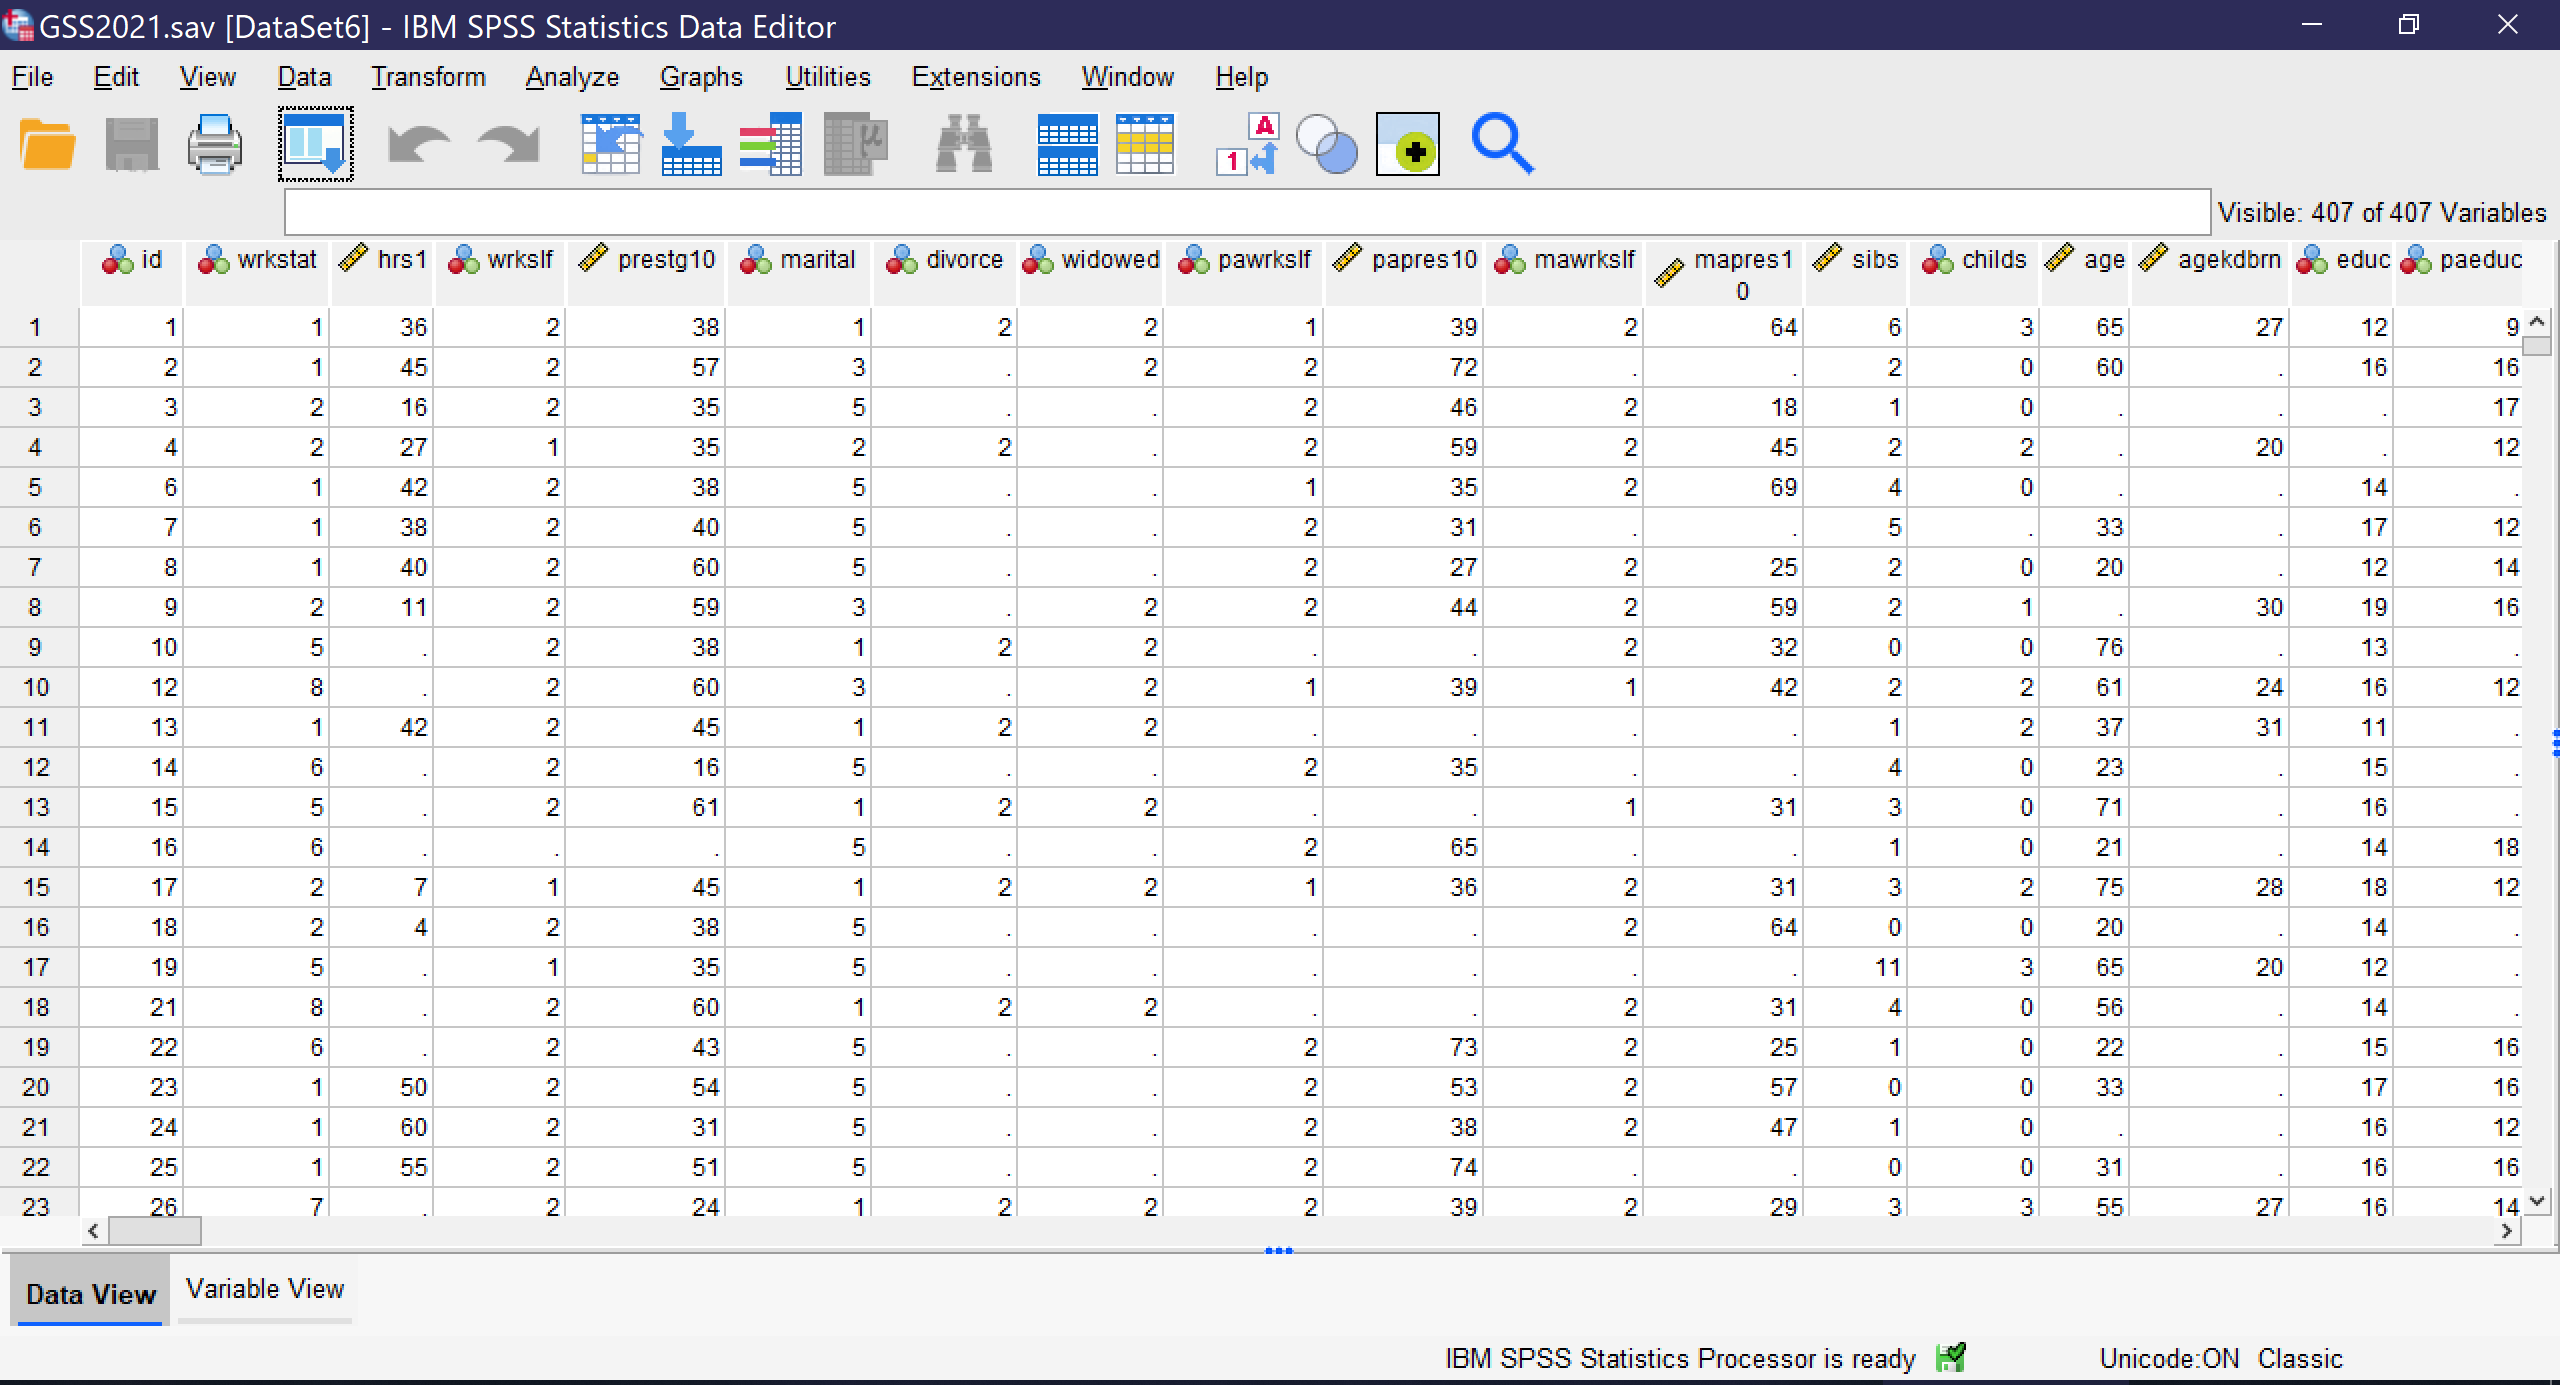
At its core, SPSS is a menu-driven statistical package designed for survey-style data. You import a dataset — usually a CSV, Excel file, or SPSS native format (.sav) — define your variables in the Variable View tab, and then move to the Data View tab where your actual numbers live. The separation between variable definitions and data values is one of those design choices that feels clunky at first but actually prevents a lot of errors once you get used to it. Setting your measurement levels correctly in Variable View (numeric, ordinal, scale) changes what analysis options show up in the menus later, so getting that step right matters more than people realize. The basic workflow goes like this: clean your data first, which means checking for duplicates, handling outliers, and deciding how to treat missing values. Then run your descriptive statistics — means, standard deviations, frequencies — because you should always look at your data before throwing inferential tests at it. After that you pick your analysis based on your research question. T-tests for group differences, chi-square for categorical relationships, regression for prediction, ANOVA when you have more than two groups. Each of these lives under Analyze in the top menu, and each produces output in a separate window called the Viewer. One thing beginners consistently mess up is the syntax. SPSS generates syntax automatically whenever you run a procedure through the menus, and this isn't just a convenience feature. If you ever need to rerun the exact same analysis on a updated dataset, or apply identical steps to multiple variables, the syntax saves you from clicking through menus repeatedly. I started using syntax-driven workflows exclusively after one project required me to run the same logistic regression on 47 different dependent variables. Doing that through menus would have taken all afternoon. I wrote one block of syntax and set it to loop through the variables, and it finished in about twelve minutes.
Practical details that aren't in the manual
There are a few SPSS behaviors that will catch you off guard if nobody tells you about them. First, SPSS treats system-missing values differently from user-defined missing values. If you leave a cell blank, SPSS marks it as system-missing, which most analyses handle correctly by excluding it. But if you've coded "999" or "-1" as a meaningful response category and then later decide it should be missing, you need to explicitly define it in Variable View under the Missing Values column. Otherwise SPSS will include those 999s in your calculations and your mean will be completely wrong. I learned this the hard way on a project where half the participants had skipped a demographic question and it was coded as 999 instead of truly missing. My age statistics were garbage until I caught it. Another thing worth noting is how SPSS handles pairwise versus listwise deletion. When you run a correlation matrix, SPSS uses pairwise deletion by default, meaning it includes every case that has data for the two variables in question. This can produce a correlation matrix where the N varies across cells, which is fine statistically but confusing if you're not expecting it. Listwise deletion, which removes any case missing data on any variable in the analysis, is more conservative and usually what you want for regression, but SPSS doesn't always apply it consistently across procedures. You have to check each output carefully. Reliability analysis in SPSS is straightforward — your Cronbach's alpha values come out with minimal effort — but the software doesn't tell you much about why a scale might have low reliability. It will give you the alpha if you delete each item, which helps you identify problematic items, but it won't explain whether the problem is poor item-total correlations, low variance, or something else. I've seen people abandon perfectly good scales because the overall alpha was borderline, not realizing that the issue was a single poorly worded item that could have been fixed with a quick reword rather than removal.
Get the Full Details
For multivariate work, SPSS can handle MANOVA, discriminant analysis, and clustering, but the output is dense and easy to misinterpret. The assumption testing is somewhat buried — you have to request it explicitly in most procedures — and SPSS won't warn you if your sample size is inadequate for the number of predictors you're using. Rule of thumb is at least 10 to 20 cases per predictor variable, but SPSS will happily run a regression on a dataset that violates this and give you output that looks professional but is statistically unstable. I once saw a published study with about fifteen cases per predictor that used twelve predictors in a single model. The effect sizes were enormous and the model was fundamentally unreliable.
Where SPSS falls short
SPSS is not the right tool for everything. If you're working with longitudinal or hierarchical data, you're better off using something like R, Stata, or HLM that handles mixed-effects models natively. SPSS has a vague attempt at generalized estimating equations and some basic multilevel options, but they're limited and poorly documented. For structural equation modeling, SPSS's AMOS extension exists but it's expensive and the syntax-free approach doesn't scale well beyond simple models. For text analysis, machine learning, or anything involving big data, SPSS isn't even in the conversation. The software also struggles with reproducibility. While syntax helps, the point-and-click workflow that most users rely on leaves no audit trail. Two people running the same analysis through menus might end up with different results if they chose different options for missing value handling or outlier treatment without realizing it. This is a real problem in academic publishing where reviewers increasingly demand methodological transparency. I've switched most of my work to R precisely because the code itself is the documentation, but SPSS still has a place for quick analyses and for departments that don't have the staffing to maintain a coding workflow. If you're new to this, start by installing IBM SPSS Statistics — it's commercial software with a demo available on their website, and most universities provide licenses for students. Import a small dataset and practice defining variables, running frequencies, and creating basic graphs. Don't jump into regression until you can comfortably navigate the interface and understand what each output table is telling you. The software will give you numbers fast, but it won't teach you statistics. Knowing when not to run a test is more important than knowing how to run one.