Why your risk numbers are lying to you
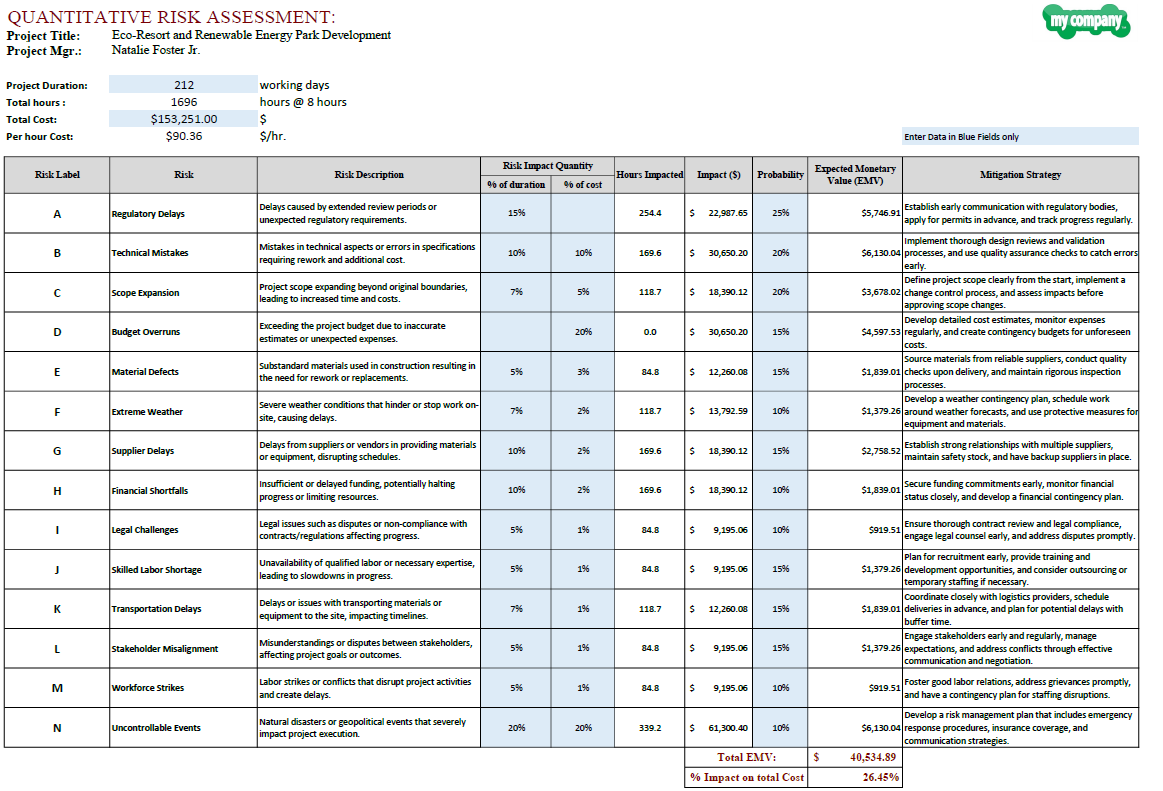
I spent three years building quantitative risk models for a mid-size fintech before we shut the project down. Not because the math was wrong, but because nobody understood what it was actually telling them. That's the problem with a Quantitative Risk Assessment Example that looks clean on paper but falls apart in practice. The method itself is straightforward. You assign numbers to risks instead of tagging them high, medium, or low. High and low are opinions. Numbers at least force you to commit to a position.
Working Quantitative Risk Assessment Example for Payment Fraud
Let me walk through one I actually used. We were assessing fraud risk on a card-not-present payment gateway handling roughly 40,000 transactions per day. The board wanted a single dollar figure for annual expected loss so they could decide whether to buy insurance or invest in detection tools. We started with three variables per risk scenario: the annualized rate of occurrence and the average loss magnitude if that scenario materializes. ARO comes from historical data when you have it. Loss magnitude comes from incident reports, payout records, regulatory fines, and remediation costs. Multiply them together and you get the annualized loss expectancy for that scenario. Our base scenario was friendly fraud, where a legitimate cardholder disputes a charge after receiving the product. Historical data from the previous two years showed about 2.3 percent of transactions fell into this bucket, with an average dispute value of $87. That gave us an ALE of roughly $74,000 per year. Simple enough.
The second scenario was credential stuffing attacks hitting our login endpoint. We estimated an ARO of 4 occurrences per year based on our SIEM logs, with an average loss of $310,000 per incident when you factor in account takeovers, payout fraud, and the operational cost of investigation and remediation. That's $1.24 million in annualized loss expectancy for that single risk category. The third scenario was a compromised API key being used to drain merchant balances. We had no historical precedent for this, so we used a triangular distribution with a low estimate of $50,000, a most likely estimate of $400,000, and a high estimate of $2.1 million based on similar incidents at peer companies. We modeled it at 0.3 occurrences per year. That landed us around $378,000 in ALE. Add those up and the total annualized risk exposure came to roughly $1.69 million. The insurance policy we were considering covered up to $500,000 with a $75,000 deductible. The gap between what insurance would pay and our actual expected loss was the decision point. We chose to invest in a behavioral biometrics layer instead, which our model predicted would reduce the credential stuffing ARO from 4 to 1.2 per year, dropping total expected loss to about $920,000 annually. The tool cost us $180,000 per year to operate. The math supported the investment by a comfortable margin.
Get the Full Details

The methodology you actually need
There are a few standard approaches and most people pick the wrong one without realizing it. The first is the pure frequency-severity model, which is what I just described. You estimate how often a risk event happens and what it costs when it does. This works well when you have historical data. It falls apart when you're assessing novel risks like a new attack vector you've never seen before. In those cases you're essentially guessing with confidence intervals, and the output looks more precise than it actually is. The second approach is Monte Carlo simulation. You define probability distributions for each variable instead of point estimates and run thousands of iterations to generate a range of possible outcomes. This is the more honest approach because it shows you the variance, not just a single number. The downside is that garbage in still gives you garbage out, just with prettier histograms. If your input distributions are poorly calibrated, the simulation just spreads the error across more output scenarios.
The third approach is fault tree analysis combined with quantitative leaf estimation. You map out the logical pathways that lead to a risk event and assign probabilities to each branch. This is useful for complex dependent risks where one failure triggers another. It's also labor-intensive and easy to mess up if you miss a dependency path. I've seen teams spend six weeks building a fault tree only to discover they'd omitted a critical intermediate node that accounted for 40 percent of the modeled risk. For most organizations, I'd recommend starting with the frequency-severity model and layering in Monte Carlo once you have enough data to justify it. Fault tree analysis is worth the effort only if you're dealing with highly interdependent systems where cascade failures are a real concern.
What nobody tells you about building these models
Here's the thing that trips people up. The biggest source of error isn't the math. It's the input data. I've seen risk assessment teams pull ARO numbers from industry reports that were two years old and applied to a completely different business model. They'd calculate a precise-looking ALE and present it as fact. The precision is misleading. The inputs are noise. Another common mistake is ignoring correlated risks. If you model fraud and account takeover as separate independent events, you're overstating the total risk because they share common root causes. A single compromised employee credential can trigger both scenarios simultaneously. When you treat them as independent, your model counts the overlapping damage twice. You need to build in correlation coefficients or at least acknowledge the dependency explicitly. Then there's the cost of risk mitigation. People forget to subtract the cost of the controls themselves from the risk reduction benefit. A detection system that costs more than the losses it prevents is a net negative. I watched a compliance team recommend a $2.4 million SIEM upgrade that their own model showed would only prevent $600,000 in annual losses. The numbers didn't support the spend, but the presentation made it look reasonable because they focused on the tail risk reduction instead of the expected value calculation.
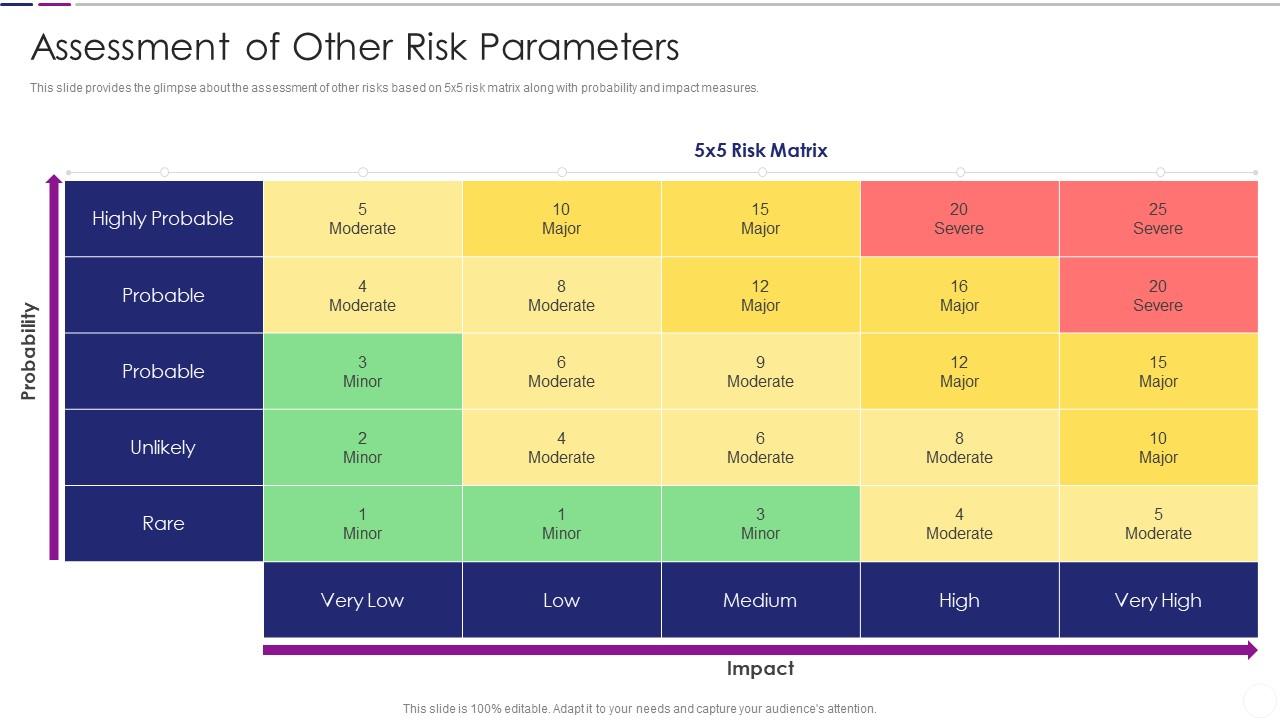
One practical workaround I developed for the input data problem is to maintain a living risk register that gets updated quarterly with actual loss data, not just theoretical estimates. Every incident that occurs, no matter how small, gets logged with its true cost including indirect factors like engineer time, customer support escalation, and reputation impact. After 18 months of this, your ARO and severity estimates start reflecting reality instead of whatever your last risk workshop produced.
When quantitative risk assessment fails completely
This method breaks down in a few specific scenarios and you should know about them before you commit to it. First, it fails for black swan events with zero historical precedent and no reasonable analogy. The 2021 Colonial Pipeline ransomware attack is a good example. There was no prior incident in the pipeline sector with comparable economics. Any quantitative model built before that event would have produced a number that was confidently wrong. For these situations, qualitative scenario planning and stress testing are more appropriate, even if they feel less rigorous. Second, it fails when the cost of implementing controls exceeds the organization's ability to pay for them. A model might tell you that your annualized risk exposure is $12 million and that investing $8 million in controls would reduce it to $2 million. The math looks good on paper. In practice, no board approves an $8 million capex request based on a model output, especially when the $12 million exposure is probabilistic, not guaranteed. Sometimes you have to accept the risk or transfer it through insurance, even if the numbers suggest otherwise.
Third, it fails in highly dynamic environments where the risk landscape changes faster than your model can be updated. If you're assessing risks for a new product line that ships monthly features, your ARO and severity estimates will be stale within weeks. In those cases, continuous monitoring and automated risk scoring are more practical than a quarterly or annual quantitative assessment exercise. The honest takeaway is that quantitative risk assessment is a tool for making better decisions, not for producing the right answer. The output is only as good as your inputs and your assumptions. Treat it as a structured way to surface uncertainty rather than a magic calculator. The organizations that get the most value out of it are the ones that update their models regularly and treat the results as hypotheses to test, not conclusions to accept.


