Building Something That Actually Works
Most people approach quantitative trading with the wrong assumption. They think it is about finding the one perfect indicator or chasing accuracy on historical data. It is not. It is about building systems that remain slightly profitable after every possible real-world friction is subtracted from the theoretical edge. I spent three years trying to make momentum-based strategies work before I figured that out. The strategies looked fine on paper. They lost money in practice because I kept forgetting about slippage on illiquid names and the way execution algorithms move against you during volatile sessions.Starting Your First Quantitative Trading Strategies Project
The first thing you need is clean data. Not the kind you download from a free API. I mean data with survivorship bias removed, adjusted for splits and dividends, and with enough depth to test across multiple market regimes. Most retail tools give you survivorship-biased data that makes your backtest look great until you try it live. Get your data pipeline right before you write a single line of strategy code. A proper setup with corrected historical data takes about a week to build if you know what you are doing. From scratch, plan on two to three weeks of frustrating data wrangling.My approach is to use raw tick data from brokers or providers like Polygon, Stack, or Alpaca for equities, and then aggregate it myself into whatever timeframe my strategy requires. This gives me full control over how I handle missing bars, corporate actions, and timestamp alignment. Skipping this step is the most common reason retail backtests fail in production.
The Execution Reality Check
Here is a specific problem I ran into that took me months to debug. I built a mean-reversion strategy on mid-cap stocks that showed a sharp edge in backtesting. But the live results were terrible. The strategy would buy and immediately drift against me by 30 to 80 basis points. I thought the market had become inefficient. It had not. The issue was that my backtest executed fills at the midpoint of the bid-ask spread. In reality, when I was buying across 20 positions in a single rebalance window, I was moving the market. My own orders were creating the slippage I was not accounting for. The workaround was brutal but simple. I added a market impact model based on volume participation. Instead of assuming I could buy any quantity at the observed price, I modeled impact as a function of my order size relative to the average daily dollar volume. This cut my backtest returns by roughly 40 percent, which was exactly what I needed to see. The strategy still worked after that adjustment, but barely. That narrow margin forced me to redesign the entry logic entirely, which ended up being the better outcome anyway.Core Components You Cannot Skip
A working quantitative system rests on four components. They all need to be solid independently before you combine them. Weakness in any one of them will break the whole thing.Data and Signal Generation
The signal is your prediction. It can be anything from a simple moving average crossover to a machine learning model predicting next-day returns. The critical detail most people ignore is regime detection. A signal that works in low-volatility trending markets often fails catastrophically in high-volatility mean-reverting environments. I always include a volatility regime classifier in my pipelines. The simplest version uses the 20-day standard deviation of returns relative to a rolling 12-month distribution. If the current reading is in the top quartile, the model switches to a different set of parameters or stops taking new signals entirely. This alone prevented several blow-ups in my own book during the 2022 rate-hike cycle.You should also normalize your features properly. Raw price values are not useful across different stocks. Use z-scores, rank normalization, or percentile ranks within a lookback window. This makes your signal portable across assets and time periods, which matters when you are testing across 500 or more securities.
Risk Management and Position Sizing
This is where most strategies actually survive or die. Not the signal. The risk layer. I use a combination of volatility targeting and Kelly fraction sizing with a strict cap. Volatility targeting means adjusting position sizes so that each trade contributes roughly equal risk. If stock A has twice the volatility of stock B, I hold half as many shares of A.The Kelly fraction tells you the theoretically optimal bet size based on your edge and the variance of your edge. But full Kelly is dangerous in practice because it assumes your edge estimate is perfect. It is never perfect. I use quarter-Kelly as my starting point and then apply a hard maximum portfolio exposure rule. Total portfolio beta stays below 1.2 at all times. Individual position size never exceeds 5 percent of net asset value. These are boring rules. They kept me alive.
Get the Full Details
Backtesting Framework
Do not use an online backtester for serious work. Tools like QuantConnect are fine for quick experiments, but they abstract away too much of the execution reality. I use a Python-based custom framework built around pandas and NumPy, with event-driven execution simulation. It takes longer to build. The resulting backtest is meaningfully more accurate.Key parameters you must get right in your backtest: commission per trade, minimum price tick, fill latency simulation, partial fill probability, and capital allocation between rebalances. A backtest without a realistic commission model on a strategy that trades frequently is just entertainment. At typical retail commission rates and a conservative slippage estimate of 2 to 5 basis points per trade, a strategy turning over 50 times per year loses a significant chunk of gross alpha before it even hits the market.
Live Deployment and Monitoring
Deployment is a separate discipline from strategy development. You need a production environment that handles missing data gracefully, enforces position limits automatically, logs every decision, and alerts you when something deviates from expected behavior. I run my strategies through a staging environment that mirrors production data feeds and connectivity but uses paper trading execution. I run it side by side with a live account for at least 30 trading days before committing real capital. During that period, I track the drawdown between the live signals and the paper execution. Anything above 10 basis points per trade in discrepancy tells me there is an infrastructure problem I need to fix before going fully live.Common Mistakes That Waste Months
Overfitting is the obvious one. But the more insidious version is path-dependent optimization. You optimize a strategy for one specific historical period and then wonder why it fails when market structure shifts. The 2020 pandemic crash, the 2021 meme stock frenzy, the 2022 quant crash. These events changed liquidity dynamics, correlation structures, and execution costs in ways that invalidated models trained on pre-2020 data. A practical defense is walk-forward testing. You optimize on an in-sample window, test on an out-of-sample window, then roll both windows forward in time and repeat. If your strategy degrades significantly between in-sample and out-of-sample performance, it is overfitted. The ratio of out-of-sample to in-sample Sharpe should be above 0.7 for a strategy to be worth considering further. Below 0.5, scrap it and start over.Another mistake is ignoring transaction costs in the strategy design phase. I have seen people optimize a high-frequency reversion strategy that generates 15 basis points of edge per trade while incurring 12 basis points in round-trip costs including slippage. The backtest shows profit. Live it is a slow bleed. Build cost awareness into your optimization objective. MaximizeSharpe ratio after costs, not before.
What Quantitative Trading Strategies Can and Cannot Do
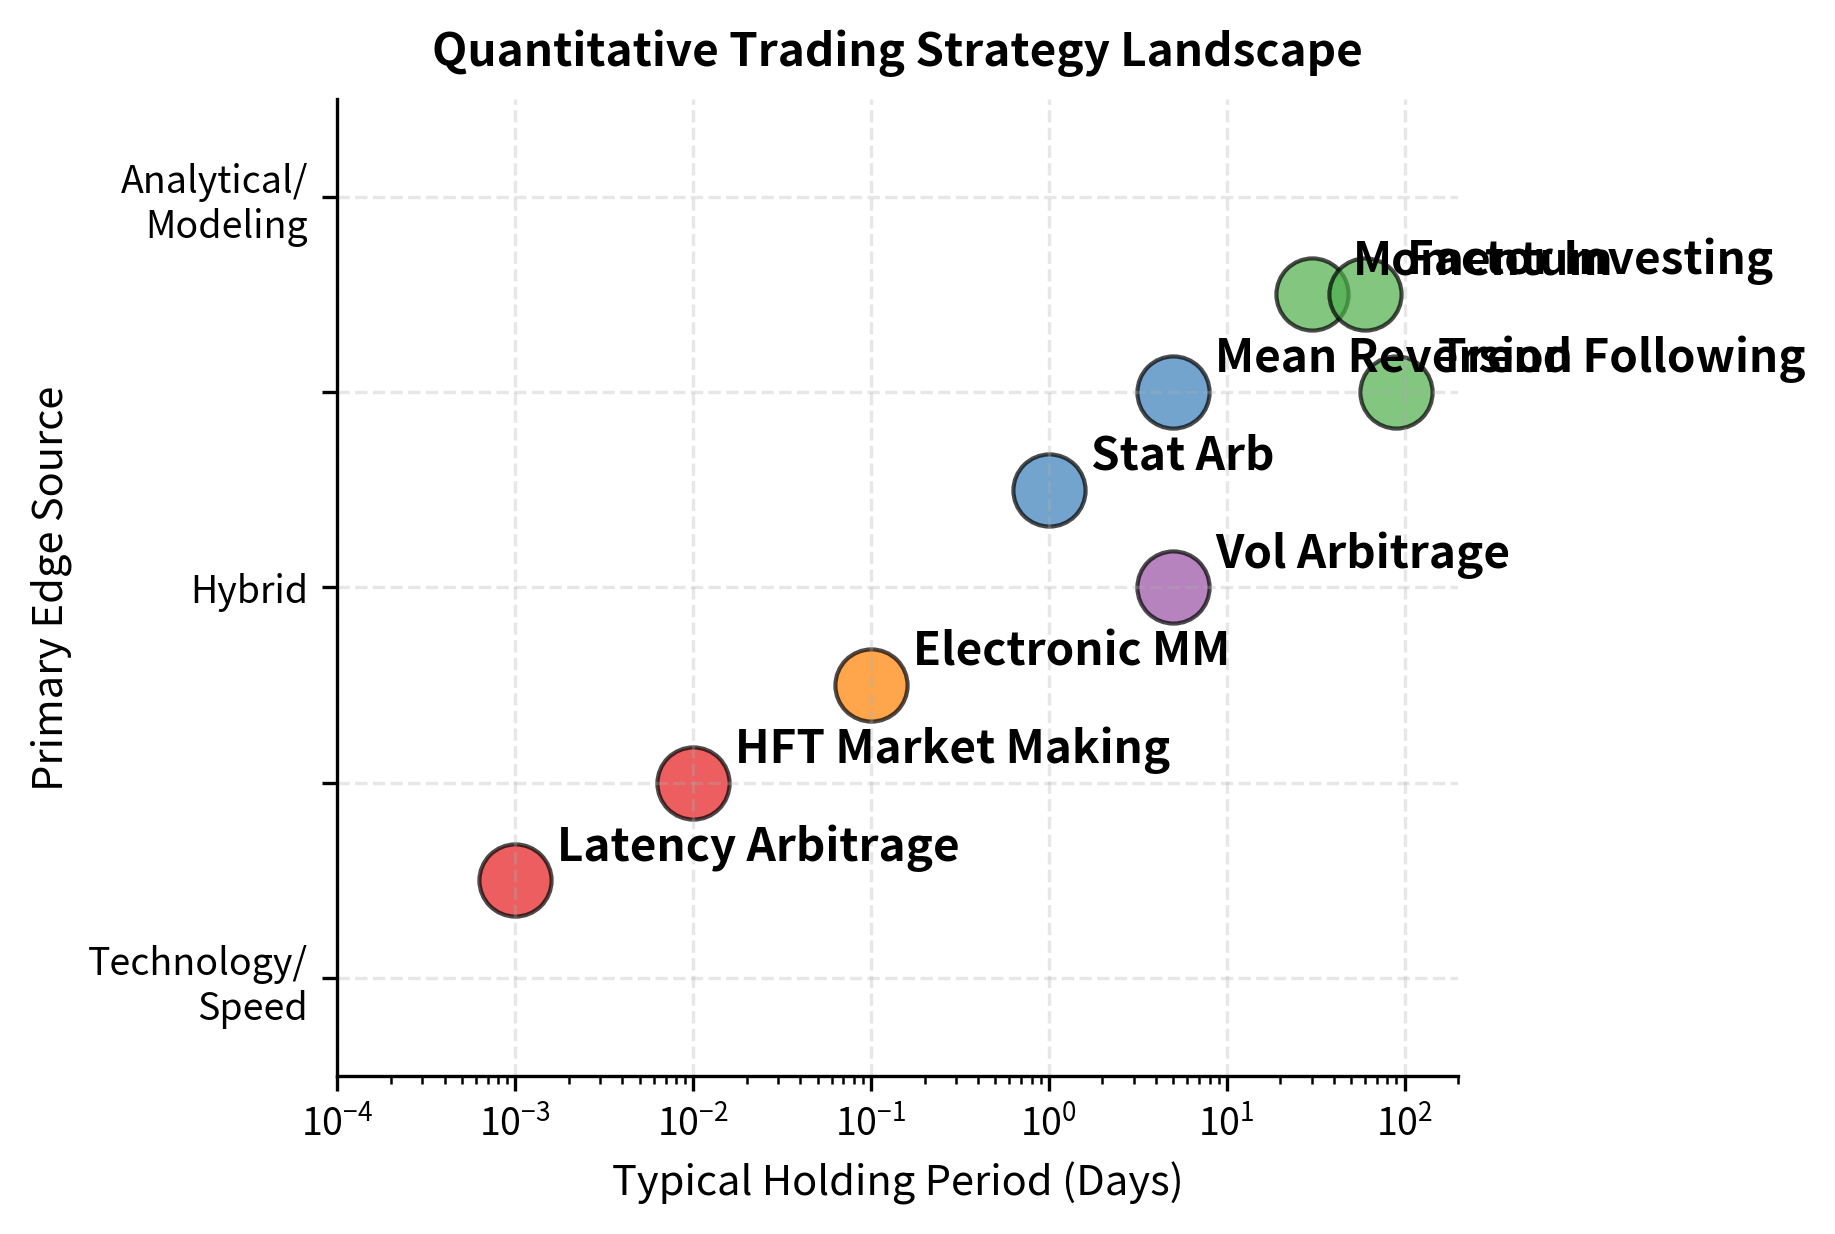
They cannot guarantee profits. They cannot replace human judgment on market structure changes. They fail in regime shifts that are unlike anything in the training data. A strategy trained on five years of data will struggle during a structural break in volatility regime or liquidity conditions that did not exist during that window. Quantitative Trading Strategies work best when they target edges that are mechanically driven rather than sentiment-driven. Market-making arbitrage, statistical arbitrage between cointegrated pairs, and factor-based strategies that exploit structural demand imbalances tend to be more robust than discretionary signal-based approaches. Mechanical edges persist because they are rooted in market microstructure, not in human psychology.I once tried to build a sentiment-based strategy using news NLP models. The signals looked promising in backtest. They collapsed in live trading within three weeks because other participants had already identified and front-run the same patterns. The edge was arbitrated away faster than I could respond. Factor-based approaches do not face the same speed of decay because the edge comes from structural factors like size, value, and quality premiums that persist across decades.

Tools and Resources
For data, Polygon.io and Alpha Vantage are reasonable starting points for retail traders. Institutional-grade data comes from Bloomberg, FactSet, or Tick Data Services, but those require significant budget. For backtesting, I recommend building your own pipeline with Python libraries. Backtrader is decent for simpler strategies. Zipline is good if you are coming from the Quantopian ecosystem. For production systems, a custom framework with event-driven architecture is worth the development time.Portfolio analytics and risk monitoring can be handled with pyfolio or custom dashboards. I use a combination of Grafana for real-time PnL visualization and PostgreSQL for storing all trade-level history. This makes it possible to trace any trade back to its originating signal, the market conditions at execution time, and the actual fill versus expected fill comparison.
The honest truth is that building a profitable quantitative trading system takes significantly more engineering discipline than most people expect. The alpha is rarely in the signal. It is in the details nobody talks about: data cleaning, realistic cost modeling, proper regime handling, and ruthless process discipline. The systems that survive are usually the most boring ones built by people who spent more time fixing infrastructure than chasing new signals.