What You Actually Need To Know Before Using This
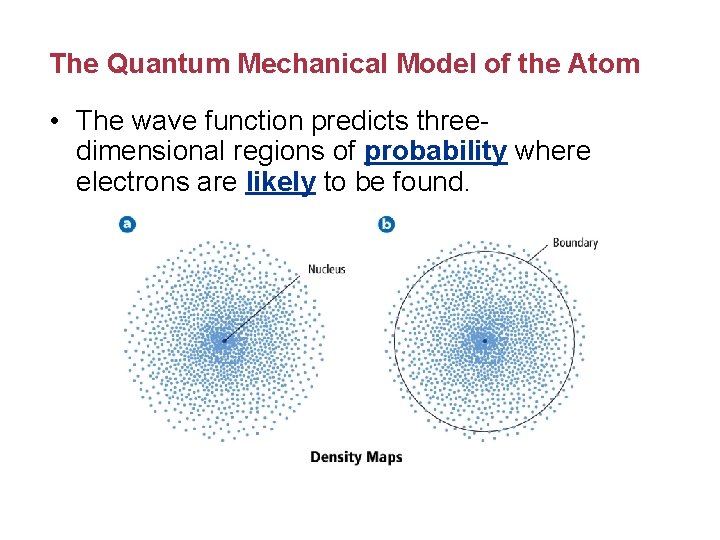
The Quantum Mechanical Model Of The Atom isn't something you learn once and move on from. It keeps revealing new complications every time you try to apply it to real molecules. I spent years trying to get reliable results from it in computational chemistry work before I stopped fighting the model and just learned how to work with its actual behavior. The Schrödinger equation still doesn't have a general closed-form solution for anything beyond hydrogen, so every application is an approximation of some kind. That fact alone determines everything about how you use this. When I first tried using Hartree-Fock calculations on a small organic molecule, I got results that looked wrong at first glance. The electron density plots showed unexpected asymmetry around the central atom. It took me two weeks to realize the problem wasn't the code or the basis set — it was that I had chosen a restricted open-shell approach for a system that needed unrestricted treatment. The model itself wasn't broken. My choice of how to approximate it was. That experience taught me to check the spin state and the multiplicity before running anything.
Getting Started With The Quantum Mechanical Model Of The Atom
You need to decide what level of theory you're working at, because that decision cascades through everything else. A minimal basis set like STO-3G will give you quick results but the numbers are rough. A triple-zeta basis set with polarization functions like 6-311G is more realistic for actual work. The computational cost scales badly with system size, so there's a real tradeoff here. For a molecule with about 50 atoms, a moderate basis set on a decent machine might take a few hours. A large molecule with a large basis set could run days or weeks. The practical workflow usually goes like this. You start with a molecular geometry. That can come from X-ray crystallography data, from literature values, or from a molecular mechanics pre-optimization. You feed it into your quantum chemistry package. Gaussian, ORCA, and Q-Chem are the main options most people use. You specify the method, the basis set, and any constraints you need. Then you run the calculation and examine the output. One thing beginners consistently miss is that the output file contains far more information than what shows up in the summary. The raw orbital energies, the convergence history, the integral values — all of that matters if your calculation behaves strangely. I once wasted an entire day troubleshooting poor convergence before checking the SCF cycle log and realizing the initial guess was poorly constructed. Switching to a core Hamiltonian guess instead of the default fixed kernel guess fixed it immediately. The default guess is convenient but not always appropriate.
Another common pitfall involves the treatment of solvent effects. Gas-phase calculations give you one set of results. Solvent models like PCM or SMD shift things significantly for charged or polar systems. If you're comparing to experimental data, you almost certainly need to include solvent. Running a calculation without it and then wondering why your energies don't match measured values is a very common mistake I see repeatedly.
Get the Full Details

Where This Model Breaks Down
Despite how often it appears in textbooks, the Quantum Mechanical Model Of The Atom has well-defined failure modes that nobody talks about enough. The single-reference methods like Hartree-Fock and standard DFT assume one dominant electron configuration. When you have near-degenerate orbitals, which happens with transition metals and certain radical species, those methods produce unreliable results. Multi-reference methods exist but they're computationally expensive and harder to set up correctly. The accuracy of DFT depends entirely on which functional you choose, and there's no single functional that works well across all chemical systems. This isn't a minor issue. It's a fundamental limitation. Van der Waals interactions are another area where standard approximations fail. Most common functionals don't capture dispersion forces properly. If you're studying things like pi-stacking or molecular crystals, you need a DFT-D correction or a specialized functional. Adding a semi-empirical dispersion correction typically takes very little extra computation time but can change your binding energies by tens of kilojoules per mole. The computational cost is probably the biggest practical bottleneck. Full configuration interaction is exact but scales factorially with system size, making it impossible for anything beyond tiny systems. Coupled-cluster methods like CCSD(T) are considered the gold standard for single-reference systems but scale as N^7. That means doubling your system size increases computation time by roughly a factor of 128. There are useful approximations and local correlation methods that help, but the scaling problem is real.
If you're working with large biomolecules or materials, periodic boundary conditions and plane-wave basis sets become relevant. Programs like VASP and CP2K handle this differently than the Gaussian-type basis set approach. Mixing the two approaches because you found a paper that used both is a bad idea. They have different conventions for energy references and everything else.
Practical Tips From Working With This Daily
Always verify that your calculation converged properly. Check the final energy, look at the orbital occupations, and make sure the density didn't oscillate wildly during the SCF cycle. A converged calculation with clearly wrong results is more dangerous than a non-converged one because you might trust the output without questioning it. When comparing relative energies, always use the same method and basis set consistently. Mixing a DFT energy with a Hartree-Fock energy and treating them as comparable is a fundamental error. Energy differences only make sense within a single theoretical framework. This sounds obvious but it's surprisingly common in the literature. Thermochemical analysis requires more than just the electronic energy. You need to account for zero-point vibrational energy, thermal corrections, and entropy. These come from a frequency calculation, which also tells you whether your geometry is actually a minimum or a transition state. If you have imaginary frequencies, your structure isn't stable. The number and magnitude of imaginary frequencies tells you what kind of mode is problematic.

For people just starting out, I'd recommend beginning with small, well-characterized molecules where you can compare your results to known experimental values. Water, ammonia, benzene — these have been studied extensively and serve as good validation cases. Once you're confident your setup produces reasonable numbers, you can move to more complex systems. Skipping this validation step leads to unreliable results that are hard to diagnose later. The field is moving toward increasingly accurate methods but the fundamental challenges remain. Linear-scaling methods and machine learning potentials show promise for larger systems, but they introduce their own uncertainties. The Quantum Mechanical Model Of The Atom continues to be the foundation of computational chemistry even with all its imperfections, because nothing else comes close for most applications. Understanding what it can and cannot do reliably is what separates useful results from noise.