Getting code out the door without breaking everything
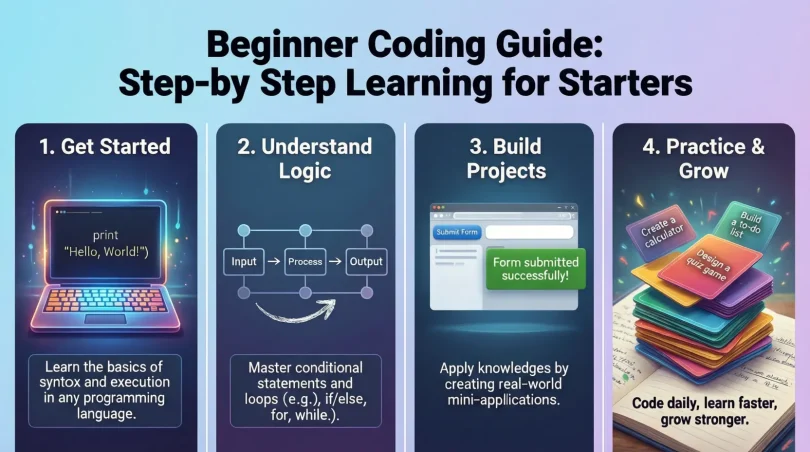
Most people treat "write it fast" and "write it right" as opposite goals. They aren't, once you stop trying to skip the boring parts. Quick Coding Step By Step is really just a structured way of moving from problem statement to working code in under an hour, without the refactoring debt that normally follows. The trick isn't speed. The trick is not lying to yourself about what stage you're in. It's a five-step workflow: define the input and output before touching a keyboard, sketch the control flow on paper, write the dumbest possible version that satisfies both, fill in the gaps, then test against edge cases you deliberately make uncomfortable. That's it. No framework decisions upfront, no architecture meetings, no dependency research at step one. You earn the right to make those calls after you've proven the core logic works. I learned this the hard way. About three years ago I was building a small ETL pipeline for a client who needed daily CSV imports processed through some custom business rules and loaded into PostgreSQL. I spent two days deciding between Airflow, Prefect, and just writing a bash script with Python underneath. The pipeline ended up taking four days to deliver, and half that time was me uninstalling and reinstalling orchestration libraries. If I had followed the five steps straight through, it would have been a single 90-minute session. The script still runs in production today.
The five steps, explained like you're actually doing them
Step one: input and output on paper
Before anything else, write down exactly what data enters your program and what data leaves it. Not what you think might enter it. What actually will. If you're building a CLI tool that reads a JSON config, write the shape of that JSON. If you're writing a function, write the expected type signature and a couple of concrete examples of what goes in and what comes out. This step takes three minutes. Skipping it costs you at least forty-five. I once spent an afternoon debugging a date parsing issue only to realize I hadn't specified whether my input dates were ISO 8601 or US format in the project notes. The test data used one format, the production data used the other, and my code matched whichever one I'd accidentally hardcoded first. Writing the spec on paper would have surfaced this in seconds.
Step two: control flow before code
Draw the sequence of operations. Not a diagram. A list. Numbered. Each step should be something you can implement in a single function or a few lines of code. If a step feels too big, break it down until it fits. This is where most people's "quick" plans fall apart because they jump straight to implementation without checking whether their mental model actually holds together. I once mapped out a webhook handler that looked reasonable until I listed the steps and realized I hadn't accounted for what happens when the upstream service sends the payload twice. The idempotency question wasn't obvious from the high-level description. Numbering the steps exposed it. I added a deduplication key check as step three and moved on. Took thirty seconds after catching it on paper. Would have taken three hours to debug in production.
Get the Full Details

Step three: write the dumbest version that works
This is the step people resist the most. You write code that does the job in the most straightforward way possible, even if it's ugly. Hardcode values if you need to. Use simple loops instead of comprehensions. No abstractions. No patterns. The goal is a working program that passes your concrete examples from step one, not a program you'd be proud to show anyone. I know the temptation to optimize early. You can feel it. You see the structure and think you know where the bottlenecks will be. Don't. In my experience, the things you optimize first are rarely the things that matter. A pagination endpoint I built with naive offset-based queries ran fine for months because the dataset stayed small. When it grew to two million rows, the query time jumped from 80 milliseconds to 14 seconds, and I had already built three layers of abstraction on top of the query builder. If I'd left it dumb, I would have spotted the performance problem during step five testing and swapped to cursor-based pagination in ten minutes.
Step four: fill in the gaps
Once the dumb version works, go back and add the pieces you intentionally skipped: error handling, input validation, logging, any abstractions that make the code readable for someone else. This is where the work actually happens. The first version is your proof of concept. This version is your deliverable. The gap-filling phase is also where you should consider whether Quick Coding Step By Step is even the right approach. If the project requires production-grade reliability, security review, or complex state management, this workflow will get you to a prototype in an hour but won't get you to deploy-ready code without significant additional effort. The method trades completeness for velocity. That's the trade. Acknowledge it.
Step five: break it on purpose
Test with inputs your program shouldn't receive. Empty files, malformed JSON, null values where strings are expected, concurrent requests if your tool handles them, boundary conditions on numeric ranges. This isn't about writing more tests. It's about actively trying to find what your dumb version can't handle before someone else does. I found this step uncomfortable for a while. My ego wanted the code to work without having to sabotage it. But the edge cases you catch here are the same edge cases that cause incidents at 2 AM. There's no shortcut around it. A data export script I wrote for a client crashed silently when a single row contained a tab character inside a quoted field, because I'd written the parser with split-comma instead of proper CSV handling. Adding a single test case with embedded tabs revealed it immediately. The fix was switching to the csv module. Forty seconds.

Where this method fails
Quick Coding Step By Step doesn't work well for distributed systems, real-time applications, or anything with strict compliance requirements. It also breaks down when the problem space itself is poorly understood. If you're building something where you don't yet know what the right input-output contract looks like, five steps isn't going to help. You need exploration first. The method assumes you can define the boundaries upfront, which isn't always true. For those cases, consider iterative prototyping instead. Build the thing, see what breaks, adjust. It's slower in the short term but avoids the false confidence that comes from treating an undefined problem like it has clean edges. I've seen teams ship "quick" implementations of fuzzy requirements and then spend six weeks untangling the mess because nobody stopped to ask whether the original problem was actually well-specified.
Practical notes from actual use
The whole workflow typically takes 45 to 90 minutes for a small-to-medium task. A moderately complex script with three data transformations and a database write usually lands around an hour if you stay disciplined about the steps. It stretches when you get sidetracked by implementation details during step one, which is the most common failure mode. You start describing the code instead of the interface. One thing most guides don't mention: the paper sketch in step two benefits from being done in pen, not digitally. The friction of rewriting a digital list makes you think harder about whether each step is actually necessary. I switched from typed outlines to handwritten ones after realizing my digital lists always had three or four steps that existed only because I'd copy-pasted them from a previous project without editing them down. If you want to start using this today, there's nothing to download. The method is just the five steps in this order. What helps is keeping a template of the format: input specification, output specification, numbered control flow, then the code file itself. I keep a simple markdown file with those four sections for every project, and I delete the file when the project is done. The template takes up less space in my workflow than any tooling would.