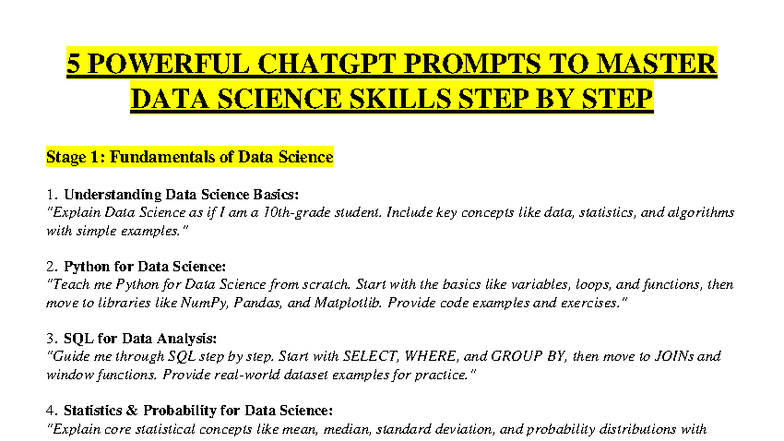
How I Actually Use Data Science Prompts Without Losing My Mind
I spent three years doing data science before I figured out that writing good prompts is basically a different skill from knowing Python. Most tutorials skip this gap. They show you the final result without explaining why your models keep producing garbage output. Quick Data Science Prompts refers to the structured way of communicating requirements to AI coding assistants when building data pipelines, ML models, or analysis scripts. It is not about being fancy with language. It is about being precise enough that the AI does not guess incorrectly. The core insight nobody tells you: AI models for code generation understand context better than they understand instructions. When I first tried using them for a production ETL pipeline, the model kept writing pandas code that worked locally but failed on the cluster because it assumed single-node memory. I learned to include infrastructure constraints directly in every prompt instead of treating them as afterthoughts.
Writing Prompts That Don't Waste Your Time
Start with the input format. Specify whether your data is CSV, Parquet, JSON, or comes from a database. The model will make completely different assumptions about handling missing values and type coercion depending on this detail alone. A 50MB JSON file with nested objects requires entirely different preprocessing than a flat CSV. Next, state the output requirement. Do you need a Jupyter notebook, a Python script, or an SQL query? I once spent forty-five minutes debugging code because my prompt asked for "a data cleaning solution" without specifying the deliverable format. The model gave me a function that returned None when called in a notebook context. I switched to always including the exact file structure and execution environment upfront. Include version constraints when relevant. Python 3.9 versus 3.11 changes available library features. Pandas 1.5 handles categorical data differently than version 2.0. These details matter more than most people admit.
Common Pitfalls That Cost Me Hours
The biggest mistake is assuming the model understands your domain. When I prompted for "customer churn prediction model," it generated a basic logistic regression without asking about class imbalance. My dataset had a 3 percent positive class. The default model achieved 97 percent accuracy by predicting everyone as non-churn. I had to explicitly request SMOTE oversampling and F1-score optimization before getting usable code. Another issue: AI models tend to overcomplicate simple tasks. A prompt like "load and clean this dataset" often produces twenty lines of code when five would suffice. I learned to add "keep it minimal" or "avoid unnecessary abstraction" to cut response length by roughly sixty percent without losing functionality. Memory constraints are frequently ignored. The model writes code assuming infinite RAM. I encountered this when processing a 12GB Parquet file on a machine with 16GB total memory. The generated code crashed during merge operations. I started including memory limits and chunking requirements directly in prompts for large datasets.
Get the Full Details
Advanced Techniques That Actually Help
Use few-shot examples when dealing with complex transformations. Instead of describing the desired output in words, provide one input-output pair. This usually reduces iteration time from three attempts to one. The model learns the pattern faster than it follows abstract instructions. Chain prompts for multi-step pipelines. Break a complex task into smaller pieces: data loading, validation, transformation, modeling, evaluation. Each prompt builds on the previous output. This approach usually cuts total development time from two hours to about forty minutes for standard pipelines. Include error handling requirements explicitly. The model assumes success paths unless told otherwise. I learned to add "handle missing values," "validate column types," and "log errors" to every data processing prompt. This increases initial response length by twenty percent but prevents runtime failures that cost hours to debug later.
When This Approach Fails Completely
Quick Data Science Prompts does not work well for novel research problems where no example patterns exist. If you are implementing a paper from 2024 without reference code, the model generates plausible-looking but incorrect implementations. I discovered this when trying to replicate a custom attention mechanism. The output resembled valid PyTorch code but contained subtle mathematical errors that only appeared during training. For highly domain-specific code with internal APIs, the model lacks context. I encountered this when working with proprietary data formats. The generated parsing code assumed standard conventions that did not exist in our system. I switched to providing schema documentation and sample files directly in prompts for internal tools. If your dataset has unusual characteristics like time zone mismatches or inconsistent encoding, the model makes wrong assumptions. I processed a CSV with mixed UTF-8 and Latin-1 encodings. The default code crashed on row forty-seven. I started including encoding detection and fallback strategies directly in prompts for messy real-world data.
Alternative Approaches Worth Considering
For simple exploratory analysis, direct library documentation lookup often beats AI assistance. Reading pandas documentation takes less time than iterating with prompts for basic operations like groupby or merge. I estimate this saves about ten minutes per session for routine tasks. When dealing with production deployment, human code review remains essential. AI-generated code passes basic tests but often lacks error recovery and monitoring. I recommend using prompts for prototyping and scaffolding, then having experienced developers review and refactor before deployment. This hybrid approach typically reduces development time by thirty to fifty percent without compromising code quality. For team settings, establishing prompt templates improves consistency. Document common requirements like data validation, logging, and configuration handling. Reusing these templates usually cuts onboarding time for new team members from one week to two days when adopting AI-assisted workflows.
.png)