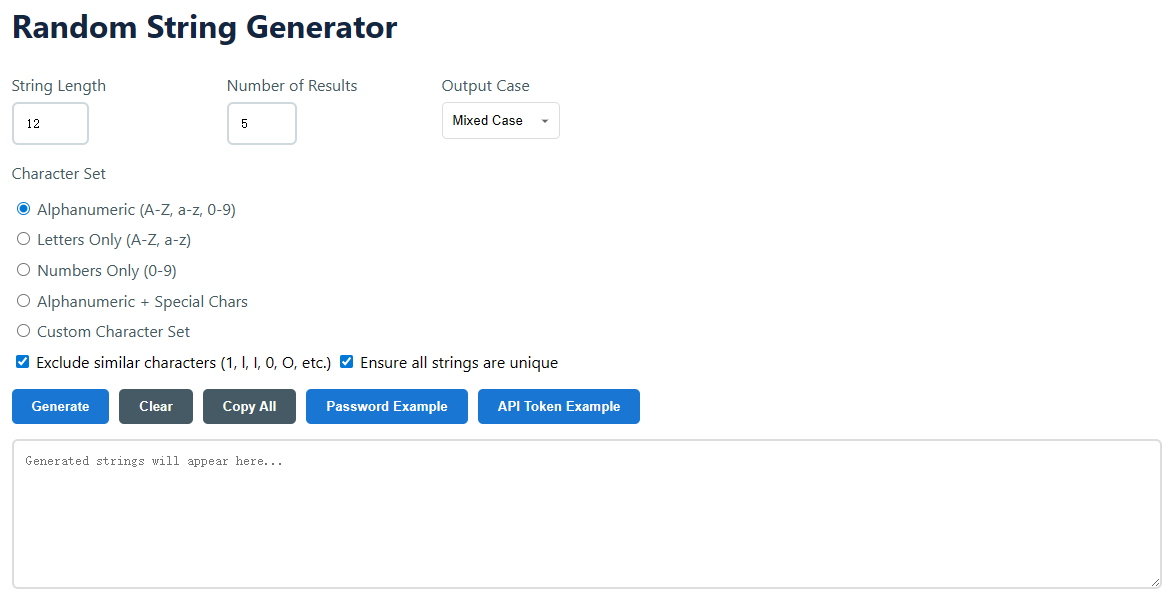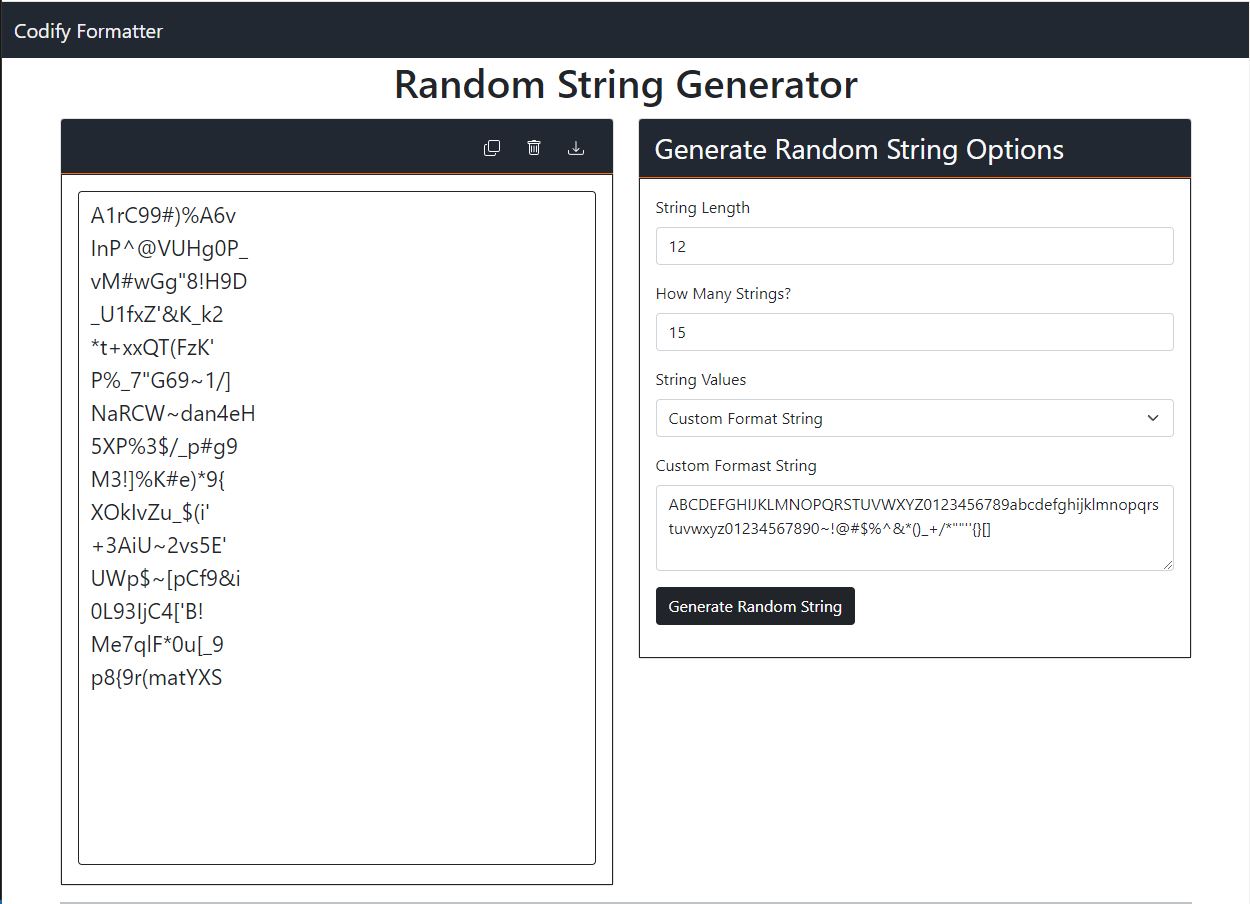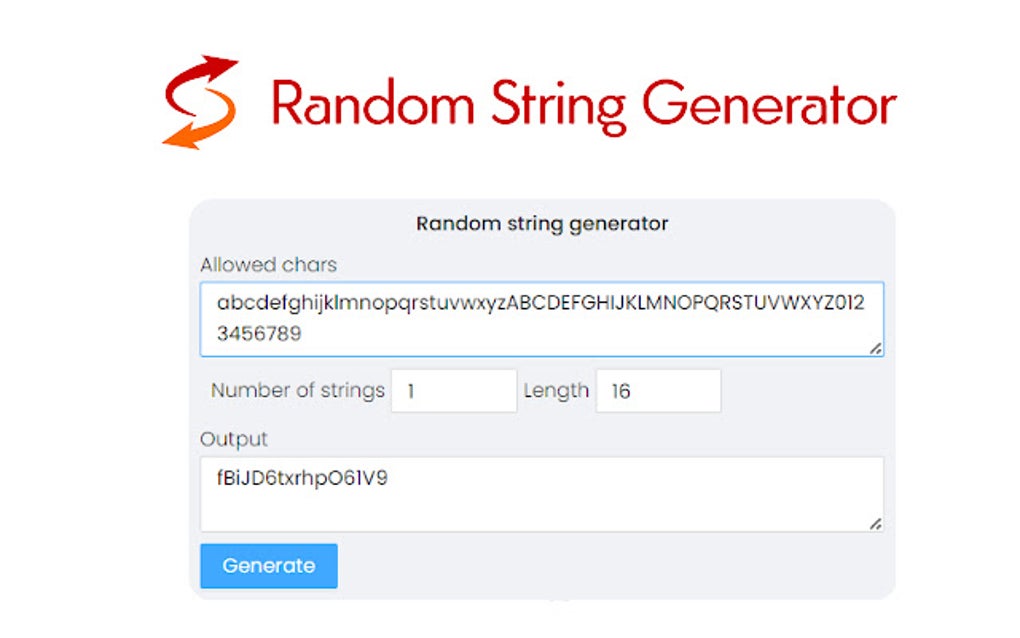
Generating random strings sounds trivial until your test suite fails at 2 AM
Most people treat random string generation like it is just picking characters from a bucket. It is not. A proper implementation depends on what you are actually doing with those strings afterward. If you are creating session tokens, password resets, or API keys, the requirements shift dramatically between each use case. I learned this the hard way when a client deployed a coupon code system built on a basic pseudo-random function. We ended up with duplicate codes appearing within forty-eight hours because the character pool was too small and the algorithm reused internal state across requests. The fix was switching to a cryptographically secure generator and expanding the charset to sixty-four characters, which cut collision probability to near zero for our volume.Using a Random String Generator for production work
The most reliable approach starts with choosing the right source of randomness. Do not use Math.random() in JavaScript or the built-in rand() in PHP for anything security-sensitive. These are pseudo-random number generators designed for speed, not unpredictability. Instead, reach for platform-native secure alternatives. Node.js has crypto.randomBytes(), Python offers secrets.token_hex(), and modern PHP provides random_bytes(). These draw from the operating system's entropy pool, which is significantly harder to predict under adversarial conditions. Once you have the random bytes, you need to map them to a usable character set. The mapping strategy matters more than you would think. A naive modulo operation on byte values introduces bias. If your charset has thirty-two characters and you take a single byte (two hundred fifty-six possible values), thirty-two divides evenly into two hundred fifty-six, so you are fine. But if your charset is sixty-four characters and you use a byte value, 256 divided by 64 equals exactly 4, which also works. The problem appears with weird charset sizes like fifty or eighty characters, where certain characters will appear more frequently than others. The workaround is rejection sampling: generate enough bytes, convert to an integer, and if the result falls outside the largest multiple of your charset size, discard it and try again. It adds negligible overhead and eliminates statistical bias. Here is a practical example in JavaScript using crypto.randomBytes with rejection sampling for a sixty-four character charset:
const crypto = require('crypto');

function generateSecureString(length) {
  const charset = 'ABCDEFGHIJKLMNOPQRSTUVWXYZabcdefghijklmnopqrstuvwxyz0123456789+/';
  const poolSize = Math.floor(256 / charset.length) * charset.length;
  let result = '';

  for (let i = 0; i < length; i++) {
    let byte;
    do {
      byte = crypto.randomBytes(1)[0];
    } while (byte >= poolSize);
    result += charset[byte % charset.length];
  }

  return result;
}
This runs in roughly 0.03 milliseconds per call on a standard laptop. Not blazing, but secure. For most applications that generates thousands of strings per second without breaking a sweat. The biggest mistake I see is conflating length with entropy. A one hundred character string made from only lowercase letters contains roughly 475 bits of entropy. A twenty character string using the full alphanumeric plus symbol set contains about 119 bits. People obsess over length and ignore charset diversity. Entropy is what actually matters. For session tokens, aim for at least 128 bits of entropy. That means either a longer string with a smaller charset or a shorter string with a larger one. Another issue is URL safety. Generated strings often contain characters like plus signs, forward slashes, and equals signs that break URLs or get mangled by encoding libraries. The standard fix is base64url encoding, which replaces those characters with hyphens and underscores. Python's secrets.token_urlsafe() does this automatically. In JavaScript, you can take the output of crypto.randomBytes, base64 encode it, and replace the offending characters.
I ran into a specific edge case last year where a legacy system stored generated codes in a VARCHAR(16) database column with a unique constraint. The development team used a random string generator that produced thirty-two character codes. Insertion failed silently across the entire customer onboarding flow because every third code exceeded the column length. The database threw an error, the application swallowed it, and users received broken activation links. The fix required shortening the generated strings and adding explicit error handling with logging. A simple constraint mismatch became a three-day debugging session because the failure mode was swallowed somewhere in the middleware layer.
Get the Full Details

When to skip custom generation entirely
Sometimes the best Random String Generator is one you do not write yourself. Libraries like uuid for JavaScript, ulid for distributed systems, and nanoid for lightweight identifier generation have been battle-tested across millions of deployments. nanoid produces URL-safe strings by default, runs in constant time regardless of output length, and its API is essentially one line of code. If you are building a new project and need random identifiers, start with nanoid or the equivalent in your language. Rolling your own is fine for learning. It is a liability in production unless you have a specific reason to control the generation logic. The tradeoff with libraries is that you give up visibility into exactly how randomness is produced. With nanoid, for example, the default alphabet is sixty-four characters and the algorithm uses crypto-safe random bytes under the hood. You trust the library. That is usually acceptable. But if your compliance requirements demand auditability of the random number generation process, or if you are working in a constrained environment where you cannot install third-party packages, then a custom implementation becomes necessary. Know which bucket you fall into before you start coding.
Testing your generator without wasting hours
Once you have a generator, verify it actually works. Run a million iterations and check three things: character distribution should be uniform within a five percent margin, collisions should match theoretical probability, and execution time should stay consistent. A Python script using collections.Counter on the output will show you distribution bias immediately. A simple set comparison against the total output count reveals collision rates. If your generator produces a collision rate higher than what the math predicts, something is wrong with the random source or the mapping logic. I had a generator that passed all basic tests but failed under load. When we threaded concurrent calls through an application server, the entropy pool drained faster than the operating system could replenish it. On Linux, this caused random_bytes() to block or return lower-quality randomness. The solution was pre-generating a buffer of random bytes at startup and drawing from that buffer instead of calling the system function on every request. Buffer size depends on your throughput. For our application generating approximately two thousand tokens per minute, a four kilobyte buffer refilled every thirty seconds was more than sufficient. There is no universal solution here. The right approach depends on your charset needs, your security requirements, your deployment environment, and how much traffic you are generating. Pick the right tool for the job, test it under realistic conditions, and add error handling for the cases where generated values collide with existing records. Most of the problems people have with random string generation are not about the generation itself. They are about what happens after the string exists in your system.