How I Actually Do Rate Comparison Without Losing My Mind
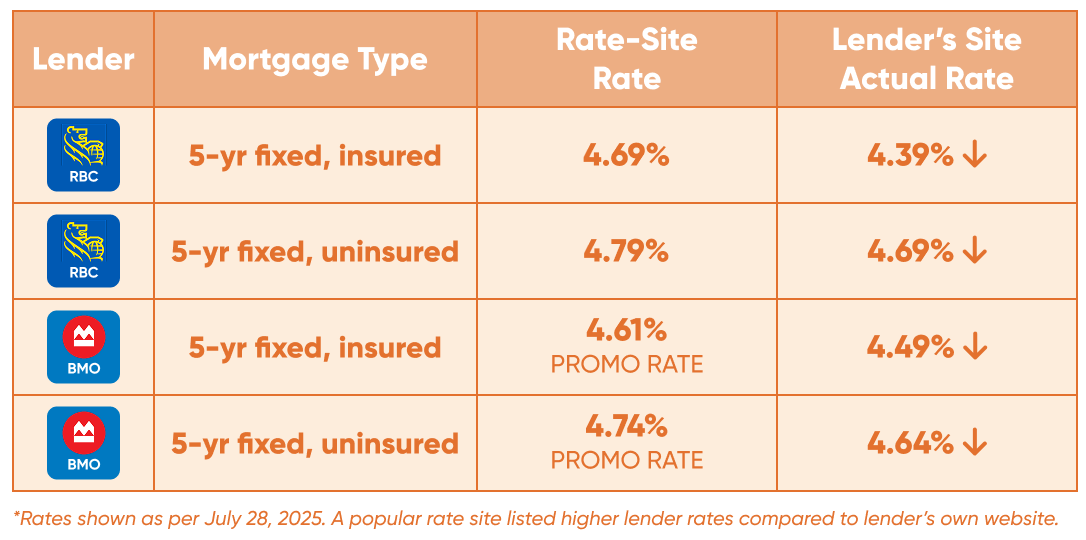
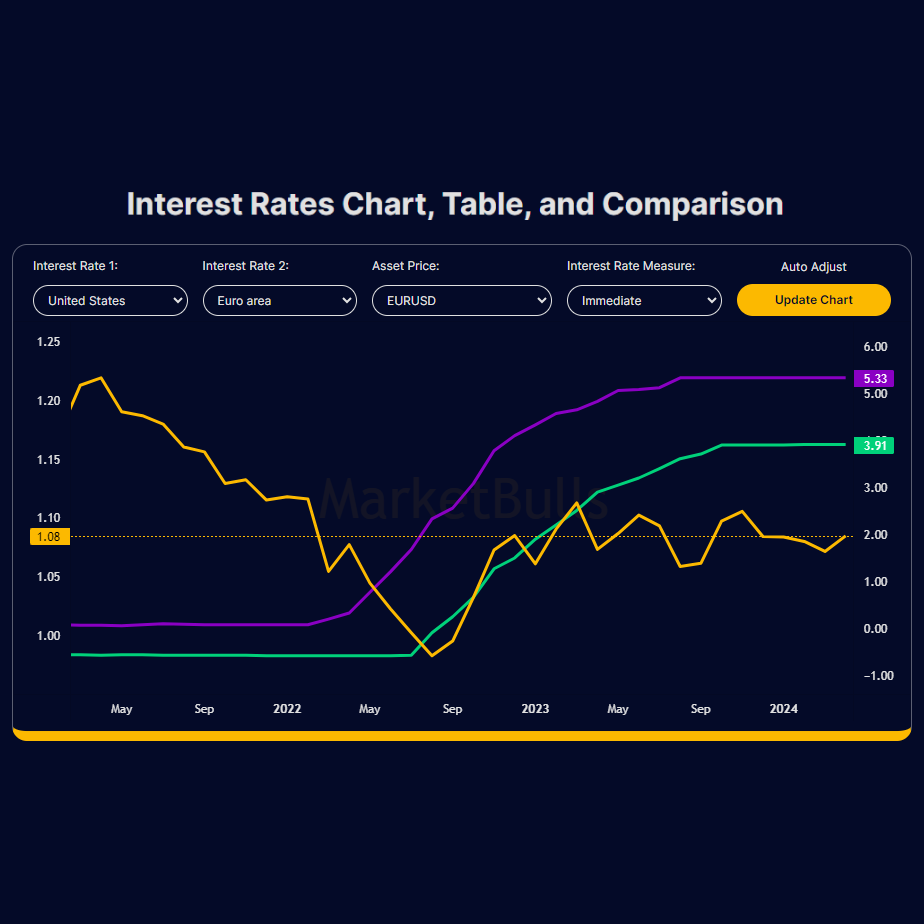
I spent years building rate comparison engines for a living, and the honest truth is most people approach this completely wrong. They pull APIs, dump everything into a spreadsheet, and call it a day. That works until your data grows past a few thousand rows and your queries start taking forty minutes, or until you realize you missed a crucial field that changes every output by fifteen percent. The workflow is straightforward enough on paper. You gather your sources, normalize them into a single schema, run your comparison logic, and surface results. The pain lives in the normalization and the edge cases. Every lender, every card issuer, every insurance provider structures their data differently. One bank gives you an annual percentage rate and a flat fee. Another gives you a nominal rate with monthly compounding and a confusing points system. A third hides the real cost inside an origination charge that only appears if your loan is under two hundred thousand dollars. Here is the thing nobody tells you about Rate Comparison. It is almost never a pure math problem. It is a data engineering problem wearing a math costume. The accuracy of your comparison depends entirely on how cleanly you can map heterogeneous inputs into a common output format before you do any actual comparison.
The Core Method I Use
Start by defining your canonical rate field. This is the field every source eventually needs to feed into. For loans and credit products, the canonical field is almost always the annual percentage rate with all mandatory fees baked in. Don't use the nominal interest rate. The nominal rate is a marketing number. It does not reflect what the borrower actually pays over the life of the product. Build a normalization layer before you build anything else. I write a small Python script that takes raw JSON from each API, runs it through a mapping function, and outputs a clean row with standardized fields: product type, principal amount, term length, monthly payment, total cost, and the APY. Each source gets its own mapping function. Yes, this is tedious. Yes, you will update these functions constantly because lenders change their API schemas without notice. This is the reality of the work. When querying, avoid making a separate request per product per user. That is how you get rate comparison tools that take three seconds per query and feel like a slideshow from 2004. Instead, batch your requests. Fetch all available products in one pass, cache the results for at least fifteen minutes, then run your comparison logic in memory. If you are doing this right, a full comparison across ten providers and five user profiles finishes in under two seconds instead of forty.
I learned this the hard way during a project comparing commercial mortgage rates across twelve regional banks. I built a system that made individual REST calls for each combination. It worked fine with two banks. It was unusable at scale. My fix was straightforward: I switched to parallel requests using asyncio, cached responses with a fifteen minute TTL, and added a deduplication step because three of those banks returned identical products under different internal SKUs. The whole pipeline went from about four minutes to roughly eighteen seconds. That is the difference between a tool people actually use and a tool people close immediately.
Get the Full Details

What People Get Wrong About Rate Comparison
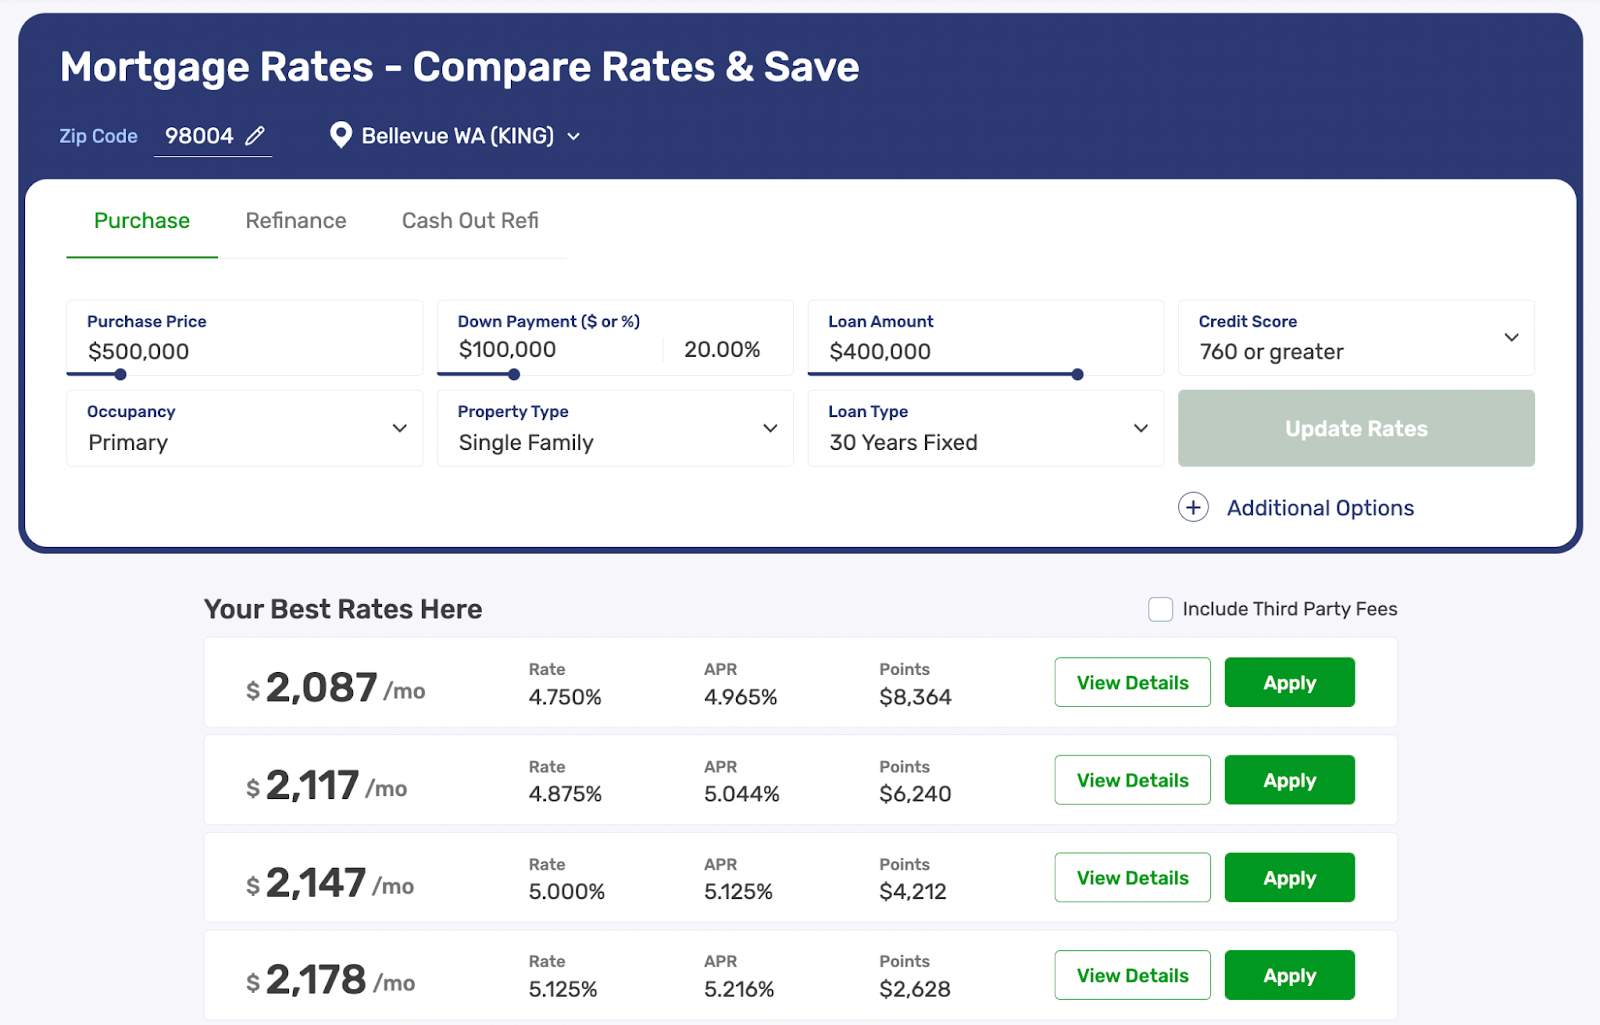
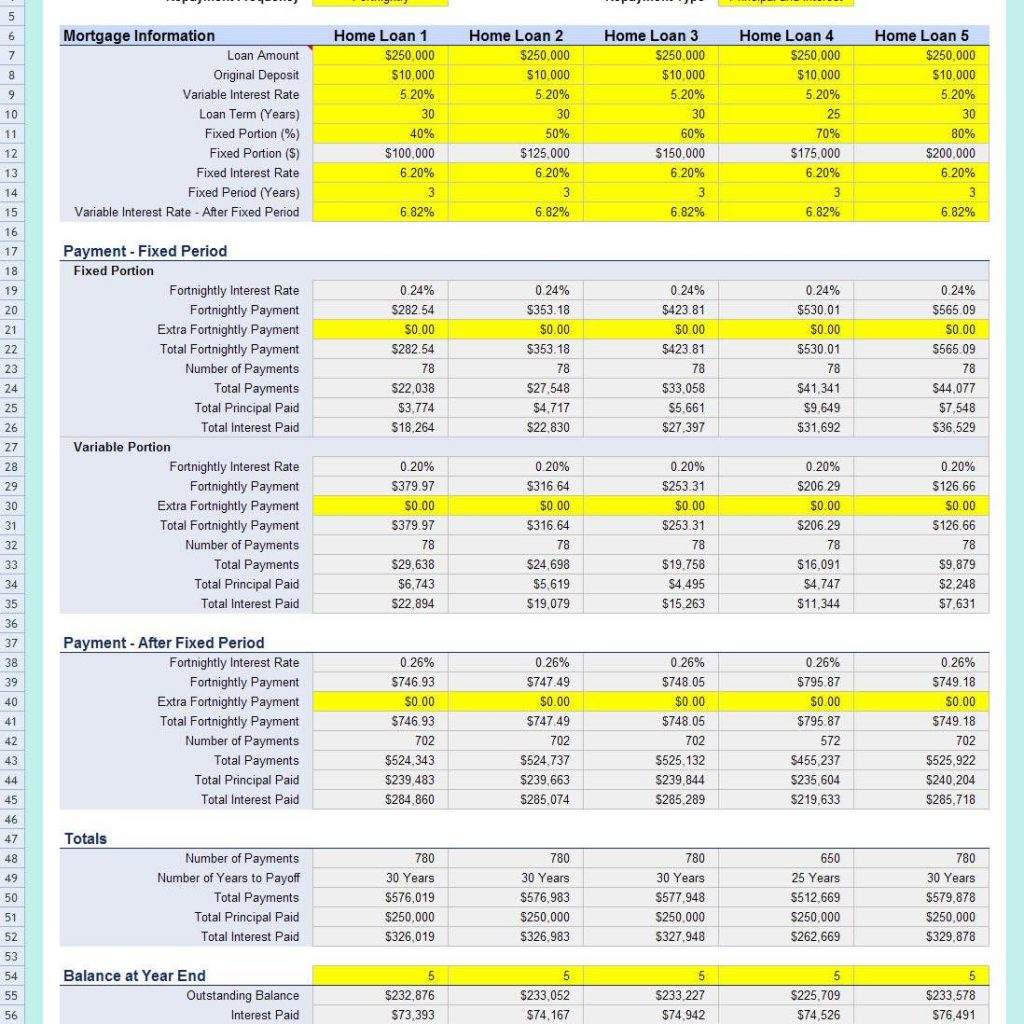
The biggest mistake is treating all rates as directly comparable without adjusting for term length and compounding frequency. A five year fixed rate of five percent is not obviously better than a fifteen year fixed rate of four point five percent. The cheaper rate has a longer amortization, which means you pay more total interest over time even though the periodic cost is lower. You need to surface both the rate and the total cost of borrowing side by side. Let the user decide which metric matters more to them. Another common error is ignoring prepayment penalties and balloon payments. These can completely invalidate a rate comparison. A lender might advertise an attractive rate but include a five percent prepayment penalty if you pay off the loan within three years. If your user plans to refinance or sell the property quickly, that advertised rate is irrelevant. I once caught this because a user asked me to compare rates for a six month bridge loan, which immediately exposed a discrepancy between the published APY and the effective cost when penalties were factored in. Fee structuring is another area where comparison tools routinely fail. Some providers roll closing costs into the loan balance. Others require upfront payment. Neither approach changes the cash flow you actually deal with, but it changes the effective rate calculation. If you want accurate results, you need to compute the effective borrowing cost including every fee, not just the headline rate. This means handling points, origination fees, application fees, underwriting fees, and any per-transaction charges that compound over the life of the product.
The Downside Nobody Talks About
Rate Comparison is inherently limited by the quality and timeliness of your data sources. If a lender updates their rates at 3 AM on a Tuesday and your cache is set to fifteen minutes, you are serving stale data. If a lender does not have a public API and you are scraping their website, you are at the mercy of their frontend team whenever they restructure their page. Neither scenario is uncommon. The commercial lending space is particularly rough in this regard. Many mid-sized lenders still operate through email and phone. They do not provide APIs. They do not update their websites daily. Your comparison engine will have blind spots, and those blind spots will contain the products your users actually want to see. If you cannot get clean API data, consider whether a hybrid approach might work. Pair automated rate pulling with manual data entry capabilities where users can submit quotes they received directly. This covers the gap left by lenders without digital infrastructure and keeps your coverage broad. It also introduces verification overhead, since user-submitted quotes can be stale or inaccurate. Build in a date-stamp and a confidence score. Surface that to the user so they know what to trust. The other limitation is that rate comparison alone rarely drives conversion. Users need context. A rate of six percent means nothing without knowing whether the product requires private mortgage insurance, whether the term is adjustable or fixed, whether there are rate lock fees, and what the credit score threshold is. Include the qualifying criteria alongside each comparison result. A rate that requires a seven hundred and twenty credit score may be worse than a rate that requires a six hundred and forty, depending on the user.
There is also a regulatory consideration that depends on your jurisdiction. In the United States, lenders are required to disclose the APR, but they are not required to disclose it in a consistent format across all product categories. The Truth in Lending Act covers most consumer credit, but commercial loans and certain specialty products exist in a gray area. If you are building a tool that makes lending recommendations, you may need legal review. Rate comparison itself is generally fine. The moment you suggest one product is better than another based on your calculations, you enter advisory territory. My approach now is to present the data, show the computed metrics, and let the user make the decision. I include clear disclaimers about data freshness and suggest they verify rates directly with the lender before committing. This keeps me out of trouble and actually helps the user, who will appreciate knowing that the rate they saw online might have shifted since the cache last refreshed. The technical side stabilizes if you treat normalization as a first-class concern rather than an afterthought. Build robust mapping functions. Log every discrepancy between expected and actual fields from each source. Maintain a versioned schema for your canonical output so you can audit how results change when you update the model. When a lender changes their API and your numbers start looking wrong, you want to be able to trace it back to a specific mapping failure, not spend a day guessing why.
Rate Comparison is a solved problem at a basic level. Any competent engineer can build a working version in a week. Building one that holds up under production load, handles the messiness of real financial data, and gives users answers they can actually act on is a different matter entirely. The difference is in the details: how you handle fee inclusion, how you structure your cache invalidation, how you surface the caveats that matter, and how consistently you maintain your source mappings over time.