Getting Data In and Out of R Without Losing Your Mind
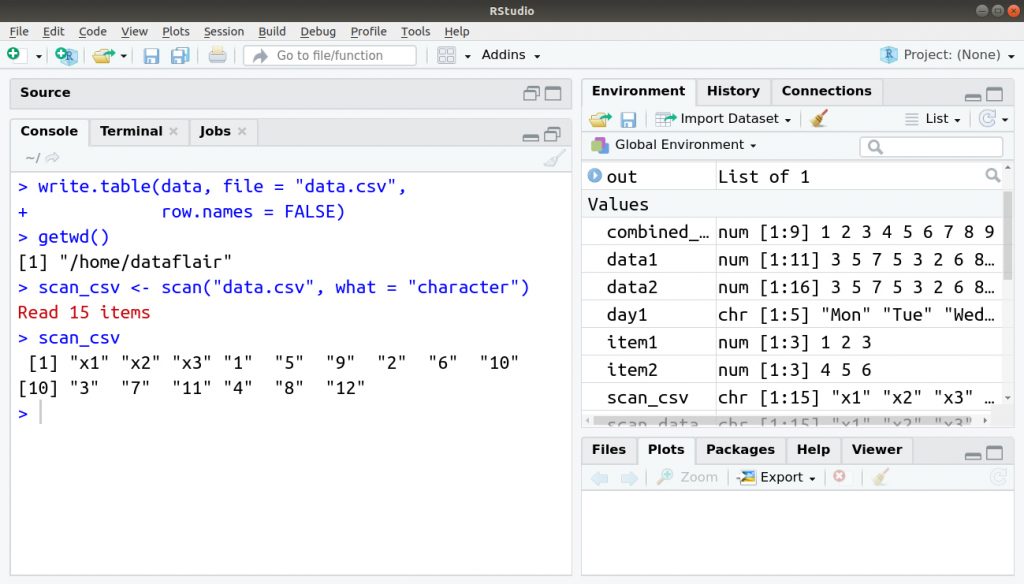
Data ingestion and export are where most people waste their time in R. I used to watch my code crawl at 200MB/s on a single CSV because I was using base R functions for something that required more. The learning curve is real but the payoff is immediate once you understand which tools actually work. Start with the basics. Base R has read.csv, read.table, readr::read_csv, and data.table::fread. They all do roughly the same thing but perform differently under load. read.csv is fine for small datasets. Once your files cross 500MB, you need something else. readr::read_csv is faster and more consistent with column types. fread from data.table is the fastest option for flat files and it handles messy data without complaining.
Reading And Writing In R: The Core Functions
For CSVs, use fread("file.csv") if speed matters, or read_csv("file.csv") if you want clean type inference. Both return data frames. fread returns a data.table by default. That's important because data.table operations differ from base R data frame operations in subtle ways that will trip you up later if you don't notice them. Excel files need the readxl package. read_excel("file.xlsx", sheet = 1) reads the first sheet. There is no ambiguity about encoding here since XLSX handles that internally. Pass col_types = "skip" for columns you don't need. This alone can cut read times in half for wide spreadsheets with 200+ columns where you only use ten of them. JSON data comes from jsonlite::fromJSON("file.json"). It returns a list by default, which you then convert with as.data.frame(). Nested JSON is where people get stuck. Flatten it first with jsonlite::prettify() or use fromJSON with simplifyVector = TRUE to coerce nested structures into flat tables.
For R's native format, saveRDS(obj, "file.rds") and readRDS("file.rds"). This preserves object classes, attributes, and exact state. It's the standard for saving models, large processed objects, and anything you need to reload without reprocessing. Don't use save() and load() for single objects. save() writes to a workspace snapshot and loads everything into your global environment. That's a different workflow entirely.
Get the Full Details
Writing Data Out
write.csv and fwrite from data.table handle CSV output. fwrite("file.csv", data) is dramatically faster than write.csv for anything over 100,000 rows. It also defaults to writing commas instead of semicolons, which means European readers won't immediately break your files. For Excel output, write_xlsx from readxl isn't the right tool. Use openxlsx::write.xlsx() or writexl::write_xlsx(). The openxlsx package handles formulas and multiple sheets. If you need to write a sheet with conditional formatting or merged cells, go with openxlsx. The writexl package is simpler but only supports flat sheets. jsonlite::toJSON(df, auto_unbox = TRUE) converts data frames to JSON with proper scalar boxing. Without auto_unbox, every column becomes a length-one vector inside an array. Your downstream consumer will parse it wrong.
For RDS, use saveRDS(). It's lossless and fast. A 2GB object takes about 4 seconds to write on a modern SSD. Reading it back is equally quick. This is the format I use for model artifacts and intermediate processing steps.
A Problem I Actually Hit
Recently I was reading a 3GB CSV with mixed encodings. Columns had data from three different regions with different character sets. readr::read_csv choked on the encoding boundary around row 4.2 million. The error was cryptic: "Invalid UTF-8 byte sequence." No line number. No column name. Just a crash. The workaround was to read the file in chunks using data.table::fread with the select parameter to isolate the problematic columns, then merge them back. Specifically, I used fread("file.csv", select = c("id", "region_code", "description")) to pull only the clean columns first, then fread again with encodeString() on the suspect column after pre-processing it through iconv(). That gave me the data I needed without the full-file encoding panic.
Things Beginners Miss
Column type guessing is the biggest source of silent bugs. read_csv will infer a column as character if it sees one non-numeric value in the first thousand rows, even if the remaining 99% are numbers. This turns your numeric columns into factors or characters unexpectedly. Always specify col_types explicitly when the data has mixed formats or leading zeros. Col_types = cols(id = col_character(), amount = col_double()) prevents this. Another counter-intuitive point: fread caches its results. If you run fread("file.csv") twice in the same R session, the second call is near-instant because it hits the internal cache. This is useful for interactive work but dangerous if the file changes on disk. You'll be working with stale data. Use input = "file.csv" or set FREAD_CACHE to FALSE to disable it when reproducibility matters. The na.strings parameter behaves differently across functions. read.csv treats "NA" as missing. fread treats "", "NA", and a few others by default. If you export from one function and re-import with another, your missing values might not match. Check na.rm and na_strings settings explicitly when switching between readr and data.table workflows.
When Things Break Completely
RDS files are not portable across major R version upgrades. An object saved in R 4.3 may not read cleanly in R 4.4 if internal structures changed. This is rare but it happened to me with a custom S3 class in 2024. The object loaded but methods were missing. Save version info alongside your RDS files or use the .rdsx format from the vroom package, which is more forward-compatible. CSV export of data containing factor columns with levels that include commas will produce invalid CSV unless you quote properly. write.csv handles this by default, but fread with quote = FALSE disables quoting entirely and can corrupt your output. Always test export and re-import on a sample before running it on the full dataset. If you're working with files over 10GB, neither read_csv nor fread will be comfortable. Use vroom::vroom() or duckdb::duckdb_read_csv(). Vroom streams data and uses parallel parsing. DuckDB reads directly from the file without loading it into memory first. For a 12GB CSV, vroom cut my load time from about 8 minutes to roughly 90 seconds on my machine.
The best approach depends on your data size and format. Flat files under 500MB: fread or read_csv. Excel with multiple sheets: readxl for reading, openxlsx for writing. JSON with nesting: jsonlite with simplifyVector. Large repeated reads: vroom. RDS for serialization when you need exact state preservation. Nothing here is perfect, but knowing the trade-offs saves hours of debugging.